P.S. Free 2026 Linux Foundation CKA dumps are available on Google Drive shared by UpdateDumps: https://drive.google.com/open?id=1F_s5B9bojfOoJjBxZ-3mSBCqkrOh4Ntu
Certified Kubernetes Administrator (CKA) Program Exam CKA practice test not only gives you the opportunity to practice with real exam questions but also provides you with a self-assessment report highlighting your performance in an attempt. UpdateDumps keeps an eye on changes in the Linux Foundation CKA exam syllabus and updates Certified Kubernetes Administrator (CKA) Program Exam CKA Exam Dumps accordingly to make sure they are relevant to the latest exam topics. After making the payment for Certified Kubernetes Administrator (CKA) Program Exam CKA dumps questions you'll be able to get free updates for up to 365 days.
| Section | Weight | Objectives |
|---|---|---|
| Workloads & Scheduling | 15% | - Deployments and rolling updates - ConfigMaps and Secrets - Scheduling constraints |
| Troubleshooting | 30% | - Application and networking debugging - Cluster component troubleshooting |
| Storage | 10% | - Storage classes - PersistentVolumes and PersistentVolumeClaims |
| Services & Networking | 20% | - Ingress configuration - Services (ClusterIP, NodePort, LoadBalancer) - Network policies |
| Cluster Architecture, Installation & Configuration | 25% | - Kubernetes architecture components - Cluster installation and configuration - High availability setup |
>> New CKA Learning Materials <<
As long as you get to know our CKA exam questions, you will figure out that we have set an easier operation system for our candidates. Once you have a try, you can feel that the natural and seamless user interfaces of our CKA study materials have grown to be more fluent and we have revised and updated CKA Study Materials according to the latest development situation. In the guidance of teaching syllabus as well as theory and practice, our CKA training guide has achieved high-quality exam materials according to the tendency in the industry.
NEW QUESTION # 49
Create a persistent volume with name app-data, of capacity 2Gi and access mode ReadWriteMany. The type of volume is hostPath and its location is /srv/app-data.
Answer:
Explanation:
solution
Persistent Volume
A persistent volume is a piece of storage in a Kubernetes cluster. PersistentVolumes are a cluster-level resource like nodes, which don't belong to any namespace. It is provisioned by the administrator and has a particular file size. This way, a developer deploying their app on Kubernetes need not know the underlying infrastructure. When the developer needs a certain amount of persistent storage for their application, the system administrator configures the cluster so that they consume the PersistentVolume provisioned in an easy way.
Creating Persistent Volume
kind: PersistentVolume apiVersion: v1 metadata: name:app-data spec: capacity: # defines the capacity of PV we are creating storage: 2Gi #the amount of storage we are tying to claim accessModes: # defines the rights of the volume we are creating - ReadWriteMany hostPath: path: "/srv/app-data" # path to which we are creating the volume Challenge Create a Persistent Volume named app-data, with access mode ReadWriteMany, storage classname shared, 2Gi of storage capacity and the host path /srv/app-data.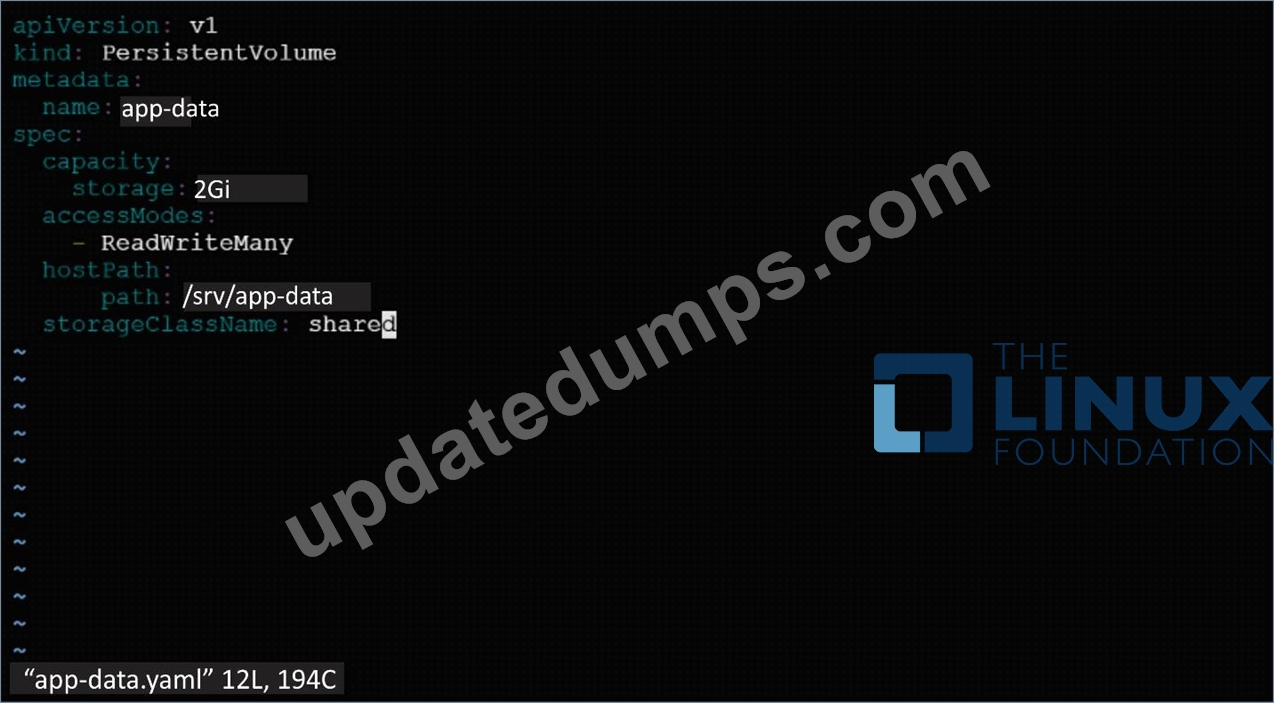
2. Save the file and create the persistent volume.
3. View the persistent volume.
Our persistent volume status is available meaning it is available and it has not been mounted yet. This status will change when we mount the persistentVolume to a persistentVolumeClaim.
PersistentVolumeClaim
In a real ecosystem, a system admin will create the PersistentVolume then a developer will create a PersistentVolumeClaim which will be referenced in a pod. A PersistentVolumeClaim is created by specifying the minimum size and the access mode they require from the persistentVolume.
Challenge
Create a Persistent Volume Claim that requests the Persistent Volume we had created above. The claim should request 2Gi. Ensure that the Persistent Volume Claim has the same storageClassName as the persistentVolume you had previously created.
kind: PersistentVolume apiVersion: v1 metadata: name:app-data
spec:
accessModes: - ReadWriteMany resources:
requests: storage: 2Gi
storageClassName: shared
2. Save and create the pvc
njerry191@cloudshell:~ (extreme-clone-2654111)$ kubect1 create -f app-data.yaml persistentvolumeclaim/app-data created
3. View the pvc
4. Let's see what has changed in the pv we had initially created.
Our status has now changed from available to bound.
5. Create a new pod named myapp with image nginx that will be used to Mount the Persistent Volume Claim with the path /var/app/config.
Mounting a Claim
apiVersion: v1 kind: Pod metadata: creationTimestamp: null name: app-data spec: volumes: - name:congigpvc persistenVolumeClaim: claimName: app-data containers: - image: nginx name: app volumeMounts: - mountPath: "/srv/app-data " name: configpvc
NEW QUESTION # 50
You are tasked with setting up fine-grained access control for a Kubernetes cluster running a microservices application. You need to ensure that developers can only access the resources related to their specific microservices while preventing them from accessing or modifying other services' resources. Define RBAC roles and permissions to achieve this, including details of the resources, verbs, and namespaces involved. Consider the following:
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Specify the YAML configurations for roles, role bindings, and service accounts to enable the required access control, ensuring developers only have access to their respective microservice's resources within their assigned namespaces. Solution (Step by Step) : 1. Define Roles:
2. Create Service Accounts: apiVersion: vl kind: ServiceAccount metadata: name: order-service-sa namespace: order-service-ns -- apiVersion: vl kind: ServiceAccount metadata: name: payment-service-sa namespace: payment-service-ns -- apiVersion: vl kind: ServiceAccount metadata: name: inventory-service-sa namespace: inventory-service-ns 3. Bind Roles to Service Accounts: -- apiVersion: rbac.authorization.k8s.io/v1 kind: RoleBinding metadata: name: order-service-dev-binding namespace: order-service-ns roleRef: apiGroup: rbac.authorization.k8s.io kind: Role name: order-service-dev subjects: - kind: ServiceAccount name: order-service-sa namespace: order-service-ns -- apiVersion: rbac.authorization.k8s.io/v1 kind: RoleBinding metadata: name: payment-service-dev-binding namespace: payment-service-ns roleRef: apiGroup: rbac.authorization.k8s.io kind: Role name: payment-service-dev subjects: - kind: ServiceAccount name: payment-service-sa namespace: payment-service-ns -- apiVersion: rbac.authorization.k8s.io/v1 kind: RoleBinding metadata: name: inventory-service-dev-binding namespace: inventory-service-ns roleRef: apiGroup: rbac.authorization.k8s.io kind: Role name: inventory-service-dev subjects: - kind: ServiceAccount name: inventory-service-sa namespace: inventory-service-ns 4. Assign Service Accounts to Users: This step requires external authentication mechanisms like OIDC or LDAP. Assuming you have these mechanisms set up, you can associate the service accounts with specific users ('john.doe@example.com' , 'jane.doe@example.com', and 'peter.pan@example.com') using the configured authentication provider. Roles: Define the specific permissions for each microservice developer within their respective namespaces. The roles allow developers to access resources like Pods, Deployments, Services, ConfigMaps, and Secrets related to their assigned microservice. Service Accounts: Service accounts are created in each namespace for each microservice, representing the identity of the developer group. Role Bindings: Role bindings connect the defined roles with the service accounts, granting the associated permissions. User Association: This step connects the service accounts with individual developers through external authentication mechanisms, enabling them to utilize the assigned permissions. By following these steps, you ensure that developers can only access and manage resources associated with their respective microservices within their assigned namespaces. This fine-grained access control policy effectively restricts access and prevents developers from interfering with other microservices or resources. ,
NEW QUESTION # 51
You are deploying an application on Kubernetes. You need to ensure that a minimum of three pods are always running for this application. How can you achieve this? Describe how to configure the deployment with a replica count and a liveness probe to monitor the health of the pods.
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Create a Deployment with a Replica Count:
- Create a YAML file named 'deployment.yamr with the following content:
- Apply the YAML file using 'kubectl apply -f deployment.yaml&. 2. Configure a Liveness Probe: - Update the 'deployment.yaml' file to include a liveness probe. For example, you could use a HTTP probe: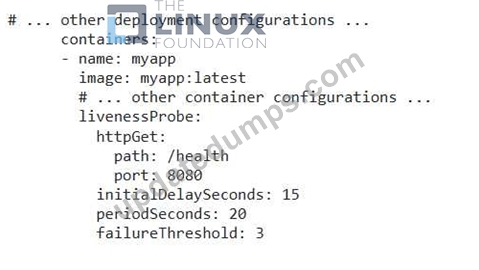
- Apply the updated YAML file using 'kubectl apply -f deployment.yaml'. 3. Verify the Deployment: - Check the status of the deployment using get deployments myapp-deploymen. - Ensure that three pods are running and that the liveness probe is monitoring their health. You can use 'kubectl describe pod myapp-deployment-XXXX' (where XXXX is the pod name) to see the details of the pod and the liveness probe status.
NEW QUESTION # 52
Given a partially-functioning Kubernetes cluster, identify symptoms of failure on the cluster.
Determine the node, the failing service, and take actions to bring up the failed service and restore the health of the cluster. Ensure that any changes are made permanently.
You can ssh to the relevant I nodes (bk8s-master-0 or bk8s-node-0) using:
[student@node-1] $ ssh <nodename>
You can assume elevated privileges on any node in the cluster with the following command:
[student@nodename] $ | sudo -i
Answer:
Explanation:
See the solution below.
Explanation
solution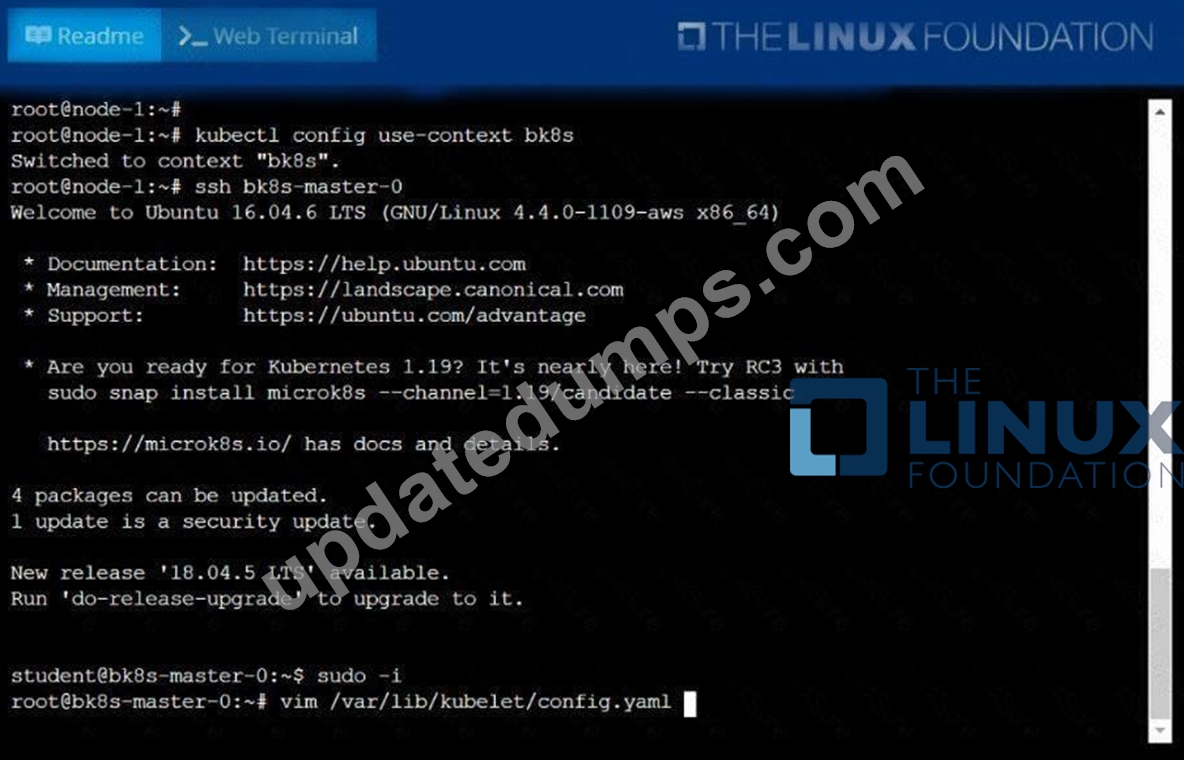


NEW QUESTION # 53
Resume the rollout of the deployment
Answer:
Explanation:
kubectl rollout resume deploy webapp
NEW QUESTION # 54
......
The language of our CKA study materials is simple. The learners may come from many social positions and their abilities to master our CKA study materials are varied. Based on this consideration we apply the most simple and easy-to-be-understood language to help the learners no matter he or she is the students or the in-service staff, the novice or the experienced employee which have worked for many years. CKA Study Material use the simple language to explain the answers and detailed knowledge points and the concise words to show the complicated information about the CKA study material.
CKA New Exam Bootcamp: https://www.updatedumps.com/Linux-Foundation/CKA-updated-exam-dumps.html
P.S. Free & New CKA dumps are available on Google Drive shared by UpdateDumps: https://drive.google.com/open?id=1F_s5B9bojfOoJjBxZ-3mSBCqkrOh4Ntu