DOWNLOAD the newest TestsDumps Databricks-Generative-AI-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1TuvEYDEI4kMJhybKovD_qxJyDOlGc_cI
Our company boosts top-ranking expert team, professional personnel and specialized online customer service personnel. Our experts refer to the popular trend among the industry and the real exam papers and they research and produce the detailed information about the Databricks-Generative-AI-Engineer-Associate exam study materials. They constantly use their industry experiences to provide the precise logic verification. The Databricks-Generative-AI-Engineer-Associate prep material is compiled with the highest standard of technology accuracy and developed by the certified experts and the published authors only. And you will be bound to pass the Databricks-Generative-AI-Engineer-Associate exam with them.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Reliable Databricks-Generative-AI-Engineer-Associate Dumps <<
We Promise we will very happy to answer your question on our Databricks-Generative-AI-Engineer-Associate exam braindumps with more patience and enthusiasm and try our utmost to help you out of some troubles. So don’t hesitate to buy our {Examcode} study materials, we will give you the high-quality product and professional customer services. As long as you study with ourDatabricks-Generative-AI-Engineer-Associate learning guide, you will be sure to get your dreaming certification.
NEW QUESTION # 77
What is the most suitable library for building a multi-step LLM-based workflow?
Answer: B
Explanation:
* Problem Context: The Generative AI Engineer needs a tool to build amulti-step LLM-based workflow. This type of workflow often involves chaining multiple steps together, such as query generation, retrieval of information, response generation, and post-processing, with LLMs integrated at several points.
* Explanation of Options:
* Option A: Pandas: Pandas is a powerful data manipulation library for structured data analysis, but it is not designed for managing or orchestrating multi-step workflows, especially those involving LLMs.
* Option B: TensorFlow: TensorFlow is primarily used for training and deploying machine learning models, especially deep learning models. It is not designed for orchestrating multi-step tasks in LLM-based workflows.
* Option C: PySpark: PySpark is a distributed computing framework used for large-scale data processing. While useful for handling big data, it is not specialized for chaining LLM-based operations.
* Option D: LangChain: LangChain is a purpose-built framework designed specifically for orchestrating multi-step workflowswith large language models (LLMs). It enables developers to easily chain different tasks, such as retrieving documents, summarizing information, and generating responses, all in a structured flow. This makes it the best tool for building complex LLM-based workflows.
Thus,LangChainis the most suitable library for creating multi-step LLM-based workflows.
NEW QUESTION # 78
A Generative AI Engineer I using the code below to test setting up a vector store: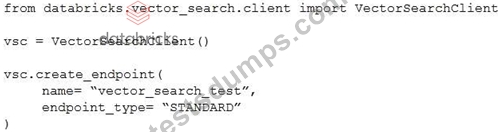
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: B
Explanation:
Context: The Generative AI Engineer is setting up a vector store using Databricks' VectorSearchClient. This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options:
* Option A: vsc.get_index(): This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index(): After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index(): This function would create an index that directly accesses the data without synchronization. While also a valid approach, it's less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search(): This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, henceOption B.
NEW QUESTION # 79
A Generative AI Engineer is building a multi-turn chat app with LangGraph on Databricks. The app must persist chat history-messages, roles, timestamps, and session IDs-for many concurrent users, support SQL queries, and stay governed in Unity Catalog. The engineer also wants ACID guarantees, low-latency reads and writes, and an easy way to sync chat data into Delta tables for analytics and model training.
Which approach fits these requirements?
Answer: B
Explanation:
Lakebase provides a Postgres database suited to transactional application state, including concurrent chat- history reads and writes. A Postgres-backed LangGraph checkpoint or memory component can persist conversation state across requests and application restarts. SQL support and transactional guarantees address the application's operational requirements. Databricks also documents registering Lakebase databases in Unity Catalog and feeding Lakebase changes into Delta tables for downstream analytics. These integrations require appropriate configuration and permissions; they are not automatic simply because a table exists.
MLflow runs are intended for experiment and application tracking rather than serving as a low-latency conversation database. Per-turn Spark writes introduce unnecessary processing overhead, while driver- memory storage with periodic snapshots risks losing recent conversation state. Databricks documentation
NEW QUESTION # 80
A Generative AI Engineer is tasked with deploying an application that takes advantage of a custom MLflow Pyfunc model to return some interim results.
How should they configure the endpoint to pass the secrets and credentials?
Answer: D
Explanation:
Context: Deploying an application that uses an MLflow Pyfunc model involves managing sensitive information such as secrets and credentials securely.
Explanation of Options:
* Option A: Use spark.conf.set(): While this method can pass configurations within Spark jobs, using it for secrets is not recommended because it may expose them in logs or Spark UI.
* Option B: Pass variables using the Databricks Feature Store API: The Feature Store API is designed for managing features for machine learning, not for handling secrets or credentials.
* Option C: Add credentials using environment variables: This is a common practice for managing credentials in a secure manner, as environment variables can be accessed securely by applications without exposing them in the codebase.
* Option D: Pass the secrets in plain text: This is highly insecure and not recommended, as it exposes sensitive information directly in the code.
Therefore,Option Cis the best method for securely passing secrets and credentials to an application, protecting them from exposure.
NEW QUESTION # 81
A Generative AI Engineer is experimenting with using parameters to configure an agent in Mosaic Agent Framework. However, they are struggling to get the agent to respond with relevant information with this configuration:
config = {"prompt_template": "You are a trivia bot. Generate a question based on the user's input: {user_input}", "input_vars": ["user_input"], "parameters": {"temperature": 0.01, "max_tokens": 500}} Which error is causing the problem?
Answer: C
Explanation:
In the Mosaic AI Agent Framework and underlying LangChain-based configurations, the "input_vars" or "input_variables" must be correctly mapped and referenced within the template. If the configuration dictionary identifies user_input as the variable but the logic executing the chain does not correctly "inject" the runtime value into the {user_input} placeholder, the LLM will receive a literal string (or an empty value) rather than the user's actual question. This results in the model failing to provide relevant information because it essentially doesn't know what the user asked. Engineering standards require ensuring that the key used in the input_vars list matches the key in the JSON payload sent to the model serving endpoint. If there is a mismatch or a failure to parse, the prompt remains static, leading to generic or irrelevant responses.
NEW QUESTION # 82
......
Are you praparing for the coming Databricks-Generative-AI-Engineer-Associate exam right now? And you feel exhausted when you are searching for the questions and answers to find the keypoints, right? In fact, you do not need other reference books. Our Databricks-Generative-AI-Engineer-Associate study materials will offer you the most professional guidance. In addition, our Databricks-Generative-AI-Engineer-Associate learning quiz will be updated according to the newest test syllabus. So you can completely rely on our Databricks-Generative-AI-Engineer-Associate study materials to pass the exam.
Databricks-Generative-AI-Engineer-Associate Exam Lab Questions: https://www.testsdumps.com/Databricks-Generative-AI-Engineer-Associate_real-exam-dumps.html
2026 Latest TestsDumps Databricks-Generative-AI-Engineer-Associate PDF Dumps and Databricks-Generative-AI-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1TuvEYDEI4kMJhybKovD_qxJyDOlGc_cI