There are many merits of our product on many aspects and we can guarantee the quality of our CCAR-P practice engine. Firstly, our experienced expert team compile them elaborately based on the real exam. Secondly, both the language and the content of our CCAR-P study materials are simple. The content emphasizes the focus and seizes the key to use refined CCAR-P Questions and answers to let the learners master the most important information by using the least practic. Three, we provide varied functions to help the learners learn our study materials and prepare for the exam.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Developer Productivity & Operational Enablement | 7% | - Support debugging, monitoring, and operational resolution - Configure Claude tools and environments for teams - Improve developer workflows with AI-assisted tooling |
| Topic 2: Evaluation, Testing & Optimization | 16% | - Implement iterative improvement pipelines - Optimize performance, prompting, and model selection - Test accuracy, reliability, latency, and cost - Define evaluation metrics and success criteria |
| Topic 3: Governance, Safety & Risk Management | 14% | - Ensure regulatory compliance (GDPR, HIPAA, etc.) - Address ethical AI considerations and bias mitigation - Manage data privacy and security compliance - Implement guardrails and safety controls |
| Topic 4: Integration | 19% | - Integrate Claude with enterprise systems, APIs, and tools - Implement Model Context Protocol (MCP) integrations - Integrate with data pipelines and RAG systems - Design authentication, authorization, and observability |
| Topic 5: Stakeholder Communication & Lifecycle Management | 14% | - Conduct structured discovery and requirement gathering - Document architectures and support full lifecycle phases - Communicate architectural decisions and trade-offs - Manage stakeholder feedback and expectation alignment |
| Topic 6: Solution Design & Architecture | 17% | - Translate business problems into Claude-based AI solutions - Select architectural patterns: workflow, agentic, augmented LLM - Align solutions to business value pillars - Design end-to-end architectures and feedback loops - Design multi-agent systems and orchestration strategies |
| Topic 7: Claude Models, Prompting & Context Engineering | 13% | - Mitigate prompt injection, leaks, and jailbreak risks - Design system prompts, templates, and guardrails - Select appropriate Claude models based on trade-offs - Apply context engineering and context management techniques |
>> Reliable CCAR-P Test Question <<
As we all know, practice makes perfect. It’s also applied into preparing for the exam. CCAR-P training materials of us contain both quality and quantity, and you will get enough practice if you choose us. In addition, CCAR-P exam cram cover most of the knowledge points for the exam, and you can master the major knowledge points for the exam as well as improve your professional ability in the process of learning. We are pass guarantee and money back guarantee if you fail to pass your exam by using CCAR-P Exam Dumps of us. Online and offline service are available by us, if you have any questions, you can consult us.
NEW QUESTION # 58
You are designing a feedback session for a deployment in flight.
Which structure best supports productive stakeholder feedback?
Answer: D
Explanation:
A structured feedback session must enable informed review, traceable decisions, and accountable follow- through. Option B allows stakeholders to examine architecture diagrams, evaluation results, risk registers, or prototypes before the meeting. The focused agenda keeps discussion aligned with decisions that must be made rather than allowing the session to become an unstructured status conversation. Written decision records prevent different participants from leaving with incompatible interpretations. Assigning an owner and due date to every action converts feedback into executable delivery work. Options A, C, and D depend heavily on memory, provide inadequate preparation time, and create weak decision traceability. In-flight deployments particularly require documented feedback because accepted changes may affect scope, cost, risk, testing, and release timing.
Study Guide references/topics: Stakeholder feedback; decision records; action ownership; lifecycle alignment; communication planning.
NEW QUESTION # 59
You are auditing a procurement-assistant agent whose defined responsibility is to draft purchase requests for review.
For each tool currently configured on the agent, select yes if the tool should remain after a least-privilege audit. Otherwise, select no if it should be removed.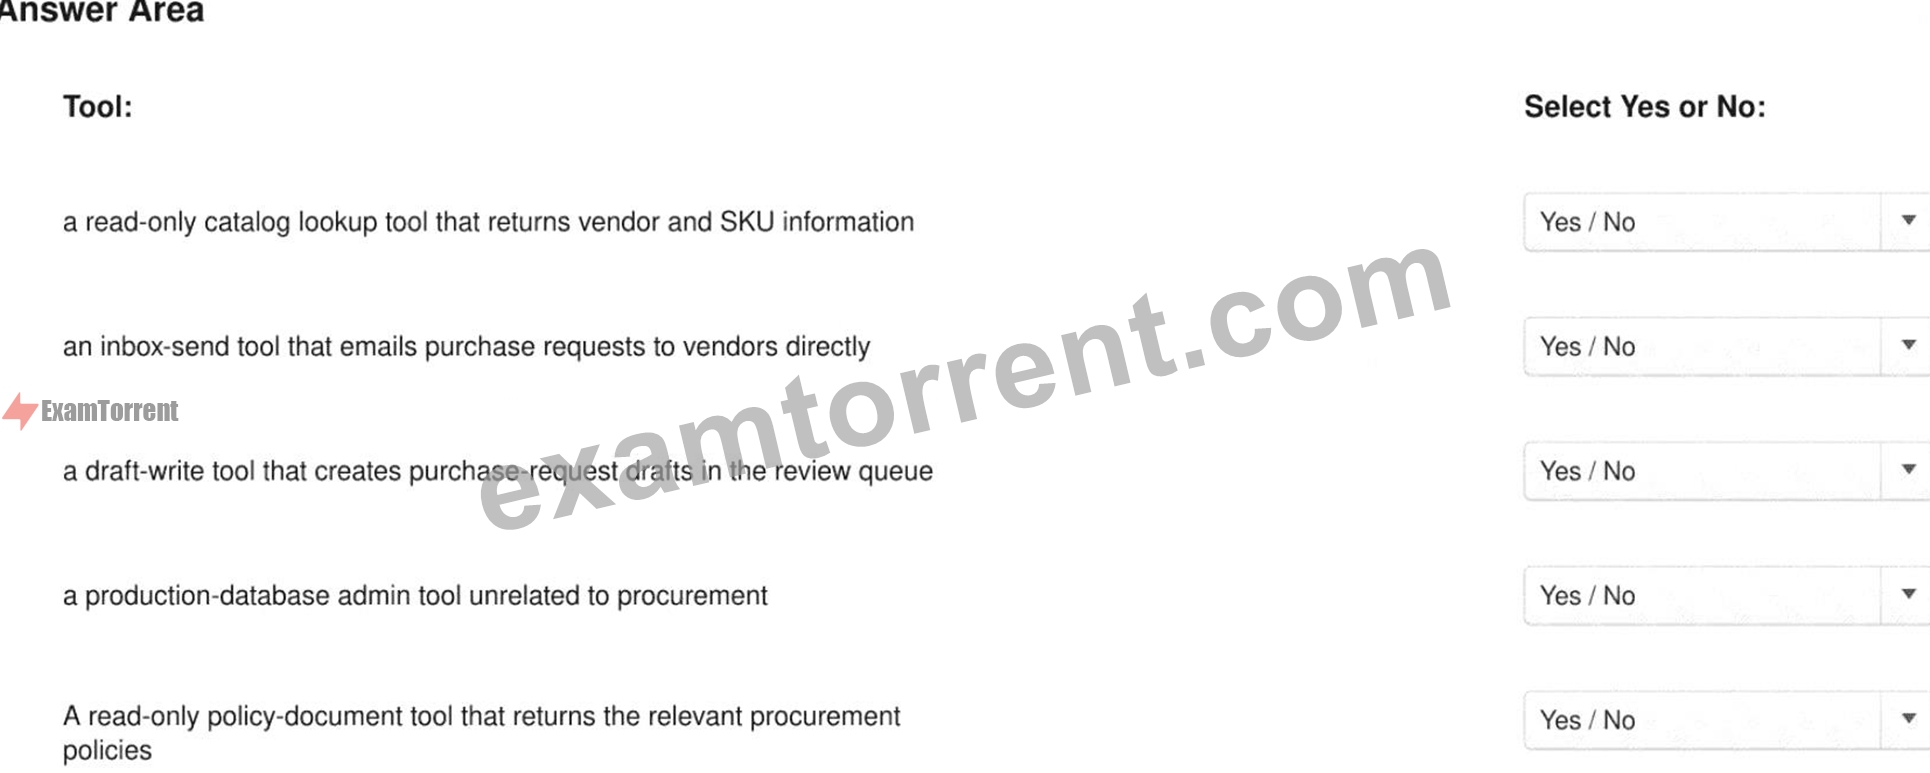
Answer:
Explanation: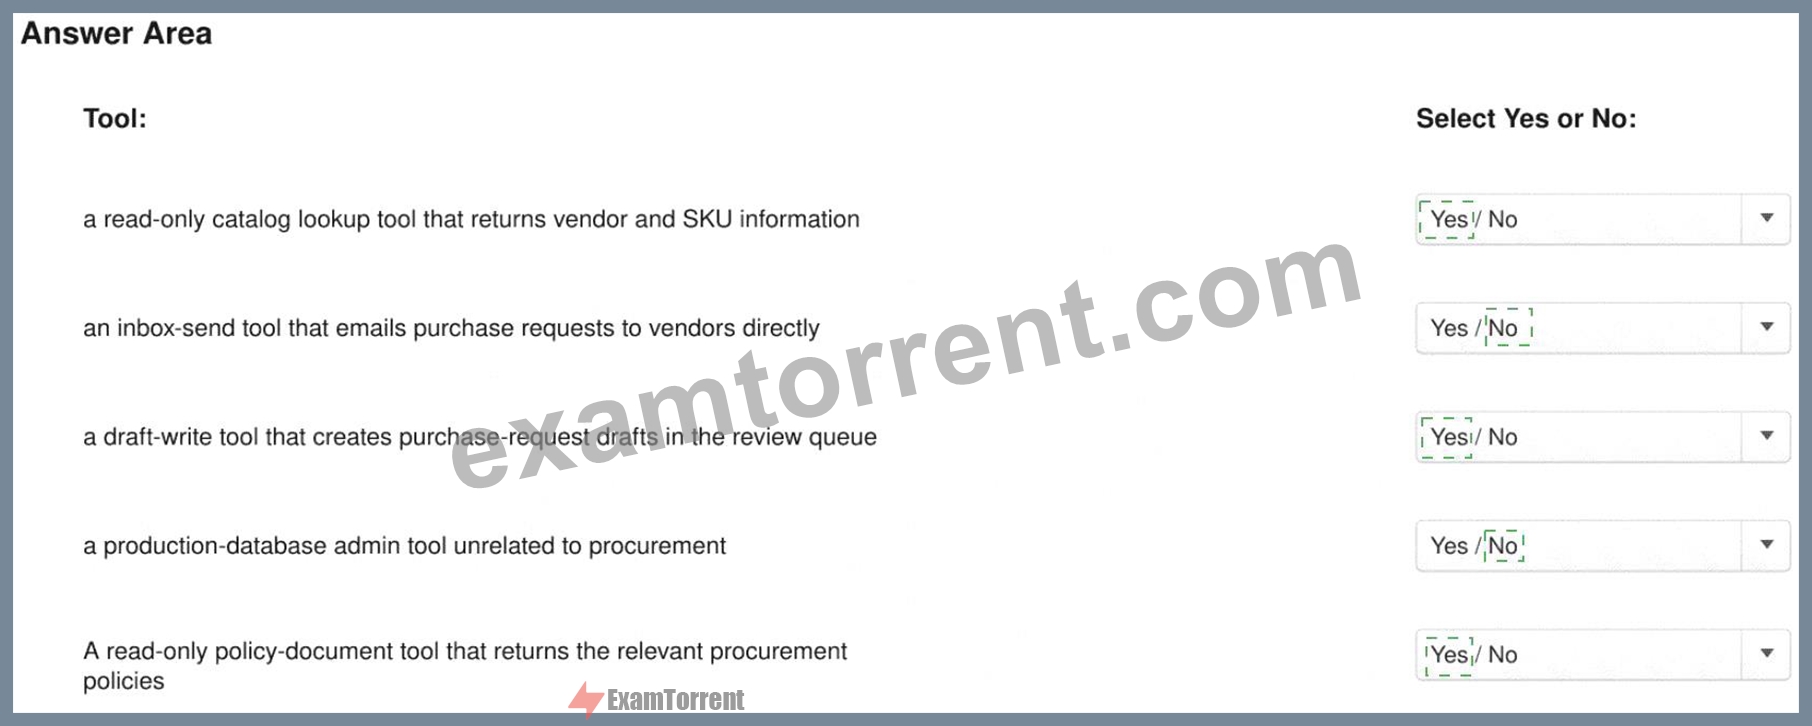
Explanation:
Yes, No, Yes, No, Yes
Least privilege requires each retained tool to be necessary for the agent's assigned responsibility and restricted to the minimum action level needed. Catalog lookup is appropriate because vendor and SKU information is needed to prepare an accurate request. The policy-document tool is similarly justified because the agent must ground the draft in applicable procurement rules. The draft-write tool is also aligned because it writes only to a review queue, preserving the required human approval boundary.
The inbox-send tool exceeds the stated responsibility. Sending a request directly to a vendor converts a drafting assistant into an externally acting purchasing agent and bypasses the review stage. The production- database administrator tool is unrelated to procurement and introduces unnecessary destructive capability, privilege-escalation exposure, and potential data-access risk.
Anthropic's prompt-injection guidance recommends limiting access to sensitive data and actions and applying least privilege so that a compromised agent can cause minimal damage. Claude Code also supports tool- specific allow, ask, and deny rules that are enforced outside the model. Prompt-Injection Mitigation, Claude Code Permissions Study Guide references/topics: Capability-bloat auditing; least privilege; tool scoping; human review gates; separation of drafting and execution authority.
NEW QUESTION # 60
You are identifying the highest-impact optimization for a deployment whose token cost is dominated by a long, repeated system prompt and a large retrieved context per request.
Which optimization most directly targets the dominant cost driver?
Answer: B
NEW QUESTION # 61
After a prompt-template update, several previously passing test cases now produce unexpected outputs.
Which test type is specifically designed to detect this category of failure?
Answer: C
Explanation:
Regression tests determine whether behavior that previously met requirements still passes after a change. A stable reference set provides identical inputs, expected outcomes, and scoring rules across prompt versions, allowing the team to attribute failures to the update. Integration tests verify interactions among components but may not measure detailed output behavior. Adversarial tests target attacks and misuse cases, while smoke tests establish only that essential system paths remain available. The failed cases should be added to or retained within the regression suite, and the old and new prompt should be compared under the same model, parameters, tools, and retrieval context. Anthropic describes regression evaluations as protection against behavioral backsliding. Demystifying evals for AI agents
NEW QUESTION # 62
A technical team is cataloguing risks specific to Claude's use in a document-grounded Q & A system.
Which two items represent failure modes intrinsic to LLM-based systems rather than generic software defects? (Select two.)
Answer: D,E
Explanation:
Over-refusal and hallucination are characteristic model-behavior risks. An overly broad safety response can reject a legitimate request even when the surrounding application operates correctly. A plausible but unsupported answer is a groundedness failure arising from probabilistic generation and inadequate source adherence. These risks require model-specific evaluations, grounding instructions, citations, verification, and calibrated fallback behavior. Expired certificates, database timeouts, and load-balancer misconfiguration are conventional distributed-system failures that should be addressed through infrastructure monitoring, retries, health checks, and configuration management. Distinguishing these categories matters because ordinary software remediation will not resolve behavioral failures, while prompt changes will not repair infrastructure.
Anthropic's hallucination guidance recommends auditable citations and supporting evidence for generated claims. Reducing hallucinations
NEW QUESTION # 63
......
Three formats of Anthropic CCAR-P practice material are always getting updated according to the content of real Anthropic CCAR-P examination. The 24/7 customer service system is always available for our customers which can solve their queries and help them if they face any issues while using the CCAR-P Exam product. Besides regular updates, ExamTorrent also offer up to 1 year of free real Claude Certified Architect - Professional (CCAR-P) exam questions updates.
Valid CCAR-P Test Forum: https://www.examtorrent.com/CCAR-P-valid-vce-dumps.html