P.S. Free 2026 Databricks Databricks-Generative-AI-Engineer-Associate dumps are available on Google Drive shared by Getcertkey: https://drive.google.com/open?id=1Zc95F37NZRBQG-i4_2Hmr6DlLlLqHx2c
Our Databricks-Generative-AI-Engineer-Associate study materials are different from common study materials, which can motivate you to concentrate on study. Up to now, many people have successfully passed the Databricks-Generative-AI-Engineer-Associate exam with our assistance. So you need to be brave enough to have a try. We can guarantee that you will love learning our Databricks-Generative-AI-Engineer-Associate Preparation engine as long as you have a try on it. And you can free download the demos of our Databricks-Generative-AI-Engineer-Associate learning guide on our website, it is easy, fast and convenient.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Generative AI Engineer Associate |
| Exam Number: | Databricks-Generative-AI-Engineer-Associate |
| Exam Price: | USD 200 |
| Exam Format: | Multiple select, Multiple choice |
| Available Languages: | English |
| Real Exam Qty: | 45-60 |
| Certificate Validity Period: | 2 years |
| Exam Duration: | 90 minutes |
| Related Certifications: | Databricks Certified Machine Learning Associate Databricks Certified Data Engineer Associate |
| Recommended Training: | Mosaic AI Documentation Databricks Academy - Generative AI Courses |
| Exam Registration: | Databricks Certification Portal |
| Sample Questions: | Databricks Databricks-Generative-AI-Engineer-Associate Sample Questions |
| Exam Way: | Online proctored exam |
| Pre Condition: | No strict prerequisites, but experience with Python, machine learning fundamentals, and Databricks platform is recommended. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification |
>> Valid Databricks-Generative-AI-Engineer-Associate Study Notes <<
Passing the Databricks-Generative-AI-Engineer-Associate exam and obtaining the certification mean opening up a new and fascination phase of your professional career. Just imagine that what a brighter future will be with the Databricks-Generative-AI-Engineer-Associate certification! You may be employed by a bigger enterprise and get a higher position. The income will be doubled for sure. And Our Databricks-Generative-AI-Engineer-Associate study braindumps enable you to meet the demands of the actual certification exam within days. We can claim that with our Databricks-Generative-AI-Engineer-Associate practice guide for 20 to 30 hours, you are able to attend the exam with confidence.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 50
A Generative AI Engineer is building an LLM to generate article summaries in the form of a type of poem, such as a haiku, given the article content. However, the initial output from the LLM does not match the desired tone or style.
Which approach will NOT improve the LLM's response to achieve the desired response?
Answer: C
Explanation:
The task at hand is to improve the LLM's ability to generate poem-like article summaries with the desired tone and style. Using aneutralizerto normalize the tone and style of the underlying documents (option B) will not help improve the LLM's ability to generate the desired poetic style. Here's why:
* Neutralizing Underlying Documents:A neutralizer aims to reduce or standardize the tone of input data. However, this contradicts the goal, which is to generate text with aspecific tone and style(like haikus). Neutralizing the source documents will strip away the richness of the content, making it harder for the LLM to generate creative, stylistic outputs like poems.
* Why Other Options Improve Results:
* A (Explicit Instructions in the Prompt): Directly instructing the LLM to generate text in a specific tone and style helps align the output with the desired format (e.g., haikus). This is a common and effective technique in prompt engineering.
* C (Few-shot Examples): Providing examples of the desired output format helps the LLM understand the expected tone and structure, making it easier to generate similar outputs.
* D (Fine-tuning the LLM): Fine-tuning the model on a dataset that contains examples of the desired tone and style is a powerful way to improve the model's ability to generate outputs that match the target format.
Therefore, using a neutralizer (option B) isnotan effective method for achieving the goal of generating stylized poetic summaries.
NEW QUESTION # 51
When developing an LLM application, it's crucial to ensure that the data used for training the model complies with licensing requirements to avoid legal risks.
Which action is NOT appropriate to avoid legal risks?
Answer: B
Explanation:
* Problem Context: When using data to train a model, it's essential to ensure compliance with licensing to avoid legal risks. Legal issues can arise from using data without permission, especially when it comes from third-party sources.
* Explanation of Options:
* Option A: Reaching out to data curatorsbeforeusing the data is an appropriate action. This allows you to ensure you have permission or understand the licensing terms before starting to use the data in your model.
* Option B: Usingoriginal datathat you personally created is always a safe option. Since you have full ownership over the data, there are no legal risks, as you control the licensing.
* Option C: Using data that is explicitly labeled with an open license and adhering to the license terms is a correct and recommended approach. This ensures compliance with legal requirements.
* Option D: Reaching out to the data curatorsafteryou have already started using the trained model isnot appropriate. If you've already used the data without understanding its licensing terms, you may have already violated the terms of use, which could lead to legal complications. It's essential to clarify the licensing termsbeforeusing the data, not after.
Thus,Option Dis not appropriate because it could expose you to legal risks by using the data without first obtaining the proper licensing permissions.
NEW QUESTION # 52
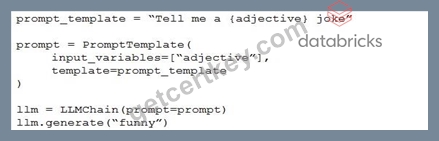
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.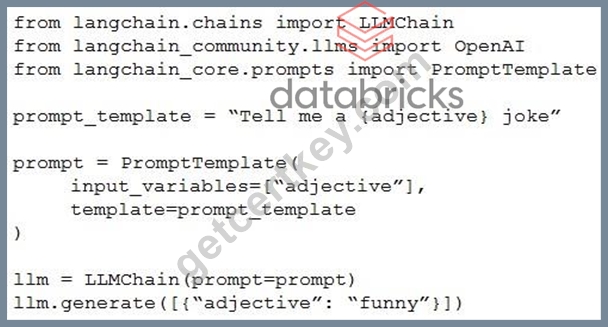
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
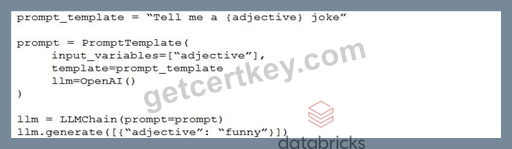
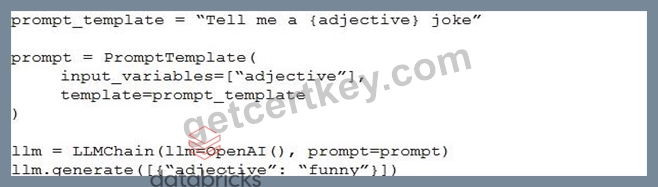
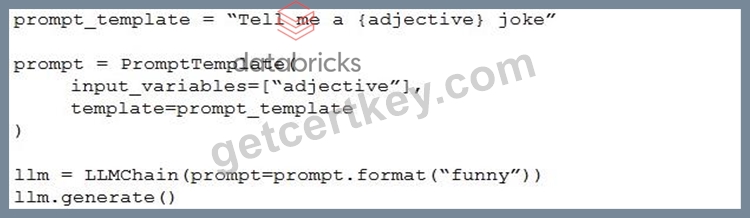
Answer: A
Explanation:
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here's a detailed breakdown of why Option C is the right choice and how it addresses the issue:
Proper Initialization: In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
Correct Use of Classes and Methods:
The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
Option A: Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
Option B: Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
Option D: Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain's architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
NEW QUESTION # 53
A Generative AI Engineer is deploying an agent using Mosaic AI Model Serving. The agent needs to access various Databricks resources, including Vector Search, Databricks SQL, and Functions. They need to find the easiest and best-practice way to authenticate the deployed agent to access these resources.
What approach should they choose?
Answer: A
NEW QUESTION # 54
A Generative AI Engineer I using the code below to test setting up a vector store: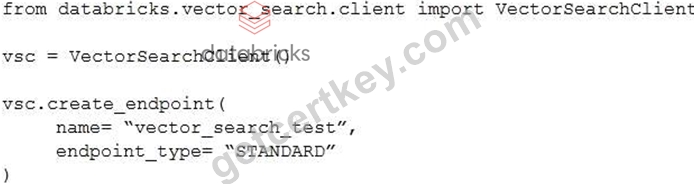
Assuming they intend to use Databricks managed embeddings with the default embedding model, what should be the next logical function call?
Answer: C
Explanation:
Context : The Generative AI Engineer is setting up a vector store using Databricks ' VectorSearchClient.
This is typically done to enable fast and efficient retrieval of vectorized data for tasks like similarity searches.
Explanation of Options :
* Option A: vsc.get_index() : This function would be used to retrieve an existing index, not create one, so it would not be the logical next step immediately after creating an endpoint.
* Option B: vsc.create_delta_sync_index() : After setting up a vector store endpoint, creating an index is necessary to start populating and organizing the data. The create_delta_sync_index() function specifically creates an index that synchronizes with a Delta table, allowing automatic updates as the data changes. This is likely the most appropriate choice if the engineer plans to use dynamic data that is updated over time.
* Option C: vsc.create_direct_access_index() : This function would create an index that directly accesses the data without synchronization. While also a valid approach, it ' s less likely to be the next logical step if the default setup (typically accommodating changes) is intended.
* Option D: vsc.similarity_search() : This function would be used to perform searches on an existing index; however, an index needs to be created and populated with data before any search can be conducted.
Given the typical workflow in setting up a vector store, the next step after creating an endpoint is to establish an index, particularly one that synchronizes with ongoing data updates, hence Option B .
NEW QUESTION # 55
......
Databricks-Generative-AI-Engineer-Associate Latest Exam Cost: https://www.getcertkey.com/Databricks-Generative-AI-Engineer-Associate_braindumps.html
What's more, part of that Getcertkey Databricks-Generative-AI-Engineer-Associate dumps now are free: https://drive.google.com/open?id=1Zc95F37NZRBQG-i4_2Hmr6DlLlLqHx2c