NCP-AIO Reliable Exam Online - NCP-AIO PDF Download

What's more, part of that GuideTorrent NCP-AIO dumps now are free: https://drive.google.com/open?id=1EggWZ-ueJN_dm2Qk5KlawlyZ6MwDMHja
We develop many reliable customers with our high quality NCP-AIO prep guide. When they need the similar exam materials and they place the second even the third order because they are inclining to our NCP-AIO study braindumps in preference to almost any other. Compared with those uninformed exam candidates who do not have effective preparing guide like our NCP-AIO study braindumps, you have already won than them. Among wide array of choices, our products are absolutely perfect. Besides, from economic perspective, our NCP-AIO Real Questions are priced reasonably so we made a balance between delivering satisfaction to customers and doing our own jobs. So in this critical moment, our NCP-AIO prep guide will make you satisfied.
NVIDIA NCP-AIO Exam Overview:
| Certification Vendor: | NVIDIA |
|---|
| Exam Name: | NVIDIA-Certified Professional: AI Operations Exam |
|---|
| Exam Number: | NCP-AIO |
|---|
| Exam Price: | $500 USD |
|---|
| Real Exam Qty: | 30–75 |
|---|
| Available Languages: | English |
|---|
| Exam Duration: | 120 minutes |
|---|
| Exam Format: | Hands-on lab exercises, Multiple choice, Scenario-based |
|---|
| Passing Score: | Pass/Fail (not officially disclosed) |
|---|
| Certificate Validity Period: | 2 years |
|---|
| Related Certifications: | NVIDIA-Certified Associate: AI Infrastructure and Operations (NCA-AIIO)
NVIDIA-Certified Professional: AI Networking (NCP-AIN)
NVIDIA-Certified Professional: AI Infrastructure (NCP-AII) |
|---|
| Recommended Training: | NVIDIA AI Operations Training |
|---|
| Exam Registration: | NVIDIA Certification Portal
Certiverse Exam Platform |
|---|
| Sample Questions: | NVIDIA NCP-AIO Sample Questions |
|---|
| Exam Way: | Online remote proctored exam |
|---|
| Pre Condition: | Recommended: 2–3 years of experience managing AI infrastructure, GPU systems, or data center operations; familiarity with Kubernetes, containers, and NVIDIA software stack |
|---|
| Official Syllabus URL: | https://www.nvidia.com/en-us/learn/certification/ai-operations-professional/ |
|---|
>> NCP-AIO Reliable Exam Online <<
NVIDIA NCP-AIO PDF Download & Best NCP-AIO Vce
Our NVIDIA NCP-AIO can help you clear exams at first shot. We promise that we provide you with best quality NVIDIA NCP-AIO original questions and competitive prices. We provide one year studying assist service and one year free updates downloading of NVIDIA AI Operations exam questions.
| Topic | Details |
|---|
| Topic 1 | - Administration: This section of the exam measures the skills of system administrators and covers essential tasks in managing AI workloads within data centers. Candidates are expected to understand fleet command, Slurm cluster management, and overall data center architecture specific to AI environments. It also includes knowledge of Base Command Manager (BCM), cluster provisioning, Run.ai administration, and configuration of Multi-Instance GPU (MIG) for both AI and high-performance computing applications.
|
| Topic 2 | - Troubleshooting and Optimization: NVIThis section of the exam measures the skills of AI infrastructure engineers and focuses on diagnosing and resolving technical issues that arise in advanced AI systems. Topics include troubleshooting Docker, the Fabric Manager service for NVIDIA NVlink and NVSwitch systems, Base Command Manager, and Magnum IO components. Candidates must also demonstrate the ability to identify and solve storage performance issues, ensuring optimized performance across AI workloads.
|
| Topic 3 | - Installation and Deployment: This section of the exam measures the skills of system administrators and addresses core practices for installing and deploying infrastructure. Candidates are tested on installing and configuring Base Command Manager, initializing Kubernetes on NVIDIA hosts, and deploying containers from NVIDIA NGC as well as cloud VMI containers. The section also covers understanding storage requirements in AI data centers and deploying DOCA services on DPU Arm processors, ensuring robust setup of AI-driven environments.
|
| Topic 4 | - Workload Management: This section of the exam measures the skills of AI infrastructure engineers and focuses on managing workloads effectively in AI environments. It evaluates the ability to administer Kubernetes clusters, maintain workload efficiency, and apply system management tools to troubleshoot operational issues. Emphasis is placed on ensuring that workloads run smoothly across different environments in alignment with NVIDIA technologies.
|
NVIDIA AI Operations Sample Questions (Q77-Q82):
NEW QUESTION # 77
You need to deploy a containerized AI application from NGC using a CI/CD pipeline. The pipeline should automatically build, test, and deploy the container image to a Kubernetes cluster whenever changes are pushed to the code repository. Which of the following CI/CD tools and practices are most suitable for this scenario?
- A. Integrate NVIDIA GPU Cloud (NGC) CLI into the CIICD pipeline to fetch and deploy pre-built containers.
- B. Use Jenkins with the Docker plugin to build the image and 'kubectl apply' to deploy it.
- C. Use AWS CodePipeline with AWS CodeBuild to build the image and AWS Elastic Kubernetes Service (EKS) to deploy the application.
- D. Employ CircleCl with a custom script to build the image and directly push it to the container registry.
- E. Utilize GitLab CI/CD with kaniko to build the image and Helm to manage deployments.
Answer: A,C,E
Explanation:
B, D and E are the correct. GitLab CI/CD with kaniko and Helm provides a robust and scalable solution for building and deploying container images. NGC CLI allows fetching and deploying pre-built containers, simplifying the process. AWS CodePipeline, CodeBuild, and EKS offer a complete CI/CD solution within the AWS ecosystem. Option A is a valid but less modern approach. Option C lacks a structured deployment process.
NEW QUESTION # 78
A cloud engineer is looking to provision a virtual machine for machine learning using the NVIDIA Virtual Machine Image (VMI) and Rapids.
What technology stack will be set up for the development team automatically when the VMI is deployed?
- A. Ubuntu Server, Docker-CE, NVIDIA Container Toolkit, CSP CLI, NGC CLI, NVIDIA Driver, Rapids
- B. Ubuntu Server, Docker-CE, NVIDIA Container Toolkit, CSP CLI, NGC CLI
- C. Cent OS, Docker-CE, NVIDIA Container Toolkit, CSP CLI, NGC CLI
- D. Ubuntu Server, Docker-CE, NVIDIA Container Toolkit, CSP CLI, NGC CLI, NVIDIA Driver
Answer: A
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
The NVIDIA Virtual Machine Image (VMI) for machine learning provisioning automatically sets up anUbuntu Serverenvironment with essential components including Docker-CE, NVIDIA Container Toolkit, CSP CLI, NGC CLI, NVIDIA Driver, andRapids-a suite of GPU-accelerated data science and analytics libraries. This comprehensive stack enables immediate development and deployment of ML workloads.
NEW QUESTION # 79
A user submits a Slurm job script with the following options:
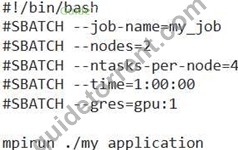
Assuming each node has 4 GPUs, how many GPU resources will be allocated to this job across the entire cluster?
Answer: E
Explanation:
The job requests 2 nodes (nodes=2) and one GPU per node Therefore, a total of 2 GPUs (2 nodes 1 GPU/node) will be allocated to the job.
NEW QUESTION # 80
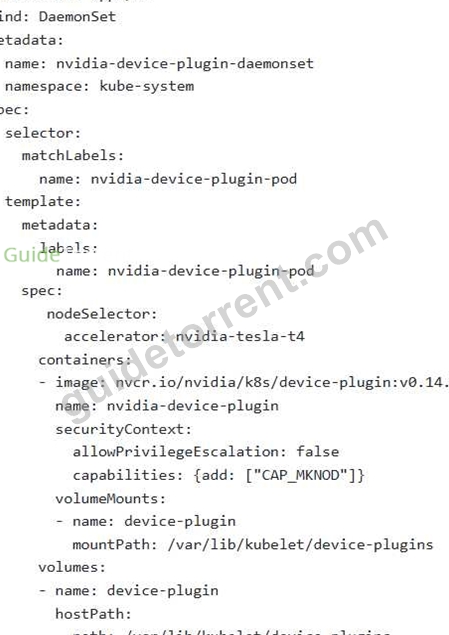
Consider this YAML snippet for deploying the NVIDIA device plugin. Which statement is true about the highlighted segment?
- A. This will ensure that the pod is only deployed on the node with certain taints, but with no other scheduling requirements
- B. It will make sure that only tolerations are set, but there's no affinity.
- C. It will make sure that the device plugin gets deployed on nodes with 'accelerator: nvidia-tesla-t4' label
- D. It's a deprecated way of defining affinities. Consider using nodeAffinity instead.
- E. It will make sure that the node affinity is ignored during scheduling.
Answer: C
Explanation:
The 'nodeselector' is used to target the deployment to nodes with label 'accelerator: nvidia-tesla-t4'. "nodeAffinity' is a more advanced way of doing this and is recommended, but in the absence of explicit nodeAffinity, nodeSelector is sufficient.
NEW QUESTION # 81
Consider the following Kubernetes pod definition:
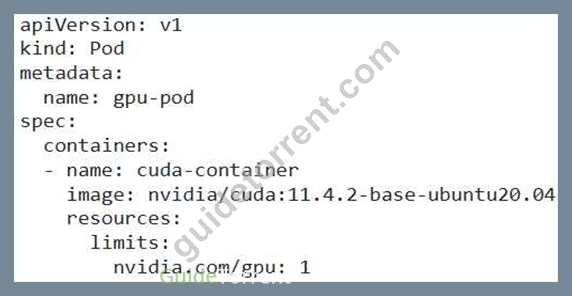
What does the 'nvidia.com/gpu: 1' setting achieve?
- A. It ensures that the pod is scheduled on a node with at least one NVIDIA GPU.
- B. It reserves one virtual GPU (vGPU) instance for the container.
- C. It allocates one full GPU to the container.
- D. It limits the container's GPU memory usage to IGB.
- E. It allows the container to access NVIDIA drivers and libraries.
Answer: A,C,E
Explanation:
The 'nvidia.com/gpu: 1 ' resource request ensures the pod is scheduled on a node with a GPU. It effectively allocates one full GPU to the container (unless using vGPU). It also implicitly provides access to NVIDIA drivers and libraries through the device plugin mechanism. It doesn't directly limit memory usage or reserve vGPU instances; those require additional configurations.
NEW QUESTION # 82
......
NCP-AIO PDF Download: https://www.guidetorrent.com/NCP-AIO-pdf-free-download.html
- Updated NCP-AIO Reliable Exam Online - Pass NCP-AIO Exam 🥱 Download [ NCP-AIO ] for free by simply searching on ⇛ www.examcollectionpass.com ⇚ 💂NCP-AIO Updated Demo
- NCP-AIO Exam Consultant 🐅 NCP-AIO Exam Consultant 🔋 NCP-AIO Exam Vce 👈 Search on ☀ www.pdfvce.com ️☀️ for ➥ NCP-AIO 🡄 to obtain exam materials for free download 🍵Practice NCP-AIO Tests
- NCP-AIO Free Brain Dumps 🥥 NCP-AIO Reliable Test Online 🥱 NCP-AIO Certification Questions 🕝 Simply search for ➤ NCP-AIO ⮘ for free download on ⮆ www.prepawaypdf.com ⮄ 💐NCP-AIO Latest Test Guide
- NCP-AIO Valid Test Vce Free 📄 New NCP-AIO Braindumps Pdf 🎭 NCP-AIO Quiz 😦 Open website ➤ www.pdfvce.com ⮘ and search for ▷ NCP-AIO ◁ for free download 🌗NCP-AIO Latest Test Guide
- Trustable NVIDIA NCP-AIO Reliable Exam Online - NCP-AIO Free Download 🕞 Easily obtain free download of 「 NCP-AIO 」 by searching on ➡ www.dumpsquestion.com ️⬅️ 😮NCP-AIO Valid Test Vce Free
- NCP-AIO Certification Questions 🍯 NCP-AIO Latest Test Guide 🕥 Practice NCP-AIO Tests ✏ Search for ☀ NCP-AIO ️☀️ and download it for free on { www.pdfvce.com } website 🤐NCP-AIO Reliable Braindumps Free
- NCP-AIO Free Brain Dumps 📝 NCP-AIO Vce Torrent ⚪ NCP-AIO Exam Consultant 🍘 Search for [ NCP-AIO ] and easily obtain a free download on ➽ www.examcollectionpass.com 🢪 📱NCP-AIO Vce Torrent
- Trustable NVIDIA NCP-AIO Reliable Exam Online - NCP-AIO Free Download 🧺 Open ⇛ www.pdfvce.com ⇚ and search for ▷ NCP-AIO ◁ to download exam materials for free 👼NCP-AIO Exam Vce
- Reliable NCP-AIO Reliable Exam Online | Amazing Pass Rate For NCP-AIO: NVIDIA AI Operations | High-quality NCP-AIO PDF Download 😼 Simply search for ⇛ NCP-AIO ⇚ for free download on ➽ www.torrentvce.com 🢪 🖱NCP-AIO Free Brain Dumps
- NCP-AIO Dump Check 💽 NCP-AIO Reliable Braindumps Free 😷 Exam NCP-AIO Vce Format 🙃 Search on ▶ www.pdfvce.com ◀ for 【 NCP-AIO 】 to obtain exam materials for free download 🤲NCP-AIO Updated Demo
- Reliable NCP-AIO Reliable Exam Online | Amazing Pass Rate For NCP-AIO: NVIDIA AI Operations | High-quality NCP-AIO PDF Download 📷 Simply search for 【 NCP-AIO 】 for free download on ▷ www.vce4dumps.com ◁ 💨Exam NCP-AIO Vce Format
- www.twosapp.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, mahsaamini5421.blogspot.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
P.S. Free 2026 NVIDIA NCP-AIO dumps are available on Google Drive shared by GuideTorrent: https://drive.google.com/open?id=1EggWZ-ueJN_dm2Qk5KlawlyZ6MwDMHja