ちなみに、GoShiken DP-100の一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=1nhIVEHmylMVKqV8phTzAkmKEBWcpqsAi
我々の提供する商品はあなたに100%試験に合格できるのを助けることができます。あなたはDP-100試験に合格する自信がないなら、ここであなたに一番優秀の参考資料を推薦します。このサイトであなたは我々の提供するDP-100サンプルを無料でダウンロードすることができます。短時間の学習で最新の試験に合格することができます。
DP-100試験は、データサイエンスの概念に関する候補者の知識と、実際のシナリオでこれらの概念を適用する能力をテストする一連の複数選択質問で構成されています。この試験は困難なように設計されており、候補者は試験を試みる前に十分な時間を費やすことが奨励されています。 Microsoftは、オンラインコース、調査ガイド、練習試験など、候補者が準備できるように、さまざまなトレーニングリソースを提供しています。
Microsoft DP-100認定試験に備えるためには、データサイエンスの概念と技術についての堅固な理解と、Azureツールとサービスの使用経験が必要です。Microsoftは、オンラインコース、練習問題、スタディガイドなど、試験に備えるための様々なトレーニングコースやリソースを提供しています。また、書籍やチュートリアルなどのサードパーティリソースも多数あります。
偉大な事業を実現するために信心を持つ必要があります。あなたは自分の知識レベルを疑っていて試験の準備をする前に詰め込み勉強しているときに、自分がどうやって試験に受かることを確保するかを考えましたか。心配しないでください。GoShikenはあなたがMicrosoftのDP-100認定試験に合格する確保です。GoShiken のトレーニング試験は問題と解答に含まれています。しかも100パーセントの合格率を保証できます。GoShikenのMicrosoftのDP-100試験トレーニング資料を手に入れたら、あなたは自分の第一歩を進めることができます。試験に合格してから、あなたのキャリアは美しい時期を迎えるようになります。
Microsoft DP-100試験は、Azureに関するデータサイエンスソリューションの設計と実装における候補者の知識とスキルを検証する認定テストです。この試験は、Azure Servicesを使用してインテリジェントソリューションの構築と展開の専門知識を紹介したいデータサイエンティスト、データエンジニア、およびAI開発者に最適です。 DP-100試験では、データの調査と準備、モデリング、機能エンジニアリング、機械学習など、データサイエンスのコア概念に焦点を当てています。
質問 # 301
You have an Azure Machine Learning workspace and a collection of image files stored in two Azure Blob Storage accounts. You need to configure data asset properties Which values should you use in your configuration? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.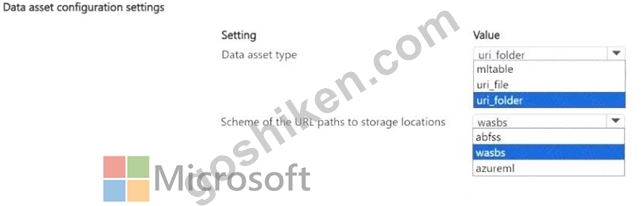
正解:
解説: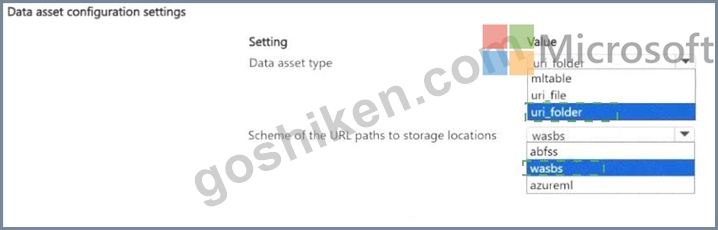
Explanation: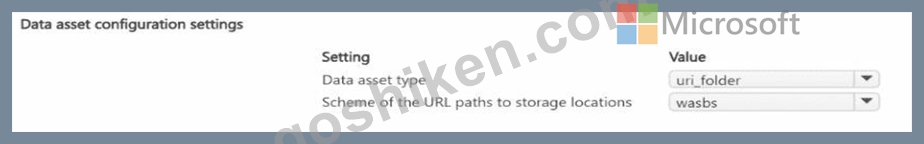
質問 # 302
You need to correct the model fit issue.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.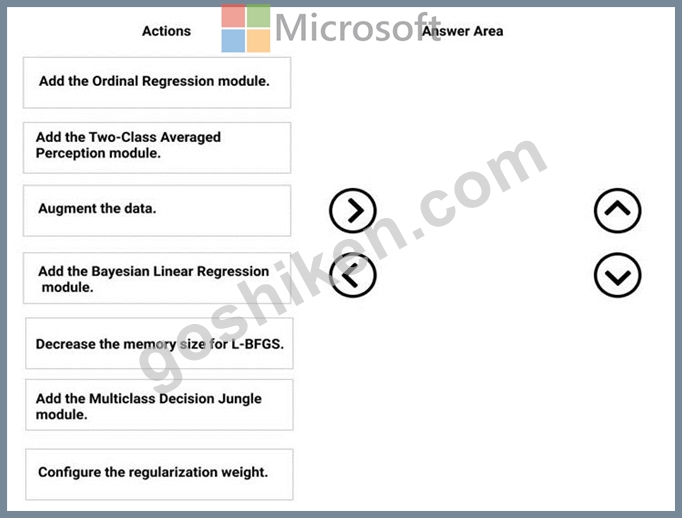
正解:
解説: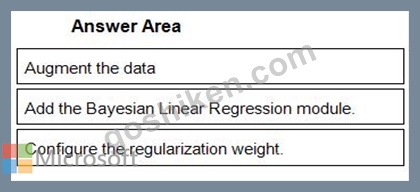
1 - Augment the data
2 - Add the Bayesian Linear Regression module.
3 - Configure the regularization weight.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/linear-regr ession
Topic 2,
Overview
You are a data scientist in a company that provides data science for professional sporting events. Models will be global and local market data to meet the following business goals:
* Understand sentiment of mobile device users at sporting events based on audio from crowd reactions.
* Access a user's tendency to respond to an advertisement.
* Customize styles of ads served on mobile devices.
* Use video to detect penalty events.
Current environment
Requirements
* Media used for penalty event detection will be provided by consumer devices. Media may include images and videos captured during the sporting event and snared using social media. The images and videos will have varying sizes and formats.
* The data available for model building comprises of seven years of sporting event media. The sporting event media includes: recorded videos, transcripts of radio commentary, and logs from related social media feeds feeds captured during the sporting events.
* Crowd sentiment will include audio recordings submitted by event attendees in both mono and stereo Formats.
Advertisements
* Ad response models must be trained at the beginning of each event and applied during the sporting event.
* Market segmentation nxxlels must optimize for similar ad resporr.r history.
* Sampling must guarantee mutual and collective exclusivity local and global segmentation models that share the same features.
* Local market segmentation models will be applied before determining a user's propensity to respond to an advertisement.
* Data scientists must be able to detect model degradation and decay.
* Ad response models must support non linear boundaries features.
* The ad propensity model uses a cut threshold is 0.45 and retrains occur if weighted Kappa deviates from 0.1 +/-5%.
* The ad propensity model uses cost factors shown in the following diagram: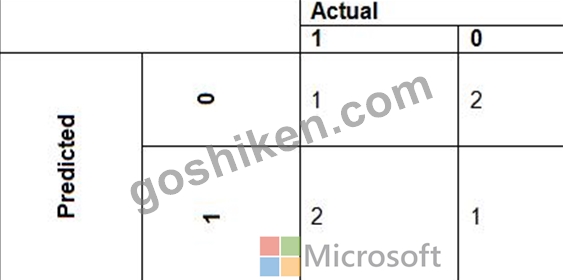
The ad propensity model uses proposed cost factors shown in the following diagram: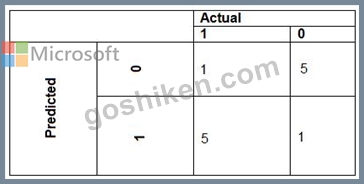
Performance curves of current and proposed cost factor scenarios are shown in the following diagram: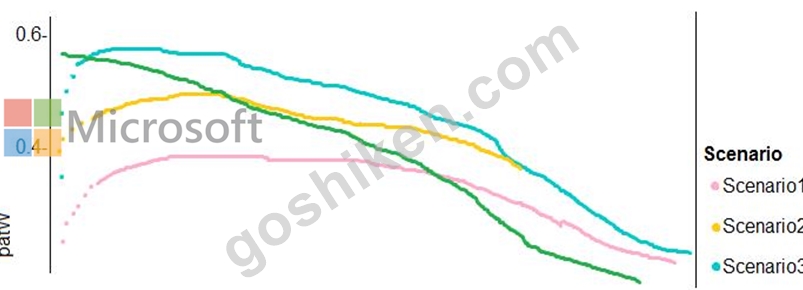
Penalty detection and sentiment
Findings
* Data scientists must build an intelligent solution by using multiple machine learning models for penalty event detection.
* Data scientists must build notebooks in a local environment using automatic feature engineering and model building in machine learning pipelines.
* Notebooks must be deployed to retrain by using Spark instances with dynamic worker allocation
* Notebooks must execute with the same code on new Spark instances to recode only the source of the data.
* Global penalty detection models must be trained by using dynamic runtime graph computation during training.
* Local penalty detection models must be written by using BrainScript.
* Experiments for local crowd sentiment models must combine local penalty detection data.
* Crowd sentiment models must identify known sounds such as cheers and known catch phrases. Individual crowd sentiment models will detect similar sounds.
* All shared features for local models are continuous variables.
* Shared features must use double precision. Subsequent layers must have aggregate running mean and standard deviation metrics Available.
segments
During the initial weeks in production, the following was observed:
* Ad response rates declined.
* Drops were not consistent across ad styles.
* The distribution of features across training and production data are not consistent.
Analysis shows that of the 100 numeric features on user location and behavior, the 47 features that come from location sources are being used as raw features. A suggested experiment to remedy the bias and variance issue is to engineer 10 linearly uncorrected features.
Penalty detection and sentiment
* Initial data discovery shows a wide range of densities of target states in training data used for crowd sentiment models.
* All penalty detection models show inference phases using a Stochastic Gradient Descent (SGD) are running too stow.
* Audio samples show that the length of a catch phrase varies between 25%-47%, depending on region.
* The performance of the global penalty detection models show lower variance but higher bias when comparing training and validation sets. Before implementing any feature changes, you must confirm the bias and variance using all training and validation cases.
質問 # 303
You use the Azure Machine Learning SDK in a notebook to run an experiment using a script file in an experiment folder.
The experiment fails.
You need to troubleshoot the failed experiment.
What are two possible ways to achieve this goal? Each correct answer presents a complete solution.
正解:C、D
解説:
Use get_details_with_logs() to fetch the run details and logs created by the run.
You can monitor Azure Machine Learning runs and view their logs with the Azure Machine Learning studio.
Incorrect Answers:
A: You can view the metrics of a trained model using run.get_metrics().
E: get_output() gets the output of the step as PipelineData.
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-pipeline-core/azureml.pipeline.core.steprun
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-monitor-view-training-logs
質問 # 304
You create a project in the Azure Al Foundry portal.
You must provide a meaningful comparison of benchmark metrics between the text-embedding-ada-002 and text-embedding-3-large models.
You need to select the metncs to use for the X and Y axes in the Metncs to compare pane.
Which metncs should you select? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.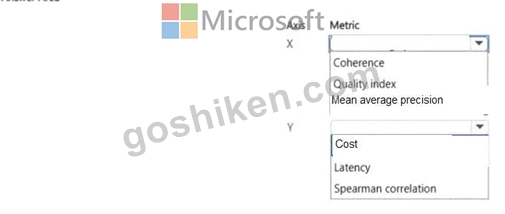
正解:
解説: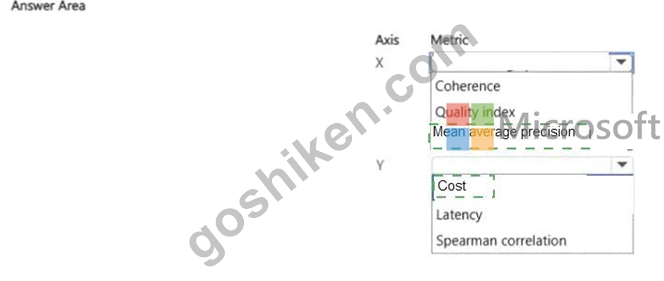
Explanation: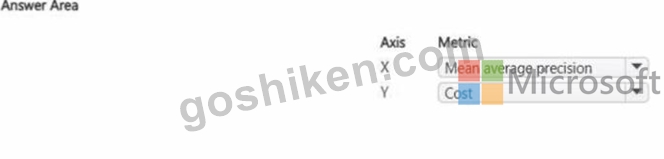
質問 # 305
You have an existing GitHub repository containing Azure Machine Learning project files.
You need to clone the repository to your Azure Machine Learning shared workspace file system.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
NOTE: More than one order of answer choices is correct. You will receive credit for any of the correct orders you select.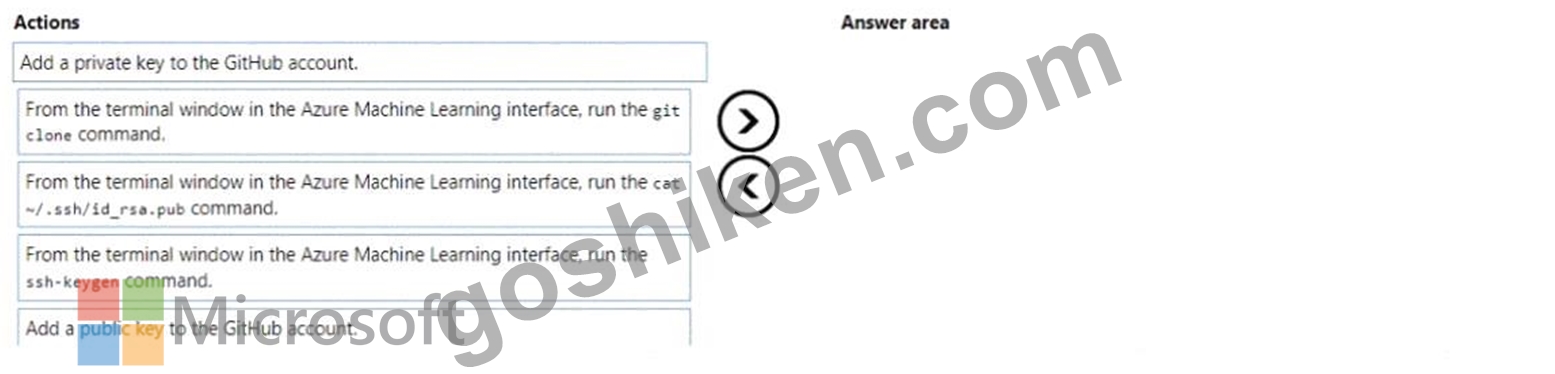
正解:
解説: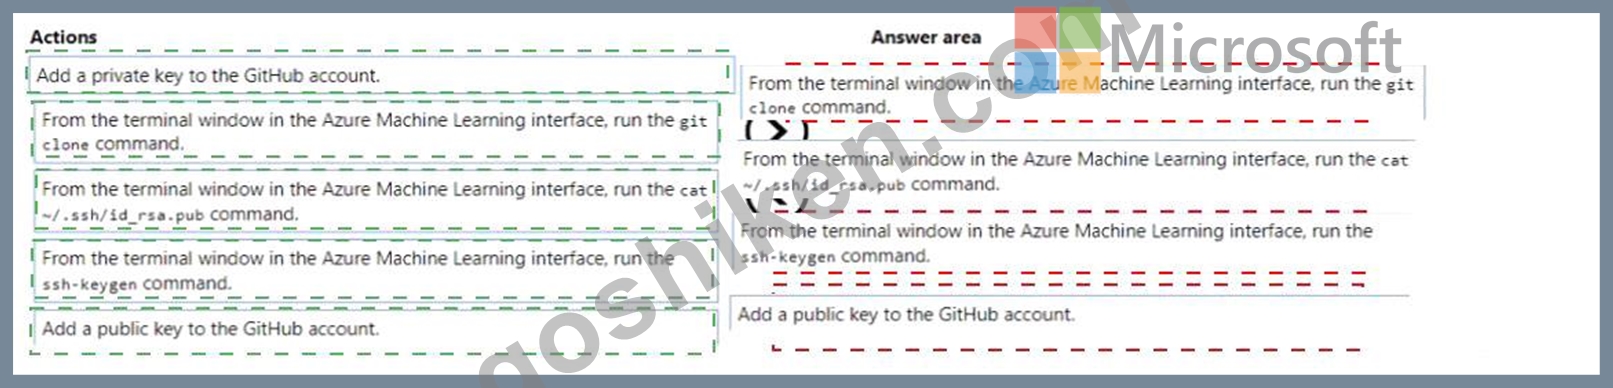
Explanation: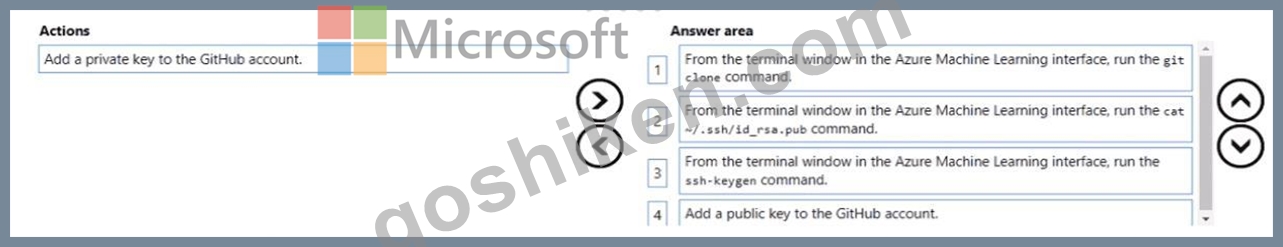
質問 # 306
......
DP-100合格対策: https://www.goshiken.com/Microsoft/DP-100-mondaishu.html
さらに、GoShiken DP-100ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1nhIVEHmylMVKqV8phTzAkmKEBWcpqsAi