DOWNLOAD the newest Actual4test Databricks-Generative-AI-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1K7fgqR3KkD4xzkr3LLPdoYSNNRVPSCoz
We believe you will also competent enough to cope with demanding and professorial work with competence with the help of our Databricks-Generative-AI-Engineer-Associate exam braindumps. Our experts made a rigorously study of professional knowledge about this Databricks-Generative-AI-Engineer-Associate exam. So do not splurge time on searching for the perfect practice materials, because our Databricks-Generative-AI-Engineer-Associate Guide materials are exactly what you need to have. Just come and buy our Databricks-Generative-AI-Engineer-Associate practice guide, you will be a winner!
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
>> Dumps Databricks-Generative-AI-Engineer-Associate Collection <<
Actual4test can promise that our Databricks-Generative-AI-Engineer-Associate training material have a higher quality when compared with other study materials. With over a decade's business experience, our Databricks-Generative-AI-Engineer-Associate study tool has attached great importance to customers' purchasing rights all along. The Databricks-Generative-AI-Engineer-Associate study materials of our website do not affect the user's normal working and learning, and greatly improves the utilization rate of time, killing two birds with one stone. It is no doubt that our study materials will help you pass your Databricks-Generative-AI-Engineer-Associate Exam in a shortest time.
NEW QUESTION # 49
A company has a typical RAG-enabled, customer-facing chatbot on its website.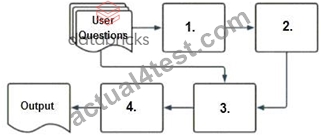
Select the correct sequence of components a user's questions will go through before the final output is returned. Use the diagram above for reference.
Answer: D
Explanation:
To understand how a typical RAG-enabled customer-facing chatbot processes a user's question, let's go through the correct sequence as depicted in the diagram and explained in option A:
* Embedding Model (1):The first step involves the user's question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
* Vector Search (2):The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
* Context-Augmented Prompt (3):The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
* Response-Generating LLM (4):Finally, the context-augmented prompt is fed into a response- generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable:
* B, C, D: These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence isembedding model, vector search, context-augmented prompt, response- generating LLM, which is option A.
NEW QUESTION # 50
Which TWO chain components are required for building a basic LLM-enabled chat application that includes conversational capabilities, knowledge retrieval, and contextual memory?
Answer: B,F
Explanation:
Building a basic LLM-enabled chat application with conversational capabilities, knowledge retrieval, and contextual memory requires specific components that work together to process queries, maintain context, and retrieve relevant information. Databricks' Generative AI Engineer documentation outlines key components for such systems, particularly in the context of frameworks like LangChain or Databricks' MosaicML integrations. Let's evaluate the required components:
* Understanding the Requirements :
* Conversational capabilities : The app must generate natural, coherent responses.
* Knowledge retrieval : It must access external or domain-specific knowledge.
* Contextual memory : It must remember prior interactions in the conversation.
* Databricks Reference: " A typical LLM chat application includes a memory component to track conversation history and a retrieval mechanism to incorporate external knowledge " ( " Databricks Generative AI Cookbook, " 2023).
* Evaluating the Options :
* A. (Q) : This appears incomplete or unclear (possibly a typo). Without further context, it's not a valid component.
* B. Vector Stores : These store embeddings of documents or knowledge bases, enabling semantic search and retrieval of relevant information for the LLM. This is critical for knowledge retrieval in a chat application.
* Databricks Reference : " Vector stores, such as those integrated with Databricks' Lakehouse, enable efficient retrieval of contextual data for LLMs " ( " Building LLM Applications with Databricks " ).
* C. Conversation Buffer Memory : This component stores the conversation history, allowing the LLM to maintain context across multiple turns. It's essential for contextual memory.
* Databricks Reference : " Conversation Buffer Memory tracks prior user inputs and LLM outputs, ensuring context-aware responses " ( " Generative AI Engineer Guide " ).
* D. External tools : These (e.g., APIs or calculators) enhance functionality but aren't required for a basic chat app with the specified capabilities.
* E. Chat loaders : These might refer to data loaders for chat logs, but they're not a core chain component for conversational functionality or memory.
* F. React Components : These relate to front-end UI development, not the LLM chain's backend functionality.
* Selecting the Two Required Components :
* For knowledge retrieval , Vector Stores (B) are necessary to fetch relevant external data, a cornerstone of Databricks' RAG-based chat systems.
* For contextual memory , Conversation Buffer Memory (C) is required to maintain conversation history, ensuring coherent and context-aware responses.
* While an LLM itself is implied as the core generator, the question asks for chain components beyond the model, making B and C the minimal yet sufficient pair for a basic application.
Conclusion : The two required chain components are B. Vector Stores and C. Conversation Buffer Memory
, as they directly address knowledge retrieval and contextual memory, respectively, aligning with Databricks' documented best practices for LLM-enabled chat applications.
NEW QUESTION # 51
A Generative AI Engineer is building a Databricks-hosted assistant that must (1) query Unity Catalog tables with row and column permissions enforced, and (2) avoid managing any external infrastructure. The team wants the LLM to use governed data access through tools exposed via MCP.
Which MCP server choice meets these constraints?
Answer: D
Explanation:
A managed Databricks MCP server provides tools for accessing Databricks services without requiring the team to host an external server. For structured table queries, a suitable managed SQL or Genie tool uses Databricks-governed data access. Unity Catalog remains responsible for authorization instead of delegating security decisions to the language model. When permissions must reflect the individual requester, the application must use the appropriate user authorization configuration so row filters and column masks are evaluated for that identity. Passing credentials in prompts exposes secrets unnecessarily. A self-managed virtual machine violates the infrastructure requirement. Direct JDBC access also fails the requested MCP architecture and introduces custom integration work. Managed hosting simplifies deployment while preserving the platform's access-control model. Databricks tools documentation , authentication documentation
NEW QUESTION # 52
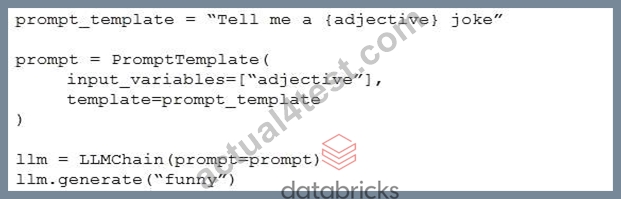
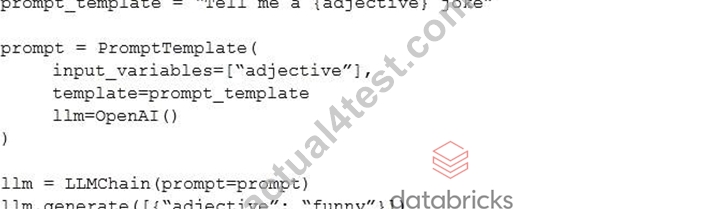
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.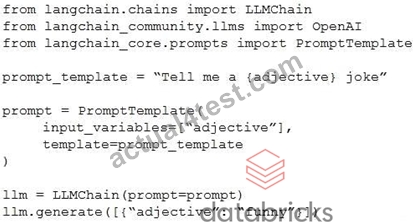
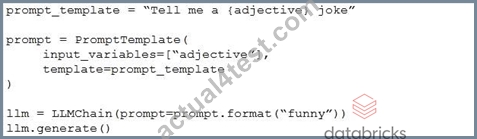
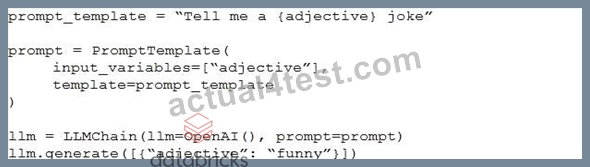
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?
Answer: D
Explanation:
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here's a detailed breakdown of why Option C is the right choice and how it addresses the issue:
* Proper Initialization: In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
* Correct Use of Classes and Methods:
* The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
* The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
* The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
* Option A: Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
* Option B: Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
* Option D: Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain's architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
NEW QUESTION # 53
A small and cost-conscious startup in the cancer research field wants to build a RAG application using Foundation Model APIs.
Which strategy would allow the startup to build a good-quality RAG application while being cost-conscious and able to cater to customer needs?
Answer: D
Explanation:
For a small, cost-conscious startup in the cancer research field, choosing a domain-specific and smaller LLM is the most effective strategy. Here's whyBis the best choice:
* Domain-specific performance: A smaller LLM that has been fine-tuned for the domain of cancer research will outperform a general-purpose LLM for specialized queries. This ensures high-quality responses without needing to rely on a large, expensive LLM.
* Cost-efficiency: Smaller models are cheaper to run, both in terms of compute resources and API usage costs. A domain-specific smaller LLM can deliver good quality responses without the need for the extensive computational power required by larger models.
* Focused knowledge: In a specialized field like cancer research, having an LLM tailored to the subject matter provides better relevance and accuracy for queries, while keeping costs low.Large, general- purpose LLMs may provide irrelevant information, leading to inefficiency and higher costs.
This approach allows the startup to balance quality, cost, and customer satisfaction effectively, making it the most suitable strategy.
NEW QUESTION # 54
......
Our Databricks training materials are famous at home and abroad, the main reason is because we have other companies that do not have core competitiveness, there are many complicated similar products on the market, if you want to stand out is the selling point of needs its own. Our Databricks-Generative-AI-Engineer-Associate test question with other product of different thing is we have the most core expert team to update our Databricks-Generative-AI-Engineer-Associate study materials, learning platform to changes with the change of the exam outline. If not timely updating Databricks-Generative-AI-Engineer-Associate Training Materials will let users reduce the learning efficiency of even lags behind that of other competitors, the consequence is that users and we don't want to see the phenomenon of the worst, so in order to prevent the occurrence of this kind of risk, the Databricks-Generative-AI-Engineer-Associate practice test dump give supervision and update the progress every day, it emphasized the key selling point of the product.
PDF Databricks-Generative-AI-Engineer-Associate Cram Exam: https://www.actual4test.com/Databricks-Generative-AI-Engineer-Associate_examcollection.html
2026 Latest Actual4test Databricks-Generative-AI-Engineer-Associate PDF Dumps and Databricks-Generative-AI-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1K7fgqR3KkD4xzkr3LLPdoYSNNRVPSCoz