DOWNLOAD the newest TestKingFree SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=10KfY4u_islmOXBZt0N8lmQvfu1HZAoVp
Individuals who hold Snowflake SPS-C01 certification exam demonstrate to their employers and clients that they have the knowledge and skills necessary to succeed in the SPS-C01 exam. TestKingFree SPS-C01 Questions have numerous benefits, including the ability to demonstrate to employers and clients that you have the necessary knowledge and skills to succeed in the actual Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam.
| Section | Weight | Objectives |
|---|---|---|
| Snowpark Concepts and Architecture | 25% | - Snowpark architecture and execution model
|
| Data Transformations and Operations | 35% | - DataFrame manipulation
|
| Snowpark API and Development | 30% | - Multi-language support
|
| Performance and Best Practices | 10% | - Security and governance
|
The aim of our design is to improving your learning and helping you gains your certification in the shortest time. If you long to gain the certification, our Snowflake Certified SnowPro Specialty - Snowpark guide torrent will be your best choice. Many experts and professors consist of our design team, you do not need to be worried about the high quality of our SPS-C01 test torrent. Now our pass rate has reached 99 percent. If you choose our SPS-C01 study torrent as your study tool and learn it carefully, you will find that it will be very soon for you to get the Snowflake Certified SnowPro Specialty - Snowpark certification in a short time. Do not hesitate and buy our SPS-C01 test torrent, it will be very helpful for you.
NEW QUESTION # 308
You are developing a Snowpark application that needs to connect to Snowflake using programmatic access. You want to use a secure method of authentication. Which of the following methods, when passed as parameters to the 'snowpark.Session.builder.configS method, would be MOST secure and appropriate for production environments?
Answer: C,E
Explanation:
Using 'oauth_access_token' and 'private_key' (especially when stored securely) are more secure than directly passing username and password. OAuth and Key Pair authentication are recommended for production environments because they avoid storing or transmitting passwords directly. Options A & B are vulnerable because they expose credentials directly in the code or configuration. Option E is incorrect because simply setting the authenticator does not ensure the user authentication will happen with secure methods. User must use Oauth or Key pair authentication for Production use case.
NEW QUESTION # 309
You are developing a Snowpark application that uses a Python UDF to perform geocoding operations. This UDF relies on a third-party geocoding library and a large dataset of geographical data stored in a file named 'geodata.db'. The UDF needs to be operationalized with minimal latency. Which of the following strategies will result in the FASTEST execution of the UDF and optimal resource utilization?
Answer: E
Explanation:
Option E is the most efficient strategy. Packaging the library and data file in a ZIP, referencing it with 'imports' , and using a global variable with caching within the UDF minimizes latency by loading the data only once per worker. It also benefits from utilizing the parallel processing capabilities of Snowpark. Using Java UDF's (C) is less efficient, unless it is highly optimized since java conversion can happen and adds overhead . Relying on external geocoding services (D) introduces network latency and is not ideal for performance. While a custom Anaconda channel (B) can simplify dependency management, it does not address the issue of loading the large 'geodata.db' file efficiently. Option A addresses the dependency managment but performance is not addressed.
NEW QUESTION # 310
You are tasked with processing a Snowpark DataFrame named 'orders df that contains order information. The DataFrame includes the following columns: 'order _ id' (INTEGER), 'customer_id' (INTEGER), 'order_date' (DATE), 'order_total' (STRING), and 'discount_code' (STRING). The 'order_total' column contains values with leading dollar signs and commas (e.g., '$1 ,234.56'). The column can contain codes like 'SAVEIO', 'SAVE20', or be NULL. Your goal is to create a new DataFrame 'transformed_df that includes the following transformations: 1 . Convert the 'order_total' column to a numeric value (DOUBLE) after removing the dollar signs and commas. 2. Apply a discount based on the 'discount_code'. If the 'discount_code' is 'SAVEIO', apply a 10% discount; if it's 'SAVE20', apply a 20% discount. If the 'discount_code' is NULL or any other value, apply no discount (0%). 3. Calculate the 'final_total' after applying the discount. Which of the following code snippets correctly and efficiently implements these transformations using Snowpark?





Answer: C
Explanation:
Option A correctly implements all transformations efficiently using Snowpark functions. It converts 'order_totar to a numeric value, applies the discount based on the using 'when' , and calculates the 'final_totar. It avoids using IJDFs or 'collect' operations, which can be less efficient. Using 'lit' with numeric values isn't necessary or best practice, so option B is less preferable. Option C attempts to use a IJDF, which is less efficient than using built-in Snowpark functions. Also 'to_number' and for IJDF is not required. Option D calculates the discount amount directly instead of the discount rate. Option E attempts to use 'rdd.map' which is not available and it's generally advised against as it removes parallelism.
NEW QUESTION # 311
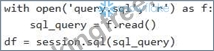
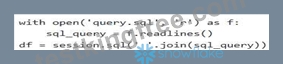
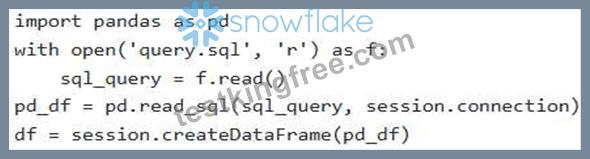
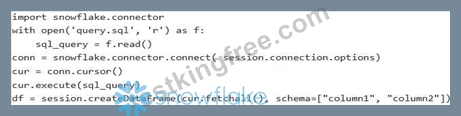
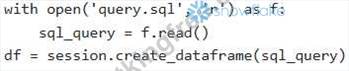
You have a SQL query stored in a file named 'query.sqr which contains several complex analytical calculations. The query depends on a Snowpark 'session' object already established. You want to create a Snowpark DataFrame from the result of this query. Which of the following code snippets achieves this with optimal performance and readability, assuming correct file access permissions?
Answer: A
Explanation:
Option A provides the most straightfomard and efficient approach. It reads the SQL query from the file and directly creates a Snowpark DataFrame using 'session.sql(sql_query)'. Option B introduces Pandas, which is unnecessary and less efficient. Option C uses the Snowflake Connector outside of Snowpark's API, which is generally not the preferred approach. Option D has a non-existent function create_dataframe' , and Option E reads lines separately requiring a join which might be erroneous.
NEW QUESTION # 312
You are tasked with creating a series of Snowpark DataFrames for a data transformation pipeline. For debugging purposes, you want to materialize these DataFrames as tables within Snowflake, but only for the duration of your session. You also need to make sure that these tables are automatically cleaned up when your session ends. Which of the following approaches offer(s) the MOST efficient and appropriate way to achieve this?
Answer: B
Explanation:
Option E is the most efficient and appropriate because it leverages local temporary views. Local temporary views are automatically dropped at the end of the session without requiring explicit cleanup. Option A requires manual cleanup which is prone to errors. Option B involves writing physical tables, even if temporary, which is less efficient than views if you need to access data within the same session and are for debugging only. Option D uses a non-existent 'temporary' option, making it incorrect. Option C makes use of CTE's, but does not persist the data as local temporary tables.
NEW QUESTION # 313
......
Our company has successfully launched the new version of our SPS-C01 exam tool. Perhaps you are deeply bothered by preparing the exam, perhaps you have wanted to give it up. Now, you can totally feel relaxed with the assistance of our SPS-C01 Study Guide. Our SPS-C01 exam dumps are definitely more reliable and excellent than other exam tool. What is more, the passing rate of our SPS-C01 study materials is the highest in the market.
Detailed SPS-C01 Answers: https://www.testkingfree.com/Snowflake/SPS-C01-practice-exam-dumps.html
P.S. Free & New SPS-C01 dumps are available on Google Drive shared by TestKingFree: https://drive.google.com/open?id=10KfY4u_islmOXBZt0N8lmQvfu1HZAoVp