What's more, part of that Real4Prep Databricks-Certified-Professional-Data-Engineer dumps now are free: https://drive.google.com/open?id=19AxaOVGVnTGLPjxMsrc9FK1Imz9_LHxR
Our most wanted version of the DatabricksExam Questions is our PDF eBook, and it is convenient even students can easily use it. Databricks Databricks-Certified-Professional-Data-Engineer pdf questions are printable and portable features make it more convenient the use. You can prepare with Databricks-Certified-Professional-Data-Engineer pdf questions and answers anywhere and anytime. This is the most reliable source of preparation. Our Databricks Databricks-Certified-Professional-Data-Engineer desktop-based practice software is the most helpful version to prepare for Databricks Certified Professional Data Engineer Exam exam as it simulates the real DatabricksCertified Network Professional Data Center certification exam according to the Databricksrules.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
| Exam Price: | USD 200 |
| Real Exam Qty: | 60-70 |
| Related Certifications: | Databricks Certified Data Engineer Associate |
| Exam Duration: | 120 minutes |
| Certificate Validity Period: | 2 years |
| Available Languages: | English |
| Exam Format: | Multiple select, Multiple choice, Scenario-based questions |
| Passing Score: | 70% |
| Recommended Training: | Databricks Academy |
| Exam Registration: | Databricks Certification Portal |
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
| Exam Way: | Online proctored exam |
| Pre Condition: | Recommended: Databricks Certified Data Engineer Associate or equivalent experience with Spark and Databricks platform. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification |
>> Actual Databricks-Certified-Professional-Data-Engineer Tests <<
For your convenience, Real4Prep has prepared authentic Databricks Databricks-Certified-Professional-Data-Engineer Exam study material based on a real exam syllabus to help candidates go through their exams. Candidates who are preparing for the Databricks exam suffer greatly in their search for preparation material.
To prepare for the Databricks Certified Professional Data Engineer exam, candidates can take advantage of the resources provided by Databricks. The company offers training courses, certification study guides, and practice exams to help candidates prepare for the exam. These resources provide an overview of the exam topics and offer hands-on experience with the Databricks platform.
Databricks Certified Professional Data Engineer certification exam is designed for professionals who want to prove their expertise in designing, building, and maintaining data processing systems using Databricks. Databricks is a cloud-based data platform that provides a unified analytics engine for data processing, machine learning, and visualization. Databricks Certified Professional Data Engineer Exam certification exam tests the candidate's knowledge and skills in various areas, including data engineering, data processing, data modeling, and data architecture.
NEW QUESTION # 159
Two of the most common data locations on Databricks are the DBFS root storage and external object storage mounted with dbutils.fs.mount().
Which of the following statements is correct?
Answer: D
Explanation:
DBFS is a file system protocol that allows users to interact with files stored in object storage using syntax and guarantees similar to Unix file systems1. DBFS is not a physical file system, but a layer over the object storage that provides a unified view of data across different data sources1. By default, the DBFS root is accessible to all users in the workspace, and the access to mounted data sources depends on the permissions of the storage account or container2. Mounted storage volumes do not need to have full public read and write permissions, but they do require a valid connection string or access key to be provided when mounting3. Both the DBFS root and mounted storage can be accessed when using %sh in a Databricks notebook, as long as the cluster has FUSE enabled4. The DBFS root does not store files in ephemeral block volumes attached to the driver, but in the object storage associated with the workspace1. Mounted directories will persist saved data to external storage between sessions, unless they are unmounted or deleted3. Reference: DBFS, Work with files on Azure Databricks, Mounting cloud object storage on Azure Databricks, Access DBFS with FUSE
NEW QUESTION # 160
A data analyst has noticed that their Databricks SQL queries are running too slowly. They claim that this issue
is affecting all of their sequentially run queries. They ask the data engineering team for help. The data
engineering team notices that each of the queries uses the same SQL endpoint, but the SQL endpoint is not
used by any other user.
Which of the following approaches can the data engineering team use to improve the latency of the data
analyst's queries?
Answer: B
NEW QUESTION # 161
You have written a notebook to generate a summary data set for reporting, Notebook was scheduled using the job cluster, but you realized it takes 8 minutes to start the cluster, what feature can be used to start the cluster in a timely fashion so your job can run immediatley?
Answer: B
Explanation:
Explanation
Cluster pools allow us to reserve VM's ahead of time, when a new job cluster is created VM are grabbed from the pool. Note: when the VM's are waiting to be used by the cluster only cost incurred is Azure. Databricks run time cost is only billed once VM is allocated to a cluster.
Here is a demo of how to setup a pool and follow some best practices,
Graphical user interface, text Description automatically generated
NEW QUESTION # 162
A data engineer is creating a data ingestion pipeline to understand where customers are taking their rented bicycles during use. The engineer noticed that, over time, data being transmitted from the bicycle sensors fail to include key details like latitude and longitude. Downstream analysts need both the clean records and the quarantined records available for separate processing.
The data engineer already has this code:
import dlt
from pyspark.sql.functions import expr
rules = {
"valid_lat": "(lat IS NOT NULL)",
"valid_long": "(long IS NOT NULL)"
}
quarantine_rules = "NOT({})".format(" AND ".join(rules.values()))
@dlt.view
def raw_trips_data():
return spark.readStream.table("ride_and_go.telemetry.trips")
How should the data engineer meet the requirements to capture good and bad data?
Answer: A
Explanation:
The requirement is that both valid (good) and invalid (bad) records must be captured and available separately for downstream processing. Invalid records should not simply be dropped; they must be quarantined in a dedicated table.
In Databricks Lakeflow Declarative Pipelines (DLT), this is achieved by creating separate output tables:
One table for valid records (Silver table) that pass the expectations.
Another quarantine table that explicitly captures records failing the expectations.
Option A correctly implements this by:
Declaring a DLT table trips_data_quarantine.
Using .filter(expr(quarantine_rules)) to isolate invalid records (records where latitude or longitude is NULL).
This ensures analysts can query both good records (from the main Silver pipeline table) and bad records (from the quarantine table).
Why not the others?
B: Uses @dlt.expect_or_drop, which drops invalid records instead of quarantining them. This violates the requirement that quarantined data should be available.
C: Same as B, but applies expectations in bulk with expect_all_or_drop. Again, bad data is dropped, not quarantined.
D: Adds an is_quarantined flag in the same table. While it marks bad records, it does not separate them into a distinct quarantine table as required by the business use case.
Therefore, Option A is the only solution aligned with Databricks documentation for quarantining invalid data into a dedicated table while keeping valid data in the main pipeline.
NEW QUESTION # 163
A Delta Lake table was created with the below query: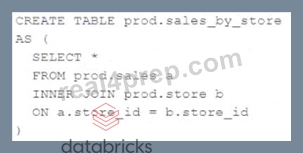
Consider the following query:
DROP TABLE prod.sales_by_store -
If this statement is executed by a workspace admin, which result will occur?
Answer: B
Explanation:
When a table is dropped in Delta Lake, the table is removed from the catalog and the data is deleted. This is because Delta Lake is a transactional storage layer that provides ACID guarantees. When a table is dropped, the transaction log is updated to reflect the deletion of the table and the data is deleted from the underlying storage. References:
* https://docs.databricks.com/delta/quick-start.html#drop-a-table
* https://docs.databricks.com/delta/delta-batch.html#drop-table
NEW QUESTION # 164
......
Databricks-Certified-Professional-Data-Engineer Exam Review: https://www.real4prep.com/Databricks-Certified-Professional-Data-Engineer-exam.html
BTW, DOWNLOAD part of Real4Prep Databricks-Certified-Professional-Data-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=19AxaOVGVnTGLPjxMsrc9FK1Imz9_LHxR