The Microsoft DP-750 web-based practice exam software can be easily accessed through browsers like Safari, Google Chrome, and Firefox. The customers do not need to download or install excessive software or applications to take the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) web-based practice exam. The DP-750 web-based practice exam software format can be accessed through any operating system like Windows or Mac.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30-35% | - Data quality and validation
|
| Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
| Deploy and manage data pipelines and workloads | 30-35% | - Operational reliability
|
| Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
>> Training DP-750 For Exam <<
We trounce many peers in this industry by our justifiably excellent DP-750 training guide and considerate services. So our DP-750 exam prep receives a tremendous ovation in market over twenty years. All these years, we have helped tens of thousands of exam candidates achieve success greatly. For all content of our DP-750 Learning Materials are strictly written and tested by our customers as well as the market. Come to try and you will be satisfied!
NEW QUESTION # 38
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
* The schemas and tables can be queried in Databricks.
* The schemas and tables appear alongside other Unity Catalog objects.
* The data is NOT copied into Databricks-managed storage.
Solution: You create a foreign catalog in Catalog Explorer.
Does this meet the goal?
Answer: B
Explanation:
The correct answer is A - Yes.
A foreign catalog created through Lakehouse Federation in Catalog Explorer is the correct solution for all three requirements. Here's why it works:
The schemas and tables of DB1 can be queried in Databricks - Lakehouse Federation pushes the query down to the external SQL Server and returns results, so analysts write normal SQL in Databricks.
They appear alongside other Unity Catalog objects - the foreign catalog sits in the same three-tier hierarchy as native catalogs, schemas, and tables, visible in Catalog Explorer alongside all other Unity Catalog assets.
The data is NOT copied into Databricks-managed storage - foreign catalogs query data in place at the source; nothing is replicated or materialised in Databricks storage.
This is exactly the scenario Lakehouse Federation was built for.
Reference: https://learn.microsoft.com/en-us/azure/databricks/query-federation/lakehouse-federation
NEW QUESTION # 39
You need to deploy Declarative Automation Bundles to a development environment. The solution must support automated and repeatable deployments across environments.
What should you use?
Answer: A
Explanation:
The Databricks CLI contains the bundle command group for validating, deploying, and running Declarative Automation Bundles. CLI commands can be executed consistently from developer terminals or CI/CD pipelines, making deployments automated, repeatable, and suitable for multiple target environments. The Databricks SDK for Python can manage workspace APIs programmatically, but it is not the standard bundle deployment interface required here. Git folders provide source-control integration inside the workspace but do not deploy bundle-defined resources. The Jobs UI supports interactive creation and management of jobs, which introduces manual steps and does not provide the same infrastructure-as-code workflow. Using commands such as databricks bundle validate and databricks bundle deploy -t dev directly satisfies the automated development deployment requirement. Microsoft Learn
NEW QUESTION # 40
Which Azure service is best integrated with Databricks Unity Catalog for centralized data governance?
Answer: B
Explanation:
Microsoft Purview integrates with Unity Catalog to provide centralized data governance, classification, and lineage tracking. It helps organizations manage data compliance and discovery. Key Vault handles secrets, not governance. DevTest Labs is for testing environments.
Azure Automation is for workflow automation.
NEW QUESTION # 41
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! processes raw data files stored in Azure Storage.
New files arrive at unpredictable intervals.
You need to ensure that Job1 starts automatically when new files arrive and does NOT consume compute resources when no data is available.
Which type of job trigger should you use?
Answer: A
Explanation:
The correct answer is C - File Arrival trigger.
File Arrival monitors a specified Azure Storage path and fires a job run each time a new file lands there. This ticks both requirements: Job1 starts automatically in response to new data (no human involvement), and when no files arrive, no job runs - no cluster spins up, no compute cost is incurred.
Option A (scheduled) runs at fixed intervals regardless of whether files are waiting. A quiet weekend still kicks off hourly (or daily) runs, burning compute for nothing. Option B (continuous) keeps the job running perpetually, consuming resources even during long gaps between file arrivals - exactly what 'does NOT consume compute resources when no data is available' rules out. Option D (manual) requires a person to trigger every run, which is unsuitable for unpredictable arrival patterns.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/triggers#file-arrival-trigger
NEW QUESTION # 42
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains:
A catalog named Corpdb
A schema named Finance in the Corpdb catalog
A table named Sales in the Finance schema
You have a group named Analysts.
You assign the following permissions to Analysts:
USE CATALOG on the Corpdb catalog
USE SCHEMA on the Finance schema
SELECT on the Sales table
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: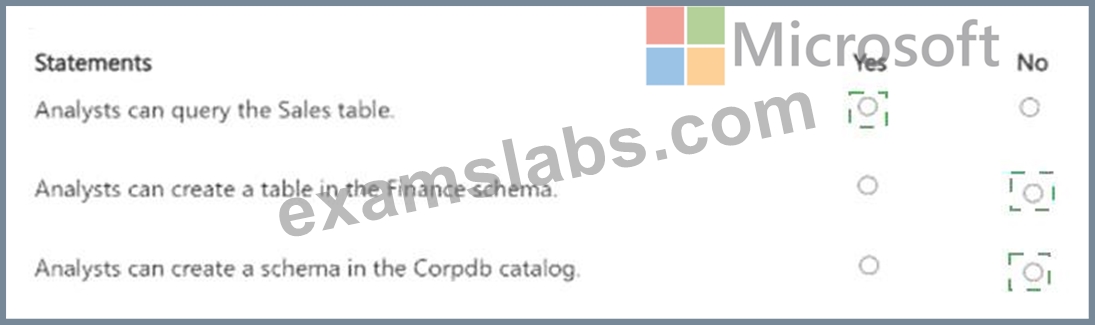
Explanation:
The Analysts group can query the Sales table because it has all three privileges required by the Unity Catalog hierarchy: USE CATALOG on Corpdb, USE SCHEMA on Finance, and SELECT on Sales. These permissions allow the group to navigate through the catalog and schema and read the table. However, USE SCHEMA does not grant permission to create tables. Creating a table in Finance would additionally require CREATE TABLE on that schema. Similarly, USE CATALOG only permits access to the catalog; it does not permit schema creation. Creating a schema in Corpdb would require the CREATE SCHEMA privilege on the catalog. Therefore, only the first statement is true.
NEW QUESTION # 43
......
Therefore, if you have struggled for months to pass Microsoft DP-750 exam, be rest assured you will pass this time with the help of our Microsoft DP-750 exam dumps. Every DP-750 exam candidate who has used our exam preparation material has passed the exam with flying colors. Availability in different formats is one of the advantages valued by Implementing Data Engineering Solutions Using Azure Databricks exam candidates. It allows them to choose the format of Microsoft DP-750 Dumps they want. They are not forced to buy one format or the other to prepare for the Microsoft DP-750 exam. ExamsLabs designed Microsoft exam preparation material in Microsoft DP-750 PDF and practice test (online and offline). If you prefer PDF Dumps notes or practicing on the Microsoft DP-750 practice test software, use either.
DP-750 Minimum Pass Score: https://www.examslabs.com/Microsoft/Microsoft-Certified-Fabric-Data-Engineer-Associate/best-DP-750-exam-dumps.html