Free PDF Databricks - Authoritative Databricks-Certified-Professional-Data-Engineer - Databricks Certified Professional Data Engineer Exam Latest Braindumps Free

Without self-assessment, you cannot ace the Databricks-Certified-Professional-Data-Engineer test. To ensure that you appear in the final Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) examination without anxiety and mistakes, TrainingDump offers desktop Databricks Databricks-Certified-Professional-Data-Engineer Practice Test software and web-based Databricks-Certified-Professional-Data-Engineer practice exam. These Databricks-Certified-Professional-Data-Engineer practice tests are customizable, simulate the original Databricks-Certified-Professional-Data-Engineer exam scenario, and track your performance.
| Section | Weight | Objectives |
|---|
| Topic 1: Pipeline Development and Orchestration | 10-15% | - Databricks workflows
- 1. Monitoring and alerting
- 2. Jobs and job scheduling
- 3. Task dependencies and orchestration
|
| Topic 2: Data Ingestion | 15-20% | - Streaming ingestion
- 1. Kafka integration
- 2. Structured streaming fundamentals
- Batch ingestion methods
- 1. DBR autoloader
- 2. Integration with external systems
- 3. Spark APIs for ingestion
|
| Topic 3: Delta Lake | 20-25% | - Delta Lake fundamentals
- 1. Time travel and data versioning
- 2. Optimize and Z-order
- 3. ACID transactions
- Delta Lake operations
- 1. Delta Live Tables
- 2. Schema evolution and enforcement
- 3. Merge, update, delete operations
|
| Topic 4: Data Processing with Spark | 25-30% | - Python and SQL for data engineering
- 1. Performance optimization techniques
- 2. Spark APIs in Python
- 3. Built-in and user-defined functions
- Spark DataFrames and Spark SQL
- 1. DataFrame operations and transformations
- 2. Spark SQL queries and functions
- 3. Window functions
|
| Topic 5: Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
- 1. Bronze, silver, gold data layers
- 2. Data governance fundamentals
- 3. Differences between data lake, data warehouse, and lakehouse
|
>> Databricks-Certified-Professional-Data-Engineer Latest Braindumps Free <<
Free PDF Databricks-Certified-Professional-Data-Engineer Latest Braindumps Free & Leader in Qualification Exams & Efficient Databricks-Certified-Professional-Data-Engineer Vce Download
Because our Databricks-Certified-Professional-Data-Engineer actual exam help exam cannonades pass the exam with rate up to 98 to 100 percent. It encourages us to focus more on the quality and usefulness of our Databricks-Certified-Professional-Data-Engineer exam questions in the future. And at the same time, we offer free demos before you really choose our three versions of Databricks-Certified-Professional-Data-Engineer Practice Guide. Time is flying, hope you can begin your review on our Databricks-Certified-Professional-Data-Engineer study engine as quickly as possible.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q199-Q204):
NEW QUESTION # 199
A data architect has heard about lake's built-in versioning and time travel capabilities. For auditing purposes they have a requirement to maintain a full of all valid street addresses as they appear in the customers table.
The architect is interested in implementing a Type 1 table, overwriting existing records with new values and relying on Delta Lake time travel to support long-term auditing. A data engineer on the project feels that a Type 2 table will provide better performance and scalability.
Which piece of information is critical to this decision?
- A. Delta Lake time travel cannot be used to query previous versions of these tables because Type 1 changes modify data files in place.
- B. Delta Lake time travel does not scale well in cost or latency to provide a long-term versioning solution.
- C. Shallow clones can be combined with Type 1 tables to accelerate historic queries for long-term versioning.
- D. Data corruption can occur if a query fails in a partially completed state because Type 2 tables requires Setting multiple fields in a single update.
Answer: B
Explanation:
Delta Lake's time travel feature allows users to access previous versions of a table, providing a powerful tool for auditing and versioning. However, using time travel as a long-term versioning solution for auditing purposes can be less optimal in terms of cost and performance, especially as the volume of data and the number of versions grow. For maintaining a full history of valid street addresses as they appear in a customers table, using a Type 2 table (where each update creates a new record with versioning) might provide better scalability and performance by avoiding the overhead associated with accessing older versions of a large table. While Type 1 tables, where existing records are overwritten with new values, seem simpler and can leverage time travel for auditing, the critical piece of information is that time travel might not scale well in cost or latency for long-term versioning needs, making a Type 2 approach more viable for performance and scalability.
:
Databricks Documentation on Delta Lake's Time Travel: Delta Lake Time Travel Databricks Blog on Managing Slowly Changing Dimensions in Delta Lake: Managing SCDs in Delta Lake
NEW QUESTION # 200
A small company based in the United States has recently contracted a consulting firm in India to implement several new data engineering pipelines to power artificial intelligence applications. All the company's data is stored in regional cloud storage in the United States.
The workspace administrator at the company is uncertain about where the Databricks workspace used by the contractors should be deployed.
Assuming that all data governance considerations are accounted for, which statement accurately informs this decision?
- A. Databricks runs HDFS on cloud volume storage; as such, cloud virtual machines must be deployed in the region where the data is stored.
- B. Cross-region reads and writes can incur significant costs and latency; whenever possible, compute should be deployed in the same region the data is stored.
- C. Databricks workspaces do not rely on any regional infrastructure; as such, the decision should be made based upon what is most convenient for the workspace administrator.
- D. Databricks notebooks send all executable code from the user's browser to virtual machines over the open internet; whenever possible, choosing a workspace region near the end users is the most secure.
- E. Databricks leverages user workstations as the driver during interactive development; as such, users should always use a workspace deployed in a region they are physically near.
Answer: B
Explanation:
This is the correct answer because it accurately informs this decision. The decision is about where the Databricks workspace used by the contractors should be deployed. The contractors are based in India, while all the company's data is stored in regional cloud storage in the United States. When choosing a region for deploying a Databricks workspace, one of the important factors to consider is the proximity to the data sources and sinks. Cross-region reads and writes can incur significant costs and latency due to network bandwidth and data transfer fees. Therefore, whenever possible, compute should be deployed in the same region the data is stored to optimize performance and reduce costs. Verified References: [Databricks Certified Data Engineer Professional], under "Databricks Workspace" section; Databricks Documentation, under
"Choose a region" section.
NEW QUESTION # 201
A company has a task management system that tracks the most recent status of tasks. The system takes task events as input and processes events in near real-time using Lakeflow Declarative Pipelines. A new task event is ingested into the system when a task is created or the task status is changed. Lakeflow Declarative Pipelines provides a streaming table (tasks_status) for BI users to query.
The table represents the latest status of all tasks and includes 5 columns:
* task_id (unique for each task)
* task_name
* task_owner
* task_status
* task_event_time
The table enables three properties: deletion vectors, row tracking, and change data feed (CDF).
A data engineer is asked to create a new Lakeflow Declarative Pipeline to enrich the tasks_status table in near real-time by adding one additional column representing task_owner's department, which can be looked up from a static dimension table (employee).
How should this enrichment be implemented?
- A. Create a new Lakeflow Declarative Pipeline: use readStream() function with option readChangeFeed to read tasks_status table CDF; enrich with the employee table; create a new streaming table as the result table and use apply_changes() function to process the changes from the enriched CDF.
- B. Create a new Lakeflow Declarative Pipeline: use the readStream() function with the option skipChangeCommits to read the tasks_status table; enrich with the employee table; store the result in a new streaming table.
- C. Create a new Lakeflow Declarative Pipeline: use the read() function to read tasks_status table; enrich with employee table; store the result in a materialized view.
- D. Create a new Lakeflow Declarative Pipeline: use the readStream() function to read tasks_status table; enrich with the employee table; store the result in a new streaming table.
Answer: A
Explanation:
Change Data Feed (CDF) allows downstream consumers to read incremental changes (inserts, updates, deletes) from a Delta table. The documentation explains that when streaming from a Delta table with CDF enabled, developers can use readStream().option( " readChangeFeed " , " true " ) to capture incremental events. For maintaining a derived table with enrichment logic, the recommended practice is to use apply_changes(), which applies CDC semantics (insert/update/delete) correctly to the target streaming table.
By joining with the static employee dimension, enriched rows are generated before being merged into the new streaming target. This ensures correctness, scalability, and minimal latency. Batch reads or skipping commits do not maintain correctness for CDC pipelines.
NEW QUESTION # 202
A CHECK constraint has been successfully added to the Delta table named activity_details using the following logic:
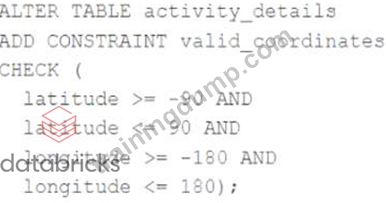
A batch job is attempting to insert new records to the table, including a record where latitude = 45.50 and longitude = 212.67.
Which statement describes the outcome of this batch insert?
- A. The write will fail completely because of the constraint violation and no records will be inserted into the target table.
- B. The write will include all records in the target table; any violations will be indicated in the boolean column named valid_coordinates.
- C. The write will fail when the violating record is reached; any records previously processed will be recorded to the target table.
- D. The write will insert all records except those that violate the table constraints; the violating records will be reported in a warning log.
- E. The write will insert all records except those that violate the table constraints; the violating records will be recorded to a quarantine table.
Answer: A
Explanation:
The CHECK constraint is used to ensure that the data inserted into the table meets the specified conditions. In this case, the CHECK constraint is used to ensure that the latitude and longitude values are within the specified range. If the data does not meet the specified conditions, the write operation will fail completely and no records will be inserted into the target table. This is because Delta Lake supports ACID transactions, which means that either all the data is written or none of it is written. Therefore, the batch insert will fail when it encounters a record that violates the constraint, and the target table will not be updated. References:
* Constraints: https://docs.delta.io/latest/delta-constraints.html
* ACID Transactions: https://docs.delta.io/latest/delta-intro.html#acid-transactions
NEW QUESTION # 203
The marketing team is launching a new campaign to monitor the performance of the new campaign for the first two weeks, they would like to set up a dashboard with a refresh schedule to run every 5 minutes, which of the below steps can be taken to reduce of the cost of this refresh over time?
- A. Reduce the max size of auto scaling from 10 to 5
- B. Setup the dashboard refresh schedule to end in two weeks
- C. Always use X-small cluster
- D. Reduce the size of the SQL Cluster size
- E. Change the spot instance policy from reliability optimized to cost optimized
Answer: B
Explanation:
Explanation
The answer is Setup the dashboard refresh schedule to end in two weeks
NEW QUESTION # 204
......
Our Databricks-Certified-Professional-Data-Engineer preparation practice are highly targeted and have a high hit rate, there are a lot of learning skills and key points in the exam, even if your study time is very short, you can also improve your Databricks-Certified-Professional-Data-Engineer exam scores very quickly. Even if you have a week foundation, I believe that you will get the certification by using our Databricks-Certified-Professional-Data-Engineer Study Materials. We can claim that with our Databricks-Certified-Professional-Data-Engineer practice engine for 20 to 30 hours, you will be ready to pass the exam with confidence.
Databricks-Certified-Professional-Data-Engineer Vce Download: https://www.trainingdump.com/Databricks/Databricks-Certified-Professional-Data-Engineer-practice-exam-dumps.html
- Databricks Databricks-Certified-Professional-Data-Engineer Online Practice Test Engine ❗ Search for ➡ Databricks-Certified-Professional-Data-Engineer ️⬅️ and download it for free immediately on ➡ www.troytecdumps.com ️⬅️ 🍓Frenquent Databricks-Certified-Professional-Data-Engineer Update
- Exam Databricks-Certified-Professional-Data-Engineer Guide Materials 🐀 New Databricks-Certified-Professional-Data-Engineer Test Pass4sure 🛢 Frenquent Databricks-Certified-Professional-Data-Engineer Update 🙂 Open website ☀ www.pdfvce.com ️☀️ and search for ➠ Databricks-Certified-Professional-Data-Engineer 🠰 for free download ➡Flexible Databricks-Certified-Professional-Data-Engineer Learning Mode
- Real Databricks Databricks-Certified-Professional-Data-Engineer Exam Questions [2023]-Secret To Pass Exam In First Attempt 🗽 Open ✔ www.prepawaypdf.com ️✔️ and search for ( Databricks-Certified-Professional-Data-Engineer ) to download exam materials for free ✋Updated Databricks-Certified-Professional-Data-Engineer Demo
- New Databricks-Certified-Professional-Data-Engineer Exam Papers 👾 Frenquent Databricks-Certified-Professional-Data-Engineer Update 🔳 Databricks-Certified-Professional-Data-Engineer Intereactive Testing Engine 🗜 Search for ➽ Databricks-Certified-Professional-Data-Engineer 🢪 on ✔ www.pdfvce.com ️✔️ immediately to obtain a free download ⚛Databricks-Certified-Professional-Data-Engineer Practice Test
- Databricks-Certified-Professional-Data-Engineer Exam Collection Pdf 🎄 Databricks-Certified-Professional-Data-Engineer Exam Simulator Online 🌮 Databricks-Certified-Professional-Data-Engineer New Real Exam 🥋 Search for ▶ Databricks-Certified-Professional-Data-Engineer ◀ and download exam materials for free through ➠ www.pdfdumps.com 🠰 🤛Online Databricks-Certified-Professional-Data-Engineer Version
- Databricks-Certified-Professional-Data-Engineer Hot Questions ↙ Databricks-Certified-Professional-Data-Engineer Real Exam 🦁 Databricks-Certified-Professional-Data-Engineer New Real Exam ⛵ Search for 《 Databricks-Certified-Professional-Data-Engineer 》 on ➤ www.pdfvce.com ⮘ immediately to obtain a free download 🌕Databricks-Certified-Professional-Data-Engineer New Real Exam
- Real Databricks Databricks-Certified-Professional-Data-Engineer Exam Questions [2023]-Secret To Pass Exam In First Attempt 🔂 Search for 《 Databricks-Certified-Professional-Data-Engineer 》 and download it for free on ⮆ www.testkingpass.com ⮄ website 🚙Updated Databricks-Certified-Professional-Data-Engineer Demo
- 100% Pass Quiz Databricks-Certified-Professional-Data-Engineer - Databricks Certified Professional Data Engineer Exam –Efficient Latest Braindumps Free 🔟 Search for ➤ Databricks-Certified-Professional-Data-Engineer ⮘ and obtain a free download on ▷ www.pdfvce.com ◁ 👠Flexible Databricks-Certified-Professional-Data-Engineer Learning Mode
- Newly Released Databricks Databricks-Certified-Professional-Data-Engineer Dumps in Three Formats [2026] ☝ Open 《 www.pdfdumps.com 》 enter ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ and obtain a free download 😎Databricks-Certified-Professional-Data-Engineer Intereactive Testing Engine
- Databricks-Certified-Professional-Data-Engineer Study Practice Guide Give Customers Best Databricks Certified Professional Data Engineer Exam Exam Materials 🍍 Search for { Databricks-Certified-Professional-Data-Engineer } and download exam materials for free through ▛ www.pdfvce.com ▟ ⚛Online Databricks-Certified-Professional-Data-Engineer Version
- Updated Databricks-Certified-Professional-Data-Engineer Demo 🧓 Databricks-Certified-Professional-Data-Engineer Exam Simulator Online 🐼 Databricks-Certified-Professional-Data-Engineer Hot Questions 🙆 Search for ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ and obtain a free download on ▶ www.torrentvce.com ◀ 🎰Frenquent Databricks-Certified-Professional-Data-Engineer Update
- kaeuchi.jp, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes