New Databricks-Certified-Professional-Data-Engineer Exam Price & Latest Databricks-Certified-Professional-Data-Engineer Dumps Free

As is known to us, perfect after-sales service for buyers is a very high value. Our Databricks-Certified-Professional-Data-Engineer guide torrent not only has the high quality and efficiency but also the perfect service system after sale. If you decide to buy our Databricks-Certified-Professional-Data-Engineer test torrent, we would like to offer you 24-hour online efficient service, you have the right to communicate with us without any worries at any time you need, and you will receive a reply, we are glad to answer your any question about our Databricks-Certified-Professional-Data-Engineer Guide Torrent. You have the right to communicate with us by online contacts or by an email. The high quality and the perfect service system after sale of our Databricks-Certified-Professional-Data-Engineer exam questions have been approbated by our local and international customers. So you can rest assured to buy.
Databricks Certified Professional Data Engineer exam covers a wide range of topics, including data engineering concepts, Databricks architecture, data ingestion and processing, data storage and management, and data security. Databricks-Certified-Professional-Data-Engineer Exam consists of 60 multiple-choice questions and participants have 90 minutes to complete it. Passing the exam requires a score of 70% or higher, and successful candidates receive a certificate that validates their expertise in building and managing data pipelines on the Databricks platform.
Databricks Certified Professional Data Engineer certification is recognized by the industry as a standard for measuring the skills and expertise of data engineers who work with Databricks. It demonstrates that the candidate has the knowledge and skills required to design and build data solutions using Databricks that meet the highest standards of performance, scalability, and reliability. Databricks Certified Professional Data Engineer Exam certification is valuable for data engineers who want to advance their careers by demonstrating their proficiency in using Databricks and for organizations that want to ensure that their data engineers have the skills and expertise needed to build and maintain data solutions using Databricks.
>> New Databricks-Certified-Professional-Data-Engineer Exam Price <<
Help You in Databricks Databricks-Certified-Professional-Data-Engineer Exam Preparation [2026]
We will try our best to solve your problems for you. I believe that you will be more inclined to choose a good service product, such as Databricks-Certified-Professional-Data-Engineer learning question. After all, everyone wants to be treated warmly and kindly, and hope to learn in a more pleasant mood. The authoritative, efficient, and thoughtful service of Databricks-Certified-Professional-Data-Engineer learning question will give you the best user experience, and you can also get what you want with our study materials. I hope our study materials can accompany you to pursue your dreams. If you can choose Databricks-Certified-Professional-Data-Engineer test guide, we will be very happy. We look forward to meeting you.
Databricks Certified Professional Data Engineer (Databricks-Certified-Professional-Data-Engineer) certification exam is a highly sought-after certification for individuals who want to demonstrate their expertise in building reliable, scalable, and performant data pipelines using Databricks. Databricks Certified Professional Data Engineer Exam certification is designed to validate the skills and knowledge required to design, implement, and maintain data pipelines for big data processing using Databricks.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q31-Q36):
NEW QUESTION # 31
The DevOps team has configured a production workload as a collection of notebooks scheduled to run daily using the Jobs Ul. A new data engineering hire is onboarding to the team and has requested access to one of these notebooks to review the production logic.
What are the maximum notebook permissions that can be granted to the user without allowing accidental changes to production code or data?
- A. Can edit
- B. Can run
- C. Can Read
- D. Can manage
Answer: C
Explanation:
Granting a user 'Can Read' permissions on a notebook within Databricks allows them to view the notebook's content without the ability to execute or edit it. This level of permission ensures that the new team member can review the production logic for learning or auditing purposes without the risk of altering the notebook's code or affecting production data and workflows. This approach aligns with best practices for maintaining security and integrity in production environments, where strict access controls are essential to prevent unintended modifications.References: Databricks documentation on access control and permissions for notebooks within the workspace (https://docs.databricks.com/security/access-control/workspace-acl.html).
NEW QUESTION # 32
A user new to Databricks is trying to troubleshoot long execution times for some pipeline logic they are working on. Presently, the user is executing code cell-by-cell, usingdisplay()calls to confirm code is producing the logically correct results as new transformations are added to an operation. To get a measure of average time to execute, the user is running each cell multiple times interactively.
Which of the following adjustments will get a more accurate measure of how code is likely to perform in production?
- A. The only way to meaningfully troubleshoot code execution times in development notebooks Is to use production-sized data and production-sized clusters with Run All execution.
- B. Scala is the only language that can be accurately tested using interactive notebooks; because the best performance is achieved by using Scala code compiled to JARs. all PySpark and Spark SQL logic should be refactored.
- C. The Jobs Ul should be leveraged to occasionally run the notebook as a job and track execution time during incremental code development because Photon can only be enabled on clusters launched for scheduled jobs.
- D. Calling display () forces a job to trigger, while many transformations will only add to the logical query plan; because of caching, repeated execution of the same logic does not provide meaningful results.
- E. Production code development should only be done using an IDE; executing code against a local build of open source Spark and Delta Lake will provide the most accurate benchmarks for how code will perform in production.
Answer: D
Explanation:
In Databricks notebooks, using thedisplay()function triggers an action that forces Spark to execute the code and produce a result. However, Spark operations are generally divided into transformations and actions.
Transformations create a new dataset from an existing one and are lazy, meaning they are not computed immediately but added to a logical plan. Actions, likedisplay(), trigger the execution of this logical plan.
Repeatedly running the same code cell can lead to misleading performance measurements due to caching.
When a dataset is used multiple times, Spark's optimization mechanism caches it in memory, making subsequent executions faster. This behavior does not accurately represent the first-time execution performance in a production environment where data might not be cached yet.
To get a more realistic measure of performance, it is recommended to:
* Clear the cache or restart the cluster to avoid the effects of caching.
* Test the entire workflow end-to-end rather than cell-by-cell to understand the cumulative performance.
* Consider using a representative sample of the production data, ensuring it includes various cases the code will encounter in production.
References:
* Databricks Documentation on Performance Optimization: Databricks Performance Tuning
* Apache Spark Documentation: RDD Programming Guide - Understanding transformations and actions
NEW QUESTION # 33
A Structured Streaming job deployed to production has been experiencing delays during peak hours of the day.
At present, during normal execution, each microbatch of data is processed in less than 3 seconds. During peak hours of the day, execution time for each microbatch becomes very inconsistent, sometimes exceeding 30 seconds. The streaming write is currently configured with a trigger interval of 10 seconds.
Holding all other variables constant and assuming records need to be processed in less than 10 seconds, which adjustment will meet the requirement?
- A. Increase the trigger interval to 30 seconds; setting the trigger interval near the maximum execution time observed for each batch is always best practice to ensure no records are dropped.
- B. Use the trigger once option and configure a Databricks job to execute the query every 10 seconds; this ensures all backlogged records are processed with each batch.
- C. The trigger interval cannot be modified without modifying the checkpoint directory; to maintain the current stream state, increase the number of shuffle partitions to maximize parallelism.
- D. Decrease the trigger interval to 5 seconds; triggering batches more frequently may prevent records from backing up and large batches from causing spill.
- E. Decrease the trigger interval to 5 seconds; triggering batches more frequently allows idle executors to begin processing the next batch while longer running tasks from previous batches finish.
Answer: B
Explanation:
Explanation
This is the correct answer because it can meet the requirement of processing records in less than 10 seconds without modifying the checkpoint directory or dropping records. The trigger once option is a special type of trigger that runs the streaming query only once and terminates after processing all available data. This option can be useful for scenarios where you want to run streaming queries on demand or periodically, rather than continuously. By using the trigger once option and configuring a Databricks job to execute the query every 10 seconds, you can ensure that all backlogged records are processed with each batch and avoid inconsistent execution times. Verified References: [Databricks Certified Data Engineer Professional], under "Structured Streaming" section; Databricks Documentation, under "Trigger Once" section.
NEW QUESTION # 34
How VACCUM and OPTIMIZE commands can be used to manage the DELTA lake?
- A. VACCUM command can be used to compact small parquet files, and the OP-TIMZE command can be used to delete parquet files that are marked for dele-tion/unused.
- B. VACCUM command can be used to delete empty/blank parquet files in a delta table, OPTIMIZE command can be used to cache frequently delta tables for better perfor-mance.
- C. VACCUM command can be used to compress the parquet files to reduce the size of the table, OPTIMIZE command can be used to cache frequently delta tables for better performance.
- D. VACCUM command can be used to delete empty/blank parquet files in a delta table. OPTIMIZE command can be used to update stale statistics on a delta table.
- E. OPTIMIZE command can be used to compact small parquet files, and the VAC-CUM command can be used to delete parquet files that are marked for deletion/unused.
(Correct)
Answer: E
Explanation:
Explanation
VACCUM:
You can remove files no longer referenced by a Delta table and are older than the retention thresh-old by running the vacuum command on the table. vacuum is not triggered automatically. The de-fault retention threshold for the files is 7 days. To change this behavior, see Configure data reten-tion for time travel.
OPTIMIZE:
Using OPTIMIZE you can compact data files on Delta Lake, this can improve the speed of read queries on the table. Too many small files can significantly degrade the performance of the query.
NEW QUESTION # 35
The data science team has created and logged a production model using MLflow. The following code correctly imports and applies the production model to output the predictions as a new DataFrame named preds with the schema "customer_id LONG, predictions DOUBLE, date DATE".
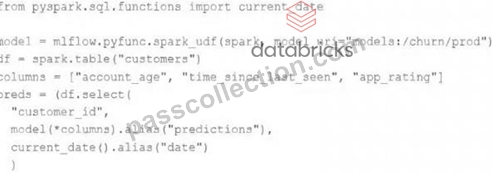
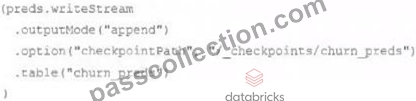
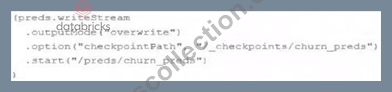
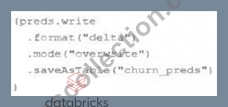
The data science team would like predictions saved to a Delta Lake table with the ability to compare all predictions across time. Churn predictions will be made at most once per day.
Which code block accomplishes this task while minimizing potential compute costs?
- A. preds.write.format("delta").save("/preds/churn_preds")
- B.
- C.
- D.
- E. preds.write.mode("append").saveAsTable("churn_preds")
Answer: E
NEW QUESTION # 36
......
Latest Databricks-Certified-Professional-Data-Engineer Dumps Free: https://www.passcollection.com/Databricks-Certified-Professional-Data-Engineer_real-exams.html
- Databricks-Certified-Professional-Data-Engineer Exam Fees 🌵 Pdf Databricks-Certified-Professional-Data-Engineer Files ⛅ Valid Databricks-Certified-Professional-Data-Engineer Exam Answers 🧖 Immediately open ▛ www.practicevce.com ▟ and search for ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ to obtain a free download 📼Databricks-Certified-Professional-Data-Engineer Real Questions
- Authorized Databricks-Certified-Professional-Data-Engineer Certification 🧀 Databricks-Certified-Professional-Data-Engineer Exam Fees ➕ Download Databricks-Certified-Professional-Data-Engineer Fee 🍋 ▷ www.pdfvce.com ◁ is best website to obtain [ Databricks-Certified-Professional-Data-Engineer ] for free download 🏀Databricks-Certified-Professional-Data-Engineer Dumps Vce
- 100% Pass Quiz 2026 Databricks Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam – Valid New Exam Price 🦧 Open [ www.verifieddumps.com ] and search for ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ to download exam materials for free 🛩Free Databricks-Certified-Professional-Data-Engineer Practice
- Valid Braindumps Databricks-Certified-Professional-Data-Engineer Ebook 🙈 Valid Databricks-Certified-Professional-Data-Engineer Exam Answers ⛰ New Databricks-Certified-Professional-Data-Engineer Dumps Free 👨 Search for ➥ Databricks-Certified-Professional-Data-Engineer 🡄 and download exam materials for free through ➠ www.pdfvce.com 🠰 📮Databricks-Certified-Professional-Data-Engineer Valid Exam Answers
- New Databricks-Certified-Professional-Data-Engineer Exam Price 100% Pass | Professional Latest Databricks-Certified-Professional-Data-Engineer Dumps Free: Databricks Certified Professional Data Engineer Exam 👭 Go to website ⏩ www.prepawayete.com ⏪ open and search for ( Databricks-Certified-Professional-Data-Engineer ) to download for free 🥚Databricks-Certified-Professional-Data-Engineer Dumps Vce
- Databricks-Certified-Professional-Data-Engineer Free Vce Dumps 🩳 Latest Databricks-Certified-Professional-Data-Engineer Dumps Ebook 🩲 New Databricks-Certified-Professional-Data-Engineer Dumps Free 😘 Open ▶ www.pdfvce.com ◀ and search for [ Databricks-Certified-Professional-Data-Engineer ] to download exam materials for free 📁Databricks-Certified-Professional-Data-Engineer Lead2pass
- Free Databricks-Certified-Professional-Data-Engineer Learning Cram 🙈 Databricks-Certified-Professional-Data-Engineer Real Questions 🔨 Databricks-Certified-Professional-Data-Engineer Latest Version 🔴 Search for 「 Databricks-Certified-Professional-Data-Engineer 」 and easily obtain a free download on 《 www.exam4labs.com 》 🔏Authorized Databricks-Certified-Professional-Data-Engineer Certification
- Pass Guaranteed Databricks-Certified-Professional-Data-Engineer - Databricks Certified Professional Data Engineer Exam Marvelous New Exam Price ✉ Enter 【 www.pdfvce.com 】 and search for ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ to download for free 🚴Databricks-Certified-Professional-Data-Engineer Dumps Vce
- Free Databricks-Certified-Professional-Data-Engineer Practice 🛩 Pdf Databricks-Certified-Professional-Data-Engineer Files 🚢 Valid Braindumps Databricks-Certified-Professional-Data-Engineer Ebook 😹 Download ⏩ Databricks-Certified-Professional-Data-Engineer ⏪ for free by simply searching on ⮆ www.troytecdumps.com ⮄ 🧾Practice Databricks-Certified-Professional-Data-Engineer Online
- Download Databricks-Certified-Professional-Data-Engineer Fee 🐲 Databricks-Certified-Professional-Data-Engineer Lead2pass 🤘 New Databricks-Certified-Professional-Data-Engineer Test Camp 🥰 Search for [ Databricks-Certified-Professional-Data-Engineer ] and download it for free on ➡ www.pdfvce.com ️⬅️ website ❤New Databricks-Certified-Professional-Data-Engineer Dumps Free
- Databricks-Certified-Professional-Data-Engineer Valid Exam Answers 🥽 Databricks-Certified-Professional-Data-Engineer Real Questions ✔️ Databricks-Certified-Professional-Data-Engineer Lead2pass 😤 Search for { Databricks-Certified-Professional-Data-Engineer } on ⮆ www.prep4sures.top ⮄ immediately to obtain a free download 🕘Free Databricks-Certified-Professional-Data-Engineer Practice
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes