Professionals who hold DP-800 certification demonstrate to their employers and clients that they have the knowledge and skills necessary to succeed in the industry. To meet the growing demand for Microsoft DP-800 certification exam, preparation platforms have emerged in recent years. TestInsides offers candidates actual DP-800 Questions Pdf, practice exams, and 24/7 support to ensure they have the best possible preparation for the exam.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
If you have decided to improve yourself IT ability by passing Microsoft exam tests, choosing our DP-800 exam braindumps will be definitely right decision. Our TestInsides promises that you can pass test at your first time to participate in the DP-800 Dumps Torrent and enhance yourself by practicing exam questions.
NEW QUESTION # 12
You have an Azure SQL database that contains tables named dbo.ProductDocs and dbo.ProductDocsEmbeddings. dbo.ProductDocs contains product documentation and the following columns:
- DocID (int)
- Title (nvarchar(200))
- Body (nvarchar(max))
- LastModified (datetime2)
The documentation is edited throughout the day.
dbo.ProductDocsEmbeddings contains the following columns:
- DocID (int)
- ChunkOrder (int)
- ChunkText (nvarchar(max))
- Embedding (vector(1536))
The current embedding pipeline runs once per night.
You need to ensure that embeddings are updated every time the underlying documentation content changes. The solution must NOT require a nightly batch process.
What should you include in the solution?
Answer: A
Explanation:
To ensure embeddings are updated immediately when the product information table changes, you should implement Azure SQL Database Change Tracking combined with Azure Functions triggered via Event Grid. This approach eliminates daily batch processes by enabling an event- driven architecture that triggers embedding regeneration only for modified rows.
Reference:
https://medium.com/@granthgharewal/why-change-tracking-needs-to-be-enabled-for-sql-trigger- azure-functions-7d230a669fb8
NEW QUESTION # 13
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have an SDK-style SQL database project stored in a Git repository. The project targets an Azure SQL database.
The CI build fails with unresolved reference errors when the project references system objects.
You need to update the SQL database project to ensure that dotnet build validates successfully by including the correct system objects in the database model for Azure SQL Database.
Solution: Build the project by running dotnet build -bl -flp:v=diag.
Does this meet the goal?
Answer: A
Explanation:
Correct:
* Add the Microsoft.SqlServer.Dacpacs.Azure.Master NuGet package to the project.
To resolve system reference errors in an SDK-style SQL project targeting Azure SQL Database, you need to add a reference to the Microsoft.SqlServer.Dacpacs.Azure.Master NuGet package.
In your .sqlproj file, include the following item group:
<ItemGroup>
<PackageReference Include="Microsoft.SqlServer.Dacpacs.Azure.Master" Version="1.60.0" />
</ItemGroup>
Why this works:
System Objects: Standard SDK-style projects don't automatically include system views (like sys.database_principals or sys.dm_db_resource_stats). This package provides the necessary metadata for the compiler.
Azure Specifics: It includes Azure-only system objects that aren't present in the standard master database dacpac used for on-premises SQL Server.
CI/CD Friendly: Since it is a NuGet package, the dotnet build command will automatically restore it during the CI process without requiring manual file paths or local installations of Visual Studio.
Incorrect:
* Add an artifact reference to the Azure SQL Database master.dacpac file.
* Add the Microsoft.SqlServer.Dacpacs.Master NuGet package to the project.
* Build the project by running dotnet build -bl -flp:v=diag.
Reference:
https://learn.microsoft.com/en-us/sql/tools/sql-database-projects/concepts/system-objects
NEW QUESTION # 14
You have an Azure SQL database named AdventureWorksDB that contains a table named dbo.Employee.
You have a C# Azure Functions app that uses an HTTP-triggered function with an Azure SQL input binding to query dbo.Employee.
You are adding a second function that will react to row changes in dbo.Employee and write structured logs.
You need to configure AdventureWorksDB and the app to meet the following requirements:
* Changes to dbo.Employee must trigger the new function within five seconds.
* Each invocation must processes no more than 100 changes.
Which two database configurations should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: C,D
Explanation:
Azure Functions' Azure SQL trigger requires change tracking to be enabled on the source table. Microsoft' s SQL trigger documentation states that setting up change tracking for the Azure SQL trigger requires two steps : enable change tracking on the database and enable change tracking on the table being monitored.
Since the question asks specifically which database configurations you should perform, enabling change tracking on dbo.Employee is one of the required database-side steps.
To meet the latency requirement that changes trigger the function within five seconds , the relevant trigger setting is Sql_Trigger_PollingIntervalMs . Microsoft documents this setting as the delay, in milliseconds, between processing each batch of changes, and a value of 5000 means the trigger polls every 5 seconds .
A few clarifications about the other options:
* B is not the documented setting name. The documented app setting is Sql_Trigger_BatchSize or host setting MaxBatchSize , not "SetSql Trigger MaxBatchSize". The screenshot wording suggests a distractor.
* D is also required in practice for the trigger to work, but the question asks for two answers and includes the polling setting plus the table-level CT setting as the actionable choices presented.
* F is wrong because the Azure SQL trigger uses change tracking , not CDC.
NEW QUESTION # 15
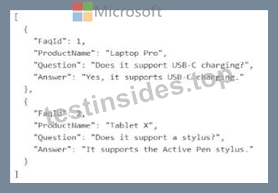
You have an Azure SQL table that contains the following data.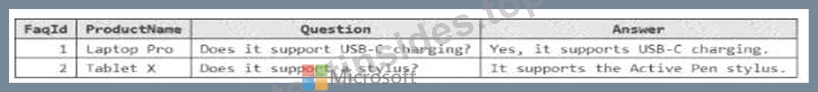
You need to retrieve data to be used as context for a large language model (LLM). The solution must minimize token usage.
Which formal should you use to send the data to the LLM?
Answer: B
Explanation:
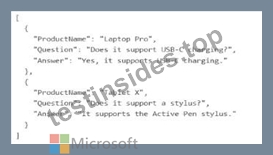
The correct choice is Option A because it provides the relevant semantic context the LLM needs while avoiding an unnecessary field that would add tokens without improving answer quality.
For LLM grounding and RAG-style context, Microsoft guidance emphasizes mapping and sending the fields that contain text pertinent to the use case . In this FAQ scenario, the useful context is the ProductName , the Question , and the Answer . Those three fields help the model understand both the subject domain and the actual Q & A pair. By contrast, FaqId is just a technical identifier and generally adds no semantic value for response generation, so including it wastes tokens.
That is why Option A is better than the others:
* Option A keeps the meaningful text fields and removes the low-value identifier.
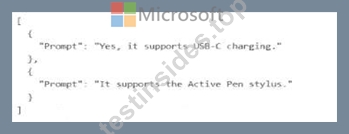
* Option B is too minimal because it includes only the answer text as Prompt, which strips away the product and question context the LLM may need for accurate grounding.
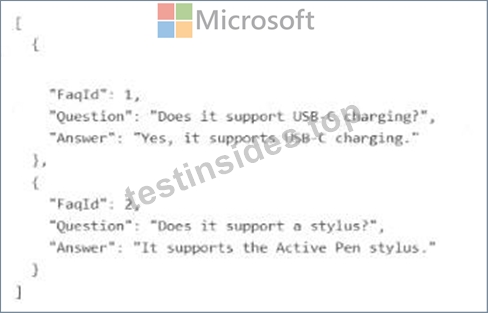
* Option C keeps FaqId but omits ProductName, which can be important disambiguating context.
* Option D includes everything, but that does not minimize token usage because it keeps the unnecessary FaqId.
NEW QUESTION # 16
You have a SQL database in Microsoft Fabric that contains a table named dbo.Orders, dbo.Orders has a clustered index, contains three years of data, and is partitioned by a column named OrderDate by month.
You need to remove all the rows for the oldest month. The solution must minimize the impact on other queries that access the data in dbo.orders.
Solution: Run the following Transact-SQL statement.
DELETE FROM dbo.Orders
WHERE OrderDate < DATEADD(nonth, -36, SYSUTCDATETIME());
Does this meet the goal?
Answer: A
Explanation:
This does not meet the goal. A row-by-row DELETE against the oldest month is not the lowest-impact way to purge data from a monthly partitioned table. Microsoft's partitioning guidance specifically says partitioning lets you perform maintenance and retention operations more efficiently by targeting just the relevant partition, including the ability to truncate data in a single partition .
The proposed statement:
DELETE FROM dbo.Orders
WHERE OrderDate < DATEADD(month, -36, SYSUTCDATETIME());
would log row deletions and can hold locks longer, creating more overhead for other queries than a partition- level maintenance operation. Since the table is already partitioned by month , the expected low-impact approach is to operate on the oldest partition directly, not issue a broad delete predicate over rows. Microsoft explicitly highlights partition-targeted truncation as a faster, more efficient retention operation than working against the whole table or rowset.
NEW QUESTION # 17
......
Our DP-800 training guide has been well known in the market. Almost all candidates know our DP-800 exam questions as a powerful brand. Once their classmates or colleagues need to prepare an exam, they will soon introduce them to choose our DP-800 Study Materials. So our study materials are helpful to your preparation of the DP-800 exam. As a matter of fact, we receive thousands of the warm feedbacks to thank us for helping them pass the exam.
Exam DP-800 Learning: https://www.testinsides.top/DP-800-dumps-review.html