P.S. Free & New DP-800 dumps are available on Google Drive shared by ActualCollection: https://drive.google.com/open?id=134dn7Eg67xYX0apgkAI66CpgN_8jJWY7
For your convenience, ActualCollection has prepared Developing AI-Enabled Database Solutions exam study material based on a real exam syllabus to help candidates go through their exams. Candidates who are preparing for the DP-800 Exam suffer greatly in their search for preparation material. You would not need anything else if you prepare for the exam with our DP-800 Exam Questions.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
If you choose the help of ActualCollection, we will spare no effort to help you pass the exam. Moreover, we also provide you with a year of free after-sales service to update the exam practice questions and answers. Do not hesitate! Please select ActualCollection, it will be the best guarantee for you to pass DP-800 Certification Exam. Now please add ActualCollection to your shopping cart.
NEW QUESTION # 87
You have an SDK-style SQL database project named MyDatabaseProject.sqlproj stored in a private GitHub repository. The repository contains the following GitHub Actions workflow:
YAML
name: Build and Deploy SQL Project
on:
push:
branches:
- main
workflow_dispatch:
jobs:
build-and-deploy:
runs-on: ubuntu-latest
permissions:
id-token: write
contents: read
steps:
- uses: actions/checkout@v4
- name: Build SQL project
run: dotnet build MyDatabaseProject.sqlproj
- name: Publish DACPAC
uses: azure/sql-action@v2
Answer:
Explanation:
Explanation:
NEW QUESTION # 88
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.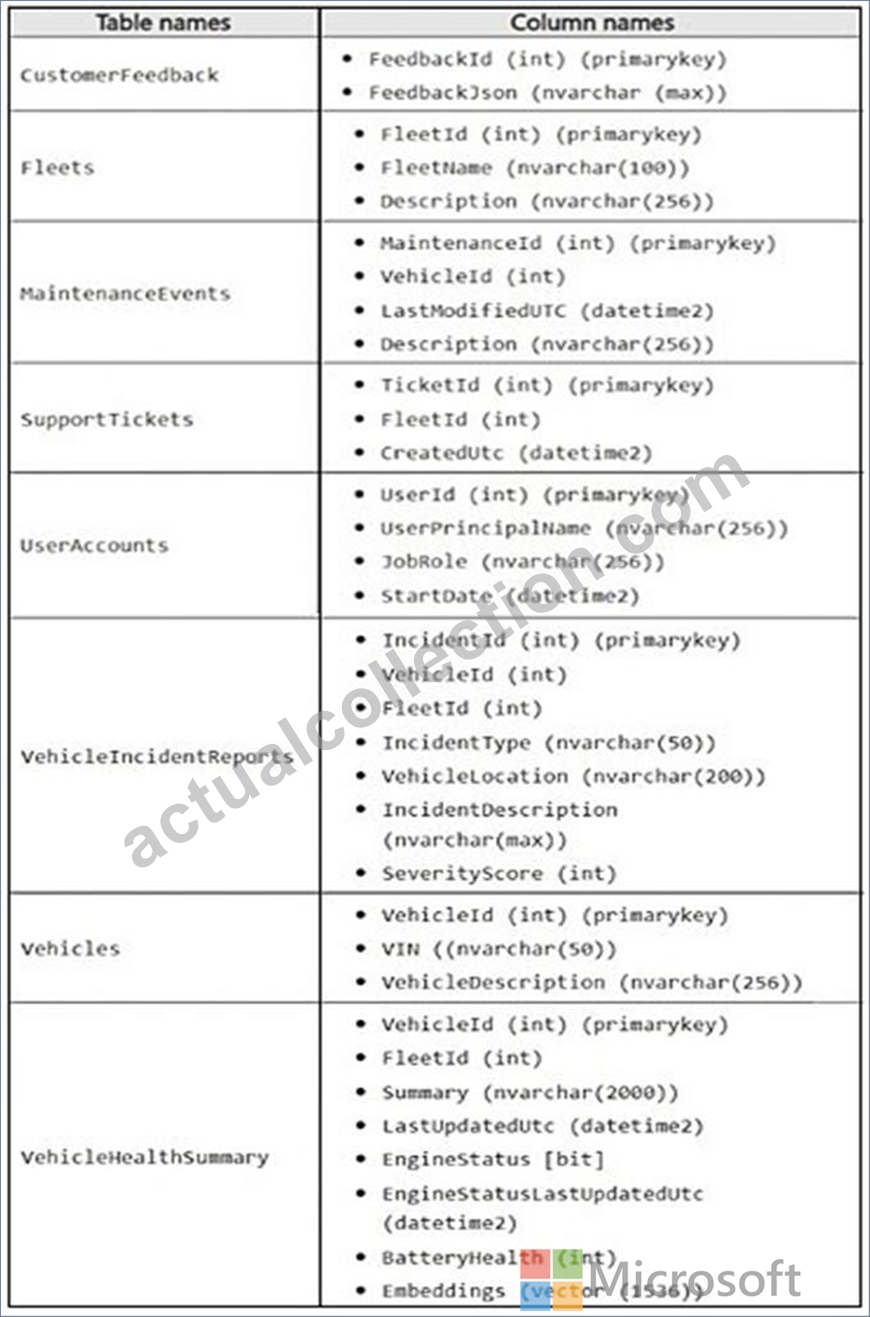
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.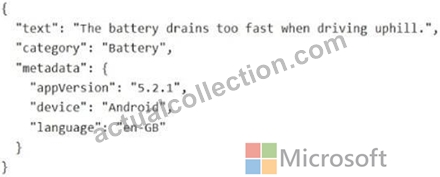
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.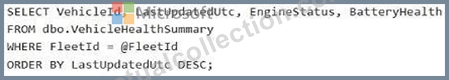
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
Hotspot Question
You need to create a table in the database to store the telemetry data.
You have the following Transact-SQL code.
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 89
You create an SDK-style SQL database project in Microsoft Visual Studio Code named Database.sqlproj and add the project to a GitHub repository.
You need to configure a GitHub Actions workflow to support the planned changes for DB1.
How should you complete the workflow? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
* pull_request
* build Database.sqlproj -c Release
The correct configuration is pull_request with dotnet build Database.sqlproj -c Release.
Fabrikam requires every pull request targeting production to be validated before merging, and all deployments must use the Release configuration.
Technical breakdown:
1. pull_request trigger: Executes the GitHub Actions workflow when a pull request targets the main branch.
This allows SQL project validation before changes are merged.
2. dotnet build: Compiles the SDK-style SQL database project, validates its database schema model, and produces a .dacpac deployment artifact.
3. -c Release: Explicitly selects the Release build configuration, satisfying Fabrikam ' s deployment configuration requirement.
4. Branch protection: Configure GitHub branch protection rules to make successful validation a required status check before merging. The workflow alone does not enforce this restriction.
5. Incorrect alternatives: push runs after changes are pushed, while merge is not a valid GitHub Actions event.
dotnet pack packages projects, and dotnet publish is not the appropriate SQL project validation command.
Microsoft identifies dotnet build as the supported compilation method for SDK-style SQL projects.
Completed GitHub Actions workflow
name: Validate SQL Project
on:
pull_request:
branches: [ " main " ]
jobs:
validate:
runs-on: ubuntu-latest
steps:
- uses: actions/checkout@v4
- name: Step 1
run: dotnet build Database.sqlproj -c Release
DP-800 Official Study Guide Reference:
Main topic: Secure, optimize, and deploy database solutions.
Subtopic: Implement CI/CD by using SQL Database Projects.
Specific examination objectives:
* Create, build, and validate database models by using SQL Database Projects, including SDK-style models.
* Manage branching, pull requests, and conflict resolution.
* Design and implement controls for deployment pipelines.
NEW QUESTION # 90
You have an Azure SQL database that contains the following tables and columns.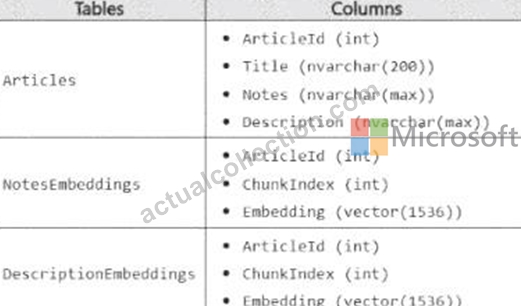
Embeddings in the NotesEnbeddings and DescriptionEabeddings tables have been generated from values in the Description and notes columns of the Articles table by using different chunk sizes.
You need to perform approximate nearest neighbor (ANN) queries across both embedding tables. The solution must minimize the impact of using different chunk sizes.
What should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.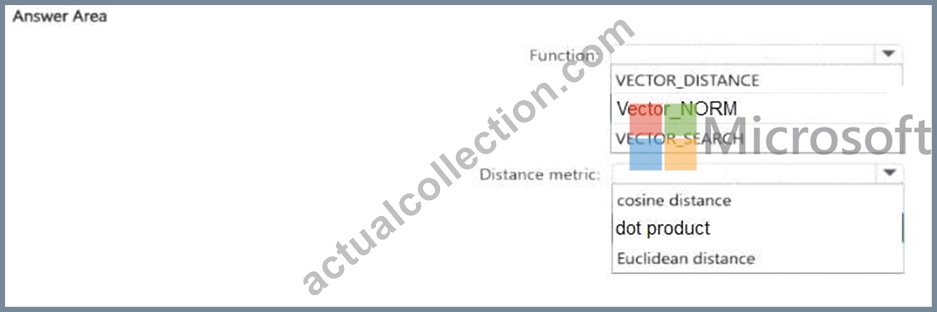
Answer:
Explanation:
Explanation:
The correct function is VECTOR_SEARCH because the requirement is to perform approximate nearest neighbor (ANN) queries. Microsoft's SQL documentation states that VECTOR_SEARCH is the function used for vector similarity search, and that an ANN index is used only with VECTOR_SEARCH when a compatible vector index exists on the target column. By contrast, VECTOR_DISTANCE calculates an exact distance and does not use a vector index for ANN retrieval.
The correct distance metric is cosine distance. Microsoft documents that VECTOR_SEARCH supports cosine, dot, and euclidean metrics, and Microsoft guidance specifically notes that cosine similarity is commonly used for text embeddings. It also states that retrieval of the most similar texts to a given text typically functions better with cosine similarity, and that Azure OpenAI embeddings rely on cosine similarity to compute similarity between a query and documents. Since both NotesEmbeddings and DescriptionEmbeddings are text-derived embeddings and the goal is to minimize the impact of different chunk sizes, cosine is the best choice because it compares direction/angle rather than being as sensitive to vector magnitude as Euclidean distance.
NEW QUESTION # 91
Case Study 2 - Fabrikam
Existing Environment
Azure Environment
Fabrikam has a single Azure subscription in the East US 2 Azure region. The subscription contains an Azure SQL database named DB1. DB1 contains the following tables:
* Patients
* Employees
* Procedures
* Transactions
* UsefulPrompts
* ProcedureDocuments
You store a column master key as a secret in Azure Key Vault.
You have an on-premises application named TransactionProcessing that uses a hard-coded username and password in a connection string to access DB1.
Problem Statements
Users report that after executing a long-running stored procedure named sp_UpdateProcedureForPatient, updates to the underlying data are sometimes inconsistent.
Requirements
Planned Changes
Fabrikam plans to manage all changes to Azure SQL Database objects by using source control in GitHub. Every pull request submitted to production will be validated before it can be merged.
Deployments must use the Release configuration.
Security Requirements
Fabrikam identifies the following security requirements:
* The TransactionProcessing application must use a passwordless connection to DB1.
* The Employees table contains two columns named TaxID and Salary that must be encrypted at rest.
* Auditors must have a tamper-evident history of transactions with cryptographic proof of changes to the employee data.
Database Performance Requirements
Records accessed by using sp_UpdateProcedureForPatient must NOT be changed by other transactions while the stored procedure runs.
AI Search, Embeddings, and Vector Indexing
Fabrikam identifies the following AI-related requirements:
* Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF).
* Users must be able to query the data in DB1 by using prompts in Copilot in Microsoft Fabric.
* The UsefulPrompts table will store prompts that doctors can use to help diagnose patient illness by connecting to an Azure OpenAI endpoint.
Development Requirements
Fabrikam identifies the following development requirements:
* Provide the functionality to retrieve all the transactions of a given patient between two dates, showing a running total.
* Expose a Data API builder (DAB) configuration file to enable Azure services to perform the following operations over a REST API:
- Read data from the procedures table without authentication.
- Read and insert data into the Transactions table once authenticated.
- Execute the sp_UpdateProcedurePatient stored procedure.
* Provide the functionality to retrieve a list of the names of patients who underwent medical procedures during the last 30 days.
* Information for each medical procedure will be stored in a table. The table will be used with a large language model (LLM) for user querying and will have the following structure.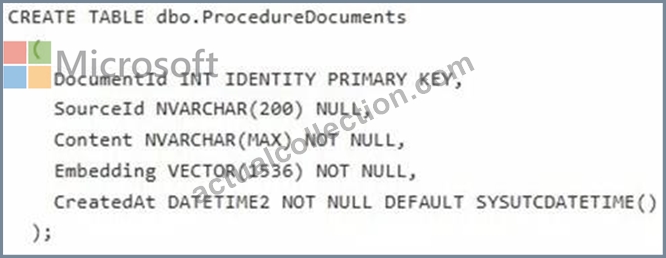
DAB
You create a DAB configuration file that meets the development requirements for DB1 and includes the following entities.
You implement ProcedureDocuments to support the planned changes.
When users consume data through the Retrieval Augmented Generation (RAG) pattern, they experience data retrieval delays.
You need to improve the data retrieval performance and reduce the number of tokens per retrieval.
What should you implement?
Answer: D
Explanation:
Scenario: Fabrikam identifies the following AI-related requirements: Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF).
To remedy data retrieval delays in a Retrieval Augmented Generation (RAG) pattern using Reciprocal Rank Fusion (RRF) on an Azure SQL Database table, you should use embeddings.
In a RAG architecture, retrieval delays often stem from inefficient or computationally heavy search processes. While RRF is excellent for merging results from multiple sources (like combining keyword and vector searches), the core of the speed problem typically lies in how the initial data is indexed and retrieved.
Role of Embeddings
Vector Search Acceleration: Embeddings convert text into high-dimensional vectors. Azure SQL Database can perform similarity searches on these vectors much faster than complex semantic text matching.
Hybrid Search Synergy: RRF is most effective when it fuses results from a keyword search (fast) and a vector search (powered by embeddings). Using embeddings ensures that the "semantic" side of the retrieval is streamlined.
Pre-computation: Since embeddings are generated once during ingestion, the retrieval phase only requires a distance calculation (e.g., Cosine Similarity), which is significantly faster than real- time natural language parsing during each query.
Reference:
https://pratikbarjatya.medium.com/unlocking-the-power-of-language-with-retrieval-augmented- generation-rag-14123cc275e6
NEW QUESTION # 92
......
In this information-dominated society, boosting plenty stocks of knowledge and being competent in some certain area can establish yourself in society and help you get a high social status. Passing DP-800 certification can help you realize these goals and find a good job with high income. If you buy our DP-800 Practice Test you can pass the DP-800 exam successfully and easily. And if you study with our DP-800 exam questions for only 20 to 30 hours, you will pass the DP-800 exam easily.
Reliable DP-800 Practice Questions: https://www.actualcollection.com/DP-800-exam-questions.html
What's more, part of that ActualCollection DP-800 dumps now are free: https://drive.google.com/open?id=134dn7Eg67xYX0apgkAI66CpgN_8jJWY7