Real Snowflake DAA-C01 Questions - Verified By Experts

DOWNLOAD the newest Prep4sureGuide DAA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1ygOSYgFeKQvSgOVc4alKehpfRmfEsCng
Our DAA-C01 practice prep provides you with a brand-new learning method that lets you get rid of heavy schoolbags, lose boring textbooks, and let you master all the important knowledge in the process of making a question. Please believe that with DAA-C01 Real Exam, you will fall in love with learning. Our DAA-C01 exam questions are contained in three versions: the PDF, Software and APP online which can cater to different needs of our customers.
| Section | Objectives |
|---|
| Topic 1: Security, Governance, and Data Sharing | - Data sharing and governance
- 1. Data masking and policies
- 2. Secure data sharing
- Access control and security
- 1. Authentication and encryption concepts
- 2. Role-based access control (RBAC)
|
| Topic 2: Data Loading and Unloading | - Data export
- 1. UNLOAD and external stages
- Data ingestion methods
- 1. Continuous ingestion and Snowpipe concepts
- 2. COPY INTO and bulk loading
|
| Topic 3: Snowflake Architecture and Data Platform Fundamentals | - Snowflake architecture concepts
- 1. Virtual warehouses and scaling
- 2. Cloud services layer, compute layer, storage layer
- Data platform fundamentals
- 1. Data lifecycle in Snowflake
- 2. Separation of storage and compute
|
| Topic 4: Data Modeling and Performance Optimization | - Performance tuning
- 1. Clustering and pruning techniques
- 2. Warehouse sizing and auto-suspend/auto-resume
- Modeling approaches in Snowflake
- 1. Data normalization vs denormalization
- 2. Star and snowflake schemas
|
| Topic 5: Data Transformation and Analysis | - Analytical workloads
- 1. Materialized views and caching
- 2. Query optimization for analytics
- SQL-based transformations
- 1. Semi-structured data (VARIANT, JSON, XML)
- 2. Joins, aggregations, window functions
|
>> Test DAA-C01 Pass4sure <<
2026 The Best Test DAA-C01 Pass4sure | DAA-C01 100% Free Reliable Test Question
The Snowflake DAA-C01 practice exam material is available in three different formats i.e Snowflake DAA-C01 dumps PDF format, web-based practice test software, and desktop DAA-C01 practice exam software. PDF format is pretty much easy to use for the ones who always have their smart devices and love to prepare for DAA-C01 Exam from them. Applicants can also make notes of printed SnowPro Advanced: Data Analyst Certification Exam (DAA-C01) exam material so they can use it anywhere in order to pass Snowflake DAA-C01 Certification with a good score.
Snowflake SnowPro Advanced: Data Analyst Certification Exam Sample Questions (Q61-Q66):
NEW QUESTION # 61
A Data Analyst creates a dashboard showing the total credit consumption for each virtual warehouse as follows:
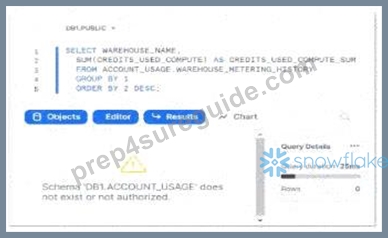
Why is the query failing?
- A. The query must be executed by a user with the ACCOUNTADMIN role.
- B. The current database context must be changed to SNOWFLAKE.
- C. DB1 must be authorized to have SELECT access to ACCOUNT_USAGE.
- D. INFORMATION_SCHEMA should be used instead of ACCOUNT_USAGE.
Answer: B
Explanation:
This error occurs due to a misunderstanding of how Snowflake resolves object names and the location of the Shared Snowflake Database. In Snowflake, the ACCOUNT_USAGE schema is a collection of views that provide comprehensive historical data about account activities, including credit consumption, storage, and query history. These views are stored within the system-defined database named SNOWFLAKE.
When the Data Analyst executes the query shown in the image, they are operating within the database context of DB1 and the schema context of PUBLIC. Because the query references ACCOUNT_USAGE.
WAREHOUSE_METERING_HISTORY without a fully qualified name, the Snowflake compiler attempts to resolve the object starting from the current database context. Consequently, it looks for a schema named ACCOUNT_USAGE inside DB1. As the error message correctly indicates, Schema 'DB1.
ACCOUNT_USAGE' does not exist.
To fix this, the Analyst has two options:
* Fully Qualify the Object Name: Modify the query to reference the full path: FROM SNOWFLAKE.
ACCOUNT_USAGE.WAREHOUSE_METERING_HISTORY. This is the most common best practice as it allows the query to run regardless of the user's current session context.
* Change the Context: Use the command USE DATABASE SNOWFLAKE; before running the query.
This changes the session's database context so that ACCOUNT_USAGE can be found.
It is a common misconception (represented in Option A) that only an ACCOUNTADMIN can access these views. While access is restricted by default, the ACCOUNTADMIN can grant IMPORTED PRIVILEGES on the SNOWFLAKE database to other roles, such as a Data Analyst role. However, the specific error shown is a namespace resolution error, not a permission-denied error (which would typically say "Insufficient privileges"). Therefore, changing the context or fully qualifying the name is the direct solution to this specific failure.
NEW QUESTION # 62
You're working with time series data in Snowflake, specifically website traffic data with timestamps and page views. You need to calculate the cumulative page views for each day. However, the data contains missing timestamps, and you want to fill those gaps with a default page view count of 0 before calculating the cumulative sum. Which of the following approaches, used in conjunction with a cumulative SUM aggregate function, is MOST efficient?
- A. Create a separate table containing all dates in the range and LEFT JOIN it with the website traffic data, using COALESCE to fill missing page views with 0 before applying the cumulative SUM.
- B. Use a stored procedure to iterate through the date range, inserting missing dates with a page view count of O before applying the cumulative SUM.
- C. Use the 'GENERATE_SERIES' function (if available via UDF) to create a series of dates, LEFT JOIN with the website traffic data, and use COALESCE to fill missing page views with 0 before the cumulative SUM.
- D. Use a recursive CTE (Common Table Expression) to generate the missing dates and then UNION ALL with the existing data, filling missing page views with 0 using NVL, prior to applying the cumulative SUM.
- E. Use a LATERAL FLATTEN function to generate a list of dates, LEFT JOIN it with the website traffic data, and use ZEROIFNULL to fill missing page views with 0 before the cumulative SUM.
Answer: A
Explanation:
Creating a separate date table and using a LEFT JOIN with COALESCE is the most efficient approach. Stored procedures (A) are generally slower for large datasets. Recursive CTEs (C) can be resource-intensive. Using UDFs or Lateral Flatten (D & E) may also increase complexity and overhead compared to a simple JOIN. The key is to leverage Snowflake's ability to handle joins efficiently.
NEW QUESTION # 63
You're working with product catalog data in Snowflake. The product information is stored in a table named 'PRODUCTS' , and a key attribute, 'attributes' , contains a semi-structured JSON object for each product. This 'attributes' object can have varying keys, but you are interested in extracting specific keys and pivoting them into columns. The relevant JSON structure is as follows : { "color": "red", "size": "L", "material": "cotton", "style": "casual"} '"What method is the MOST efficient to transform this data to a relational structure, assuming you want to analyze product attributes such as 'color' and 'size' as separate columns?
- A. Using dynamic SQL to generate a query that extracts the required attributes using JSON path accessors and then creates a new table.
- B. Using a stored procedure to iterate through each row, parse the JSON, and update a new table with pivoted columns.
- C. Creating a view with direct JSON path accessors (e.g., for each desired attribute.
- D. Using LATERAL FLATTEN to unnest the 'attributes' and then using a CASE statement to pivot the data.
- E. Creating a new table with a 'VARIANT column for the attributes and performing transformations in a BI tool.
Answer: C
Explanation:
Option B is the most efficient. Directly accessing the JSON elements using path accessors like allows Snowflake to optimize the query execution, which typically offers superior performance compared to flattening and pivoting with 'CASE statements. Flattening (Option A) introduces unnecessary complexity and overhead when specific attributes are known and desired. Options C and D are generally inefficient and should be avoided for this type of transformation. Creating a view is more performant and simple. Option E is overkill and introduces complexity that isn't needed since the required attributes are known.
NEW QUESTION # 64
You have a Snowflake table named 'sensor_data' with a column 'reading' containing JSON data'. The JSON structure varies, but you want to extract a specific nested value, 'temperature', using a UDE The path to 'temperature' might be different depending on the 'sensor_type'. Some sensors have the temperature at '$.metrics.temperature' , others at '$.reading.temp_c'. The sensor type is stored in the 'sensor_type' column. You want to create a UDF named which takes the JSON 'reading' and the 'sensor_type' as input and extracts the temperature, returning NULL if the path does not exist in the JSON. How can you implement this using a JavaScript UDF and Snowflake's JSON parsing functions for optimal performance?
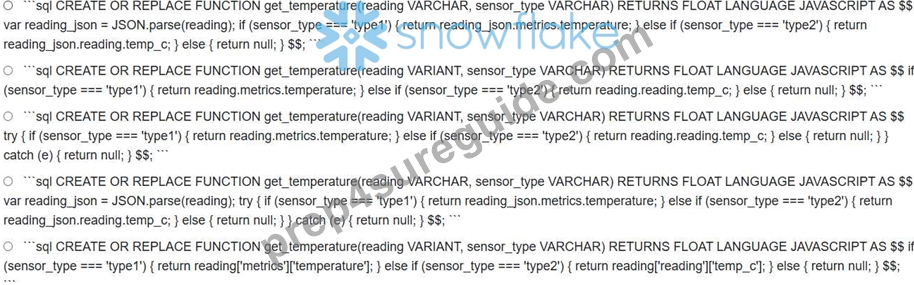
- A. Option D
- B. Option C
- C. Option B
- D. Option E
- E. Option A
Answer: B
Explanation:
Option C is the MOST optimal. It uses 'VARIANT as the input data type for 'reading' , which avoids the unnecessary parsing of JSON using as Snowflake automatically parses JSON data into a VARIANT type. It also includes a 'try...catch' block to handle cases where the specified path does not exist within the JSON, returning 'NULL' as required. This prevents errors from halting the query. Using 'VARIANT directly and exception handling offers superior performance. Option A and D parse VARIANT as String, leading to parsing overhead. B misses the try catch block and is prone to failure when temp is not available for a given sensor. Option E is less efficient than option C due to using array notation.
NEW QUESTION # 65
What role does operationalizing data play in maintaining reports and dashboards for business requirements?
- A. Operationalizing data complicates dashboard management.
- B. Operationalizing data ensures consistent and efficient usage.
- C. It limits the usability of reports by narrowing down access.
- D. It restricts data updates, affecting dashboard accuracy.
Answer: B
Explanation:
Operationalizing data ensures consistent and efficient usage of reports and dashboards.
NEW QUESTION # 66
......
It is not hard to know that SnowPro Advanced: Data Analyst Certification Exam torrent prep is compiled by hundreds of industry experts based on the syllabus and development trends of industries that contain all the key points that may be involved in the examination. Therefore, with DAA-C01 exam questions, you no longer need to purchase any other review materials, and you also don’t need to spend a lot of money on tutoring classes. At the same time, DAA-C01 Test Guide will provide you with very flexible learning time in order to help you pass the exam.
Reliable DAA-C01 Test Question: https://www.prep4sureguide.com/DAA-C01-prep4sure-exam-guide.html
- Exam DAA-C01 Forum 🤽 Premium DAA-C01 Exam 🟧 Exam DAA-C01 Forum 🦪 Download ▛ DAA-C01 ▟ for free by simply entering ✔ www.exam4labs.com ️✔️ website 🍧Latest DAA-C01 Test Format
- Reliable DAA-C01 Exam Question 🐗 Latest DAA-C01 Test Format 💹 Dumps DAA-C01 Cost 🎓 Easily obtain ⇛ DAA-C01 ⇚ for free download through ➤ www.pdfvce.com ⮘ ⏹DAA-C01 Vce Free
- Get Excellent Marks in One Go with Snowflake DAA-C01 Real Dumps ➡️ Open website “ www.testkingpass.com ” and search for ➠ DAA-C01 🠰 for free download 🩸DAA-C01 Flexible Testing Engine
- Latest DAA-C01 Test Format 🟤 Dumps DAA-C01 Cost 🔋 DAA-C01 Preparation 🍮 Download ⇛ DAA-C01 ⇚ for free by simply searching on ➡ www.pdfvce.com ️⬅️ 🦺DAA-C01 Exam Collection
- Valid DAA-C01 Exam Fee 😦 Simulations DAA-C01 Pdf 💢 Regualer DAA-C01 Update ⏰ ▷ www.testkingpass.com ◁ is best website to obtain ▛ DAA-C01 ▟ for free download 🦸DAA-C01 Flexible Testing Engine
- DAA-C01 Reliable Exam Question 🌍 Valid DAA-C01 Exam Fee 🪕 DAA-C01 Exam Collection ▛ Open ➤ www.pdfvce.com ⮘ and search for ( DAA-C01 ) to download exam materials for free 🥞Training DAA-C01 Tools
- DAA-C01 Exam Certification Cost 🅿 Latest DAA-C01 Test Format 💓 DAA-C01 Reliable Exam Pattern 🦸 Open ➥ www.examcollectionpass.com 🡄 and search for ⮆ DAA-C01 ⮄ to download exam materials for free 🎳Regualer DAA-C01 Update
- Use DAA-C01 Practice Exam Software For Self Evaluation ✨ Simply search for ➤ DAA-C01 ⮘ for free download on ▶ www.pdfvce.com ◀ 🏓DAA-C01 Flexible Testing Engine
- DAA-C01 Exam Collection 🚮 DAA-C01 Reliable Exam Question ➖ DAA-C01 Reliable Exam Question 🏊 Open “ www.pass4test.com ” enter ▶ DAA-C01 ◀ and obtain a free download 🍠DAA-C01 Flexible Testing Engine
- Dumps DAA-C01 Cost ♿ Valid DAA-C01 Exam Fee 🪔 DAA-C01 Vce Free 💚 Download { DAA-C01 } for free by simply entering ▛ www.pdfvce.com ▟ website 🐧DAA-C01 Test Answers
- Authentic Snowflake DAA-C01 Dumps PDF - The Best Way To Pass Exam 🦺 Open ➥ www.dumpsquestion.com 🡄 and search for ▷ DAA-C01 ◁ to download exam materials for free 🐁DAA-C01 Exam Collection
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, p.me-page.com, mayagriffiths253.blogspot.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Free 2026 Snowflake DAA-C01 dumps are available on Google Drive shared by Prep4sureGuide: https://drive.google.com/open?id=1ygOSYgFeKQvSgOVc4alKehpfRmfEsCng