Certified-Data-Engineer-Professional最新対策問題 & Certified-Data-Engineer-Professional関連試験

DatabricksのCertified-Data-Engineer-Professional試験に受かることを通じて現在の激しい競争があるIT業種で昇進したくて、IT領域で専門的な技能を強化したいのなら、豊富なプロ知識と長年の努力が必要です。DatabricksのCertified-Data-Engineer-Professional試験に受かるのはあなたが自分をIT業種にアピールする方法の一つです。でも、試験に合格するために大量な時間とエネルギーを費やすことはなく、Fast2testのDatabricksのCertified-Data-Engineer-Professional試験トレーニング資料を選んだらいいです。Fast2testのトレーニング資料はIT認証試験に受かるために特別に研究されたものですから、この資料を手に入れたら難しいDatabricksのCertified-Data-Engineer-Professional認定試験に気楽に合格することができるようになります。
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- Advanced Data Transformation
- 1. Write efficient Spark SQL and PySpark transformations
- 2. Apply window functions, joins, and aggregations to large datasets
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 2. Build append-only pipelines for batch and streaming data using Delta
- 3. Ingest data from message buses and cloud storage
|
| Monitoring and Alerting | - Monitoring
- 1. Use system tables for resource, cost, audit, and workload monitoring
- 2. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 3. Use Query Profiler and Spark UI to monitor workloads
- 4. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
- Debugging and Troubleshooting
- 1. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 2. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 3. Analyze errors and remediate failed job runs
|
| Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Configure sharing with external platforms using the open sharing protocol
- 2. Configure Databricks-to-Databricks Sharing
- 3. Share live Lakehouse data with external computing platforms
|
| Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Ensuring Data Security and Compliance | - Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
- Data Security
- 1. Apply anonymization and pseudonymization techniques
- 2. Use row filters and column masks for sensitive data
- 3. Use ACLs to secure workspace objects and enforce least privilege
|
| Cost & Performance Optimisation | - Delta Optimization
- 1. Use Change Data Feed to address streaming table limitations and improve latency
- 2. Apply data skipping and file pruning techniques
- 3. Understand deletion vectors and liquid clustering
- Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
|
| Data Modelling | - Scalable Data Models
- 1. Optimize data layout using Liquid Clustering
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Design and implement scalable data models using Delta Lake
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Compare streaming tables and materialized views
- 2. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 3. Use control flow operators in pipeline components
- 4. Configure environments, dependencies, memory, and retry behavior
- 5. Use APPLY CHANGES APIs for change data capture
- 6. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 7. Develop unit and integration tests for data processing code
- 8. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDFs
- 2. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 3. Manage and troubleshoot third-party library installations and dependencies
|
>> Certified-Data-Engineer-Professional最新対策問題 <<
Certified-Data-Engineer-Professional関連試験 & Certified-Data-Engineer-Professional最新知識
DatabricksPDFバージョン、PCバージョン、APPオンラインバージョンなど、3つの異なるバージョンのDatabricks Certified Data Engineer Professional prepトレントを選択できます。 異なるバージョンには独自の利点とユーザー数があります。PDFバージョンの機能をご紹介します。 Fast2testのCertified-Data-Engineer-Professional試験トレントのPDFは、主にデモの利便性のために、若者の間で最も一般的なバージョンであることに疑いの余地はありません。Databricks Certified Data Engineer Professional 印刷してメモを取ることができます。
Databricks Certified Data Engineer Professional 認定 Certified-Data-Engineer-Professional 試験問題 (Q200-Q205):
質問 # 200
Which of the following is true of Delta Lake and the Lakehouse?
- A. Primary and foreign key constraints can be leveraged to ensure duplicate values are never entered into a dimension table.
- B. Views in the Lakehouse maintain a valid cache of the most recent versions of source tables at all times.
- C. Delta Lake automatically collects statistics on the first 32 columns of each table which are leveraged in data skipping based on query filters.
- D. Z-order can only be applied to numeric values stored in Delta Lake tables
- E. Because Parquet compresses data row by row. strings will only be compressed when a character is repeated multiple times.
正解:C
解説:
Delta Lake automatically collects statistics on the first 32 columns of each table, which are leveraged in data skipping based on query filters. Data skipping is a performance optimization technique that aims to avoid reading irrelevant data from the storage layer. By collecting statistics such as min/max values, null counts, and bloom filters, Delta Lake can efficiently prune unnecessary files or partitions from the query plan. This can significantly improve the query performance and reduce the I/O cost.
質問 # 201
A data engineer has created a new cluster using shared access mode with default configurations.
The data engineer needs to allow the development team access to view the driver logs if needed.
What are the minimal cluster permissions that allow the development team to accomplish this?
- A. CAN MANAGE
- B. CAN RESTART
- C. CAN ATTACH TO
- D. CAN VIEW
正解:D
解説:
The CAN VIEW permission on a cluster allows users to see cluster details, including driver and executor logs. This is the minimal permission required for the development team to access logs without granting them the ability to modify, restart, or attach notebooks to the cluster.
質問 # 202
Which configuration parameter directly affects the size of a spark-partition upon ingestion of data into Spark?
- A. spark.sql.files.maxPartitionBytes
- B. spark.sql.adaptive.advisoryPartitionSizeInBytes
- C. spark.sql.autoBroadcastJoinThreshold
- D. spark.sql.adaptive.coalescePartitions.minPartitionNum
- E. spark.sql.files.openCostInBytes
正解:A
解説:
This is the correct answer because spark.sql.files.maxPartitionBytes is a configuration parameter that directly affects the size of a spark-partition upon ingestion of data into Spark. This parameter configures the maximum number of bytes to pack into a single partition when reading files from file- based sources such as Parquet, JSON and ORC. The default value is 128 MB, which means each partition will be roughly 128 MB in size, unless there are too many small files or only one large file.
質問 # 203
An external object storage container has been mounted to the location /mnt/finance_eda_bucket.
The following logic was executed to create a database for the finance team:
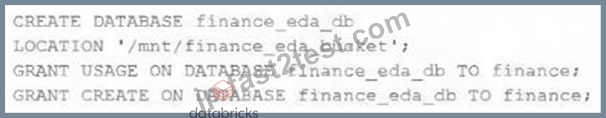
After the database was successfully created and permissions configured, a member of the finance team runs the following code:
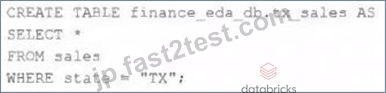
If all users on the finance team are members of the finance group, which statement describes how the tx_sales table will be created?
- A. An managed table will be created in the storage container mounted to /mnt/finance_eda_bucket.
- B. A managed table will be created in the DBFS root storage container.
- C. A logical table will persist the physical plan to the Hive Metastore in the Databricks control plane.
- D. A logical table will persist the query plan to the Hive Metastore in the Databricks control plane.
- E. An external table will be created in the storage container mounted to /mnt/finance eda bucket.
正解:A
解説:
https://docs.databricks.com/en/data-governance/unity-catalog/create-schemas.html#language-SQL
質問 # 204
A company processes semi-structured JSON files from an external source using Auto Loader in a classic Databricks job. Occasionally, records arrive with null critical fields, invalid types, or unexpected nested schema variations. The engineer must ensure that malformed or non- conforming records are not dropped silently and are captured in a separate quarantine table. The pipeline should continue processing good records into the Bronze layer without failing the job, and the approach must support both batch and streaming ingestion.
The data engineer needs to build a robust ingestion pattern that automatically routes bad records to a quarantine Delta table, while still ingesting good records into the Bronze layer for further processing.
Which approach fulfills the quarantine mechanism in this ingestion architecture?
- A. Create a notebook job with inferSchema=True, write a streaming query with .foreachBatch() and catch exceptions using try/except to redirect failed batches to quarantine.
- B. Use Lakeflow Spark Declarative Pipelines with a SQL pipeline; configure it to drop rows with nulls using where critical_fields is not null, and rely on audit logs for malformed data.
- C. Use Auto Loader with LDP and implement an EXPECT () constraint with a record audit logic to route bad records.
- D. Use Auto Loader with failFast mode to set to false, and enable schema evolution; invalid records will be silently ignored during ingestion.
正解:C
解説:
Lakeflow Spark Declarative Pipelines provide built-in support for data quality enforcement using EXPECT clauses. By defining expectations on critical fields and configuring the pipeline to audit or quarantine failed records, malformed or non-conforming JSON records are automatically routed to a quarantine Delta table while valid records continue flowing into the Bronze layer. This approach is robust, auditable, works for both batch and streaming ingestion, and avoids silently dropping bad data or failing the pipeline.
質問 # 205
......
DatabricksのCertified-Data-Engineer-Professional認定試験に受かることを悩んでいたら、Fast2testを選びましょう。Fast2testのDatabricksのCertified-Data-Engineer-Professional試験トレーニング資料は間違いなく最高のトレーニング資料ですから、それを選ぶことはあなたにとって最高の選択です。IT専門家になりたいですか。そうだったら、Fast2testを利用したください。
Certified-Data-Engineer-Professional関連試験: https://jp.fast2test.com/Certified-Data-Engineer-Professional-premium-file.html
- ハイパスレートCertified-Data-Engineer-Professional最新対策問題 - 資格試験におけるリーダーオファー - 最新の更新Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional 🐕 “ www.passtest.jp ”に移動し、《 Certified-Data-Engineer-Professional 》を検索して無料でダウンロードしてくださいCertified-Data-Engineer-Professional試験準備
- Certified-Data-Engineer-Professional認定試験 🧆 Certified-Data-Engineer-Professional真実試験 🐌 Certified-Data-Engineer-Professional試験準備 🚨 ➡ www.goshiken.com ️⬅️にて限定無料の“ Certified-Data-Engineer-Professional ”問題集をダウンロードせよCertified-Data-Engineer-Professional問題数
- 素敵Databricks Certified-Data-Engineer-Professional|便利なCertified-Data-Engineer-Professional最新対策問題試験|試験の準備方法Databricks Certified Data Engineer Professional関連試験 🦊 ➥ www.mogiexam.com 🡄サイトにて最新➠ Certified-Data-Engineer-Professional 🠰問題集をダウンロードCertified-Data-Engineer-Professional模擬問題
- Certified-Data-Engineer-Professional合格対策 🏘 Certified-Data-Engineer-Professional受験対策書 👣 Certified-Data-Engineer-Professional受験対策書 📻 ➽ www.goshiken.com 🢪から簡単に➽ Certified-Data-Engineer-Professional 🢪を無料でダウンロードできますCertified-Data-Engineer-Professional赤本勉強
- 有難い-素晴らしいCertified-Data-Engineer-Professional最新対策問題試験-試験の準備方法Certified-Data-Engineer-Professional関連試験 🐟 今すぐ▶ www.it-passports.com ◀で➥ Certified-Data-Engineer-Professional 🡄を検索して、無料でダウンロードしてくださいCertified-Data-Engineer-Professional模擬問題
- Certified-Data-Engineer-Professional認定試験 🗜 Certified-Data-Engineer-Professional模擬資料 🥜 Certified-Data-Engineer-Professional認定試験 🔣 [ Certified-Data-Engineer-Professional ]を無料でダウンロード➡ www.goshiken.com ️⬅️で検索するだけCertified-Data-Engineer-Professional学習資料
- Certified-Data-Engineer-Professional試験勉強攻略 😙 Certified-Data-Engineer-Professional認定試験 ⭐ Certified-Data-Engineer-Professional試験解説問題 🦈 URL ⏩ www.passtest.jp ⏪をコピーして開き、[ Certified-Data-Engineer-Professional ]を検索して無料でダウンロードしてくださいCertified-Data-Engineer-Professional復習問題集
- Certified-Data-Engineer-Professional受験対策書 ⌚ Certified-Data-Engineer-Professional模擬問題 👹 Certified-Data-Engineer-Professional受験対策書 🚒 ⮆ Certified-Data-Engineer-Professional ⮄の試験問題は➠ www.goshiken.com 🠰で無料配信中Certified-Data-Engineer-Professional復習問題集
- 便利なDatabricks Certified-Data-Engineer-Professional最新対策問題 - 合格スムーズCertified-Data-Engineer-Professional関連試験 | 最高のCertified-Data-Engineer-Professional最新知識 🧏 ( Certified-Data-Engineer-Professional )を無料でダウンロード「 www.passtest.jp 」ウェブサイトを入力するだけCertified-Data-Engineer-Professional無料試験
- Certified-Data-Engineer-Professional無料試験 🕧 Certified-Data-Engineer-Professional認定試験 💇 Certified-Data-Engineer-Professional受験対策書 😘 [ www.goshiken.com ]の無料ダウンロード➠ Certified-Data-Engineer-Professional 🠰ページが開きますCertified-Data-Engineer-Professional試験勉強攻略
- Certified-Data-Engineer-Professional問題数 🙎 Certified-Data-Engineer-Professional日本語版テキスト内容 ⛄ Certified-Data-Engineer-Professional合格対策 🦏 最新➤ Certified-Data-Engineer-Professional ⮘問題集ファイルは⏩ jp.fast2test.com ⏪にて検索Certified-Data-Engineer-Professional模擬問題
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes