P.S. GoShikenがGoogle Driveで共有している無料かつ新しいHPE7-J01ダンプ:https://drive.google.com/open?id=15mWYnLnBJ8atZU9zBbkVlmf6lJdrNsc6
良いサイトは、高品質のHPE7-J01信頼できるダンプトレントを生成します。 関連製品を購入する場合は、この会社に力があるかどうか、製品が有効かどうかを明確にする必要があります。 HPE7-J01信頼できるダンプトレント。 一部の企業は、低価格の製品による素晴らしい販売量を持ち、彼らの質問と回答はインターネットで収集されますが、それは非常に不正確です。 本当に一発で試験に合格したい場合は、注意が必要です。 高品質のHP HPE7-J01信頼性の高いトレントを手頃な価格で提供するのが最良の選択肢です。
| Section | Weight | Objectives |
|---|---|---|
| Management and Optimization | 15% | - Monitoring and administration
|
| Storage Architecture and Design | 30% | - Design principles for enterprise storage
|
| Data Protection and Availability | 25% | - Backup and recovery strategies
|
| Emerging Technologies and Solutions | 10% | - Hybrid cloud and multi-cloud storage
|
| Deployment and Integration | 20% | - Networking and connectivity
|
初心者にとって、HPE7-J01試験に合格するのはそんなに難しいことですか?実は、我々GoShikenのHPE7-J01問題集を選んで利用し、お客様は力の限りまで勉強して、合格しやすいです。万が一パースしない場合には、弊社は全額返金を承諾いたします。返金を願うのに対して、お客様はHPE7-J01に合格しない成績書を弊社に送付して、弊社は確認の後、支払い金額を全部返済します。
質問 # 71
An administrator needs to create an FCIP trunk connection between two data centers to interconnect their Brocade fibre data fabrics. Refer to the exhibit.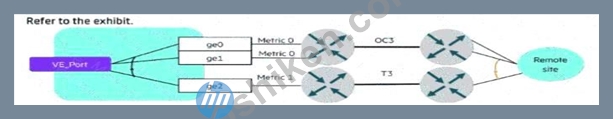
Based on this configuration, which statement is correct?
正解:D
解説:
In a Brocade FCIP (Fibre Channel over IP) environment, an extension trunk (or tunnel) can be composed of multiple circuits to provide both increased bandwidth and high availability. The operational state of these circuits-whether they are active or standby-is determined by the Metric assigned to each individual circuit.
According to the Brocade Fabric OS Extension Configuration Guide, all circuits within a tunnel or trunk have a metric of either 0 or 1.
* Metric 0: This is the default value and indicates an active circuit. If multiple circuits are configured with Metric 0, they will operate in an active-active mode, and the load will be balanced across them.
* Metric 1: This indicates a standby (or passive) circuit. Standby circuits with Metric 1 are not used for data transmission unless all Metric 0 circuits within that tunnel/failover group fail.
In the provided exhibit, there is a single VE_Port (Virtual E_Port) trunking three individual IP circuits:
* ge0 is configured with Metric 0 (Active).
* ge1 is configured with Metric 0 (Active).
* ge2 is configured with Metric 1 (Standby).
Therefore, this is a valid configuration where the system will utilize the two Metric 0 circuits (ge0 and ge1) simultaneously for data traffic, providing an active-active load-balanced connection. The third circuit (ge2) will remain in a standby state, only becoming active to maintain the link if both primary circuits go offline.
Options A and B are incorrect because trunks do not require an even number of circuits, and FCIP trunks are specifically established over Ethernet (ge) ports, not native Fibre Channel ports.
質問 # 72
A customer wants to implement an HPE Morpheus life-cycle management solution at a single site with 1004 VMs using a redundant architecture and distributed services. Which statement is correct regarding the setup and operation of this solution?
正解:A
解説:
When designing an HPE Morpheus environment for an enterprise-scale workload (such as
1,000+ VMs), a standalone "all-in-one" installation is insufficient for high availability (HA) and performance requirements. Instead, a 3-node Distributed Architecture must be implemented to ensure redundancy across all critical service layers.
In a distributed, redundant Morpheus setup, the architecture is broken down into three primary tiers: the Application tier, the Database tier (MySQL/Percona), and the Messaging/Search tier (Elasticsearch and RabbitMQ). To achieve a basic redundant footprint, you require at least two Morpheus application nodes, three database nodes (for quorum), and a messaging cluster.
According to the HPE Morpheus Architecture and Sizing Guide, a standard HA deployment starts with a minimum of six VMs to separate these functions. However, for a production environment of this size, it is recommended to have a minimum of 10 VMs. This expanded footprint typically includes 3 App nodes, 3 Database nodes, and a 3-node cluster for Elasticsearch /RabbitMQ, plus a dedicated load balancer or management node, ensuring that the loss of any single host does not impact the management plane's availability.
質問 # 73
A customer is considering purchasing an HPE StoreOnce solution to meet their VMware VM data protection needs. Which two Veeam features, paired with HPE StoreOnce, will validate the restoration of backups and allow the customer to easily create labs for validation testing from backups? (Choose two.)
正解:C、D
解説:
The integration of Veeam Backup & Replication with HPE StoreOnce via the StoreOnce Catalyst protocol offers specialized features that transform static backup data into active assets for testing and verification. To address the specific requirements of validating restores and creating testing environments, Veeam utilizes the SureBackup and DataLabs features.
Veeam SureBackup is the primary feature used to validate the recoverability of backups. It automates the process of testing a backup by booting the VM directly from the StoreOnce repository in an isolated environment (Virtual Lab). It performs heartbeats, network tests, and application-specific tests (such as checking if a SQL database responds) to ensure the data is not just present, but functional. Because HPE StoreOnce Gen4+ systems feature flash-accelerated metadata and improved random read performance, they are "Veeam Ready" to support the I/O requirements of starting VMs for these verification tasks.
Veeam DataLabs (formerly known as Virtual Lab or On-Demand Sandbox) is the broader orchestration framework that allows customers to leverage their backup data for "Labs." By creating a DataLab, an administrator can spin up an isolated copy of the production environment from the StoreOnce backups. This is used for "validation testing," such as testing security patches, verifying application upgrades, or performing
"DevOps" tasks without impacting the production systems. Option C (Immutability) and Option E (Virtual Lock) are critical for ransomware protection but do not directly facilitate the "lab creation" or "validation testing" workflows described. Option A is a general data transfer mechanism. By selecting B and D, the storage architect ensures a solution that not only protects data but proactively proves its readiness for disaster recovery.
質問 # 74
A company has a pair of Alletra 9000s, managed via the HPE GreenLake Data Services Cloud Console (DSCC). An administrator installed Kubernetes locally but requires persistent storage using the Alletra 9000s.
After installing the helm repo for the HPE CSI Driver for Kubernetes, what is the next step the administrator should perform to use the Alletra 9000s for persistent storage?
正解:D
解説:
The deployment of the HPE CSI (Container Storage Interface) Driver involves several sequential steps to enable dynamic provisioning of storage on HPE Alletra 9000 arrays. Once the Helm repository has been added, the administrator must provide the driver with the necessary authentication and connectivity details for the storage backend.
According to the HPE Storage Container Orchestration Documentation (SCOD), the definitive next step to enable communication between the Kubernetes cluster and the Alletra 9000 is to create a Kubernetes Secret. This Secret contains critical parameters such as the storage array's IP address or FQDN, and the management credentials (username and password). Without this Secret, the CSI driver cannot authenticate against the Alletra 9000 REST API to perform volume creation, mounting, or snapshot operations.
While creating a StorageClass (Option C) is a required step, it follows the creation of the Secret. The StorageClass definition must specifically reference the name of the Secret to identify which storage backend should be used for a particular tier of service. Option A (creating a namespace) is often done as part of the helm install command itself (using the --create-namespace flag) and is a general administrative task rather than a storage-specific configuration step. Option D is incorrect as the Alletra 9000 does not pull credentials from the Kubernetes conductor; rather, the Kubernetes driver pushes requests to the array using the credentials stored in the Kubernetes Secret. Establishing this secure handshake via the Secret is the foundational step for all subsequent persistent volume (PV) and persistent volume claim (PVC) activities.
質問 # 75
A customer has a variety of HPE Alletra arrays running various VM workloads managed by VMware vCenter. These arrays are managed with HPE GreenLake. The customer is concerned they are not getting the best efficiency from the HPE storage arrays. You access CloudPhysics in GreenLake to get an overall view of the hosts and VMs that have the biggest impact on the customer's current environment. Which card should you first examine to see this information?
正解:C
解説:
HPE CloudPhysics is a SaaS-based analytics platform integrated into the HPE GreenLake Data Services Cloud Console (DSCC) that provides deep insights into virtualized infrastructure. It uses a visual metaphor called "cards" to present focused analytics for specific use cases.
When a customer is concerned about storage efficiency and the overall impact of VM workloads, the Simulator for VM Rightsizing (also known as the VM Rightsizing Simulator) is the primary tool for analysis. This card specifically identifies inefficiencies such as over-provisioned or "oversized" virtual machines. By analyzing the actual resource utilization (CPU, memory, and I/O) versus the allocated capacity, the rightsizing simulator can highlight which VMs are consuming excessive resources without operational need.
Reviewing this card first is critical because storage efficiency is often compromised by "virtual sprawl" and bloated VM templates that waste disk space and IOPS on the backend HPE Alletra arrays. While the Shared Storage Analysis card (Option C) provides visibility into datastore contention and performance, the Simulator for VM Rightsizing provides the most direct answer to "efficiency" concerns by identifying the exact VMs that can be trimmed down to reclaim stranded capacity. Correcting VM sizing at the hypervisor level is often the most effective first step in optimizing the performance and capacity return on investment of the underlying storage hardware.
質問 # 76
......
HPE7-J01試験問題は、専門家によって編集され、長年の経験を持つ専門家によって承認されています。言語は理解しやすいため、学習者に障害はありません。HPのHPE7-J01ガイド急流は誰にでも適しています。コンテンツは習得が容易であり、重要な情報を簡素化しました。 HPE7-J01テストトレントは、より重要な情報を少ない質問と回答で伝え、学習をリラックスして効率的にします。 HPE7-J01試験問題を使用すると、HPE7-J01試験に簡単に合格できます。
HPE7-J01試験対策: https://www.goshiken.com/HP/HPE7-J01-mondaishu.html
さらに、GoShiken HPE7-J01ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=15mWYnLnBJ8atZU9zBbkVlmf6lJdrNsc6