P.S. Free & New AI-200 dumps are available on Google Drive shared by PDFTorrent: https://drive.google.com/open?id=1nHL9S__p4Q2xPKa-otfjIZkmZ-1Hdz8I
PDFTorrent's products are developed by a lot of experienced IT specialists using their wealth of knowledge and experience to do research for IT certification exams. So if you participate in Microsoft certification AI-200 exam, please choose our PDFTorrent's products, PDFTorrent can not only provide you a wide coverage and good quality exam information to guarantee you to let you be ready to face this very professional exam but also help you pass Microsoft Certification AI-200 Exam to get the certification.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure, monitor, and optimize AI solutions | 20% | - Manage security and configuration
|
| Topic 2: Develop containerized AI solutions on Azure | 25% | - Monitor and troubleshoot containerized workloads
|
| Topic 3: Integrate backend services and build event-driven architectures | 25% | - Implement messaging and event systems
|
| Topic 4: Develop AI solutions using Azure data services | 30% | - Implement vector-enabled databases
|
Everybody wants success, but not everyone has a strong mind to persevere in study. If you feel unsatisfied with your present status, our AI-200 actual exam can help you out. Our products always boast a pass rate as high as 99%. Using our AI-200 study materials can also save your time in the exam preparation. If you choose our AI-200 Test Engine, you are going to get the AI-200 certification easily. Just make your choice and purchase our study materials and start your study right now!
NEW QUESTION # 77
You plan to deploy a web application to AKS.
The solution must:
* Scale out the application by adding more pods during peak CPU usage
* Expose the application internally within the cluster only
You need to configure a Kubernetes resource for each requirement
Which resources should you configure? To answer, move the appropriate resources to the correct requirements You may use each resource once, more than once, or not at all. You may need to move split bar between .. or scroll to view content.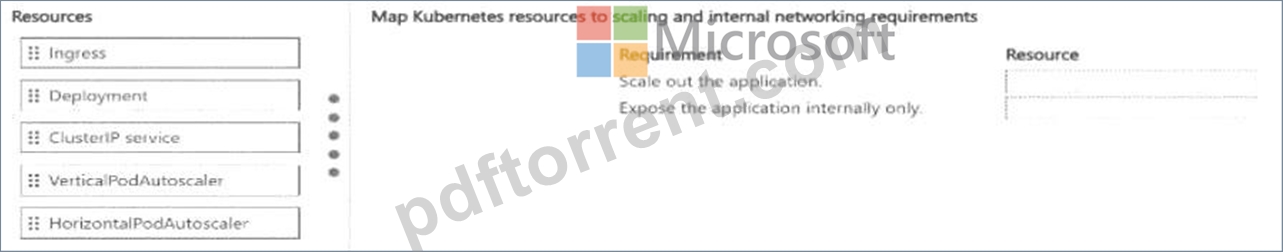
Answer:
Explanation: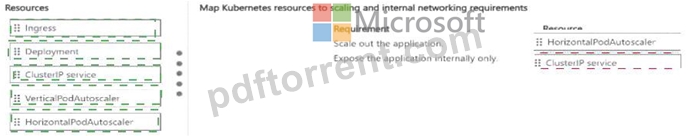
Explanation: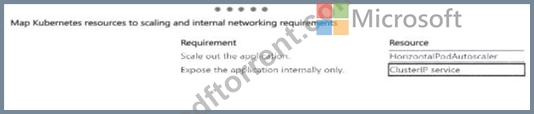
Verified answer: Scale out the application: HorizontalPodAutoscaler. Expose internally only: ClusterIP service.
Detailed Explanation: The Kubernetes HorizontalPodAutoscaler increases or decreases pod replicas in response to CPU, memory, or other metrics, so it is the resource that implements CPU-driven pod scale-out. A ClusterIP service creates an internal service IP that is reachable within the Kubernetes cluster and is the normal choice for an internal-only service. A Deployment defines the workload but does not itself implement metric-driven autoscaling, while Ingress is intended to route inbound network traffic.
Study Guide Alignment: Containerized Azure workloads: registry builds, App Service containers, Container Apps revision/scaling behavior, and AKS deployment choices.
Official Microsoft Learn References: AI-200 Study Guide | AKS scaling overview | Kubernetes services in AKS
NEW QUESTION # 78
You are developing a Java application that uses Apache Cassandra to store key and value data.
You plan to use a new Azure Cosmos DB resource and the Azure Cosmos DB for Apache Cassandra API in the application. You create a Microsoft Entra ID group named Azure Cosmos DB Creators to enable provisioning of Azure Cosmos DB accounts, databases, and containers.
The Microsoft Entra ID group must not be able to access the keys that are required to access the data.
You need to restrict access to the Microsoft Entra ID group.
Which role-based access control should you use?
Answer: A
Explanation:
The Azure Cosmos DB Operator built-in role should be used.
Provisioning Capabilities: The Azure Cosmos DB Operator role provides permissions to manage and provision Azure Cosmos accounts, databases, and containers (such as keyspaces and tables for the Apache Cassandra API).
Key Restriction: Unlike the DocumentDB Account Contributor role, it explicitly cannot access or read the account keys or connection strings. This satisfies the security requirement that the Microsoft Entra ID group must not have access to the keys required to read/write the underlying data.
Reference:
https://medium.com/azure-terraformer/terraforming-cosmos-db-access-control-arm-role-definitions-and-their-not-so-evil-twin-5de03cd92965
NEW QUESTION # 79
Your organization requires that all prompts and completions sent to Azure OpenAI be retained for zero data logging beyond what ' s required for abuse monitoring, per contractual requirements.
What should you do?
Answer: A
Explanation:
The applicable Azure OpenAI control is Modified Abuse Monitoring . Microsoft documents that customers processing highly sensitive or confidential information can apply to modify the normal abuse-monitoring process when they cannot permit Microsoft to store or conduct human review of prompts and completions.
Approval is subject to Microsoft ' s Limited Access eligibility requirements and must be requested through the designated Microsoft process.
For approved configurations, the abuse-monitoring treatment of prompts and completions is modified so that normal human review does not occur. Microsoft guidance on zero-data-retention scenarios specifically directs eligible customers to request Modified Abuse Monitoring rather than attempting to achieve the requirement by disabling unrelated telemetry services.
Disabling Azure Monitor does not change Azure OpenAI ' s service-side abuse-monitoring policy; it only affects customer-configured operational telemetry. Changing the model version likewise has no direct effect on retention requirements. Storing application data in Cosmos DB controls the application ' s own persistence layer and does not govern Azure OpenAI service processing.
Therefore, among the available choices, A is the required action. More precisely, the relevant request is Modified Abuse Monitoring ; modified content filtering/Guardrails is a separate control unless the organization also requires changes to safety filtering.
Study Guide references: Azure OpenAI # Data privacy and security; Abuse monitoring; Modified Abuse Monitoring; Limited Access requirements.
NEW QUESTION # 80
You are designing an Azure Database for PostgreSQL table for semantic search. Queries frequently filter on the created_at column.
The schema must support vector similarity search and reliable date filtering.
You need to ensure that the table meets the requirements.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,B
NEW QUESTION # 81
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
Hotspot Question
You need to configure the database resources for the Azure Database for PostgreSQL instance.
How should you complete the configuration to meet the business and technical requirements? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Box 1: Increase compute vCores
Technical requirements, Performance: Semantic search latency must remain under 200 milliseconds at peak load.
To reduce semantic search latency under 200 milliseconds at peak load, the best action is to Increase compute vCores.
Vector similarity search and semantic retrieval are highly CPU-intensive operations. The math behind vector distance calculations (such as Cosine similarity, Dot Product, or Euclidean distance) relies heavily on mathematical operations executed per query. When a system experiences peak load, compute vCores easily become the primary bottleneck. Adding more vCores directly increases parallel processing capacity, dramatically shortening the execution time of similarity calculations and keeping retrieval latency within the required 200 ms SLA.
Box 2: Increase memory allocation
The best action is to increase memory allocation.
High-dimensional vector indexes (such as HNSW or IVFFlat managed by the pgvector extension) are highly resource-intensive and rely heavily on RAM. To maintain fast vector similarity searches and avoid high-latency disk operations, the entire vector index must fit into memory (RAM residency). Scaling up the database instance's memory directly expands the PostgreSQL shared buffers and cache, ensuring the high-dimensional index remains resident in RAM for rapid semantic retrieval.
Box 3: Enable storage autoscale
Enable storage autoscale is the best action to support the continuous ingestion of transaction- based embeddings.
Continuous Ingestion Demands Dynamic Space: Continuous transaction processing causes vector databases (such as Azure Database for PostgreSQL with pgvector or Azure SQL Database) to expand constantly over time.
Preventing Ingestion Failures: If storage reaches capacity limits, the database switches into a read-only state. This immediately fails and halts all incoming real-time embedding write operations. Enabling storage autoscale allows the environment to dynamically provision storage on the fly without downtime.
Reference:
https://dl.acm.org/doi/10.1145/3695053.3731013
https://learn.microsoft.com/en-us/training/paths/develop-ai-solutions-azure-database-postgresql/
https://learn.microsoft.com/en-us/azure/architecture/guide/technology-choices/vector-search
NEW QUESTION # 82
......
As the most important element that almost all the candidates will take into consider, the pass rate of our AI-200 exam questions is high as 98% to 100%, which is unique in the market and no one has made it. And also the exam passing guarantee that makes our AI-200 Study Guide superior in the market. As the best seller, our AI-200 learning braindumps are very popular among the candidates. Many of the loyal customers are introduced by their friends or classmates.
AI-200 Study Materials Review: https://www.pdftorrent.com/AI-200-exam-prep-dumps.html
BONUS!!! Download part of PDFTorrent AI-200 dumps for free: https://drive.google.com/open?id=1nHL9S__p4Q2xPKa-otfjIZkmZ-1Hdz8I