If you fail in the exam with our AI-500 quiz prep we will refund you in full at one time immediately. If only you provide the proof which include the exam proof and the scanning copy or the screenshot of the failure marks we will refund you immediately. If any problems or doubts about our AI-500 exam torrent exist, please contact our customer service personnel online or contact us by mails and we will reply you and solve your doubts immediately. Before you buy our product, you can download and try out it freely so you can have a good understanding of our AI-500 Quiz prep. Please feel safe to purchase our AI-500 exam torrent any time as you like. We provide the best service to the client and hope the client can be satisfied.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Develop multi-agent solutions in Azure | 30–35% | - Manage state and memory
|
| Topic 2: Architect multi-agent solutions | 15–20% | - Design workflow and tool integration
|
| Topic 3: Evaluate, optimize, and monitor multi-agent solutions | 20–25% | - Assess performance and reliability
|
| Topic 4: Secure, govern, and deploy multi-agent solutions | 20–25% | - Apply security and compliance
|
>> AI-500 Valid Exam Voucher <<
How to pass the AI-500 exam and gain a certificate successfully is of great importance to people who participate in the exam. Here our company can be your learning partner and try our best to help you to get success in the AI-500 exam. Why should you choose our company with AI-500 Preparation braindumps? We have the leading brand in this carrer and successfully help tens of thousands of our customers pass therir AI-500 exam and get admired certification.
NEW QUESTION # 55
You have a multi-agent Retrieval-Augmented Generation (RAG) solution that uses a Foundry IQ knowledge base. The solution includes a support agent and a policy agent.
You have an evaluation dataset that contains the following for each user query
* The expected source IDs
* Retrieved chunks in rank order
* The final agent response
You discover that an embedding model change and a custom analyzer change cause the failed traces shown in the following table.
You need to isolate the failing parts of the RAG pipeline.
Which evaluator should you use for each agent? To answer, drag the appropriate evaluators to the correct agents. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Support agent: Document Retrieval; Policy agent: Document Retrieval.
Both failures are retrieval failures and should therefore be diagnosed with the Document Retrieval evaluator.
The dataset includes expected source IDs and ranked retrieved chunks, which provides the retrieval ground truth required by that evaluator. For the support agent, the expected source appears too low in the ranking after unrelated chunks. For the policy agent, the required exception-table source is missing entirely.
Groundedness would evaluate whether the final response is supported by the context it actually received; it could therefore pass even when the retrieval stage failed to fetch a required source. Microsoft Foundry ' s Document Retrieval evaluator compares retrieved documents against labeled ground truth and reports ranking
/search metrics such as NDCG and Fidelity. The corrected answer is Document Retrieval for both agents. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators
NEW QUESTION # 56
You have a Microsoft Foundry multi-agent solution that includes a planning agent and an execution agent You are designing a fixed order process where executions can run for several hours and can be interrupted by worker restarts.
You need to implement orchestration for the process. The solution must meet the following requirements
* Pause at predefined points.
* Resume from the last saved state after an interruption.
Which mechanisms should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Process structure: A workflow with agent executors; Pause mechanism: A human-in-the-loop (HITL) gate; Interruption recovery: Checkpoints.
The process has a fixed execution order and can run for several hours, so an explicit workflow with agent executors is preferable to free-form agent delegation. The requirement to pause at predefined points is a human-in-the-loop requirement: the workflow must be able to suspend and emit a request for approval or operator input. The requirement to resume after worker restarts is addressed by checkpoints. Microsoft Agent Framework checkpoints persist workflow progress, executor state, pending messages, shared state, and outstanding requests so execution can be restored from the last saved point. A retry policy alone re-executes operations but does not reconstruct the complete workflow state after a process interruption. The three selected mechanisms therefore cover structure, controlled pause, and durable recovery as separate but complementary workflow concerns. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Microsoft Agent Framework - Checkpoints and Human-in-the-loop
NEW QUESTION # 57
You have a Microsoft Foundry ticket-triage solution that uses connected agents. Each subagent prompt includes instructions for allowed tools and a JSON handoff.
You need to add automated prompt evaluations. The solution must identify changes that cause the subagents to do the following:
* Skip mandated evidence gathering.
* Return payloads that downstream agents cannot process.
* Handle work outside their assigned responsibilities.
How should you configure the evaluation suite? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.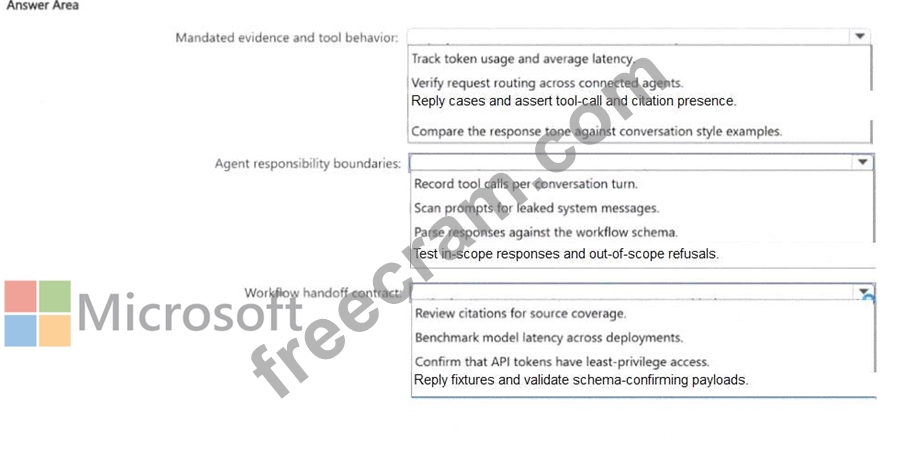
Answer:
Explanation:
Explanation:
Mandated evidence/tool behavior: Replay cases and assert tool-call and citation presence; Agent responsibility boundaries: Test in-scope responses and out-of-scope refusals; Workflow handoff contract: Replay fixtures and validate schema-conforming payloads.
The three regressions target different interfaces and should be evaluated with tests that directly observe those interfaces. Required evidence gathering is a process behavior, so replayed cases should assert that mandated tool calls and citations occur. Responsibility boundaries are best tested with both positive and negative prompts: in-scope cases must be handled, while out-of-scope work should be refused or redirected. The JSON handoff is an interface contract, so replay fixtures should be validated against the expected schema to catch missing fields, renamed properties, and type changes before downstream agents fail. Microsoft Foundry ' s agent evaluators and evaluation datasets support process-level tool checks, task-adherence checks, and structured regression testing. The supplied mappings therefore correctly align each evaluation technique with the failure it is intended to detect. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - built-in evaluators and evaluation datasets
NEW QUESTION # 58
You have a Microsoft Foundry helpdesk triage agent. Employees sign in to the agent by using Microsoft Entra. The agent can invoke the following tools:
* A ticket search tool that enforces the existing per employee authorization model
* A knowledge article tool that writes to a separate production article repository You need to recommend an identity-based access configuration for the following execution contexts:
* Ensure that interactive ticket searches enforce per employee authorization.
* Constrain approved article updates to the production article repository The solution must meet the following requirements:
* Prevent the use of embedded secrets.
* Follow the principle of least privilege
Which access configurations should you recommend? To answer, drag the appropriate configurations to the correct execution contexts. Each configuration may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Interactive ticket lookup: Delegated permissions from the signed-in employee; Approved article updates: A managed identity scoped to write production article records.
Ticket search must preserve the existing per-employee authorization model, so the downstream operation should execute in the signed-in employee ' s delegated identity context. That allows the ticket service to enforce the same user-level permissions it already uses. The knowledge-article update is an application- controlled write to one production repository, so a managed workload identity with only the required write permission is the least-privilege choice. Microsoft identity guidance distinguishes delegated/on-behalf-of access for user-context operations from managed or agent identities for service-to-service work. Both approaches also eliminate embedded secrets when configured with Microsoft Entra authentication. A broad Contributor assignment or shared API key would unnecessarily expand the blast radius and weaken audit attribution. Therefore the mixed model in the answer is intentional: delegated permissions for per-user reads, and a narrowly scoped managed identity for controlled production writes. From a security and governance perspective, the control should be enforced at the narrowest platform boundary that can deterministically block or constrain the action. Relying only on prompt text is weaker because the model can still be induced to behave unexpectedly.
Official Microsoft reference: Microsoft Foundry agent identity
NEW QUESTION # 59
You have a multitenant platform that uses Microsoft Foundry agents. The agents use conversation-based history for active turns, and the platform runs on multiple stateless container instances. Each tenant has a different transcript retention period, and users expect preferences from previous conversations to influence future sessions.
You need to persist cross-session memory after a service conversation is deleted The solution must meet the following requirements:
* Apply tenant-specific retention to transcript exports.
* Keep the compute tier stateless during scale-out.
* Minimize operational complexity
What should you include in the solution? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Extracted memory facts: Azure Cosmos DB; Cache: Azure Managed Redis with tenant-prefixed keys; Transcript exports: A shared blob container with lifecycle management policies.
The design separates durable memory, distributed cache, and retained transcripts. Azure Cosmos DB is appropriate for durable extracted facts that must survive deletion of a service conversation and remain available across stateless compute instances. Azure Managed Redis provides a shared low-latency cache; tenant-prefixed keys are a standard multitenant pattern that avoids local-process affinity. Transcript exports belong in Blob Storage, where lifecycle management rules can enforce retention and can be filtered by prefixes or tags so different tenant retention policies can coexist in one managed storage design. This combination keeps the compute tier stateless while avoiding unnecessary per-tenant infrastructure. The important security requirement is that every persistence layer also enforce tenant authorization, not just naming conventions. Within the options provided, the stated combination minimizes operational complexity while meeting cross-session persistence and retention needs. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Azure Architecture Center - multitenant data and cache patterns
NEW QUESTION # 60
......
In today's technological world, more and more students are taking the Microsoft AI-500 exam online. While this can be a convenient way to take a AI-500 exam dumps, it can also be stressful. Luckily, FreeCram's best Microsoft AI-500 Exam Questions can help you prepare for your AI-500 certification exam and reduce your stress.
Braindumps AI-500 Torrent: https://www.freecram.com/Microsoft-certification/AI-500-exam-dumps.html