If you are working all the time, and you hardly find any time to prepare for the Anthropic CCAR-P exam, then Dumpleader present the smart way to Anthropic CCAR-P exam prep for the exam. You can always prepare for the CCAR-P test whenever you find free time with the help of our CCAR-P Pdf Dumps. We have curated all the CCAR-P questions and answers that you can view the exam Anthropic CCAR-P brain dumps and prepare for the CCAR-P exam. We guarantee that you will be able to pass the CCAR-P in the first attempt.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Evaluation, Testing & Optimization | 16% | - Optimize performance, prompting, and model selection - Test accuracy, reliability, latency, and cost - Implement iterative improvement pipelines - Define evaluation metrics and success criteria |
| Topic 2: Claude Models, Prompting & Context Engineering | 13% | - Mitigate prompt injection, leaks, and jailbreak risks - Select appropriate Claude models based on trade-offs - Design system prompts, templates, and guardrails - Apply context engineering and context management techniques |
| Topic 3: Solution Design & Architecture | 17% | - Translate business problems into Claude-based AI solutions - Design end-to-end architectures and feedback loops - Align solutions to business value pillars - Select architectural patterns: workflow, agentic, augmented LLM - Design multi-agent systems and orchestration strategies |
| Topic 4: Governance, Safety & Risk Management | 14% | - Manage data privacy and security compliance - Address ethical AI considerations and bias mitigation - Implement guardrails and safety controls - Ensure regulatory compliance (GDPR, HIPAA, etc.) |
| Topic 5: Stakeholder Communication & Lifecycle Management | 14% | - Document architectures and support full lifecycle phases - Communicate architectural decisions and trade-offs - Conduct structured discovery and requirement gathering - Manage stakeholder feedback and expectation alignment |
| Topic 6: Developer Productivity & Operational Enablement | 7% | - Configure Claude tools and environments for teams - Improve developer workflows with AI-assisted tooling - Support debugging, monitoring, and operational resolution |
| Topic 7: Integration | 19% | - Implement Model Context Protocol (MCP) integrations - Integrate Claude with enterprise systems, APIs, and tools - Integrate with data pipelines and RAG systems - Design authentication, authorization, and observability |
In our study, we found that many people have the strongest ability to use knowledge for a period of time at the beginning of their knowledge. As time goes on, memory fades. Our CCAR-P training materials are designed to help users consolidate what they have learned, will add to the instant of many training, the user can test their learning effect in time after finished the part of the learning content, have a special set of wrong topics in our CCAR-P Guide dump, enable users to find their weak spot of knowledge in this function, iterate through constant practice, finally reach a high success rate. As a result, our CCAR-P study questions are designed to form a complete set of the contents of practice can let users master knowledge as much as possible, although such repeated sometimes very boring, but it can achieve good effect of consolidation.
NEW QUESTION # 33
A revenue projection assistant has missed its monthly cost target by 38 percent. Profiling shows three contributors: a 6,000-token policy preamble repeated on every call (45 percent of cost), retrieval of historical sales chunks averaging 3,000 tokens per call (30 percent), and inference on a flagship-tier model (25 percent).
Stakeholders require that projection accuracy remain unchanged.
Which two optimizations should you sequence first to reduce cost without affecting accuracy? (Select two.) Each correct answer presents part of the solution.
Answer: A,C
Explanation:
The required sequence must reduce repeated computation without changing the information or model capability used to generate projections. Prompt caching the static 6,000-token policy preamble directly addresses the largest cost contributor while preserving the complete instruction set. Anthropic states that cache reads cost substantially less than uncached input tokens, making repeated, stable prompt prefixes an ideal caching target. Prompt Caching Caching frequently reused historical-sales chunks applies the same principle to the retrieval layer. When identical, version-controlled chunks are repeatedly fetched and supplied to the model, caching their retrieval or reusable representation eliminates redundant work while maintaining the same evidence available to the projection process. The cache must use appropriate invalidation or source-version keys so updated sales data cannot be replaced by stale content.
Options A and B modify the information supplied to Claude. Fewer sales chunks could remove relevant historical evidence, while truncating policy instructions could alter constraints or projection behavior. Option D introduces a model-capability change and therefore cannot guarantee unchanged accuracy without a comparative evaluation. Those interventions may be considered later, but only after representative regression testing establishes equivalence.
Study Guide references/topics: Cost profiling; prompt caching; retrieval caching; cache invalidation; accuracy- preserving optimization; model and context trade-offs.
NEW QUESTION # 34
You are selecting the documentation set that should accompany a Claude-based deployment at handoff.
Which set is most complete?
Answer: A
Explanation:
A complete handoff package must help different stakeholders understand, operate, troubleshoot, and evolve the Claude-based solution. An architecture overview explains the system's structure and responsibilities, while Architecture Decision Records document important decisions, alternatives, and trade-offs. Component- level diagrams provide implementation context without forcing maintainers to reconstruct dependencies from source code. Operational runbooks and an on-call playbook enable reliable incident detection, diagnosis, escalation, and recovery. Documenting known limitations is particularly important for Claude applications because model behavior can vary with prompts, context, input distribution, and external dependencies.
Options B, C, and D each provide only a partial or temporary understanding of the system. They would create knowledge gaps, increase operational risk, and make future maintenance dependent on individuals rather than durable organizational documentation.
NEW QUESTION # 35
You are evaluating model-selection claims used by a peer team.
For each statement, select yes if the statement is generally true. Otherwise, select no.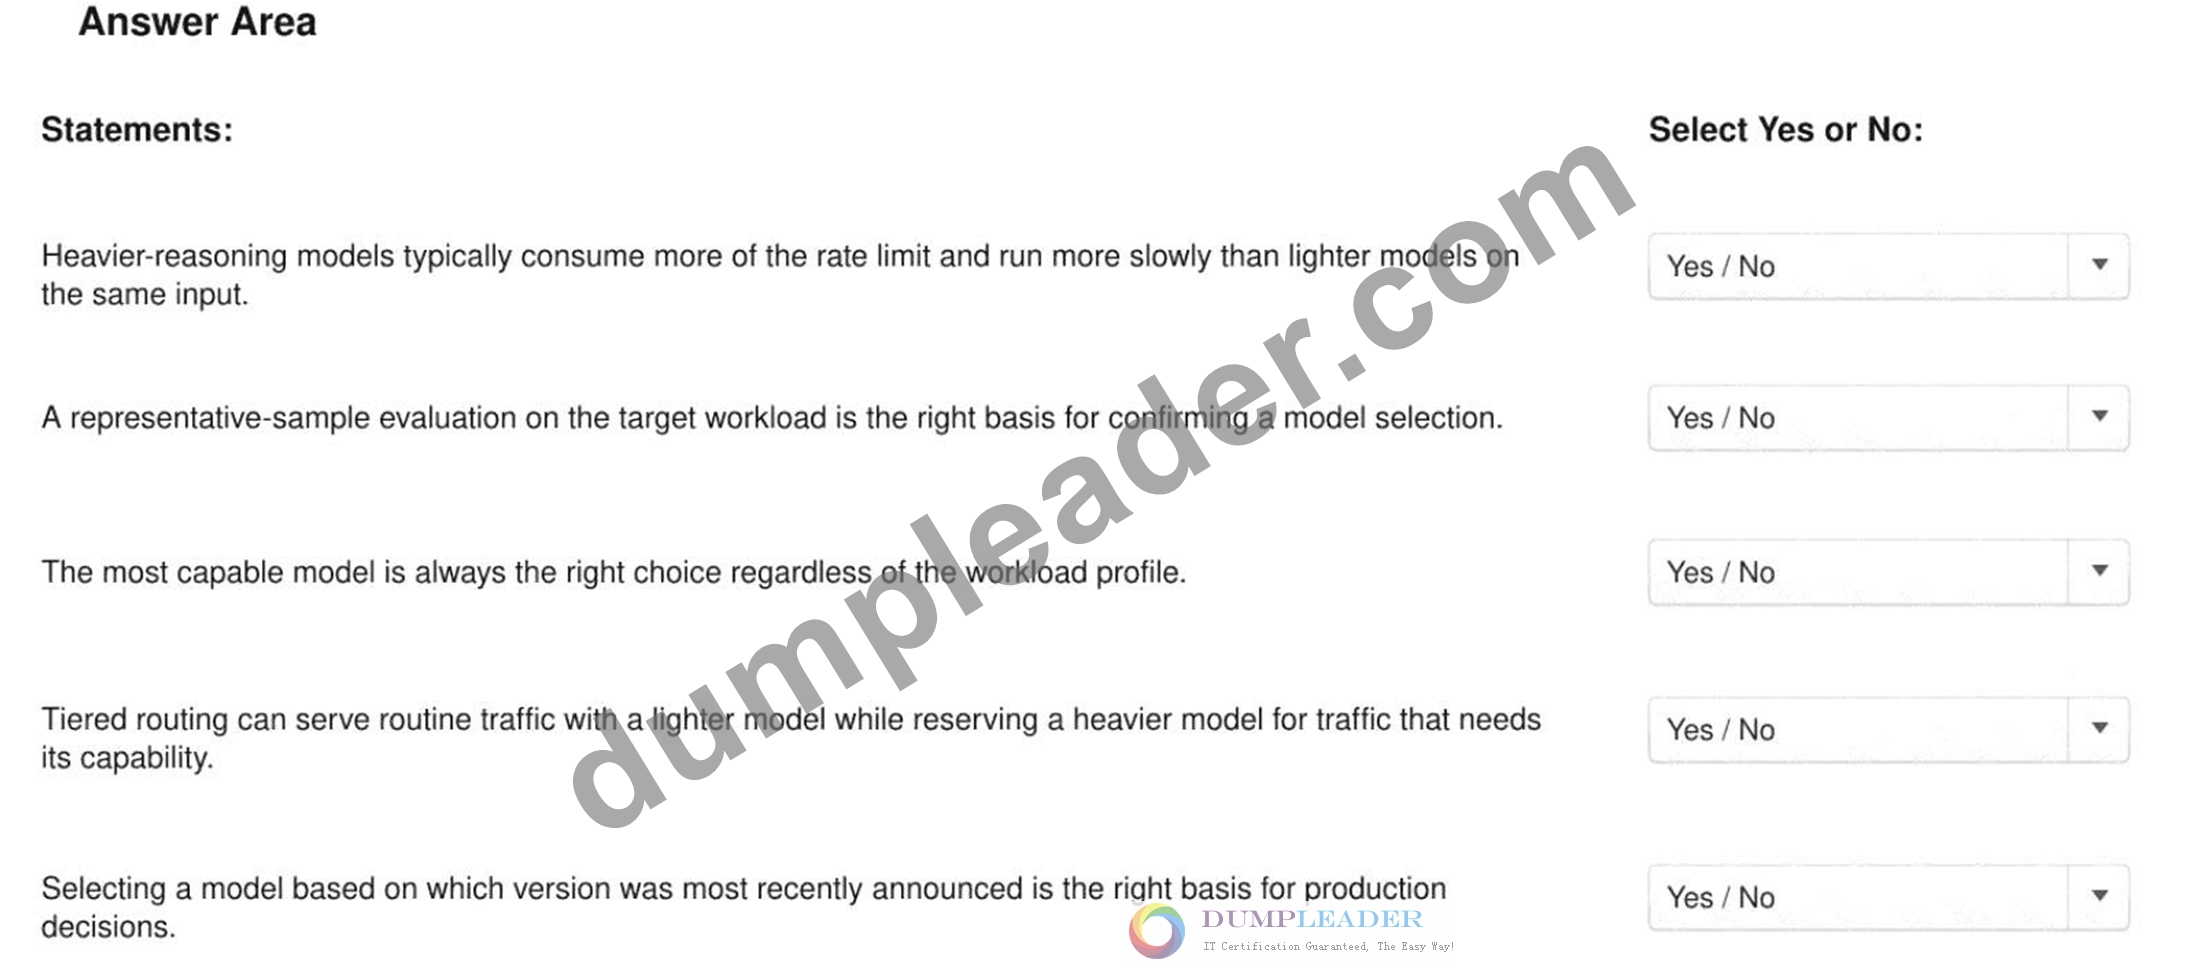
Answer:
Explanation: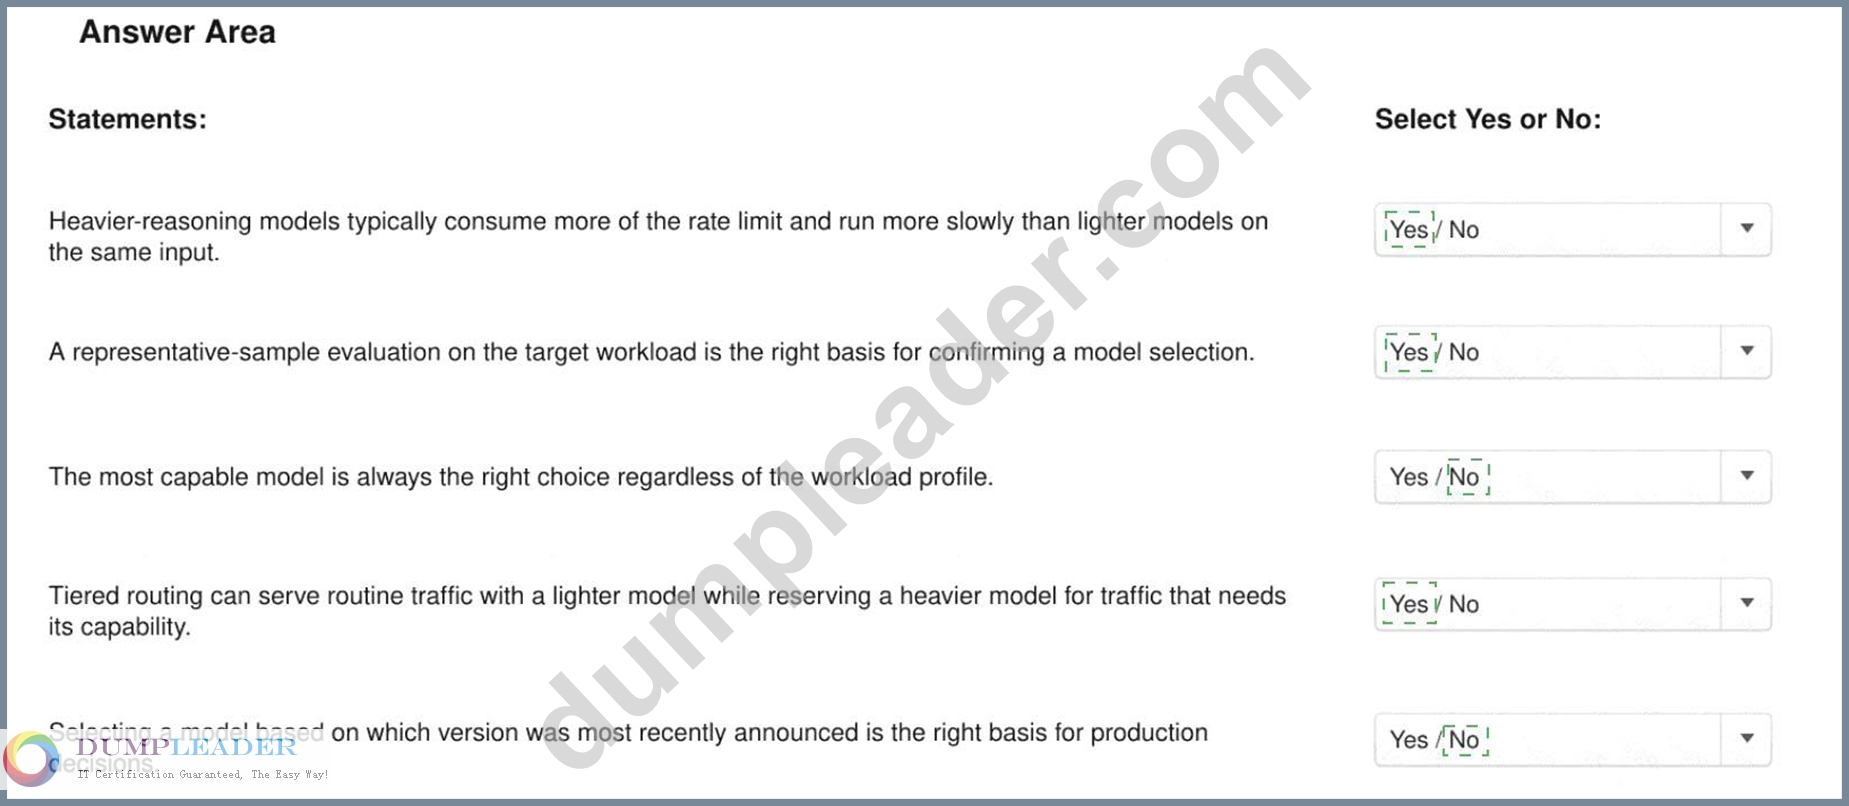
Explanation:
Yes, Yes, No, Yes, No
More capable reasoning configurations generally require greater computation, produce higher latency, and may consume larger token or rate-limit allocations than lighter alternatives. This makes the first statement generally accurate, although actual performance must be measured under the organization's specific provider and service tier.
Representative workload testing is essential because generic benchmark rankings do not establish performance on the organization's prompts, data, edge cases, tools, or required output format. Anthropic recommends benchmark tests specific to the use case, using actual prompts and data, followed by comparison of accuracy, quality, edge-case behavior, and cost. Choosing the Right Model The strongest model is not automatically the correct production choice. Model selection must balance capability, speed, cost, throughput, and operational constraints. Tiered routing implements this principle by serving predictable requests with an efficient model and escalating difficult cases to a more capable model.
Anthropic documents multi-model strategies in which lower-cost workers handle most traffic while harder decisions are escalated.
Recency is also not a valid selection criterion. A newly announced model must pass the workload's existing evaluation, security, latency, and cost gates before replacing a validated production model.
Study Guide references/topics: Model trade-offs; representative evaluations; tiered routing; escalation architectures; cost-capability optimization; model migration validation.
NEW QUESTION # 36
Engineering leadership wants to roll out Claude Skills to 280 developers across 14 teams. Skills will encode internal coding standards, code-review checklists, and incident-postmortem templates. Leadership has asked how to govern Skill authorship so that Skills remain trustworthy without bottlenecking on a single central team.
Which governance model should you recommend?
Answer: C
Explanation:
Federated authorship allows each domain team to maintain the procedural knowledge it understands while preserving organization-wide trust through a central publication gate. Team authors can update coding standards, review practices, and postmortem procedures without waiting for a single platform group to write every change. Central reviewers can validate ownership, security, tool permissions, duplication, versioning, testing evidence, and compliance before publication. Per-developer or fully decentralized publication creates inconsistent and potentially unsafe Skills. Fully centralized authorship becomes a scalability bottleneck and separates content maintenance from domain expertise. Anthropic describes Skills as packages of instructions, scripts, and resources and warns that repository Skills may grant broad tool access, making formal review essential. Claude Code Skills
NEW QUESTION # 37
You are evaluating an evaluation set used to score a Claude-based hiring-support tool. The set is drawn from one geographic region and one tenure band.
Which response is most appropriate?
Answer: B
Explanation:
The existing evaluation set does not represent the population or operating conditions the hiring-support system will encounter. Option B corrects this coverage defect by expanding geographic and tenure slices and requiring the system to be rescored before broader deployment.
Aggregate performance on one narrow group can conceal substantial differences among regions, experience levels, job families, languages, and other relevant cohorts. The expanded dataset should therefore support disaggregated metrics, not merely one combined score. It should also include representative, edge, and adversarial cases, with labels and grading procedures reviewed for consistency and potential bias.
Anthropic's evaluation guidance states that evaluations should mirror the real-world task distribution and include edge cases. Success criteria should also be relevant to the application's actual purpose and users.
Define Success Criteria and Build Evaluations
Option A replaces one unrepresentative method with another. Option C deliberately narrows coverage further.
Option D mistakes high performance on a restricted subset for evidence of generalization.
Because hiring is a consequential domain, the organization should combine representative quantitative evaluation, subgroup analysis, expert review, monitoring, access controls, transparency, and meaningful human responsibility for final decisions.
Study Guide references/topics: Dataset representativeness; evaluation slices; subgroup performance; bias detection; consequential-use governance; pre-release rescoring.
NEW QUESTION # 38
......
Dumpleader is one of the leading platforms that has been helping Claude Certified Architect - Professional Exam Questions candidates for many years. Over this long time, period the Claude Certified Architect - Professional (CCAR-P) exam dumps helped countless Anthropic CCAR-P exam questions candidates and they easily cracked their dream Claude Certified Architect - Professional (CCAR-P) certification exam. You can also trust Claude Certified Architect - Professional (CCAR-P) exam dumps and start Anthropic CCAR-P exam preparation today.
Valid CCAR-P Exam Review: https://www.dumpleader.com/CCAR-P_exam.html