Databricks-Certified-Data-Engineer-Professional Online Training Materials, Databricks-Certified-Data-Engineer-Professional Certification Torrent

The pass rate of Databricks-Certified-Data-Engineer-Professional study materials are 98.95%, if you buy Databricks-Certified-Data-Engineer-Professional study material from us, we can ensure you pass the exam successfully. Besides you can get Databricks-Certified-Data-Engineer-Professional exam dumps in ten minutes after your payment. You can use the Databricks-Certified-Data-Engineer-Professional exam dumps freely, if you have any questions in the process of your learning, you can consult the service stuff, and they have the professional knowledge about Databricks-Certified-Data-Engineer-Professional Learning Materials, so don’t hesitate to ask for help from them.
| Section | Objectives |
|---|
| Topic 1: Data Ingestion and Processing | - ETL pipeline design patterns
- Structured Streaming fundamentals
- Batch and streaming ingestion with Auto Loader
|
| Topic 2: Data Modeling and Transformation | - Performance optimization techniques
- Spark SQL transformations
- Dimensional modeling concepts
|
| Topic 3: Production Pipelines and Orchestration | - Job scheduling and monitoring
- Databricks Workflows
- Error handling and recovery strategies
|
| Topic 4: Databricks Lakehouse Platform Architecture | - Data governance concepts (Unity Catalog basics)
- Medallion architecture (Bronze, Silver, Gold)
- Workspace and cluster architecture
|
| Topic 5: Delta Lake and Data Management | - Delta Lake transactions and ACID properties
- Time travel and versioning
- Schema evolution and enforcement
|
>> Databricks-Certified-Data-Engineer-Professional Online Training Materials <<
Databricks-Certified-Data-Engineer-Professional Certification Torrent - Updated Databricks-Certified-Data-Engineer-Professional CBT
If you have any questions about installing or using our Databricks-Certified-Data-Engineer-Professional real exam, our professional after-sales service staff will provide you with warm remote service. As long as it is about our Databricks-Certified-Data-Engineer-Professional learning materials, we will be able to solve. Whether you're emailing or contacting us online, we'll help you solve the problem on the Databricks-Certified-Data-Engineer-Professional study questions as quickly as possible. You don't need any worries at all.
Databricks Certified Data Engineer Professional Exam Sample Questions (Q142-Q147):
NEW QUESTION # 142
Predictive Optimization is an automated Databricks service enabled by default for Unity Catalog Managed tables. It helps maintain Delta tables by continuously optimizing them to ensure optimal performance and costs. Which two operations does Predictive Optimization run to maintain the Delta tables? (Choose two.)
- A. PARTITION BY
- B. ANALYZE
- C. OPTIMIZE
- D. COMPACT
- E. BUCKETING
Answer: B,C
Explanation:
Predictive Optimization automatically runs OPTIMIZE to compact small files and improve data layout, and ANALYZE to collect and refresh table statistics. Together, these operations ensure efficient query planning, better data skipping, and optimized performance and cost for Unity Catalog managed Delta tables.
NEW QUESTION # 143
A data engineering team is collaborating on a Databricks project where each team member needs to develop and test code independently before merging changes into the main branch.
They want to avoid accidental overwrites or branch switching issues while ensuring that all work is version- controlled and can be integrated into their CI/CD pipeline.
How should the data engineer achieve collaboration?
- A. Team members edit notebooks directly in the workspace's shared folder and periodically copy changes into a Git folder for version control.
- B. Each team member creates their own Databricks Git folder, mapped to the same remote Git repository, and works in their own development branch within their personal folder.
- C. Team members use the Databricks CLI to clone the Git repository and perform Git operations from a cluster's web terminal.
- D. All team members work in the same Databricks Git folder and perform Git operations (pull, push, commit, branch switching) directly in that shared folder.
Answer: B
Explanation:
Using separate Databricks Git folders per user mapped to the same remote repository allows each team member to work independently on their own branch without interfering with others.
This prevents accidental overwrites or branch conflicts while ensuring all changes are version- controlled and easily integrated into CI/CD workflows.
NEW QUESTION # 144
Which of the following technologies can be used to identify key areas of text when parsing Spark Driver log4j output?
- A. C++
- B. Julia
- C. Scala Datasets
- D. pyspsark.ml.feature
- E. Regex
Answer: E
Explanation:
Regex, or regular expressions, are a powerful way of matching patterns in text. They can be used Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from to identify key areas of text when parsing Spark Driver log4j output, such as the log level, the timestamp, the thread name, the class name, the method name, and the message. Regex can be applied in various languages and frameworks, such as Scala, Python, Java, Spark SQL, and Databricks notebooks.
NEW QUESTION # 145
A data architect has designed a system in which two Structured Streaming jobs will concurrently write to a single bronze Delta table. Each job is subscribing to a different topic from an Apache Kafka source, but they will write data with the same schema. To keep the directory structure simple, a data engineer has decided to nest a checkpoint directory to be shared by both streams.
The proposed directory structure is displayed below:
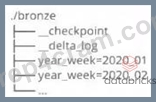
Which statement describes whether this checkpoint directory structure is valid for the given scenario and why?
- A. Yes; Delta Lake supports infinite concurrent writers.
- B. No; only one stream can write to a Delta Lake table.
- C. No; Delta Lake manages streaming checkpoints in the transaction log.
- D. No; each of the streams needs to have its own checkpoint directory.
- E. Yes; both of the streams can share a single checkpoint directory.
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
Answer: D
Explanation:
This is the correct answer because checkpointing is a critical feature of Structured Streaming that provides fault tolerance and recovery in case of failures. Checkpointing stores the current state and progress of a streaming query in a reliable storage system, such as DBFS or S3. Each streaming query must have its own checkpoint directory that is unique and exclusive to that query. If two streaming queries share the same checkpoint directory, they will interfere with each other and cause unexpected errors or data loss.
NEW QUESTION # 146
To identify the top users consuming compute resources, a data engineering team needs to monitor usage within their Databricks workspace for better resource utilization and cost control.
The team decided to use Databricks system tables, available under the System catalog in Unity Catalog, to gain detailed visibility into workspace activity. Which SQL query should the team run from the System catalog to achieve this?
- A. SELECT identity_metadata.run_as AS user_email,
SUM(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email
ORDER BY total_dbus DESC
LIMIT 10 - B. SELECT sku_name,
identity_metadata.created_by AS user_email,
SUM(usage_quantity * usage_unit) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10 - C. SELECT sku_name,
usage_metadata.run_name AS user_email,
SUM(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10 - D. SELECT sku_name,
identity_metadata.created_by AS user_email,
COUNT(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10
Answer: A
Explanation:
The system.billing.usage table in the Unity Catalog System schema provides detailed usage metrics for each workload in the workspace. The field identity_metadata.run_as identifies the user or service principal under which the job or query executed. Summing usage_quantity provides total DBU (Databricks Unit) consumption per user. According to Databricks documentation, this table is the authoritative source for monitoring workspace cost drivers, showing compute SKU, user, and DBU consumption over time. Grouping by identity_metadata.run_as and summing usage_quantity produces the correct aggregation to determine top users. Other queries use non- existent or incorrect fields (created_by, run_name, or multiplied usage quantities), which do not reflect actual billing metrics.
NEW QUESTION # 147
......
Prep4cram is a leading platform in this area by offering the most accurate Databricks-Certified-Data-Engineer-Professional exam questions to help our customers to pass the exam. And we are grimly determined and confident in helping you. With professional experts and brilliant teamwork, our Databricks-Certified-Data-Engineer-Professional practice materials have helped exam candidates succeed since the beginning. To make our Databricks-Certified-Data-Engineer-Professional simulating exam more precise, we do not mind splurge heavy money and effort to invite the most professional teams into our group.
Databricks-Certified-Data-Engineer-Professional Certification Torrent: https://www.prep4cram.com/Databricks-Certified-Data-Engineer-Professional_exam-questions.html
- Valid Databricks-Certified-Data-Engineer-Professional Exam Questions That Have Been Tried and True 🌠 Download ( Databricks-Certified-Data-Engineer-Professional ) for free by simply searching on ➥ www.exam4labs.com 🡄 💲Latest Databricks-Certified-Data-Engineer-Professional Exam Tips
- Databricks-Certified-Data-Engineer-Professional Valid Cram Materials 🌶 PDF Databricks-Certified-Data-Engineer-Professional VCE 🦢 Reliable Databricks-Certified-Data-Engineer-Professional Test Materials 🍜 Simply search for ▶ Databricks-Certified-Data-Engineer-Professional ◀ for free download on [ www.pdfvce.com ] 🎢Vce Databricks-Certified-Data-Engineer-Professional Download
- Databricks-Certified-Data-Engineer-Professional Valid Cram Materials 🕌 Databricks-Certified-Data-Engineer-Professional Exam Fee 🍯 Learning Databricks-Certified-Data-Engineer-Professional Mode 🔌 Easily obtain ▛ Databricks-Certified-Data-Engineer-Professional ▟ for free download through ⇛ www.testkingpass.com ⇚ 🤿Databricks-Certified-Data-Engineer-Professional Accurate Prep Material
- New Databricks-Certified-Data-Engineer-Professional Exam Name 🐳 Databricks-Certified-Data-Engineer-Professional Accurate Prep Material 🎺 New Databricks-Certified-Data-Engineer-Professional Exam Name 🗜 Search for ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ and download it for free immediately on ⏩ www.pdfvce.com ⏪ 🧒Databricks-Certified-Data-Engineer-Professional Valid Cram Materials
- Databricks-Certified-Data-Engineer-Professional Valid Test Topics 🐨 Study Materials Databricks-Certified-Data-Engineer-Professional Review 🦒 Databricks-Certified-Data-Engineer-Professional Valid Cram Materials 🦍 Easily obtain free download of ⮆ Databricks-Certified-Data-Engineer-Professional ⮄ by searching on ➡ www.vce4dumps.com ️⬅️ 👪Free Databricks-Certified-Data-Engineer-Professional Study Material
- Test Databricks-Certified-Data-Engineer-Professional Practice 🐐 Mock Databricks-Certified-Data-Engineer-Professional Exam 🐋 Databricks-Certified-Data-Engineer-Professional Exam Fee 💞 Easily obtain free download of ▛ Databricks-Certified-Data-Engineer-Professional ▟ by searching on ➤ www.pdfvce.com ⮘ ✏Databricks-Certified-Data-Engineer-Professional Valid Test Topics
- Learning Databricks-Certified-Data-Engineer-Professional Mode 🍧 Mock Databricks-Certified-Data-Engineer-Professional Exam 🛳 New Databricks-Certified-Data-Engineer-Professional Exam Name 🚜 Go to website ➥ www.prepawaypdf.com 🡄 open and search for ✔ Databricks-Certified-Data-Engineer-Professional ️✔️ to download for free 🍓Latest Databricks-Certified-Data-Engineer-Professional Exam Tips
- Study Materials Databricks-Certified-Data-Engineer-Professional Review 🗣 Valid Databricks-Certified-Data-Engineer-Professional Mock Exam 🏐 Updated Databricks-Certified-Data-Engineer-Professional Testkings 🐆 Easily obtain free download of ⇛ Databricks-Certified-Data-Engineer-Professional ⇚ by searching on ▶ www.pdfvce.com ◀ 🧸Learning Databricks-Certified-Data-Engineer-Professional Mode
- Pass Guaranteed Quiz 2026 Databricks Databricks-Certified-Data-Engineer-Professional Accurate Online Training Materials 💄 Copy URL 「 www.prepawaypdf.com 」 open and search for ➽ Databricks-Certified-Data-Engineer-Professional 🢪 to download for free ♿Databricks-Certified-Data-Engineer-Professional Accurate Prep Material
- New Databricks-Certified-Data-Engineer-Professional Exam Name 🦞 Reliable Databricks-Certified-Data-Engineer-Professional Test Materials 🦥 New Databricks-Certified-Data-Engineer-Professional Test Labs 😫 ⮆ www.pdfvce.com ⮄ is best website to obtain ( Databricks-Certified-Data-Engineer-Professional ) for free download 🥑Reliable Databricks-Certified-Data-Engineer-Professional Test Materials
- Advantages Of Databricks Databricks-Certified-Data-Engineer-Professional Practice Test Software 🎼 Search for 《 Databricks-Certified-Data-Engineer-Professional 》 and download it for free on ☀ www.pass4test.com ️☀️ website 🍱New Databricks-Certified-Data-Engineer-Professional Exam Name
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.chordie.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes