Dumps DY0-001 Cost | DY0-001 Exam Answers

DOWNLOAD the newest FreePdfDump DY0-001 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1Xuj_p1gtTxbVm0J-MFUDTCe3Er5QIlmx
At any point in the process of buying our DY0-001 exam braindumps, the customer does not need to check the status of the purchase order, because as long as you have paid for it, then you can get it in a second. With all those efficiency, our DY0-001 study engine is suitable in this high-speed society. With strong strength in this career, we can claim that you can only study our DY0-001 learning guide for 20 to 30 hours, you can pass your DY0-001 exam with 100% guarantee.
| Topic | Details |
|---|
| Topic 1 | - Machine Learning: This section of the exam measures skills of a Machine Learning Engineer and covers foundational ML concepts such as overfitting, feature selection, and ensemble models. It includes supervised learning algorithms, tree-based methods, and regression techniques. The domain introduces deep learning frameworks and architectures like CNNs, RNNs, and transformers, along with optimization methods. It also addresses unsupervised learning, dimensionality reduction, and clustering models, helping candidates understand the wide range of ML applications and techniques used in modern analytics.
|
| Topic 2 | - Specialized Applications of Data Science: This section of the exam measures skills of a Senior Data Analyst and introduces advanced topics like constrained optimization, reinforcement learning, and edge computing. It covers natural language processing fundamentals such as text tokenization, embeddings, sentiment analysis, and LLMs. Candidates also explore computer vision tasks like object detection and segmentation, and are assessed on their understanding of graph theory, anomaly detection, heuristics, and multimodal machine learning, showing how data science extends across multiple domains and applications.
|
| Topic 3 | - Mathematics and Statistics: This section of the exam measures skills of a Data Scientist and covers the application of various statistical techniques used in data science, such as hypothesis testing, regression metrics, and probability functions. It also evaluates understanding of statistical distributions, types of data missingness, and probability models. Candidates are expected to understand essential linear algebra and calculus concepts relevant to data manipulation and analysis, as well as compare time-based models like ARIMA and longitudinal studies used for forecasting and causal inference.
|
| Topic 4 | - Modeling, Analysis, and Outcomes: This section of the exam measures skills of a Data Science Consultant and focuses on exploratory data analysis, feature identification, and visualization techniques to interpret object behavior and relationships. It explores data quality issues, data enrichment practices like feature engineering and transformation, and model design processes including iterations and performance assessments. Candidates are also evaluated on their ability to justify model selections through experiment outcomes and communicate insights effectively to diverse business audiences using appropriate visualization tools.
|
| Topic 5 | - Operations and Processes: This section of the exam measures skills of an AI
- ML Operations Specialist and evaluates understanding of data ingestion methods, pipeline orchestration, data cleaning, and version control in the data science workflow. Candidates are expected to understand infrastructure needs for various data types and formats, manage clean code practices, and follow documentation standards. The section also explores DevOps and MLOps concepts, including continuous deployment, model performance monitoring, and deployment across environments like cloud, containers, and edge systems.
|
>> Dumps DY0-001 Cost <<
DY0-001 Exam Answers & Practice DY0-001 Engine
In FreePdfDump's website you can free download study guide, some exercises and answers about CompTIA Certification DY0-001 Exam as an attempt.
CompTIA DataAI Certification Exam Sample Questions (Q51-Q56):
NEW QUESTION # 51
A data scientist needs to analyze a company's chemical businesses and is using the master database of the conglomerate company. Nothing in the data differentiates the data observations for the different businesses. Which of the following is the most efficient way to identify the chemical businesses' observations?
- A. Perform analysis on all of the data and create a summary report on the results relevant to chemical operations.
- B. Ingest the data from all of the hard drives and perform exploratory data analysis to identify which business is responsible for chemical operations.
- C. Consult with the business team to identify which sites are responsible for chemical operations and ingest only the relevant data for analysis.
- D. Ingest data from the hard drive containing the most data and present sample results on the chemical operations.
Answer: C
Explanation:
Engaging the business team leverages domain expertise to pinpoint which records pertain to chemical operations, allowing you to extract and analyze just the relevant subset. This avoids the time and resource waste of ingesting and sifting through unrelated data.
NEW QUESTION # 52
A data scientist is building an inferential model with a single predictor variable. A scatter plot of the independent variable against the real-number dependent variable shows a strong relationship between them.
The predictor variable is normally distributed with very few outliers. Which of the following algorithms is the best fit for this model, given the data scientist wants the model to be easily interpreted?
- A. A linear regression
- B. An exponential regression
- C. A probit regression
- D. A logistic regression
Answer: A
Explanation:
The scenario provided describes a modeling problem with the following characteristics:
* A single continuous predictor variable (independent variable).
* A continuous real-number dependent variable.
* The relationship between the variables appears strong and linear, as observed from the scatter plot.
* The predictor variable is normally distributed with minimal outliers.
* The goal is to maintain interpretability in the model.
Based on the above, the most appropriate modeling technique is:
Linear Regression: This is a statistical method used to model the linear relationship between a continuous dependent variable and one or more independent variables. In simple linear regression, a straight line (y = mx
+ b) represents the relationship, where the slope and intercept can be easily interpreted. This method is preferred when the relationship is linear, the assumptions of normality and homoscedasticity are satisfied, and interpretability is required.
Why the other options are incorrect:
* A. Logistic Regression: This is used when the dependent variable is categorical (e.g., binary classification), not continuous. Therefore, not suitable for this case.
* B. Exponential Regression: Applied when the data shows an exponential growth or decay pattern, which is not implied here.
* D. Probit Regression: Similar to logistic regression but based on a normal cumulative distribution.
Used for categorical outcomes, not continuous variables.
Exact Extract and Official References:
* CompTIA DataX (DY0-001) Official Study Guide, Domain: Modeling, Analysis, and Outcomes:
"Linear regression is the most interpretable form of regression modeling. It assumes a linear relationship between independent and dependent variables and is ideal for inferential modeling when interpretability is important." (Section 3.1, Model Selection Criteria)
* Data Science Fundamentals, by CompTIA and DS Institute:
"Linear regression is a robust and interpretable statistical method used for modeling continuous outcomes. It provides coefficients which help in understanding the strength and direction of the relationship." (Chapter 4, Regression Techniques)
NEW QUESTION # 53
A data scientist is developing a model to predict the outcome of a vote for a national mascot. The choice is between tigers and lions. The full data set represents feedback from individuals representing 17 professions and 12 different locations. The following rank aggregation represents 80% of the data set:
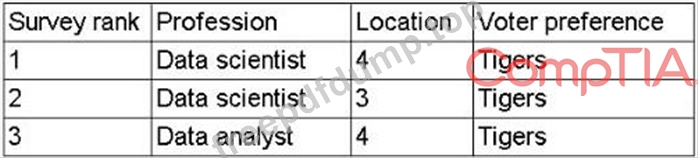
(Screenshot shows survey rankings for just two professions and a few locations, all voting for "Tigers") Which of the following is the most likely concern about the model's ability to predict the outcome of the vote?
- A. In-sample data
- B. Extrapolated data
- C. Out-of-sample data
- D. Interpolated data
Answer: B
Explanation:
# Extrapolated data refers to making predictions about data points that fall outside the observed range or distribution. Since the sample data (80%) is heavily skewed toward a small subset of professions and locations, predicting results for the remaining, unrepresented professions and regions involves extrapolation.
Why the other options are incorrect:
* A: Interpolation occurs within the bounds of observed data - not the issue here.
* C: In-sample data refers to training data, which is overrepresented in this case.
* D: Out-of-sample data is a concern in generalization but extrapolation is more specific here.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.2:"Extrapolation introduces risk when models are used outside the range of data they were trained on, especially if certain subgroups are underrepresented."
-
NEW QUESTION # 54
A data scientist is creating a responsive model that will update a product's daily pricing based on the previous day's sales volume. Which of the following resource constraints is the data scientist's greatest concern?
- A. Training time
- B. Deployment time
- C. Data collection time
- D. Development time
Answer: A
Explanation:
# Since the model must update daily based on new data, retraining must be fast enough to meet daily deadlines. Therefore, training time is the critical constraint - it determines whether pricing updates can be executed promptly.
Why the other options are incorrect:
* A: Deployment time is a one-time or infrequent process.
* C: Development time is less critical once the model is built.
* D: Data is already collected daily - assumed to be available.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 5.4:"Time-sensitive applications such as daily pricing require fast model retraining, making training time a critical factor."
* Real-Time ML Deployment Handbook, Chapter 6:"Retraining time is the bottleneck in time- constrained systems that adapt to fresh inputs regularly."
-
NEW QUESTION # 55
Which of the following techniques enables automation and iteration of code releases?
- A. Code isolation
- B. Markdown
- C. CI/CD
- D. Virtualization
Answer: C
Explanation:
# CI/CD (Continuous Integration / Continuous Deployment) is a DevOps methodology that automates the building, testing, and deployment of code. It allows teams to iteratively release updates and improvements in a reliable and scalable manner.
Why the other options are incorrect:
* A: Virtualization provides environment emulation but doesn't manage code releases.
* B: Markdown is a documentation tool - unrelated to deployment automation.
* C: Code isolation refers to modular programming, not automation pipelines.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 5.3:"CI/CD pipelines streamline model deployment through automation, allowing continuous integration and delivery of updates."
* DevOps for Data Science, Chapter 4:"CI/CD supports fast and reliable code iterations by automatically testing and deploying to production environments."
-
NEW QUESTION # 56
......
It takes a lot of effort and hard work to get the results. The first step is to download real CompTIA DataAI Certification Exam (DY0-001) Exam Questions of FreePdfDump. These CompTIA DataAI Certification Exam (DY0-001) exam questions are available in PDF, desktop practice test software, and web-based practice exam. If you are already an employee or busy in your routine, you can prepare DY0-001 Exam quickly with FreePdfDump pdf questions. DY0-001 pdf exam questions help applicants study for the CompTIA DataAI Certification Exam (DY0-001) exam at any time from any location. With the pdf questions, it will be easy for you to complete the CompTIA DataAI Certification Exam (DY0-001) exam preparation in a short time.
DY0-001 Exam Answers: https://www.freepdfdump.top/DY0-001-valid-torrent.html
- DY0-001 Learning Materials: CompTIA DataAI Certification Exam - DY0-001 Actual Lab Questions 🦘 Search for ➠ DY0-001 🠰 and download exam materials for free through ⇛ www.vceengine.com ⇚ 🏵Valid Dumps DY0-001 Sheet
- DY0-001 Quiz Braindumps - DY0-001 Test Guide - DY0-001 Test Bootcamp 🍉 Immediately open [ www.pdfvce.com ] and search for ➥ DY0-001 🡄 to obtain a free download 🆑Free DY0-001 Sample
- Authoritative Dumps DY0-001 Cost - Easy and Guaranteed DY0-001 Exam Success ♻ Go to website ▛ www.prepawaypdf.com ▟ open and search for ➥ DY0-001 🡄 to download for free 👯DY0-001 Exam PDF
- DY0-001 Latest Questions 🔺 DY0-001 Exam PDF 🤯 DY0-001 Exam Simulator Fee 🥿 Download { DY0-001 } for free by simply entering ▷ www.pdfvce.com ◁ website 🏖DY0-001 Valid Real Test
- DY0-001 Real Torrent 🎒 DY0-001 Exam PDF 💱 DY0-001 Valid Real Test 👻 Open ( www.pdfdumps.com ) and search for ➽ DY0-001 🢪 to download exam materials for free 🍕DY0-001 Certification Test Questions
- Ultimate DY0-001 Prep Guide - Dumps DY0-001 Cost ⏩ Enter ☀ www.pdfvce.com ️☀️ and search for ➽ DY0-001 🢪 to download for free 📢Valid Dumps DY0-001 Sheet
- Pass Guaranteed Quiz DY0-001 - CompTIA DataAI Certification Exam Marvelous Dumps Cost 🦛 { www.prep4away.com } is best website to obtain ➥ DY0-001 🡄 for free download 🏳Valid Dumps DY0-001 Sheet
- DY0-001 Learning Materials: CompTIA DataAI Certification Exam - DY0-001 Actual Lab Questions 🏄 Search for ⇛ DY0-001 ⇚ and download exam materials for free through ✔ www.pdfvce.com ️✔️ 🙁Valid DY0-001 Test Pdf
- 100% Pass Quiz CompTIA - DY0-001 –Trustable Dumps Cost 🏩 Simply search for ▶ DY0-001 ◀ for free download on { www.pdfdumps.com } 🤽DY0-001 Real Torrent
- Reliable DY0-001 Exam Bootcamp 🦜 DY0-001 New Practice Questions 🌶 DY0-001 Test Dumps Free ⏭ Open website ( www.pdfvce.com ) and search for ➥ DY0-001 🡄 for free download ☕DY0-001 Valid Exam Review
- DY0-001 Learning Materials: CompTIA DataAI Certification Exam - DY0-001 Actual Lab Questions 🕡 Copy URL ➥ www.dumpsmaterials.com 🡄 open and search for “ DY0-001 ” to download for free ✊DY0-001 Exam PDF
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, ccitonline.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, writeablog.net, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
2026 Latest FreePdfDump DY0-001 PDF Dumps and DY0-001 Exam Engine Free Share: https://drive.google.com/open?id=1Xuj_p1gtTxbVm0J-MFUDTCe3Er5QIlmx