BTW, DOWNLOAD part of Itcertkey Data-Engineer-Associate dumps from Cloud Storage: https://drive.google.com/open?id=1abuwo2litcrwtI6WEhgZNiLZkNCuI2oP
The AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) study material of Itcertkey is available in three different and easy-to-access formats. The first one is printable and portable AWS Certified Data Engineer - Associate (DEA-C01) (Data-Engineer-Associate) PDF format. With the PDF version, you can access the collection of actual Amazon Data-Engineer-Associate Questions with your smart devices like smartphones, tablets, and laptops.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Ingestion and Transformation | 34% | - Implement data quality and validation - Transform and enrich data
|
| Topic 2: Data Store Management | 26% | - Optimize storage performance and cost - Manage data lifecycle and storage tiers - Design and implement data storage solutions
|
| Topic 3: Data Operations and Support | 22% | - Automate operational tasks - Backup, restore, and disaster recovery - Monitor and troubleshoot data pipelines
|
| Topic 4: Data Security and Governance | 18% | - Encrypt data at rest and in transit - Protect sensitive data - Implement access control and authentication
|
>> Valid Test Data-Engineer-Associate Tutorial <<
Thousands of people will crowd into our website to choose the Data-Engineer-Associate study materials. So people are different from the past. Learning has become popular among different age groups. Our Data-Engineer-Associate guide questions truly offer you the most useful knowledge. You can totally trust us. We are trying our best to meet your demands. Why not give our Data-Engineer-Associate Practice Engine a chance? Our products will live up to your expectations.
NEW QUESTION # 197
A data engineer is using an AWS Glue ETL job to remove outdated customer records from a table that contains customer account information. The data engineer is using the following SQL command to remove customers that exist in a table named monthly_accounts_update from the customer accounts table:
MERGE INTO accounts t USING monthly_accounts_update s ON t.customer = s.customer WHEN MATCHED THEN DELETE What will happen when the data engineer runs the SQL command?
Answer: A
Explanation:
Option A is correct. The MERGE INTO statement is used to conditionally update, insert, or delete rows based on a match condition between a target table and a source table. In this statement, the target table is accounts and the source table is monthly_accounts_update. The join condition is t.customer = s.customer. Because the statement uses WHEN MATCHED THEN DELETE, every row in accounts that has a matching customer value in monthly_accounts_update will be deleted from the target table.
AWS documentation for MERGE INTO states that it conditionally updates, deletes, or inserts rows into an Apache Iceberg table, and the syntax explicitly includes WHEN MATCHED THEN DELETE. AWS Glue guidance and examples for Iceberg also show MERGE INTO as a supported pattern for row-level changes in Glue ETL workflows. This means the syntax is valid for supported Glue-Iceberg use cases, so option D is incorrect. Options B and C are also incorrect because the statement does not retain only matching rows and does not delete the entire table. It deletes only the rows in the target table that satisfy the match condition.
NEW QUESTION # 198
A data engineer maintains a materialized view that is based on an Amazon Redshift database. The view has a column named load_date that stores the date when each row was loaded.
The data engineer needs to reclaim database storage space by deleting all the rows from the materialized view.
Which command will reclaim the MOST database storage space?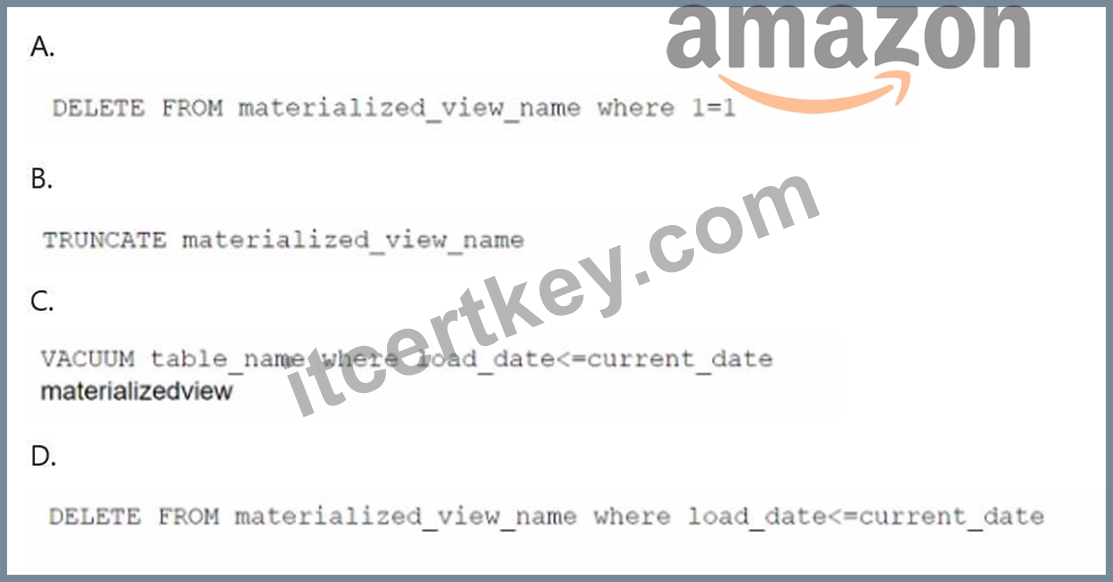
Answer: D
Explanation:
To reclaim the most storage space from a materialized view in Amazon Redshift, you should use a DELETE operation that removes all rows from the view. The most efficient way to remove all rows is to use a condition that always evaluates to true, such as 1=1. This will delete all rows without needing to evaluate each row individually based on specific column values like load_date.
* Option A: DELETE FROM materialized_view_name WHERE 1=1;This statement will delete all rows in the materialized view and free up the space. Since materialized views in Redshift store precomputed data, performing a DELETE operation will remove all stored rows.
Other options either involve inappropriate SQL statements (e.g., VACUUM in option C is used for reclaiming storage space in tables, not materialized views), or they don't remove data effectively in the context of a materialized view (e.g., TRUNCATE cannot be used directly on a materialized view).
References:
* Amazon Redshift Materialized Views Documentation
* Deleting Data from Redshift
NEW QUESTION # 199
A company wants to analyze sales records that the company stores in a MySQL database. The company wants to correlate the records with sales opportunities identified by Salesforce.
The company receives 2 GB erf sales records every day. The company has 100 GB of identified sales opportunities. A data engineer needs to develop a process that will analyze and correlate sales records and sales opportunities. The process must run once each night.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: A
Explanation:
Problem Analysis:
The company processes 2 GB of daily sales records and 100 GB of Salesforce sales opportunities.
The goal is to analyze and correlate the two datasets with low operational overhead.
The process must run once nightly.
Key Considerations:
Amazon AppFlow simplifies data integration with Salesforce.
AWS Glue can extract data from MySQL and perform ETL operations.
Step Functions can orchestrate workflows with minimal manual intervention.
Apache Airflow and Flink add complexity, which conflicts with the requirement for low operational overhead.
Solution Analysis:
Option A: MWAA + Lambda + Step Functions
Requires custom Lambda code for dataset correlation, increasing development and operational complexity.
Option B: AppFlow + Glue + MWAA
MWAA adds orchestration overhead compared to the simpler Step Functions.
Option C: AppFlow + Glue + Step Functions
AppFlow fetches Salesforce data, Glue extracts MySQL data, and Step Functions orchestrate the entire process.
Minimal setup and operational overhead, making it the best choice.
Option D: AppFlow + Kinesis + Flink + Step Functions
Using Kinesis and Flink for batch processing introduces unnecessary complexity.
Final Recommendation:
Use Amazon AppFlow to fetch Salesforce data, AWS Glue to process MySQL data, and Step Functions for orchestration.
Amazon AppFlow Overview
AWS Glue ETL Documentation
AWS Step Functions
NEW QUESTION # 200
A media company uses software as a service (SaaS) applications to gather data by using third-party tools. The company needs to store the data in an Amazon S3 bucket. The company will use Amazon Redshift to perform analytics based on the data.
Which AWS service or feature will meet these requirements with the LEAST operational overhead?
Answer: B
Explanation:
Amazon AppFlow is a fully managed integration service that enables you to securely transfer data between SaaS applications and AWS services like Amazon S3 and Amazon Redshift. Amazon AppFlow supports many SaaS applications as data sources and targets, and allows you to configure data flows with a few clicks. Amazon AppFlow also provides features such as data transformation, filtering, validation, and encryption to prepare and protect your data. Amazon AppFlow meets the requirements of the media company with the least operational overhead, as it eliminates the need to write code, manage infrastructure, or monitor data pipelines. Reference:
Amazon AppFlow
Amazon AppFlow | SaaS Integrations List
Get started with data integration from Amazon S3 to Amazon Redshift using AWS Glue interactive sessions
NEW QUESTION # 201
A data engineer is configuring an AWS Glue job to read data from an Amazon S3 bucket. The data engineer has set up the necessary AWS Glue connection details and an associated IAM role. However, when the data engineer attempts to run the AWS Glue job, the data engineer receives an error message that indicates that there are problems with the Amazon S3 VPC gateway endpoint.
The data engineer must resolve the error and connect the AWS Glue job to the S3 bucket.
Which solution will meet this requirement?
Answer: C
Explanation:
The error message indicates that the AWS Glue job cannot access the Amazon S3 bucket through the VPC endpoint. This could be because the VPC's route table does not have the necessary routes to direct the traffic to the endpoint. To fix this, the data engineer must verify that the route table has an entry for the Amazon S3 service prefix (com.amazonaws.region.s3) with the target as the VPC endpoint ID. This will allow the AWS Glue job to use the VPC endpoint to access the S3 bucket without going through the internet or a NAT gateway. For more information, see Gateway endpoints. Reference:
Troubleshoot the AWS Glue error "VPC S3 endpoint validation failed"
Amazon VPC endpoints for Amazon S3
[AWS Certified Data Engineer - Associate DEA-C01 Complete Study Guide]
NEW QUESTION # 202
......
Work hard and practice with our Amazon Data-Engineer-Associate dumps till you are confident to pass the Amazon Data-Engineer-Associate exam. And that too with flying colors and achieving the Amazon Data-Engineer-Associate Certification on the first attempt. You will identify both your strengths and shortcomings when you utilize AWS Certified Data Engineer - Associate (DEA-C01) practice exam software.
Data-Engineer-Associate Free Updates: https://www.itcertkey.com/Data-Engineer-Associate_braindumps.html
DOWNLOAD the newest Itcertkey Data-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1abuwo2litcrwtI6WEhgZNiLZkNCuI2oP