BraindumpQuiz's Databricks Databricks-Certified-Data-Engineer-Associate Exam Training materials allows candidates to learn in the case of mock examinations. You can control the kinds of questions and some of the problems and the time of each test. In the site of BraindumpQuiz, you can prepare for the exam without stress and anxiety. At the same time, you also can avoid some common mistakes. So you will gain confidence and be able to repeat your experience in the actual test to help you to pass the exam successfully.
| Section | Weight | Objectives |
|---|---|---|
| Data Pipeline Architecture | 15-20% | - Monitor and optimize pipeline performance - Understand ELT vs ETL patterns - Design data pipelines for batch and streaming - Implement incremental data processing |
| Lakehouse Platform Concepts | 10-15% | - Understand the Lakehouse architecture and its benefits - Explain data governance and security concepts - Describe key Databricks Lakehouse platform components |
| Spark SQL and DataFrames | 15-20% | - Write and execute Spark SQL queries - Handle null values and data quality - Aggregate and group data - Join and union DataFrames |
| Python for Data Engineering | 10-15% | - Work with Spark APIs in Python - Use PySpark for data processing - Implement user-defined functions (UDFs) |
| Delta Lake Fundamentals | 20-25% | - Understand ACID transactions and time travel - Explain Delta Lake features and benefits - Create and manage Delta tables - Write to and read from Delta tables |
| Apache Spark Data Processing Fundamentals | 20-25% | - Use Spark SQL for data processing - Work with structured data types (arrays, maps, structs) - Apply transformations and actions on DataFrames - Create and use Spark DataFrames |
>> Databricks-Certified-Data-Engineer-Associate Reliable Exam Pass4sure <<
The website pages list the important information about our Databricks-Certified-Data-Engineer-Associate real quiz, the exam name and code, the total quantity of the questions and answers, the characteristics and merits of the product, the price, the details and the guarantee of our Databricks-Certified-Data-Engineer-Associate Training Materials, the contact methods, the evaluations of the client on our product and the related exams. You can analyze the information the website pages provide carefully before you decide to buy our Databricks-Certified-Data-Engineer-Associate exam questions.
NEW QUESTION # 89
A data engineer wants to create a data entity from a couple of tables. The data entity must be used by other data engineers in other sessions. It also must be saved to a physical location.
Which of the following data entities should the data engineer create?
Answer: E
NEW QUESTION # 90
A data engineer runs a statement every day to copy the previous day's sales into the table transactions. Each day's sales are in their own file in the location "/transactions/raw".
Today, the data engineer runs the following command to complete this task: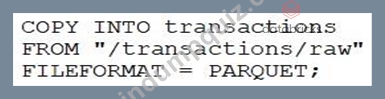
After running the command today, the data engineer notices that the number of records in table transactions has not changed.
Which of the following describes why the statement might not have copied any new records into the table?
Answer: E
Explanation:
The COPY INTO statement is an idempotent operation, which means that it will skip any files that have already been loaded into the target table1. This ensures that the data is not duplicated or corrupted by multiple attempts to load the same file. Therefore, if the data engineer runs the same command every day without specifying the names of the files to be copied with the FILES keyword or a glob pattern with the PATTERN keyword, the statement will only copy the first file that matches the source location and ignore the rest. To avoid this problem, the data engineer should either use the FILES or PATTERN keywords to filter the files to be copied based on the date or some other criteria, or delete the files from the source location after they are copied into the table2. References: 1: COPY INTO | Databricks on AWS 2: Get started using COPY INTO to load data | Databricks on AWS
NEW QUESTION # 91
A data engineer must apply a daily batch of customer records to a Delta table so that existing customers are updated, new customers are inserted, and no duplicates are created.
Which statement accomplishes this in a single atomic operation?
Answer: D
Explanation:
MERGE INTO performs upserts in a single ACID transaction, updating matched rows and inserting unmatched rows. INSERT INTO would create duplicates, and both INSERT OVERWRITE and CREATE OR REPLACE would discard existing records not present in the daily batch.
NEW QUESTION # 92
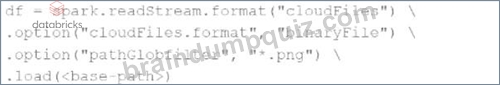
A data engineer needs to parse only png files in a directory that contains files with different suffixes. Which code should the data engineer use to achieve this task?



Answer: B
NEW QUESTION # 93
Which of the following SQL keywords can be used to convert a table from a long format to a wide format?
Answer: B
Explanation:
The SQL keyword that can be used to convert a table from a long format to a wide format is PIVOT. The PIVOT clause is used to rotate the rows of a table into columns of a new table1. The PIVOT clause can aggregate the values of a column based on the distinct values of another column, and use those values as the column names of the new table1. The PIVOT clause can be useful for transforming data from a long format, where each row represents an observation with multiple attributes, to a wide format, where each row represents an observation with a single attribute and multiple values2. For example, the PIVOT clause can be used to convert a table that contains the sales of different products by different regions into a table that contains the sales of each product by each region as separate columns1.
The other options are not suitable for converting a table from a long format to a wide format. CONVERT is a function that can be used to change the data type of an expression3. WHERE is a clause that can be used to filter the rows of a table based on a condition4. TRANSFORM is a keyword that can be used to apply a user- defined function to a group of rows in a table5. SUM is a function that can be used to calculate the total of a numeric column.
:
1: PIVOT | Databricks on AWS
2: Reshaping Data - Long vs Wide Format | Databricks on AWS
3: CONVERT | Databricks on AWS
4: WHERE | Databricks on AWS
5: TRANSFORM | Databricks on AWS
[SUM | Databricks on AWS]
NEW QUESTION # 94
......
Of course, the future is full of unknowns and challenges for everyone. Even so, we all hope that we can have a bright future. Pass the Databricks-Certified-Data-Engineer-Associate exam, for most people, is an ability to live the life they want, and the realization of these goals needs to be established on a good basis of having a good job. A good job requires a certain amount of competence, and the most intuitive way to measure competence is whether you get a series of the test Databricks certification and obtain enough qualifications. With the qualification certificate, you are qualified to do this professional job. Therefore, getting the test Databricks certification is of vital importance to our future employment. And the Databricks-Certified-Data-Engineer-Associate Study Materials can provide a good learning platform for users who want to get the test Databricks certification in a short time.
Databricks-Certified-Data-Engineer-Associate Study Materials: https://www.braindumpquiz.com/Databricks-Certified-Data-Engineer-Associate-exam-material.html