2026 Latest EduDump NCM-MCI-6.10 PDF Dumps and NCM-MCI-6.10 Exam Engine Free Share: https://drive.google.com/open?id=1ld7Dy3C_9rjxMEBpkute0FIkfjD0IUoj
As the most popular NCM-MCI-6.10 exam questions in the field, the passing rate of our NCM-MCI-6.10 learning questions has up to 98 to 100 percent. And our NCM-MCI-6.10 preparation materials have three versions to satisfy different taste and preference: PDF version, Soft version and APP version. The three versions of NCM-MCI-6.10 training prep have the same questions, only the displays are different. You can buy according to your interest. In addition, NCM-MCI-6.10 test engine is indispensable helps for your success.
| Section | Objectives |
|---|---|
| Deploy and Upgrade Nutanix Environments | - Cluster installation and configuration - Software and firmware upgrades - Foundation processes |
| Analyze and Remediate Performance Issues | - Troubleshooting storage performance - Troubleshooting network performance - Performance monitoring and metrics |
| Manage and Optimize Nutanix Storage | - Storage container and VDisk management - Storage optimization and efficiency - Data protection and disaster recovery |
| Implement and Manage Security and Compliance | - Compliance frameworks - Security hardening - Access control and authentication |
| Configure and Manage Nutanix Networking | - AHV networking configuration - Network segmentation and microsegmentation - Advanced networking scenarios |
| Manage and Configure Nutanix Virtual Infrastructure | - Resource scheduling and optimization - AHV cluster configuration - VM management and operations |
| Troubleshoot and Resolve Complex Issues | - Cluster health management - Failure recovery procedures - Log analysis and diagnostics |
>> Latest NCM-MCI-6.10 Exam Bootcamp <<
Practice tests are also a core part of the EduDump product. We recognize that retention of information is crucial, and interactive learning tools, such as practice exams are provided to help students retain the information they have learned. These NCM-MCI-6.10 Practice Tests simulate the actual exam conditions and provide applicants with an accurate assessment of their readiness for the test.
NEW QUESTION # 20
An administrator needs to configure a new write-intensive MS-SQL VM on Cluster 1.
VM specifications:
* vCPU: 12
* vRAM: 128GB
* Storage: 100 GB OS, 750 GB Data
Create the VM and any objects needed in the current environment to meet requirements, maximizing performance for the production environment. Include NEWSQL in the name of any new objects.
Production environment:
* 4 nodes
* Each node has two 8-core CPUs
* Each node has 1024 GB RAM
* Storage: 4 × 7.16 TB SSD Disks and 8 × 8 TB HDD disks
Make sure the VM is configured for maximum performance for the production environment.
Note: Network configuration is not required at this time. Do not power on the VM.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to create the high-performance SQL VM on Cluster 1.
This task requires two phases: first, creating a new all-flash storage container, and second, creating the VM with a specific vNUMA and disk controller configuration for maximum performance.
1. Access Cluster 1 Prism Element
* From the main Prism Central dashboard, navigate to Hardware > Clusters.
* Find Cluster 1 in the list and click its name. This will open the specific Prism Element login page for that cluster.
* Log in to Cluster 1's Prism Element interface.
2. Create the All-Flash Storage Container
To maximize performance for a "write-intensive" workload on a hybrid cluster, the data and log disks must be placed on an all-flash container.
* In the Cluster 1 PE interface, click the gear icon (Settings) in the top-right corner.
* From the left-hand menu, select Storage.
* Click the + Storage Container button.
* Fill in the basic details:
* Name: NEWSQL_Flash_Container
* Click Advanced Settings.
* Scroll down to the Storage Tier section.
* Select the SSD radio button. This pins all data in this container to the SSD tier, ensuring all-flash performance.
* Click Save.
3. Create and Configure the VM
Now, create the VM, applying vNUMA and multi-SCSI controller best practices.
* From the main PE dashboard, navigate to the VM view.
* Click the + Create VM button.
* Enter the compute details. This configuration is critical for vNUMA performance, as it tells the VM's guest OS about the underlying physical NUMA topology (2 CPUs with 8 cores each).
* Name: NEWSQL_VM
* vCPUs: 12
* Number of Sockets: 2
* Cores per vCPU: 6 (This creates a 2-socket, 6-core VM, totaling 12 vCPUs)
* Memory: 128 GB
* Scroll down to the Disks section and add the OS disk:
* Click + Add New Disk.
* Storage Container: Select the default (hybrid) container.
* Size: 100 GB
* Bus: SCSI
* Device Index: 0 (This will be scsi.0)
* Click Add.
* Add the Data disk (on its own controller for parallel processing):
* Click + Add New Disk.
* Storage Container: Select NEWSQL_Flash_Container.
* Size: 750 GB
* Bus: SCSI
* Device Index: 1 (This creates a new controller, scsi.1)
* Click Add.
* Add a Log disk (on its own controller, a best practice for "write-intensive" SQL):
* Click + Add New Disk.
* Storage Container: Select NEWSQL_Flash_Container.
* Size: 100 GB (A common size for a log disk)
* Bus: SCSI
* Device Index: 2 (This creates a third controller, scsi.2)
* Click Add.
* Review the configuration: You should now have three disks attached, each on a separate controller (scsi.
0, scsi.1, scsi.2). This provides the maximum I/O performance.
* Ensure the Power on VM after creation box is unchecked.
* Click Save.
Topic 1, Performance Based Questions Set 1
Environment
You have been provisioned a dedicated environment for your assessment which includes the following:
Initial Steps
* When you first log into Prism Central or Prism Element you may see the EULA screen. Accept the EULA with any name and then disable Pulse.
* To access Prism Element, the pass-through from Prism Central
(Infrastructure\Hardware\Clusters\cluster-x\Launch Prism Element) works better than directly using the external IP:9440.
Workstation
* Windows Server 2019
* All software/tools/etc to perform the required tasks
* Nutanix Documentation and whitepapers can be found in Desktop\Files\Documentation and Desktop\Files\Documentation 6.10
* Note that the Workstation is the system you are currently logged into
* Windows Server 2019
* All software/tools/etc to perform the required tasks
* Nutanix Documentation and whitepapers can be found in Desktop\Files\Documentation and Desktop\Files\Documentation 6.10
* Note that the Workstation is the system you are currently logged into Nutanix Cluster
* There are two clusters provided, connected to one Prism Central. The connection information for the relevant cluster will be displayed to the right of the question. Please make sure you are working on the correct cluster for each item. Please ignore any licensing violations.
Important Notes
* If the text is too small and hard to read, or you cannot see all of the GUI, you can increase/decrease the zoom of the browser with CTRL + and CTRL - (the plus and minus keys).
Prism Central Web Console
* admin / ykZUCJMER7V*
* nutanix / UJ2xE!DEXGY
Cluster 1
* CVM external IP: 34.53.118.63
* CVM DR IP: 172.30.0.6
* admin / 9Fw0B!3QH4X)
* nutanix / GNP*FE2504XWZ
* root / KR*6HY0z5E8
Cluster 2
* CVM external IP: 34.82.155.5
* CVM DR IP: 172.30.0.4
* admin / 5*K30fA76X
* nutanix / N*3F%1ME!Z7T9
NEW QUESTION # 21
Task 5
An administrator has noticed that after a host failure, the SQL03 VM was not powered back on from another host within the cluster. The Other SQL VMs (SQL01, SQL02) have recovered properly in the past.
Resolve the issue and configure the environment to ensure any single host failure affects a minimal number os SQL VMs.
Note: Do not power on any VMs
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
One possible reason why the SQL03 VM was not powered back on after a host failure is that the cluster was configured with the default (best effort) VM high availability mode, which does not guarantee the availability of VMs in case of insufficient resources on the remaining hosts. To resolve this issue, I suggest changing the VM high availability mode to guarantee (reserved segments), which reserves some memory on each host for failover of VMs from a failed host. This way, the SQL03 VM will have a higher chance of being restarted on another host in case of a host failure.
To change the VM high availability mode to guarantee (reserved segments), you can follow these steps:
Log in to Prism Central and select the cluster where the SQL VMs are running.
Click on the gear icon on the top right corner and select Cluster Settings.
Under Cluster Services, click on Virtual Machine High Availability.
Select Guarantee (Reserved Segments) from the drop-down menu and click Save.
To configure the environment to ensure any single host failure affects a minimal number of SQL VMs, I suggest using anti-affinity rules, which prevent VMs that belong to the same group from running on the same host. This way, if one host fails, only one SQL VM will be affected and the other SQL VMs will continue running on different hosts.
To create an anti-affinity rule for the SQL VMs, you can follow these steps:
Log in to Prism Central and click on Entities on the left menu.
Select Virtual Machines from the drop-down menu and click on Create Group.
Enter a name for the group, such as SQL Group, and click Next.
Select the SQL VMs (SQL01, SQL02, SQL03) from the list and click Next.
Select Anti-Affinity from the drop-down menu and click Next.
Review the group details and click Finish.
I hope this helps. How else can I help?
https://portal.nutanix.com/page/documents/details?targetId=AHV-Admin-Guide-v6_5:ahv-affinity-policies-c.html
A screenshot of a computer Description automatically generated with medium confidence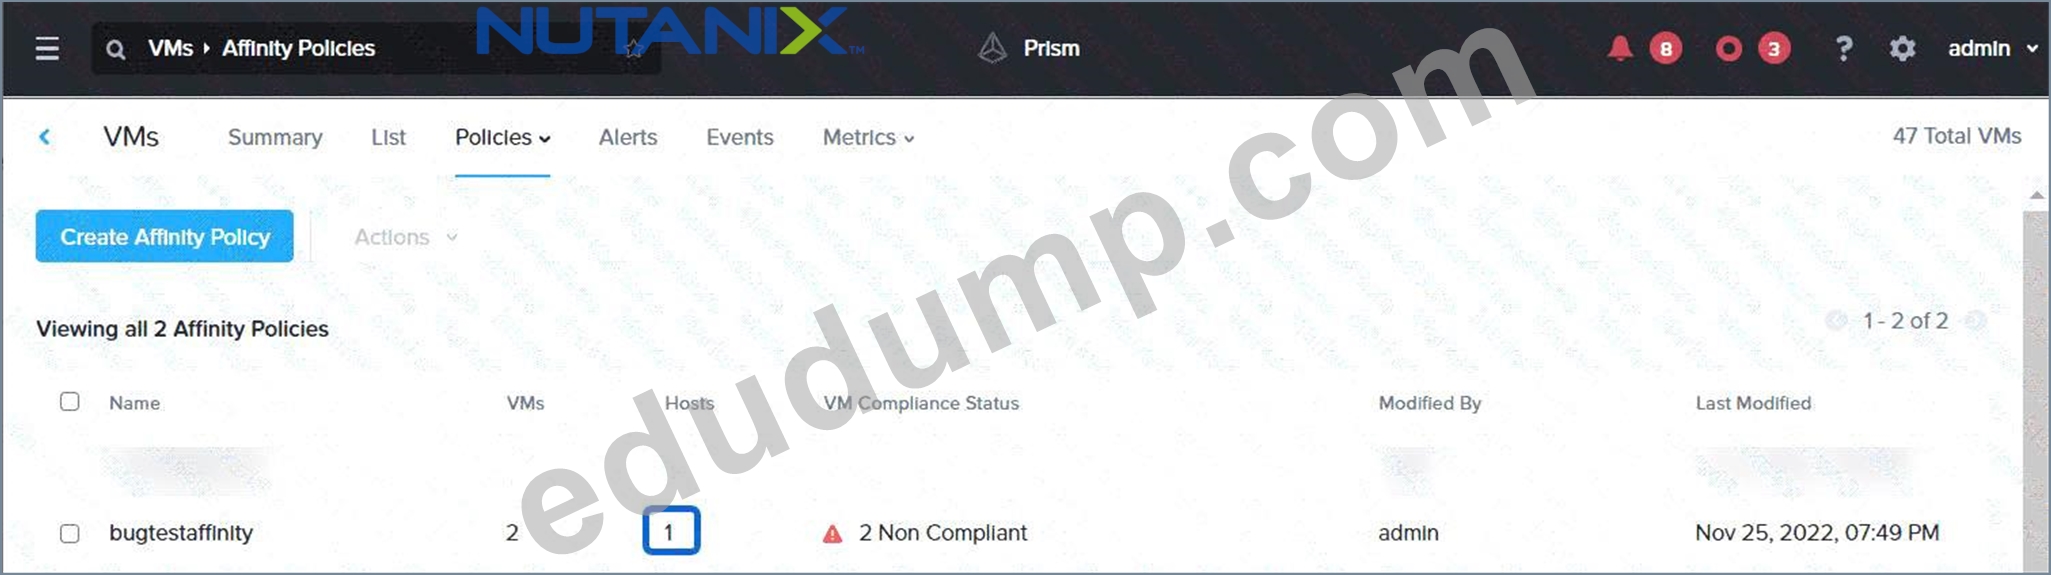
NEW QUESTION # 22
Task 14
An administrator has been asked to configure a storage for a distributed application which uses large data sets across multiple worker VMs.
The worker VMs must run on every node. Data resilience is provided at the application level and low cost per GB is a Key Requirement.
Configure the storage on the cluster to meet these requirements. Any new object created should include the phrase Distributed_App in the name.
Answer:
Explanation:
See the Explanation for step by step solution.
Explanation:
To configure the storage on the cluster for the distributed application, you can follow these steps:
Log in to Prism Element of cluster A using the credentials provided.
Go to Storage > Storage Pools and click on Create Storage Pool.
Enter a name for the new storage pool, such as Distributed_App_Storage_Pool, and select the disks to include in the pool. You can choose any combination of SSDs and HDDs, but for low cost per GB, you may prefer to use more HDDs than SSDs.
Click Save to create the storage pool.
Go to Storage > Containers and click on Create Container.
Enter a name for the new container, such as Distributed_App_Container, and select the storage pool that you just created, Distributed_App_Storage_Pool, as the source.
Under Advanced Settings, enable Erasure Coding and Compression to reduce the storage footprint of the data.
You can also disable Replication Factor since data resilience is provided at the application level. These settings will help you achieve low cost per GB for the container.
Click Save to create the container.
Go to Storage > Datastores and click on Create Datastore.
Enter a name for the new datastore, such as Distributed_App_Datastore, and select NFS as the datastore type.
Select the container that you just created, Distributed_App_Container, as the source.
Click Save to create the datastore.
The datastore will be automatically mounted on all nodes in the cluster. You can verify this by going to Storage > Datastores and clicking on Distributed_App_Datastore. You should see all nodes listed under Hosts.
You can now create or migrate your worker VMs to this datastore and run them on any node in the cluster.
The datastore will provide low cost per GB and high performance for your distributed application.
NEW QUESTION # 23
An administrator is experiencing an unidentified issue which is causing inode exhaustion on CVMs in Cluster
1. The time between receiving alerts and exhaustion is too short; the administrator needs to lower the alert thresholds to allow more time to clean up inodes until the issue has been identified and resolution implemented.
From Prism Element, modify the appropriate alert policy setting critical threshold for Cluster 1 to 60% and warning threshold to 45%. Ensure the check runs every minute and is not resolved without administrator action.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to modify the alert policy from the Prism Element (PE) interface for Cluster 1.
1. Access Cluster 1 Prism Element
* From the main Prism Central dashboard, navigate to Hardware > Clusters.
* Find Cluster 1 in the list and click its name. This will open the specific Prism Element login page for that cluster.
* Log in to Cluster 1's Prism Element interface.
2. Modify the Alert Policy
* In the Cluster 1 PE interface, click the gear icon (Settings) in the top-right corner.
* From the left-hand menu, select Alert Policies.
* In the search bar, type inode to find the correct policy.
* Select the checkbox for the policy named cvm_inode_usage_high.
* Click the Update button.
* In the "Update Alert Policy" dialog, configure the following settings:
* Warning Threshold (%): Change the value to 45.
* Critical Threshold (%): Change the value to 60.
* Check Interval (Secs): Change the value to 60 (to run the check every minute).
* Auto Resolve: Uncheck this box (to ensure the alert is not resolved without administrator action).
* Click Save.
NEW QUESTION # 24
The Database team is reporting performance degradation for a business-critical application on Saturdays.
The team is requesting monitoring of processor, memory and storage utilization for the cluster for the application: SQL01, SQL02.
The report should contain views for the following:
* At the cluster level, only for the Cluster 1: The maximum percentage of CPU used
* At the VM level, including any future VM with the prefix SQL: The maximum time taken, maximum percentage of time a VM waits to use the physical CPU, out of the total CPU The report should run on Sundays at 12:00 AM for the previous 7 days. The report should show when completed.
Create a report named SQL_Batch_Saturday that meets these requirements.
Generate an instance of the report named SQL_Batch_Saturday as a CSV and save the file.
Note: You must name the report SQL_Batch_Saturday to receive any credit. Any other name will not be accepted. SMTP is not configured.
Answer:
Explanation:
See the Explanation below for detailed answer.
Explanation:
Here is the step-by-step solution to create and run the report, performed entirely within Prism Central.
1. Create the Analysis Session
First, we will build the charts and entities for the report using the Analysis tool.
* From the Prism Central main menu, navigate to Operations > Analysis.
* Click the + New Session button.
* Add the required entities:
* In the "Entities" search box, type Cluster 1 and select Cluster: Cluster 1.
* In the "Entities" search box, type SQL01 and select VM: SQL01.
* In the "Entities" search box, type SQL02 and select VM: SQL02.
* Click Add Charts > New Chart to add the Cluster CPU chart:
* Title: Cluster 1 Max CPU Usage
* Entity Type: Cluster
* Metric: Cluster CPU Usage %
* Aggregation: Select Maximum.
* Click Add.
* Click Add Charts > New Chart to add the VM CPU Ready Time chart:
* Title: VM Max CPU Ready Time
* Entity Type: VM
* Metric: CPU Ready Time %
* Aggregation: Select Maximum.
* Click Add.
2. Save and Configure the Report
Now, save the session as a report and configure it to dynamically include all VMs with the SQL prefix.
* Click the Save as Report icon (the bookmark icon in the upper right).
* Name the report SQL_Batch_Saturday and click Save.
* Navigate to Operations > Reports.
* Find the SQL_Batch_Saturday report you just created and click its name to open the report editor.
* In the Entities tile, click the Edit (pencil) icon.
* By default, it will list "Cluster 1", "SQL01", and "SQL02".
* Change the VM selection:
* Select the radio button for All VMs prefixed with.
* In the text box, enter SQL.
* Ensure "Cluster 1" is still listed under "Clusters".
* Click Save.
3. Schedule the Report
* While still in the report editor for SQL_Batch_Saturday, click the Schedule button.
* Configure the schedule:
* Recurrence: Weekly
* Repeat on: Sunday
* Start Time: 12:00 AM
* Time Range: Previous 7 Days
* Configure the notification (as SMTP is not available):
* Expand the Notification Settings section.
* Check the box for Notify when ready (this enables the bell icon notification).
* Ensure "Email Report" is not checked.
* Click Save.
4. Generate and Save the CSV Instance
Finally, run the report now and download the CSV as requested.
* Navigate back to the main Operations > Reports list.
* Select the checkbox next to SQL_Batch_Saturday.
* Click the Actions dropdown and select Run Now.
* In the dialog, confirm the time range (e.g., "Last 7 Days") and click Run.
* Click the Report Instances tab.
* Wait for the report instance "SQL_Batch_Saturday" to finish running (the status will change from
"Running" to Succeeded).
* Once it has succeeded, click the Download (arrow) icon for that instance.
* Select the CSV format.
* Save the file to the desktop.
NEW QUESTION # 25
......
The 21 century is the information century. Information and cyber technology represents advanced productivity, and its rapid development and wide application have given a strong impetus to economic and social development and the progress of human civilization (NCM-MCI-6.10 exam materials). They are also transforming people's lives and the mode of operation of human society in a profound way. So you really should not be limited to traditional paper-based NCM-MCI-6.10 Test Torrent in the 21 country especially when you are preparing for an exam,our company has invested a large amount of money to introduce the advanced operation system which not only can ensure our customers the fastest delivery speed but also can encrypt all of the personal NCM-MCI-6.10 information of our customers automatically.
NCM-MCI-6.10 Pass Guarantee: https://www.edudump.com/exams/Nutanix/NCM-MCI-6.10/
2026 Latest EduDump NCM-MCI-6.10 PDF Dumps and NCM-MCI-6.10 Exam Engine Free Share: https://drive.google.com/open?id=1ld7Dy3C_9rjxMEBpkute0FIkfjD0IUoj