BTW, DOWNLOAD part of Real4exams ARA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1VijQGtLxUrle1tq7VnzJBklTLdUH0Tdv
Different from traditional learning methods, our ARA-C01 exam products adopt the latest technology to improve your learning experience. We hope that all candidates can try our free demo before deciding to buy our ARA-C01 study guide. The Q&A contained in the free demo are also compiled by our vetaren professionals who keep close on the changes of the ARA-C01 learning dumps according to the real exam. Come and have a try, you will get satisfied with our ARA-C01 training engine!
| Section | Objectives |
|---|---|
| Topic 1: Performance and Optimization | - Cost optimization
|
| Topic 2: Security, Governance, and Compliance | - Data governance
|
| Topic 3: Data Architecture and Design | - Design scalable Snowflake architectures
|
| Topic 4: Data Sharing and Collaboration | - Secure data sharing
|
| Topic 5: Data Pipelines and Data Engineering | - Data ingestion and transformation
|
>> ARA-C01 Latest Exam Cram <<
As the saying goes, practice makes perfect. We are now engaged in the pursuit of Craftsman spirit in all walks of life. Professional and mature talents are needed in each field, similarly, only high-quality and high-precision SnowPro Advanced Architect Certification qualification question can enable learners to be confident to take the qualification examination so that they can get the certificate successfully, and our ARA-C01 Learning Materials are such high-quality learning materials, it can meet the user to learn the most popular test site knowledge. Because our experts have extracted the frequent annual test centers are summarized to provide users with reference.
NEW QUESTION # 86
A table, EMP_ TBL has three records as shown: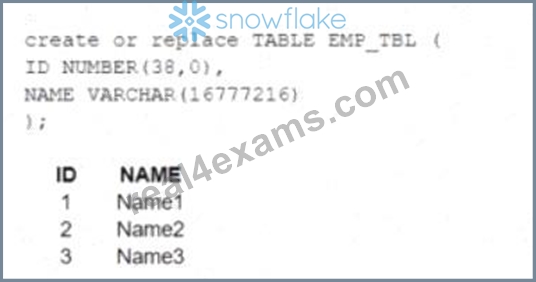
The following variables are set for the session: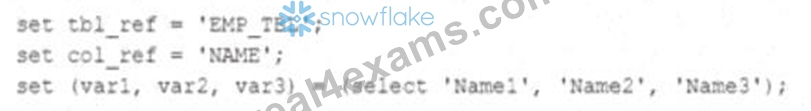
Which SELECT statements will retrieve all three records? (Select TWO).
Answer: A,B
Explanation:
* The correct answer is B and E because they use the correct syntax and values for the identifier function and the session variables.
* The identifier function allows you to use a variable or expression as an identifier (such as a table name or column name) in a SQL statement. It takes a single argument and returns it as an identifier. For example, identifier($tbl_ref) returns EMP_TBL as an identifier.
* The session variables are set using the SET command and can be referenced using the $ sign. For example, $var1 returns Name1 as a value.
* Option A is incorrect because it uses Stbl_ref and Scol_ref, which are not valid session variables or identifiers. They should be $tbl_ref and $col_ref instead.
* Option C is incorrect because it uses identifier<Stbl_ref>, which is not a valid syntax for the identifier function. It should be identifier($tbl_ref) instead.
* Option D is incorrect because it uses Cvarl, var2, and var3, which are not valid session variables or values. They should be $var1, $var2, and $var3 instead. References:
* Snowflake Documentation: Identifier Function
* Snowflake Documentation: Session Variables
* Snowflake Learning: SnowPro Advanced: Architect Exam Study Guide
NEW QUESTION # 87
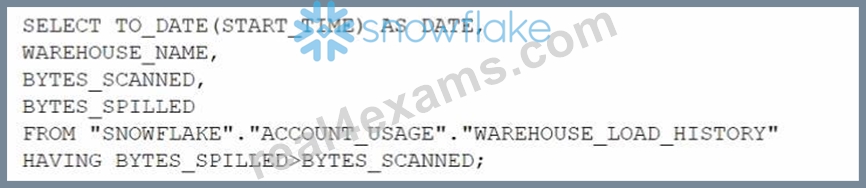
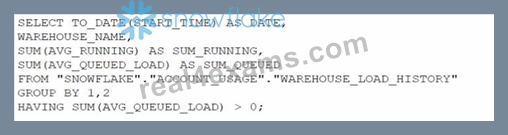
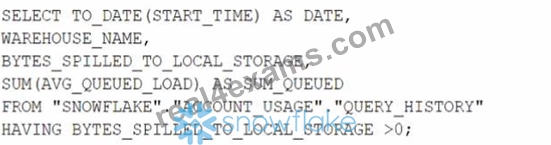
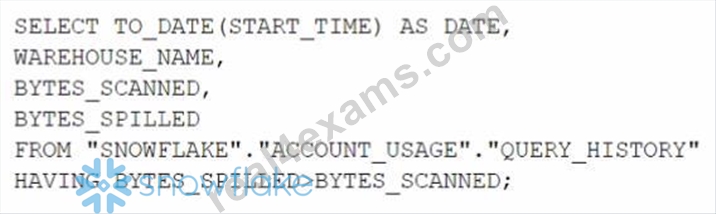
Which query will identify the specific days and virtual warehouses that would benefit from a multi-cluster warehouse to improve the performance of a particular workload?
Answer: B
Explanation:
The correct answer is option B. This query is designed to assess the need for a multi-cluster warehouse by examining the queuing time (AVG_QUEUED_LOAD) on different days and virtual warehouses. When theAVG_QUEUED_LOADis greater than zero, it suggests that queries are waiting for resources, which can be an indicator that performance might be improved by using a multi-cluster warehouse to handle the workload more efficiently. By grouping by date and warehouse name and filtering on the sum of the average queued load being greater than zero, the query identifies specific days and warehouses where the workload exceeded the available compute resources. This information is valuable when considering scaling out warehouses to multi-cluster configurations for improved performance.
NEW QUESTION # 88
Data is being imported and stored as JSON in a VARIANT column. Query performance was fine, but most recently, poor query performance has been reported.
What could be causing this?
Answer: B
Explanation:
Data is being imported and stored as JSON in a VARIANT column. Query performance was fine, but most recently, poor query performance has been reported. This could be caused by the following factors:
* The order of the keys in the JSON was changed. Snowflake stores semi-structured data internally in a column-like structure for the most common elements, and the remainder in a leftovers-like column. The order of the keys in the JSON affects how Snowflake determines the common elements and how it optimizes the query performance. If the order of the keys in the JSON was changed, Snowflake might have to re-parse the data and re-organize the internal storage, which could result in slower query performance.
* There were variations in string lengths for the JSON values in the recent data imports. Non-native values, such as dates and timestamps, are stored as strings when loaded into a VARIANT column.
Operations on these values could be slower and also consume more space than when stored in a relational column with the corresponding data type. If there were variations in string lengths for the JSON values in the recent data imports, Snowflake might have to allocate more space and perform more conversions, which could also result in slower query performance.
The other options are not valid causes for poor query performance:
* There were JSON nulls in the recent data imports. Snowflake supports two types of null values in semi- structured data: SQL NULL and JSON null. SQL NULL means the value is missing or unknown, while JSON null means the value is explicitly set to null. Snowflake can distinguish between these two types of null values and handle them accordingly. Having JSON nulls in the recent data imports should not affect the query performance significantly.
* The recent data imports contained fewer fields than usual. Snowflake can handle semi-structured data with varying schemas and fields. Having fewer fields than usual in the recent data imports should not affect the query performance significantly, as Snowflake can still optimize the data ingestion and query execution based on the existing fields.
Considerations for Semi-structured Data Stored in VARIANT
Snowflake Architect Training
Snowflake query performance on unique element in variant column
Snowflake variant performance
NEW QUESTION # 89
Why might a Snowflake Architect use a star schema model rather than a 3NF model when designing a data architecture to run in Snowflake? (Select TWO).
Answer: B,D
NEW QUESTION # 90
A media company needs a data pipeline that will ingest customer review data into a Snowflake table, and apply some transformations. The company also needs to use Amazon Comprehend to do sentiment analysis and make the de-identified final data set available publicly for advertising companies who use different cloud providers in different regions.
The data pipeline needs to run continuously and efficiently as new records arrive in the object storage leveraging event notifications. Also, the operational complexity, maintenance of the infrastructure, including platform upgrades and security, and the development effort should be minimal.
Which design will meet these requirements?
Answer: D
Explanation:
Option B is the best design to meet the requirements because it uses Snowpipe to ingest the data continuously and efficiently as new records arrive in the object storage, leveraging event notifications. Snowpipe is a service that automates the loading of data from external sources into Snowflake tables1. It also uses streams and tasks to orchestrate transformations on the ingested data. Streams are objects that store the change history of a table, and tasks are objects that execute SQL statements on a schedule or when triggered by another task2. Option B also uses an external function to do model inference with Amazon Comprehend and write the final records to a Snowflake table. An external function is a user-defined function that calls an external API, such as Amazon Comprehend, to perform computations that are not natively supported by Snowflake3. Finally, option B uses the Snowflake Marketplace to make the de-identified final data set available publicly for advertising companies who use different cloud providers in different regions. The Snowflake Marketplace is a platform that enables data providers to list and share their data sets with data consumers, regardless of the cloud platform or region they use4.
Option A is not the best design because it uses copy into to ingest the data, which is not as efficient and continuous as Snowpipe. Copy into is a SQL command that loads data from files into a table in a single transaction. It also exports the data into Amazon S3 to do model inference with Amazon Comprehend, which adds an extra step and increases the operational complexity and maintenance of the infrastructure.
Option C is not the best design because it uses Amazon EMR and PySpark to ingest and transform the data, which also increases the operational complexity and maintenance of the infrastructure. Amazon EMR is a cloud service that provides a managed Hadoop framework to process and analyze large-scale data sets. PySpark is a Python API for Spark, a distributed computing framework that can run on Hadoop. Option C also develops a python program to do model inference by leveraging the Amazon Comprehend text analysis API, which increases the development effort.
Option D is not the best design because it is identical to option A, except for the ingestion method. It still exports the data into Amazon S3 to do model inference with Amazon Comprehend, which adds an extra step and increases the operational complexity and maintenance of the infrastructure.
NEW QUESTION # 91
......
There may be a lot of people feel that the preparation process for ARA-C01 exams is hard and boring, and hard work does not necessarily mean good results, which is an important reason why many people are afraid of examinations. Today, our ARA-C01 Exam Materials will radically change this. High question hit rate makes you no longer aimless when preparing for the exam, so you just should review according to the content of our ARA-C01 study guide prepared for you.
ARA-C01 Practice Exam Questions: https://www.real4exams.com/ARA-C01_braindumps.html
DOWNLOAD the newest Real4exams ARA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1VijQGtLxUrle1tq7VnzJBklTLdUH0Tdv