DOWNLOAD the newest PrepPDF Databricks-Certified-Professional-Data-Engineer PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1qy7qHQCQ3MZeRLBOh1Qu8Q2MOBCCE3pF
Our Databricks-Certified-Professional-Data-Engineer desktop practice test software works after installation on Windows computers. The Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer web-based practice exam has all the features of the desktop software, but it requires an active internet connection. If you are busy in your daily routine and cant manage a proper time to sit and prepare for the Databricks-Certified-Professional-Data-Engineer Certification test, our Databricks-Certified-Professional-Data-Engineer PDF questions file is ideal for you. You can open and use the Databricks-Certified-Professional-Data-Engineer Questions from any location at any time on your smartphones, tablets, and laptops. Questions in the Databricks Certified Professional Data Engineer Exam Databricks-Certified-Professional-Data-Engineer PDF document are updated, and real.
Databricks Certified Professional Data Engineer exam is a comprehensive assessment of a candidate's ability to design, implement, and manage data pipelines on the Databricks platform. Databricks Certified Professional Data Engineer Exam certification exam covers a wide range of topics, including data ingestion, data processing, data transformation, and data storage. Databricks-Certified-Professional-Data-Engineer exam is designed to test the candidate's knowledge of best practices for building efficient and scalable data pipelines that can handle large volumes of data.
Databricks Certified Professional Data Engineer certification exam is a hands-on exam that requires candidates to demonstrate their skills in building data pipelines and workflows using Databricks. Databricks-Certified-Professional-Data-Engineer Exam consists of a set of performance-based tasks that require candidates to design, implement, and manage data solutions in a Databricks environment. Candidates are given a set of data engineering scenarios and must use Databricks to build solutions that meet the requirements of each scenario.
>> New Databricks-Certified-Professional-Data-Engineer Real Exam <<
You can learn Databricks-Certified-Professional-Data-Engineer quiz torrent skills and theory at your own pace, and you will save more time and energy that you can complete other thing. We also provide every candidate who wants to get certification with free Demo to check our materials. No other Databricks-Certified-Professional-Data-Engineer study materials or study dumps can bring you the knowledge and preparation that you will get from the Databricks-Certified-Professional-Data-Engineer Study Materials available only from PrepPDF. Not only will you be able to pass any Databricks-Certified-Professional-Data-Engineer test, but will gets higher score, if you choose our Databricks-Certified-Professional-Data-Engineer study materials.
Databricks Certified Professional Data Engineer certification is an excellent choice for individuals who are looking to specialize in data engineering and want to demonstrate their expertise in Databricks technologies. It is also a valuable credential for companies that use Databricks and want to ensure that their employees have the necessary skills to manage and analyze large amounts of data effectively.
NEW QUESTION # 168
A data engineer, while designing a Pandas UDF to process financial time-series data with complex calculations that require maintaining state across rows within each stock symbol group, must ensure the function is efficient and scalable.
Which approach will solve the problem with minimum overhead while preserving data integrity?
Answer: A
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
The Databricks documentation recommends applyInPandas() for complex per-group operations where maintaining internal state within each group is necessary. When using applyInPandas(), Spark provides all records for each grouping key as a Pandas DataFrame to the function, allowing efficient vectorized operations with local state management. This approach ensures high performance and scalability while maintaining logical isolation between groups. In contrast, SCALAR and SCALAR_ITER UDFs operate on individual rows or batches and cannot maintain inter-row state effectively. grouped_agg UDFs are limited to computing aggregates and do not support complex multi-row transformations. Therefore, applyInPandas() is the correct and Databricks-recommended solution for stateful per-group time-series computations.
NEW QUESTION # 169
To identify the top users consuming compute resources, a data engineering team needs to monitor usage within their Databricks workspace for better resource utilization and cost control. The team decided to use Databricks system tables, available under the System catalog in Unity Catalog, to gain detailed visibility into workspace activity.
Which SQL query should the team run from the System catalog to achieve this?
A)
SELECT sku_name,
identity_metadata.created_by AS user_email,
COUNT(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10
B)
SELECT identity_metadata.run_as AS user_email,
SUM(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email
ORDER BY total_dbus DESC
LIMIT 10
C)
SELECT sku_name,
identity_metadata.created_by AS user_email,
SUM(usage_quantity * usage_unit) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10
D)
SELECT sku_name,
usage_metadata.run_name AS user_email,
SUM(usage_quantity) AS total_dbus
FROM system.billing.usage
GROUP BY user_email, sku_name
ORDER BY total_dbus DESC
LIMIT 10
Answer: A
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
The system.billing.usage table in the Unity Catalog System schema provides detailed usage metrics for each workload in the workspace. The field identity_metadata.run_as identifies the user or service principal under which the job or query executed. Summing usage_quantity provides total DBU (Databricks Unit) consumption per user. According to Databricks documentation, this table is the authoritative source for monitoring workspace cost drivers, showing compute SKU, user, and DBU consumption over time. Grouping by identity_metadata.run_as and summing usage_quantity produces the correct aggregation to determine top users. Other queries use non-existent or incorrect fields (created_by, run_name, or multiplied usage quantities), which do not reflect actual billing metrics.
NEW QUESTION # 170
A data engineer has ingested a JSON file into a table raw_table with the following schema:
1.transaction_id STRING,
2.payload ARRAY<customer_id:STRING, date:TIMESTAMP, store_id:STRING>
The data engineer wants to efficiently extract the date of each transaction into a table with the fol-lowing
schema:
1.transaction_id STRING,
2.date TIMESTAMP
Which of the following commands should the data engineer run to complete this task?
Answer: B
NEW QUESTION # 171
The data governance team is reviewing code used for deleting records for compliance with GDPR. They note the following logic is used to delete records from the Delta Lake table named users.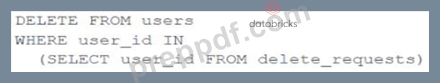
Assuming that user_id is a unique identifying key and that delete_requests contains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
Answer: C
Explanation:
The code uses the DELETE FROM command to delete records from the users table that match a condition based on a join with another table called delete_requests, which contains all users that have requested deletion. The DELETE FROM command deletes records from a Delta Lake table by creating a new version of the table that does not contain the deleted records. However, this does not guarantee that the records to be deleted are no longer accessible, because Delta Lake supports time travel, which allows querying previous versions of the table using a timestamp or version number. Therefore, files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files from physical storage. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Delete from a table" section; Databricks Documentation, under "Remove files no longer referenced by a Delta table" section.
NEW QUESTION # 172
The data science team has requested assistance in accelerating queries on free form text from user reviews.
The data is currently stored in Parquet with the below schema:
item_id INT, user_id INT, review_id INT, rating FLOAT, review STRING
The review column contains the full text of the review left by the user. Specifically, the data science team is looking to identify if any of 30 key words exist in this field.
A junior data engineer suggests converting this data to Delta Lake will improve query performance.
Which response to the junior data engineer s suggestion is correct?
Answer: D
Explanation:
Converting the data to Delta Lake may not improve query performance on free text fields with high cardinality, such as the review column. This is because Delta Lake collects statistics on the minimum and maximum values of each column, which are not very useful for filtering or skipping data on free text fields.
Moreover, Delta Lake collectsstatistics on the first 32 columns by default, which may not include the review column if the table has more columns. Therefore, the junior data engineer's suggestion is not correct. A better approach would be to use a full-text search engine, such as Elasticsearch, to index and query the review column. Alternatively, you can use natural language processing techniques, such as tokenization, stemming, and lemmatization, to preprocess the review column and create a new column with normalized terms that can be used for filtering or skipping data. References:
* Optimizations: https://docs.delta.io/latest/optimizations-oss.html
* Full-text search with Elasticsearch: https://docs.databricks.com/data/data-sources/elasticsearch.html
* Natural language processing: https://docs.databricks.com/applications/nlp/index.html
NEW QUESTION # 173
......
Databricks-Certified-Professional-Data-Engineer Reliable Test Online: https://www.preppdf.com/Databricks/Databricks-Certified-Professional-Data-Engineer-prepaway-exam-dumps.html
BONUS!!! Download part of PrepPDF Databricks-Certified-Professional-Data-Engineer dumps for free: https://drive.google.com/open?id=1qy7qHQCQ3MZeRLBOh1Qu8Q2MOBCCE3pF