The AI-200 certificate you have obtained can really prove your ability to work. Of course, our AI-200 study materials will also teach you how to improve your work efficiency. No matter how good the newcomer is, your status will not be shaken! Our AI-200 Practice Braindumps really are so powerful. If you still have concerns, you can use the free trial versions first. They are the free demos of the AI-200 exam questions for you to free download.
| Section | Objectives |
|---|---|
| Develop containerized solutions on Azure | - Implement containerized applications
|
| Connect to and consume Azure services | - Integrate Azure services
|
| Secure, monitor, troubleshoot Azure solutions | - Operate AI cloud solutions
|
| Develop AI solutions by using Azure data management services | - Work with Azure data platforms for AI workloads
|
>> Valid Microsoft AI-200 Exam Duration <<
After paying our AI-200 exam torrent successfully, buyers will receive the mails sent by our system in 5-10 minutes. Then candidates can open the links to log in and use our AI-200 test torrent to learn immediately. Because the time is of paramount importance to the examinee, everyone hope they can learn efficiently. So candidates can use our AI-200 guide questions immediately after their purchase is the great advantage of our product. The language is easy to be understood makes any learners have no obstacles. The AI-200 Test Torrent is suitable for anybody no matter he or she is in-service staff or the student, the novice or the experience people who have worked for years. The software boosts varied self-learning and self-assessment functions to check the results of the learning.
NEW QUESTION # 27
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
Drag and Drop Question
You need to configure event-driven scaling for the backend API services to meet the technical requirements.
Which settings should you use for each element? To answer, move the appropriate settings to the correct elements. You may use each setting once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.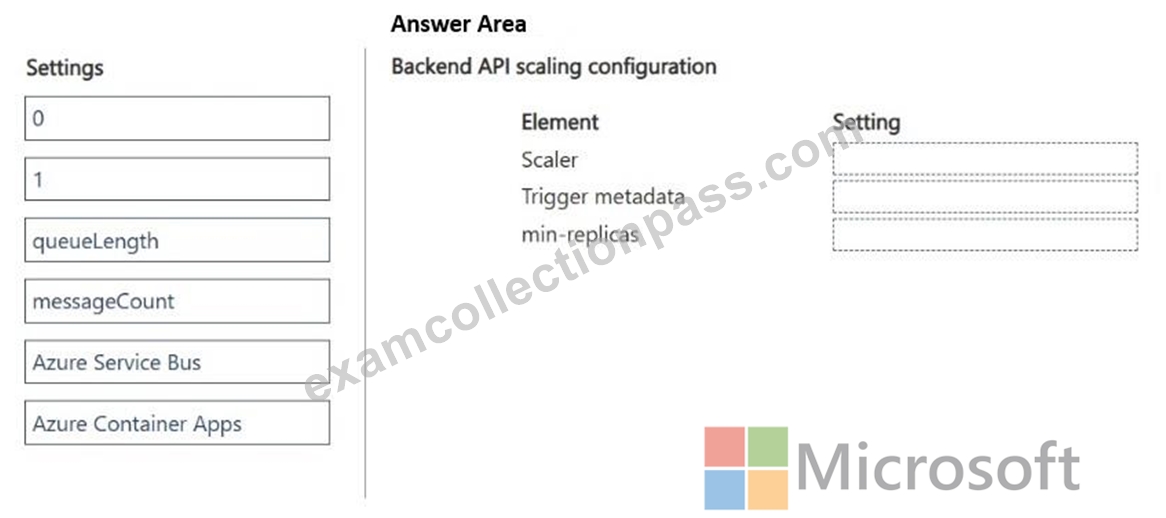
Answer:
Explanation: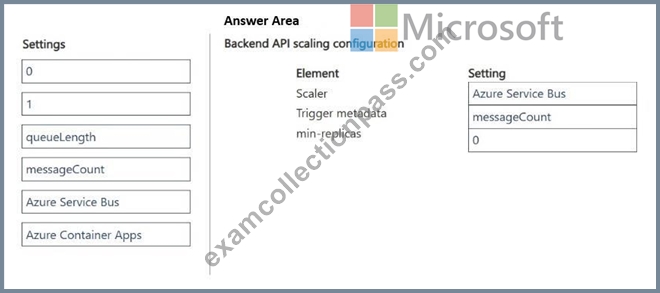
Explanation:
Scenario, technical requirements.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Box 1: Azure Service Bus
Scaler TypeType
Set the scale rule type to custom.
KEDA Scaler Name: Set the type inside the custom specification block to azure-service-bus.
Box 2: messageCount
Trigger Metadata Values
The metadata block dictates how KEDA calculates the required replica count.
Configure the following core metadata parameters:
queueName: The explicit string name of your targeted Azure Service Bus
*-> queue.messageCount: The target integer threshold of concurrent pending messages assigned per replica (e.g., 5 or 10). KEDA uses this value to scale out systematically.
activationMessageCount: Set to 1 or 0. This defines the exact metric floor required to transition the container app out of a dormant state.
namespace: The canonical name of your Service Bus namespace
Box 3: 0
Min-Replicas ConfigurationValue
Set --min-replicas to 0.
Setting this value to zero enables full serverless cost efficiency. KEDA actively handles the background polling, allowing your backend API containers to scale down completely and run zero active replicas when the Service Bus queue contains zero pending messages.
Reference:
https://oneuptime.com/blog/post/2026-02-16-how-to-set-up-keda-based-auto-scaling-with-queue-triggers-in-azure-container-apps/view
NEW QUESTION # 28
You deploy an API to Azure Container Apps.
The solution must provide the following functionality:
* Support the concurrent activation of multiple application versions.
* Allocate a specific percentage of incoming requests to a secondary version You need to configure revision behavior.
Which configurations should you use? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.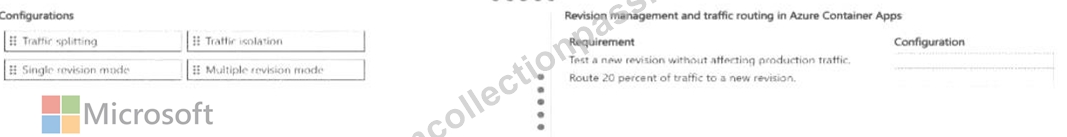
Answer:
Explanation: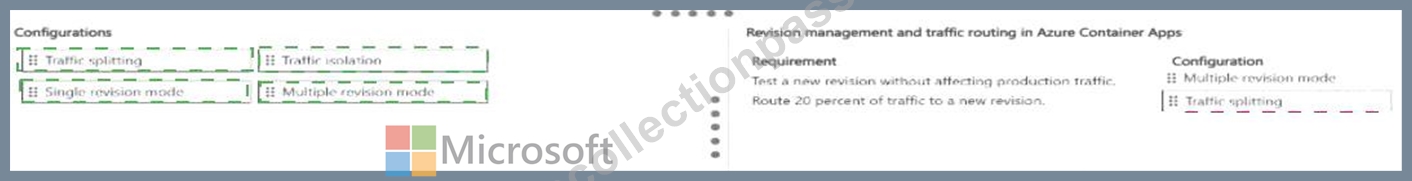
Explanation: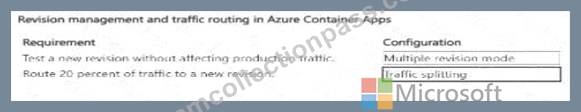
oncurrent active versions: Multiple revision mode. Route a percentage to the secondary version: Traffic splitting.
Detailed Explanation: Azure Container Apps supports side-by-side application versions through multiple revision mode. Once multiple revisions can be active, ingress traffic can be distributed by percentage across those revisions. This is the required combination for canary or controlled rollout scenarios. Single revision mode deactivates the previous revision as a new one becomes active, while traffic splitting is the specific feature that assigns a percentage of incoming requests to each active revision.
Study Guide Alignment: Containerized Azure workloads: registry builds, App Service containers, Container Apps revision/scaling behavior, and AKS deployment choices.
Official Microsoft Learn References: AI-200 Study Guide | Azure Container Apps revisions
NEW QUESTION # 29
Your team wants to track token usage, latency, and error rates for an Azure OpenAI-backed application in production, with alerting on anomalies. What should you configure?
Answer: C
Explanation:
Azure Monitor, configured via diagnostic settings on the Azure OpenAI resource, collects logs and metrics such as token consumption, latency, and errors, and supports alert rules for anomaly detection in production.
NEW QUESTION # 30
Hotspot Question
You have an Azure Service Bus namespace that contains a topic named Topic1.
You plan to create a subscription named Sub1 to Topic1. In Sub1, you plan to filter messages from Topic1 based on their system properties and apply an action that will annotate each filtered message.
You need to configure the filtering.
How should you configure the filtering? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.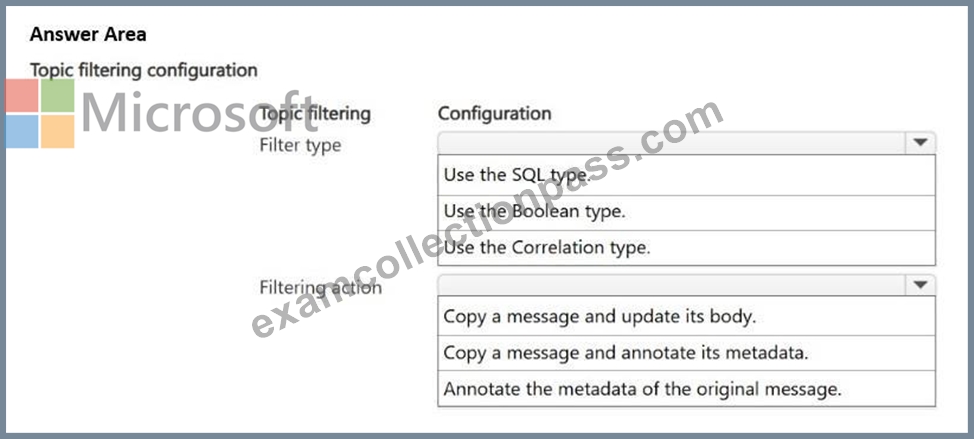
Answer:
Explanation:
Explanation:
Box 1: Use the SQL type.
To achieve this goal, you must use a SQL filter (also known as a SqlFilter) type Box 2: Copy a message and annotate its metadata.
The correct filtering action to use is to copy a message and annotate its metadata.
When an action is applied (such as setting a new property or modifying an existing one via SQL filter actions), Azure Service Bus creates a copy of the inbound message for the subscription and annotates the copy's metadata.
Reference:
https://turbo360.com/blog/azure-service-bus-topic-filter
NEW QUESTION # 31
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You plan to deploy a container to an Azure App Service API app named api1. You host the source code for api1 in a GitHub repository. The container uses the API key at runtime to connect to a backend service.
The container must be able to retrieve the API key at runtime without exposing it in the source repository or Git commit history.
You need to ensure that the API key remains outside of Git commit history and is available to the container at runtime.
Solution: Store the API key as an App Service application setting configured through the Azure Portal.
Does the solution meet the goal?
Answer: A
Explanation:
Correct:
* Store the API key in Azure Key Vault and reference it from an App Service application setting.
Storing the API key in Azure Key Vault and referencing it via App Service application settings is the recommended, secure approach. This strategy completely removes sensitive credentials from your GitHub repository and Git commit history while injecting them safely into your container environment at runtime.
Incorrect:
* Embed the API key as a hardcoded environment variable in the Dockerfile.
* Store the API key as a GitHub repository secret.
* Store the API key as an App Service application setting configured through the Azure Portal.
Reference:
https://www.qservicesit.com/full-stack-applications-on-azure
NEW QUESTION # 32
......
ExamcollectionPass makes your AI-200 exam preparation easy with it various quality features. Our AI-200 exam braindumps come with 100% passing and refund guarantee. ExamcollectionPass is dedicated to your accomplishment, hence assures you successful in AI-200 Certification exam on the first try. If for any reason, a candidate fails in AI-200 exam then he will be refunded his money after the refund process. Also, we offer one year free updates to our AI-200 Exam esteemed user, these updates are applicable to your account right from the date of purchase. 24/7 customer support is favorable to candidates who can email us if they find any ambiguity in the AI-200 exam dumps, our support will merely reply to your all Developing AI Cloud Solutions on Azure exam product related queries.
AI-200 Dumps Collection: https://www.examcollectionpass.com/Microsoft/AI-200-practice-exam-dumps.html