Through continuous development and growth of the IT industry in the past few years, AI-200 exam has become a milestone in the Microsoft exam, it can help you to become a IT professional. There are hundreds of online resources to provide the Microsoft AI-200 questions. Why do most people to choose VCE4Dumps? Because VCE4Dumps has a huge IT elite team, In order to ensure you accessibility through the Microsoft AI-200 Certification Exam, they focus on the study of Microsoft AI-200 exam. VCE4Dumps ensure that the first time you try to obtain certification of Microsoft AI-200 exam. VCE4Dumps will stand with you, with you through thick and thin.
| Section | Objectives |
|---|---|
| Topic 1: Implement and monitor AI workloads | - Monitor performance and troubleshoot issues - Deploy AI models and services |
| Topic 2: Plan and manage Azure AI solutions | - Select appropriate Azure AI services - Plan security and compliance requirements - Monitor and optimize AI solutions |
| Topic 3: Implement Azure AI solutions | - Implement computer vision solutions - Implement knowledge mining with Azure AI Search - Implement generative AI solutions using Azure OpenAI - Implement natural language processing solutions |
The VCE4Dumps is committed to making the Microsoft AI-200 certification exam preparation simple, smart, and successful. To achieve this objective VCE4Dumps is offering top-notch and real AI-200 exam questions in three different formats. The names of these Developing AI Cloud Solutions on Azure (AI-200) exam questions formats are PDF files, desktop practice test software, and web-based AI-200 practice test software.
NEW QUESTION # 20
Drag and Drop Question
You are developing a serverless Java application on Azure. You create a new Azure Key Vault to work with secrets from a new Azure Functions application.
The application must meet the following requirements:
- Reference the Azure Key Vault without requiring any changes to the
Java code.
- Dynamically add and remove instances of the Azure Functions host
based on the number of incoming application events.
- Ensure that instances are perpetually warm to avoid any cold starts.
- Connect to a VNet.
- Authentication to the Azure Key Vault instance must be removed if the Azure Functions application is deleted.
You need to grant the Azure Functions application access to the Azure Key Vault.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.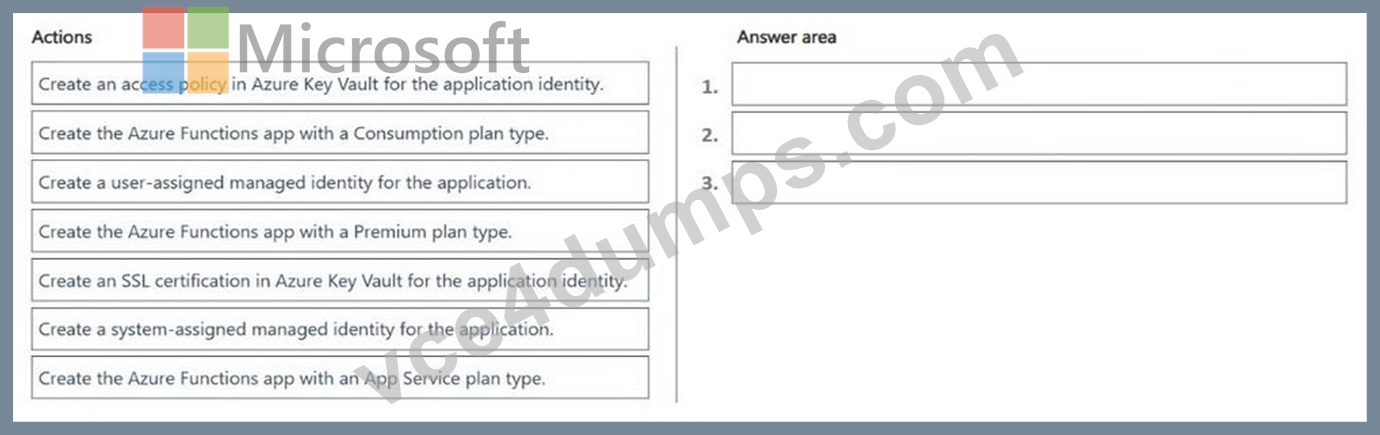
Answer:
Explanation: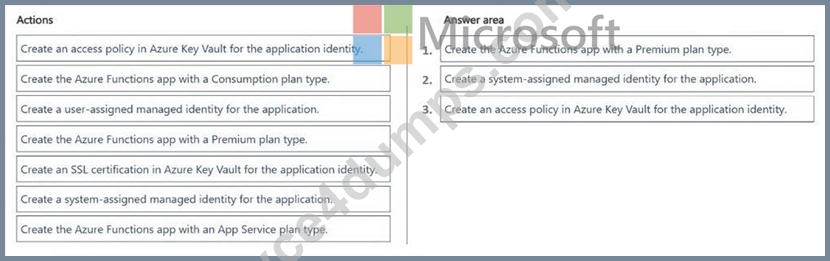
Explanation:
Step 1: Create the Azure Functions app with a Premium plan type
Perpetually Warm & VNet: The Premium plan type is the only serverless-scale hosting option that satisfies requirement 3 (keeping instances warm to eliminate cold starts) and requirement 4 (native regional VNet integration). The Consumption plan type does not keep instances warm and does not support VNet injection.
Event-Driven Scaling: It fulfills requirement 2 by dynamically adding and removing host instances using the event-driven scale controller.
Step 2: Create a system-assigned managed identity for the application
Lifecycle Coupling: It directly satisfies requirement 5. A system-assigned managed identity is tied strictly to the lifecycle of the Azure Functions resource. If the Functions application is deleted, Azure automatically removes the identity and its authentication token, ensuring that access to the Key Vault is immediately revoked. A user-assigned identity exists as an independent resource and would persist after the application's deletion.
Step 3: Create an access policy in Azure Key Vault for the application identity Granting Permissions: This step completes the access requirements. By adding an access policy (or an Azure RBAC role assignment) in Azure Key Vault specifically for the created system- assigned managed identity, you grant the runtime environment the necessary permissions to retrieve secrets.
No Code Changes: Combining the managed identity with an App Setting configured as an Azure Key Vault Reference allows the Functions platform to fetch secrets automatically at runtime, keeping your Java source code unchanged Reference:
https://learn.microsoft.com/en-us/azure/azure-functions/functions-best-practices
NEW QUESTION # 21
You have an Azure web app that uses Azure Cosmos DB as a data store. You create a Cosmos DB container by running the following PowerShell script: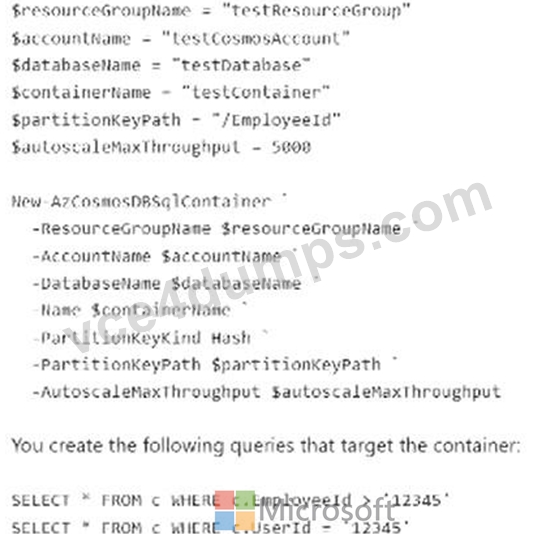
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.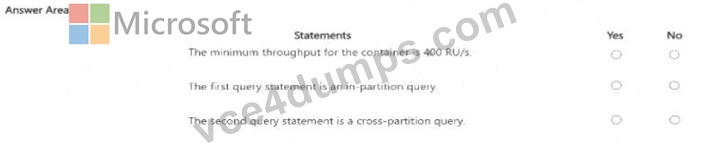
Answer:
Explanation:
Explanation: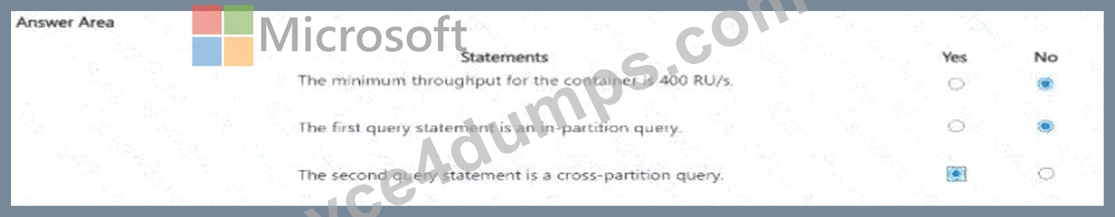
The question maps directly to the AI-200 objective "Develop AI solutions by using Azure Cosmos DB for NoSQL," which includes running queries and optimizing query performance and Request Unit (RU) consumption.
Statement 1: No - The minimum throughput is not 400 RU/s.
The PowerShell command provisions the container with:
-AutoscaleMaxThroughput 5000
Azure Cosmos DB autoscale operates between approximately 10% and 100% of the configured maximum throughput . Microsoft documentation specifically gives the example of an autoscale container provisioned with 5,000 RU/s scaling between 500 RU/s and 5,000 RU/s . Therefore, for this container, the minimum operating autoscale throughput is 500 RU/s , not 400 RU/s.
Therefore:
"The minimum throughput for the container is 400 RU/s." # No
Statement 2: No - The first query is not an in-partition query.
The container uses:
/EmployeeId
as its partition key.
The first query is:
SELECT * FROM c WHERE c.EmployeeId > ' 12345 '
Although the query references the partition key, it uses a range predicate ( > ) , not an equality predicate.
Microsoft explicitly states that a range filter on a partition key is not scoped to a single physical partition .
To qualify as an in-partition query, the filter must identify the applicable partition, typically through an equality predicate such as:
WHERE c.EmployeeId = ' 12345 '
Microsoft ' s documentation provides essentially the same example: a query using DeviceId > ... against a container partitioned by DeviceId is not an in-partition query .
Therefore:
"The first query statement is an in-partition query." # No
Statement 3: Yes - The second query is a cross-partition query.
The second query is:
SELECT * FROM c WHERE c.UserId = ' 12345 '
The container ' s partition key is /EmployeeId, not /UserId. Because the query contains no filter on the partition key , Azure Cosmos DB cannot route it to one logical partition. It must fan out the query across the applicable physical partitions and combine the results.
Microsoft describes this behavior directly: when a query does not contain a filter on the partition key, it must execute across the partitions.
Therefore:
"The second query statement is a cross-partition query." # Yes
NEW QUESTION # 22
You are implementing semantic retrieval in Redis.
The solution must support low-latency, approximate nearest neighbor (ANN) vector similarity search for large-scale AI retrieval workloads.
You need to select the appropriate vector schema settings.
Which configuration values should you select? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: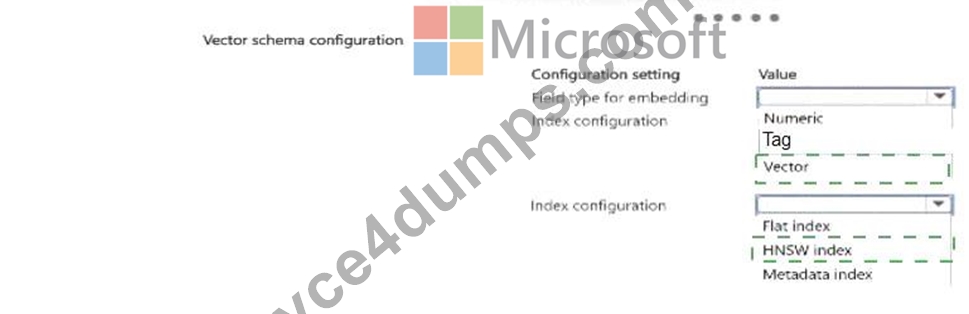
Explanation: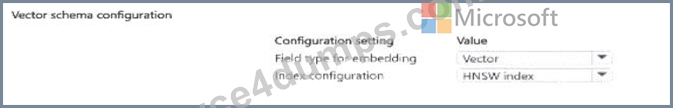
NEW QUESTION # 23
Drag and Drop Question
A recommendation system stores 3 million embeddings in Azure Database for PostgreSQL.
During peak hours, P95 similarity-query latency increases, and the cache hit ratio drops significantly.
You suspect that the vector index working set no longer fits in memory, resulting in more disk reads.
You need to scale server resources and validate the outcome.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
Answer:
Explanation: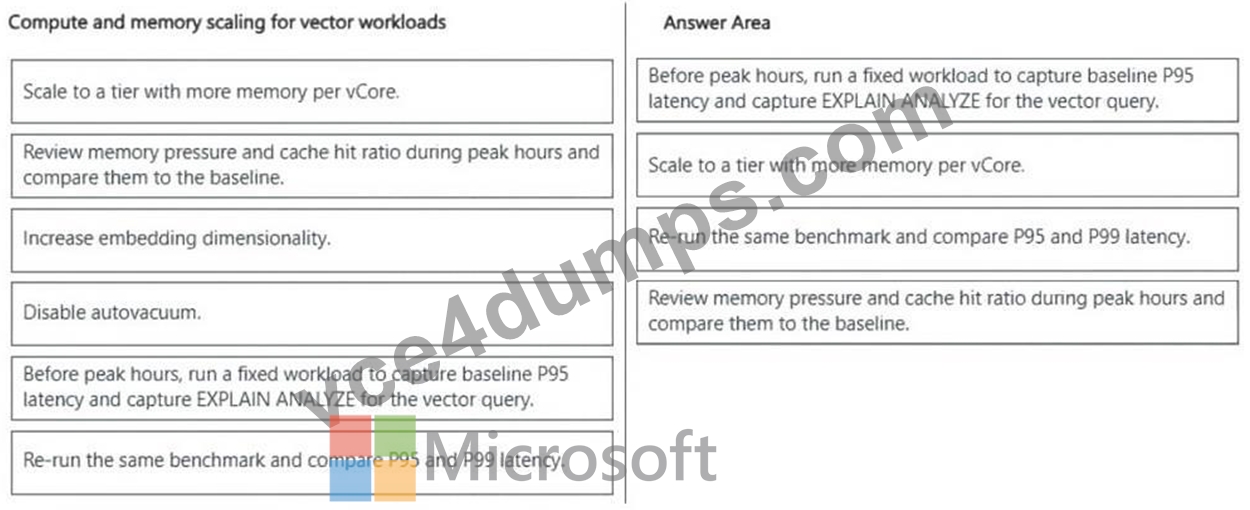
Explanation:
Step 1: Before peak hours, run a fixed workload to capture baseline P95 latency and capture EXPLAIN ANALYZE for the vector query Establishing a baseline is crucial for performance tuning. Running EXPLAIN ANALYZE provides deep insight into whether the query is actually using the vector index (like HNSW or IVFFlat) or falling back to a slow sequential scan.
Step 2: Scale to a tier with more memory per vCore
Since the problem states that the vector index working set no longer fits in memory, scaling to a tier with higher memory (such as Memory-Optimized tiers) directly solves the root cause by allowing the RAM to fully cache the vector index, eliminating slow disk reads.
Step 3: Re-run the same benchmark and compare P95 and P99 latency
To validate the outcome of your scaling operations, you must run the identical benchmark workload and compare high-percentile latencies (P95, P99) against your baseline to prove the bottleneck was resolved.
Step 4: Review memory pressure and cache hit ratio during peak hours and compare them to the baseline This step confirms the success of the resource scaling. A successful remediation will show a significantly increased cache hit ratio and reduced memory pressure/disk I/O compared to the baseline metrics.
Reference:
https://www.pgedge.com/blog/ai-features-in-pgadmin-ai-insights-for-explain-plans
NEW QUESTION # 24
A RAG application ' s retrieval step is returning documents that are topically related but not precisely relevant to the user ' s question.
You need to improve retrieval precision without retraining any model.
What should you do?
Answer: A
Explanation:
Enable semantic ranking in Azure AI Search . Semantic ranking is a query-time secondary re-ranking stage that evaluates the initial candidate results using Microsoft language-understanding models and promotes documents that are more semantically aligned with the user ' s actual query intent. It can operate over BM25 results, hybrid results, and the textual content associated with vector-search results.
This directly addresses the stated problem. Vector similarity retrieval often has strong recall but can return passages that are broadly related rather than specifically useful for answering the question. Microsoft ' s RAG guidance explains that reranking improves precision by taking the retrieved candidate set and reordering it so that the most query-relevant chunks are placed first. This reduces irrelevant context passed to the generation model and improves grounding quality without retraining either the embedding model or the LLM.
Increasing embedding dimensionality alone does not guarantee better relevance. Disabling vector search sacrifices semantic retrieval capability, while reducing the index size arbitrarily removes potentially useful content rather than improving ranking quality.
Therefore, semantic re-ranking is the correct precision-improvement mechanism .
Study Guide references: Azure AI Search # semantic ranker; RAG information retrieval; hybrid/vector search; secondary ranking; relevance optimization.
NEW QUESTION # 25
......
As sometimes new domains and topics are added to the VCE4Dumps Developing AI Cloud Solutions on Azure exam syllabus, you’ll be able to get free updates of Microsoft AI-200 dumps for 365 days that cover all the latest exam topics. We provide customers instant access to all Microsoft Exams Dumps right after making the payment. Our customer support team is available 24/7 to assist you with all your issues regarding Microsoft AI-200 Exam Preparation material.
Certification AI-200 Cost: https://www.vce4dumps.com/AI-200-valid-torrent.html