P.S. Free & New AI-300 dumps are available on Google Drive shared by ActualPDF: https://drive.google.com/open?id=1yLaGPBL_o2syB5lmzfBEo5Xu_EXI5UTq
Most people define AI-300 study tool as regular books and imagine that the more you buy, the higher your grade may be. It is true this kind of view make sense to some extent. However, our AI-300 real questions are high efficient priced with reasonable amount, acceptable to exam candidates around the world. Our AI-300 practice materials comprise of a number of academic questions for your practice, which are interlinked and helpful for your exam. Unlike those untenable practice materials in the market, our AI-300 practice materials are highly utilitarian for their accuracy of the real exam because all content are compiled by proficient experts who engaged in this area more than ten years. It is our unswerving will to help you pass the exam by AI-300 study tool smoothly.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement machine learning model lifecycle and operations | 25–30% | - Orchestrate model training and experimentation
|
| Topic 2: Design and implement an MLOps infrastructure | 15–20% | - Implement infrastructure as code for Machine Learning
|
| Topic 3: Design and implement a GenAIOps infrastructure | 20–25% | - Set up Microsoft Foundry environment
|
| Topic 4: Implement generative AI quality assurance and observability | 10–15% | - Evaluate and test generative AI applications
|
| Topic 5: Optimize generative AI systems and model performance | 15–20% | - Optimize model selection and configuration
|
You can enter a better company and improve your salary if you have certificate in this field. AI-300 training materials of us will help you obtain the certificate successfully. We have a professional team to collect the latest information for the exam, and if you choose us, you can know the latest information timely. In addition, we provide you with free update for 365 days after payment for AI-300 Exam Materials, and the latest version will be sent to your email address automatically.
NEW QUESTION # 151
A team validates a generative AI application that produces free-form text responses by using Microsoft Foundry SDK.
The evaluation dataset is registered in the Microsoft Foundry environment.
You need to configure a safety evaluation pipeline that reliably evaluates model outputs for harmful content.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.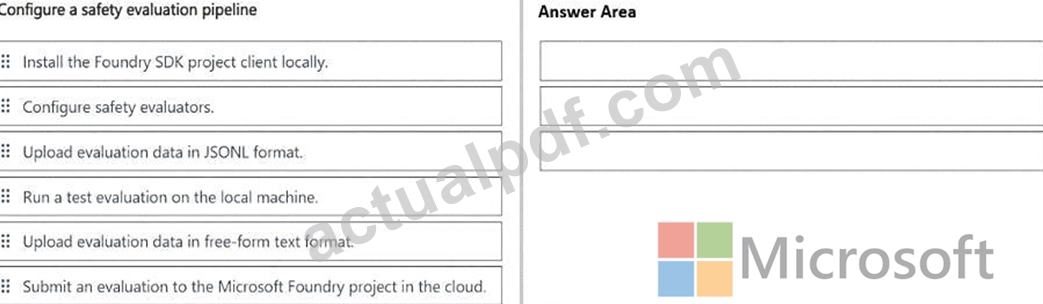
Answer:
Explanation: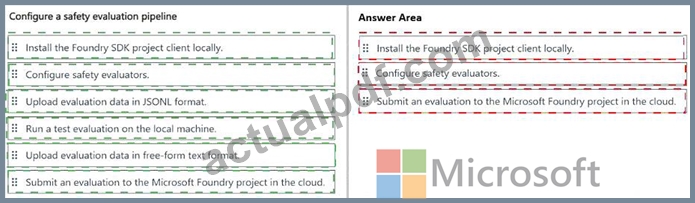
Explanation:
Correct sequence:
* Install the Foundry SDK project client locally.
* Configure safety evaluators.
* Submit an evaluation to the Microsoft Foundry project in the cloud.
The first step is to install and configure the Microsoft Foundry SDK project client . Microsoft documents the Foundry project client as the programmatic entry point for authenticating to a Foundry project and accessing its evaluation capabilities. The client typically uses DefaultAzureCredential, avoiding embedded credentials while enabling access to project resources.
Next, configure the safety evaluators that correspond to the risks that must be measured. Microsoft Foundry provides built-in safety evaluators for categories including Violence, Sexual content, Self-harm, and Hate
/Unfairness . These evaluators analyze generated responses and return structured safety assessments rather than relying on subjective manual review.
Finally, submit the evaluation to the Microsoft Foundry project in the cloud . Current Foundry evaluation workflows define the evaluator configuration, create an evaluation, and start an evaluation run in the project.
Results are persisted in Foundry for comparison, auditing, and CI/CD quality gates.
Uploading evaluation data is unnecessary because the scenario explicitly states that the dataset is already registered . Microsoft documentation specifically instructs users to skip dataset upload when a registered dataset already exists. Free-form text upload is also inappropriate because structured evaluation datasets use supported schemas such as JSONL or CSV.
Study Guide Reference: Implement generative AI quality assurance and observability - Foundry evaluations, safety evaluators, evaluation datasets, cloud evaluation runs, and harmful-content measurement.
NEW QUESTION # 152
You train models on GPU-enabled clusters but deploy them on CPU-based endpoints. Recently, inference failures occur due to incompatible dependencies. What should you do to ensure consistency?
Answer: D
Explanation:
Defining and reusing environment configurations ensures that dependencies remain consistent between training and inference. This prevents runtime errors caused by mismatched libraries.
Using identical compute resources is unnecessary and inefficient, as consistency depends on environment configuration rather than hardware.
NEW QUESTION # 153
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals.
You have an Azure Machine Learning workspace. You connect to a terminal session from the Notebooks page in Azure Machine Learning studio.
You plan to add a new Jupyter kernel that will be accessible from the same terminal session.
You need to perform the task that must be completed before you can add the new kernel.
Solution: Delete the Python 3.6 - AzureML kernel.
Does the solution meet the goal?
Answer: B
Explanation:
No. Removing the existing Python 3.6 - AzureML kernel is not a prerequisite for adding a new kernel. Azure Machine Learning supports multiple installed Jupyter kernels on the same compute instance, and notebooks can select among those kernels without requiring one existing kernel to be removed first. Microsoft states that the notebook environment automatically discovers all Jupyter kernels installed on the connected compute instance.
The supported new-kernel workflow begins by creating a separate environment, for example with conda create --name newenv, and activating it. The required pip and ipykernel packages are then installed in the environment before registering it with Jupyter by using python -m ipykernel install --user --name newenv.
Deleting an existing AzureML kernel provides no technical benefit to that workflow. Microsoft also explicitly cautions users not to delete Conda environments or Jupyter kernels they did not create , because doing so can interfere with built-in Jupyter/JupyterLab functionality on the compute instance.
Therefore, the existing Python 3.6 kernel should remain untouched; the new kernel should be installed alongside it in its own environment.
Study Guide Reference: Design and implement an MLOps infrastructure - Jupyter kernel management, Conda environments, Azure Machine Learning compute instances, and development environment isolation.
NEW QUESTION # 154
You have an Azure Machine Learning workspace.
You have the following code: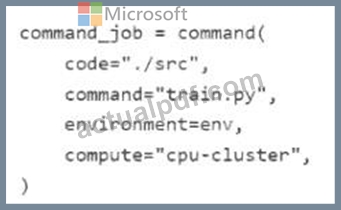
You plan to rely on serverless compute to train a model by using Azure Machine Learning Python SDK v2.
The serverless compute must use a designated number of nodes of a specific virtual machine type.
You need to modify the code to run the training job according to the plan.
How should you modify the command object? To answer, select the appropriate oations in the answer area.
NOTE: Each correct selection is worth one point.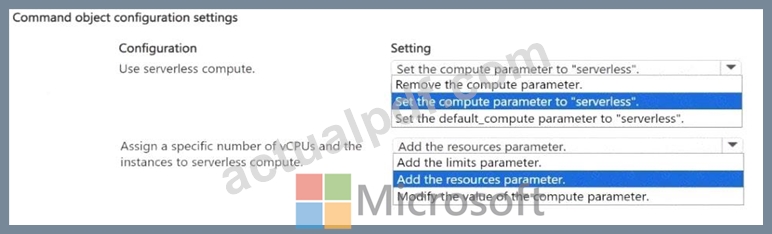
Answer:
Explanation: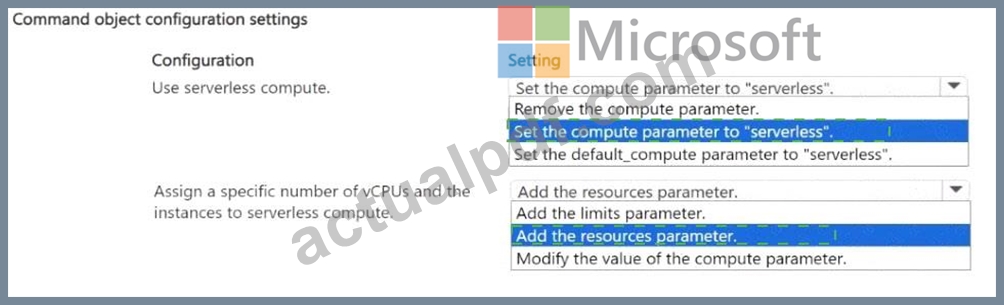
Explanation: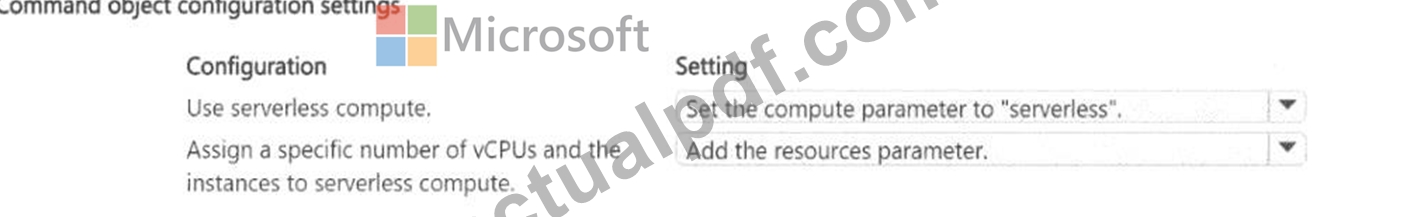
NEW QUESTION # 155
You run Azure Machine Learning training experiments. The training scripts directory contains 100 files that includes a file named .amlignore. The directory also contains subdirectories named ./outputs and ./logs.
There are 20 files in the training scripts directory that must be excluded from the snapshot to the compute targets. You create a file named .gitignore in the root of the directory. You add the names of the 20 files to the .gitignore file. These 20 files continue to be copied to the compute targets.
You need to exclude the 20 files.
What should you do?
Answer: B
Explanation:
To exclude the 20 files from the training snapshot, you must add the file names to the .amlignore file located in the root of your training scripts directory.
Why the Files Are Still Copying
Azure Machine Learning training experiments use a specific order of precedence when creating a directory snapshot for compute targets:
.amlignore takes absolute priority: If an .amlignore file exists in the directory, Azure ML only respects the rules inside it. It completely ignores any .gitignore file present.
.gitignore is a fallback: Azure ML only respects .gitignore rules if an .amlignore file does not exist in the directory. Because you have both files, the .gitignore file is being completely bypassed.
Reference:
https://learn.microsoft.com/en-us/python/api/azureml-core/azureml.core.experiment.experiment
NEW QUESTION # 156
......
We provide you the free download and tryout of our AI-300 study tool before your purchase our product and we provide the demo of the product to let the client know our product fully. After you visit the pages of our AI-300 test torrent on the websites, you can know the characteristics and merits of the AI-300 Guide Torrent. In the pages of our product on the website, you can find the details and guarantee and the contact method, the evaluations of the client on our AI-300 test torrent and other information about our AI-300 exam questions. So it is very convenient for you.
AI-300 Valid Test Registration: https://www.actualpdf.com/AI-300_exam-dumps.html
DOWNLOAD the newest ActualPDF AI-300 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1yLaGPBL_o2syB5lmzfBEo5Xu_EXI5UTq