大量の時間と金銭をかかるのに比べて、正しい仕方は肝心なことです。もしあなたはMicrosoft AI-200試験に準備しているなら、あんたのための整理される備考資料はあなたにとって最善のオプションです。我々の目標はあなたに試験にうまく合格させることです。弊社の誠意を信じてもらいたいし、Microsoft AI-200試験2成功するのを祈って願います。
| Section | Weight | Objectives |
|---|---|---|
| Develop containerized AI solutions on Azure | 25% | - Monitor and troubleshoot containerized workloads
|
| Integrate backend services and build event-driven architectures | 25% | - Implement messaging and event systems
|
| Develop AI solutions using Azure data services | 30% | - Implement vector-enabled databases
|
| Secure, monitor, and optimize AI solutions | 20% | - Manage security and configuration
|
主要な環境では、人々はより多くの仕事のプレッシャーに直面しています。そのため、彼らはMicrosoft認証を一般の群れよりも高めたいと考えています。有効で効率的なAI-200ガイドトレントを選択する方法は、ほとんどの候補者が懸念する可能性のある重要なトピックです。だから今、それは正しいです、あなたは私たちのところに来ます。当社は、特にMicrosoft認定試験に関するこの分野の高品質なAI-200試験問題で有名です。試験のためにAI-200学習教材を実践している数千人の受験者に受け入れられています。
質問 # 138
You are creating a hazard notification system that has a single signaling server which triggers audio and visual alarms to start and stop.
You implement Azure Service Bus to publish alarms, each alarm controller uses Azure Service Bus to receive alarm signals as part of a transaction Alarm events must be recorded for audit purposes Each transaction record must include information about the alarm type that was activated.
You need to implement a reply-trail auditing solution
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
正解:A、F
解説:
Detailed Explanation: For a multiplexed request/reply pattern, ReplyToSessionId on the request tells the responder which SessionId to place on the reply, so carrying the request SessionId into ReplyToSessionId provides the reply-session routing context. For correlation, the standard request/reply pattern copies the original request MessageId into the reply CorrelationId. SequenceNumber and DeliveryCount are broker- managed delivery metadata and are not writable application correlation fields, so they cannot be used as the proposed audit-link mechanism.
Study Guide Alignment: Azure service integration: Service Bus, Event Grid, Azure Functions triggers
/bindings, and event-driven processing.
Official Microsoft Learn References: AI-200 Study Guide | Service Bus messages, routing, and correlation | Service Bus message sessions
質問 # 139
Case Study 2 - Proseware Inc.
Background
Proseware Inc. develops AI-powered knowledge management solutions for enterprise customers.
The company is modernizing its platform to support semantic search, intelligent document retrieval, and real-time partner integrations.
The engineering team uses Python and Azure SDKs. The architecture is being redesigned to support containerized microservices, vector search workloads, and serverless backend processing.
Planned Application Architecture
Microservices are containerized by using Docker.
Code for containerized microservices and Azure Function apps is developed locally but stored in a GitHub repository.
Custom images for containerized microservices are stored in Azure Container Registry (ACR).
Base images are stored in Docker Hub. Custom images must be rebuilt automatically whenever their base images are updated.
Azure Cosmos DB for NoSQL stores documents, metadata, and vector embeddings.
Azure Functions generate vector embeddings of Azure Cosmos DB for NoSQL-hosted documents and send messages to Service Bus to trigger search index updates.
Azure Container Apps (ACA) apps host backend API services that provide semantic search across Azure Cosmos DB for NoSQL documents. API services process Service Bus messages and update search indexes.
Azure Kubernetes Service (AKS) processes batch vector embedding regeneration for existing Azure Cosmos DB for NoSQL documents (whenever the embedding model is changed).
An extranet-facing containerized webhook allows business partners to submit documents to be processed by internal AI workflows for semantic search and retrieval.
Monitoring
Telemetry generated by Azure resources is sent to Azure Monitor.
A Log Analytics workspace is used to collect ACA apps logs, AKS container logs, and Azure Functions apps logs.
Monitoring of Azure Functions is currently implemented by using Azure Application Insights SDK instrumentation.
Business Requirements
Embeddings for new or updated Azure Cosmos DB for NoSQL-hosted documents must be automatically generated.
Backend API services must scale automatically during business hours.
Cold start delay of backend APIs must be minimized.
Secrets must be stored outside of container images.
Developers must be able to correlate telemetry across Azure Functions hosts and apps.
All tracing must be implemented by using OpenTelemetry SDK instrumentation.
Development efforts must be minimized.
Technical Requirements
Container images must be built automatically and validated before code updates are merged into the main branch.
Image build automation must run inside the Azure Container Registry, eliminating dependency on local developer machines and external build services.
Dependency of image builds on local developer machines must be eliminated.
Event-driven scaling in ACA must occur based on the number of pending messages in the Azure Service Bus queue.
Azure Cosmos DB for NoSQL RU consumption must be minimized.
Vector similarity search must use embeddings stored in Azure Cosmos DB for NoSQL.
The partner-facing containerized webhook service must run on Azure App Service.
Secrets must NOT be stored in container images, source control, or application configuration directly. They must be accessed securely at runtime.
All secrets must be stored centrally in Azure Key Vault and accessed at runtime through a managed identity.
Azure App Service must supply secrets at runtime without relying on external services.
Resources and workloads must be deployed by using Bicep templates through an automated, version-controlled pipeline. Local and command-line deployments must be eliminated to ensure repeatable, auditable deployments.
Known Issues
RU consumption spikes during vector similarity queries.
You need to address the known issue resulting from vector similarity queries.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
正解:A、B
解説:
Known Issues: RU consumption spikes during vector similarity queries.
To address the RU (Request Unit) consumption spikes during vector similarity queries in Azure Cosmos DB, you should perform the following two steps:
Modify the indexing precision of the vector fields
Change the vector index type from flat to quantizedFlat or diskANN
Indexing Precision Tuning: Modifying parameters like vector quantization (e.g., configuring quantizedByteSize) alters the size and precision of the stored vector elements. Lowering the precision decreases memory usage and index size, allowing faster searches that consume far fewer RUs at the expense of marginal recall accuracy.
Index Type Modification: A standard flat index conducts a brute-force k-nearest neighbors (kNN) exact search across every document. This requires vast computational overhead and causes RU spikes as your dataset grows. Transitioning to quantizedFlat or diskANN leverages compression techniques and advanced graph-traversal algorithms to perform approximate nearest neighbor (ANN) searches, dropping query latency and compute costs significantly.
Reference:
https://learn.microsoft.com/en-us/azure/cosmos-db/gen-ai/vector-search-performance-tips
質問 # 140
You need to add a custom voice that matches your company's brand for a text-to-speech feature, distinct from any standard neural voice. What should you use?
正解:C
解説:
Custom Neural Voice lets you train a unique synthetic voice from recorded voice samples, producing a brand-specific voice rather than using one of the standard prebuilt neural voices.
質問 # 141
A semantic search application queries Azure Database for PostgreSQL and stores document embeddings and metadata in a table with the following columns:
* embedding (pgvector)
* department
* created_at
The application must return the top five most similar documents for a given query embedding only from the finance department. You need to implement semantic retrieval with metadata filtering.
Which query components should you select? To answer, move the appropriate query components to the correct requirements. You may use each query component once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.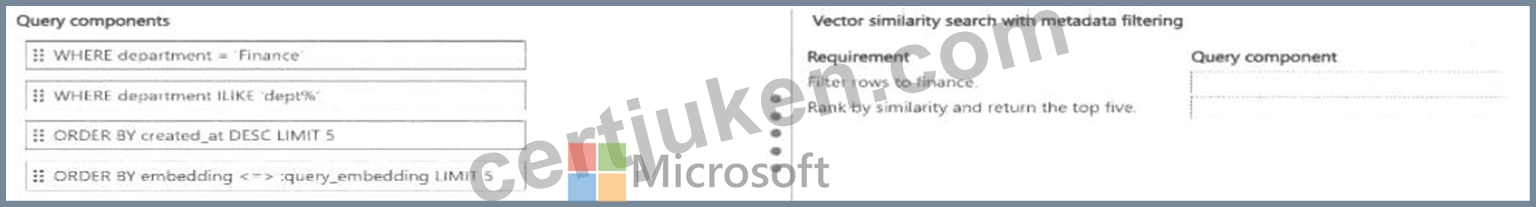
正解:
解説: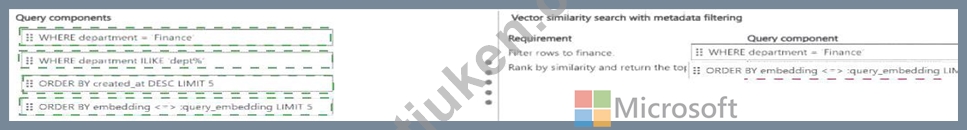
Explanation: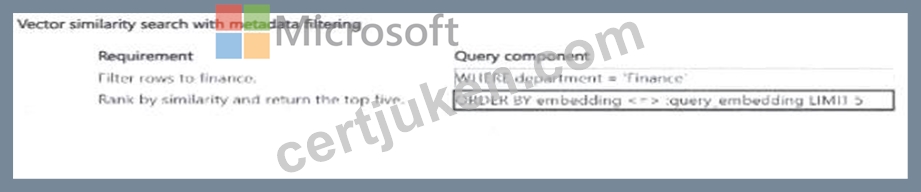
Verified Answer: Filter: `WHERE department = ' finance ' `. Rank/top five: `ORDER BY embedding < = > query_embedding LIMIT 5`.
Detailed Explanation: The metadata predicate must restrict the candidate rows to the Finance department, so the `WHERE department = ' finance ' ` component supplies the required filter. The pgvector cosine-distance operator ` < = > ` orders rows by vector distance to the supplied query embedding, and `LIMIT 5` keeps only the five nearest matches. Ordering by creation date would rank recency rather than semantic similarity, and a wildcard department filter would not satisfy the Finance-only requirement.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Vector similarity search with Azure PostgreSQL
質問 # 142
An AI platform uses App Configuration for feature flags and endpoint routing.
The platform stores secrets alongside configuration data and does NOT support dynamic refresh.
The solution must support dynamic configuration refresh while ensuring that secrets are NOT stored in App Configuration.
You need to enable secure dynamic configuration management for the platform.
Which three actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
正解:A、B、C
解説:
[A]
Setting up a cache expiration or polling interval enables the application to detect configuration changes periodically without restarting, fulfilling the requirement for dynamic refresh.
[B]
Using Azure Managed Identities eliminates hardcoded credentials. It allows your application to securely authenticate to both Azure App Configuration and Azure Key Vault.
[C]
Moving API keys to Azure Key Vault adheres to security best practices. Azure App Configuration can reference these secrets securely using Key Vault references, ensuring secrets are never stored as plaintext in the configuration store.
Reference:
https://smartbridge.com/azure-ai-foundry-enterprise-guide-2/
質問 # 143
......
Microsoft製品を購入する前に、無料でダウンロードして試用できるため、AI-200テスト準備を十分に理解できます。このように、クライアントは、ウェブサイト上で私たちのDeveloping AI Cloud Solutions on Azure試験問題のページを訪問することができます。 したがって、クライアントはAI-200試験問題をよく理解し、AI-200試験問題の品質を確認したので、AI-200トレーニングガイドを購入するかどうかを決定できます。 CertJukenお客様に最高のAI-200学習ガイドを提供し、お客様に満足していただけるようにします。
AI-200試験問題: https://www.certjuken.com/AI-200-exam.html