Efficient DP-750 Pdf Files - Find Shortcut to Pass DP-750 Exam

It is similar to the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) desktop-based exam simulation software, but it requires an active internet. No extra plugins or software installations are required to take the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) web-based practice test. Every browser such as Chrome, Mozilla Firefox, MS Edge, Internet Explorer, Safari, and Opera supports this format of DP-750 mock exam.
| Section | Weight | Objectives |
|---|
| Topic 1: Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
- 1. Connect to Azure Data Lake Storage, Azure Data Factory, Microsoft Entra ID
- 2. Configure monitoring with Azure Monitor and diagnostic settings
- Select and configure compute resources
- 1. Configure cluster policies, instance pools, and libraries
- 2. Choose compute types: serverless, job compute, SQL warehouse, classic compute
- 3. Manage workspace settings, permissions, and networking
|
| Topic 2: Prepare and process data | 30–35% | - Optimize and manage data storage
- 1. Handle structured, semi-structured, and unstructured data
- 2. Implement lakehouse architecture and manage table versions
- 3. Optimize Delta tables: partitioning, Z-ordering, vacuum, optimize
- Ingest and transform data
- 1. Implement schema enforcement, schema drift, and slowly changing dimensions
- 2. Transform using Spark SQL, PySpark, Scala, and Delta Lake
- 3. Ingest batch and streaming data from multiple sources
|
| Topic 3: Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
- 1. Apply SDLC practices and version control
- 2. Monitor performance, logs, and execution metrics
- 3. Troubleshoot failures, repair and restart jobs
- Build and orchestrate pipelines
- 1. Implement CI/CD with Git, Databricks Asset Bundles, CLI, and APIs
- 2. Design and implement Lakeflow Spark Declarative Pipelines
- 3. Configure Lakeflow Jobs: schedules, triggers, alerts, retries
|
| Topic 4: Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
- 1. Set up external locations and storage credentials
- 2. Grant and revoke permissions, manage groups and service principals
- Implement data governance and security
- 1. Configure access control: row-level, column-level, attribute-based security
- 2. Manage catalogs, schemas, tables, views, and volumes
- 3. Enforce data quality, lineage, and auditing
|
>> DP-750 Pdf Files <<
100% Pass Quiz 2026 Microsoft Latest DP-750: Implementing Data Engineering Solutions Using Azure Databricks Pdf Files
Though there are three different versions of our DP-750 practice guide to cater to all needs of our worthy customers: the PDF, Software and APP online. I love the Software version the most. The software version of our DP-750 exam questions can be used in the Windows system, which is designed by the experts from our company. The functions of the software version are very special. For example, the software version of our DP-750 Learning Engine can simulate the real exam environment.
Microsoft Implementing Data Engineering Solutions Using Azure Databricks Sample Questions (Q53-Q58):
NEW QUESTION # 53
Hotspot Question
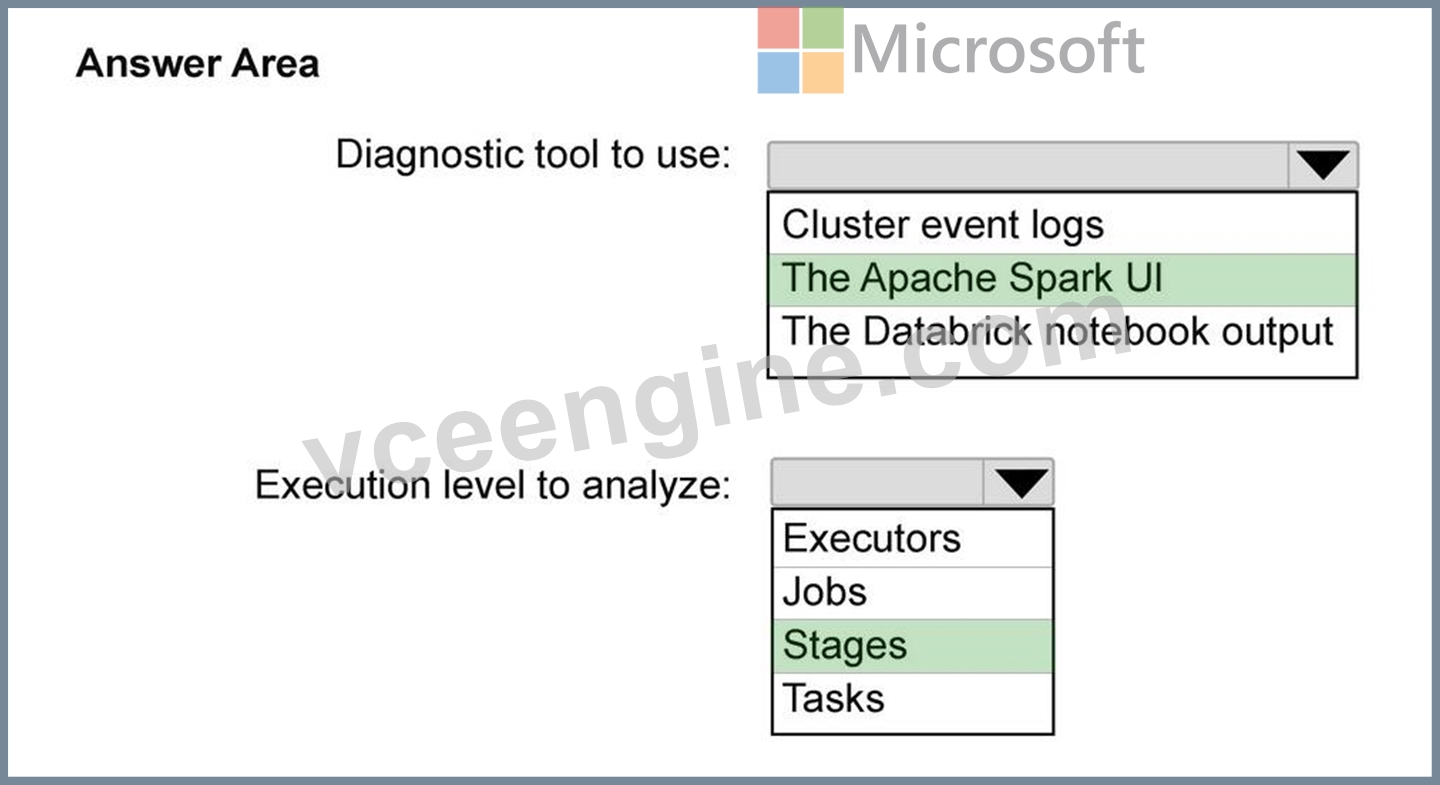
You have an Azure Databricks workspace that contains an all-purpose cluster named Cluster1.
You discover that out-of-memory (OOM) errors intermittently cause jobs running on Cluster1 to fail.
You need to identify the root cause of the failures by analyzing the runtime execution behavior.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.

Answer:
Explanation:
NEW QUESTION # 54
Hotspot Question
You have an Azure Databricks workspace.
You need to ingest streaming data from Azure Event Hubs by using Apache Spark Structured Streaming. The solution must authenticate to Event Hubs and read the event payload.
How should you complete the PySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.

Answer:
Explanation:

NEW QUESTION # 55
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
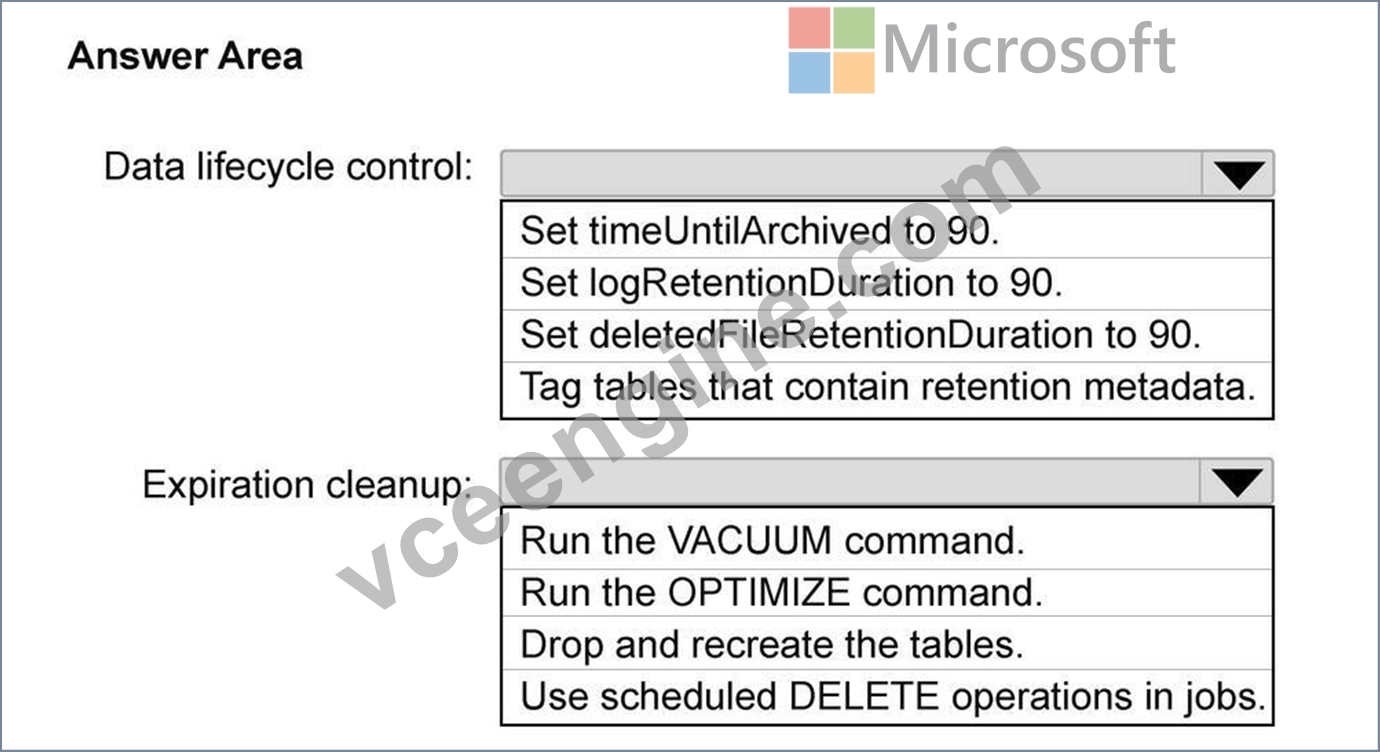
You need to implement a data lifecycle and expiration solution that meets the following requirements:
- Transaction logs and deleted data files that are older than 90 days
must be removed from Delta tables to reclaim storage.
- All the tables must remain available for querying during the cleanup
process.
- Administrative effort must be minimized.
What should you do for each requirement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:

NEW QUESTION # 56
You need to configure compute for the ingestion of telemetry data. The solution must meet the data ingestion and processing requirements.
What should you do?
- A. Increase an all-purpose cluster to a larger fixed node type.
- B. Disable autoscaling for a job compute cluster.
- C. Enable Photon acceleration for a job compute cluster.
- D. Move the ingestion pipelines to shared compute.
Answer: C
Explanation:
The correct answer is A. Photon is Azure Databricks' native vectorized query engine, written in C++, designed to accelerate data ingestion and SQL-heavy workloads significantly over the standard Spark JVM path. Enabling it on a job compute cluster directly addresses Contoso's requirement for 'fast and consistent performance for BI workloads' and 'production ingestion workloads that can scale automatically during telemetry spikes.' Photon integrates transparently - no code changes are needed - and pairs well with autoscaling job clusters to handle the bursty 40,000-sensor telemetry load.
Option B contradicts the isolation requirement: Contoso explicitly needs production and development separated, not merged onto shared compute. Option C with a fixed large node gives peak capacity at all times, driving up costs even during quiet periods. Option D disabling autoscaling is the opposite of what's needed - telemetry spikes require elastic scaling, not a locked node count.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/photon
NEW QUESTION # 57
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two managed Delta tables named sales.schema1.table1 and sales.schema1.table2.
sales.schema1.table1 contains sales data from the current year.
sales.schema1 .table2 contains historical data.
You need to load all the rows from sales.schema1.table1 into sales.schema1.table2. The solution must preserve any existing data in sales.schema1.table2 and minimize processing effort.
Which command should you run?
- A. CREATE OR REPLACE TABLE sales.schema1.table2 AS SELECT * FROM sales.schema1.table1;
- B. INSERT OVERWRITE sales.schema1.table2 SELECT * FROM sales.schema1.table1;
- C. INSERT INTO sales.schema1.table2 SELECT * FROM sales.schema1.table1;
- D. CREATE TABLE sales.schema1.table2 AS SELECT * FROM sales.schema1.table1;
Answer: C
Explanation:
To load all rows from one table into the other while preserving existing data and minimizing processing effort, you should use the SQL INSERT INTO statement.
Preserves Data: INSERT INTO appends new rows to the target table without modifying or deleting the existing data.
Lowest Processing Effort: It performs a direct data append at the storage level. Unlike MERGE INTO, it does not scan the target table for matches, saving significant compute time and costs.
Delta Lake Optimization: Because these are Delta tables, appending data simply writes new parquet files and commits them to the transaction log, making the operation fast and efficient.
Reference:
https://medium.com/@gema.correa/handling-schema-evolution-and-schema-compensation-in-databricks-lessons-from-the-field-7af8d915beef
NEW QUESTION # 58
......
The company is preparing for the test candidates to prepare the DP-750 exam guide professional brand, designed to be the most effective and easiest way to help users through their want to get the test DP-750 certification and obtain the relevant certification. In comparison with similar educational products, our training materials are of superior quality and reasonable price, so our company has become the top enterprise in the international market. Our DP-750 practice materials have been well received by the users, mainly reflected in the following advantages.
DP-750 Exam Vce Format: https://www.vceengine.com/DP-750-vce-test-engine.html
- Test DP-750 Voucher 🔀 Flexible DP-750 Testing Engine 💜 Exam DP-750 Tutorial 🏺 Search for “ DP-750 ” and download exam materials for free through 「 www.verifieddumps.com 」 ☝Exam DP-750 Exercise
- Test DP-750 Simulator Free 💒 Reliable DP-750 Exam Vce ☸ DP-750 Exam Registration 🎧 Enter ➡ www.pdfvce.com ️⬅️ and search for ➠ DP-750 🠰 to download for free ❎Reliable DP-750 Test Prep
- New DP-750 Exam Answers 🚅 DP-750 Latest Braindumps Sheet 🦺 Exam DP-750 Papers ⏮ Open website ▶ www.prepawayexam.com ◀ and search for { DP-750 } for free download 🛂Flexible DP-750 Testing Engine
- Reliable DP-750 Exam Vce 🥌 Test DP-750 Simulator Free 🌴 Test DP-750 Voucher 🧫 ⏩ www.pdfvce.com ⏪ is best website to obtain ➥ DP-750 🡄 for free download 🚇DP-750 Valid Learning Materials
- New DP-750 Exam Answers 🍤 DP-750 Latest Braindumps Sheet 🕛 DP-750 Latest Braindumps Sheet 🧖 Easily obtain free download of ⮆ DP-750 ⮄ by searching on ( www.troytecdumps.com ) 📧Trustworthy DP-750 Pdf
- DP-750 Latest Exam Price 🚗 Book DP-750 Free 🦅 Flexible DP-750 Testing Engine 📿 Search for { DP-750 } on { www.pdfvce.com } immediately to obtain a free download 🤤New DP-750 Test Format
- Test DP-750 Voucher 🥀 New Study DP-750 Questions ⬜ Best DP-750 Preparation Materials 👧 Easily obtain ( DP-750 ) for free download through ⏩ www.easy4engine.com ⏪ ✋DP-750 Exam Registration
- 100% Pass 2026 Microsoft - DP-750 - Implementing Data Engineering Solutions Using Azure Databricks Pdf Files 🔩 ➤ www.pdfvce.com ⮘ is best website to obtain ➡ DP-750 ️⬅️ for free download ⤴Trustworthy DP-750 Pdf
- Free PDF Quiz 2026 DP-750: High Pass-Rate Implementing Data Engineering Solutions Using Azure Databricks Pdf Files 🛶 Search for ➡ DP-750 ️⬅️ and download exam materials for free through ➥ www.testkingpass.com 🡄 🎠Reliable DP-750 Test Prep
- Free PDF Quiz Microsoft - DP-750 - Useful Implementing Data Engineering Solutions Using Azure Databricks Pdf Files 🦙 The page for free download of ( DP-750 ) on ▷ www.pdfvce.com ◁ will open immediately 💛Best DP-750 Preparation Materials
- Best DP-750 Preparation Materials 💉 Book DP-750 Free 🙅 Reliable DP-750 Exam Vce 👾 Search for ( DP-750 ) and easily obtain a free download on “ www.prepawaypdf.com ” 👠Test DP-750 Simulator Free
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes