P.S. Free & New DP-100 dumps are available on Google Drive shared by TestInsides: https://drive.google.com/open?id=1Eq2u8mjKtrVH5UniCCO6DOPyWc8JT3Jp
our DP-100 exam prep is renowned for free renewal in the whole year. As you have experienced various kinds of exams, you must have realized that renewal is invaluable to study materials, especially to such important DP-100 exams. And there is no doubt that being acquainted with the latest trend of exams will, to a considerable extent, act as a driving force for you to pass the DP-100 Exams and realize your dream of living a totally different life.
| Section | Objectives |
|---|---|
| Topic 1: Deploy and consume models | - Monitor deployed models and endpoints - Deploy models to endpoints |
| Topic 2: Optimize and manage models | - Track experiments and manage model lifecycle - Improve model performance |
| Topic 3: Design and prepare a machine learning solution | - Select appropriate Azure services for machine learning workloads - Plan and configure Azure Machine Learning workspace - Manage compute and data assets |
| Topic 4: Explore and analyze data | - Perform exploratory data analysis - Ingest and prepare data for modeling |
| Topic 5: Train machine learning models | - Train models using Azure Machine Learning - Tune hyperparameters and evaluate models |
>> DP-100 Latest Learning Material <<
With these two Designing and Implementing a Data Science Solution on Azure DP-100 practice exams, you will get the actual Microsoft DP-100 exam environment. Whereas the TestInsides PDF file is ideal for restriction-free test preparation. You can open this PDF file and revise DP-100 Real Exam Questions at any time. Choose the right format of Designing and Implementing a Data Science Solution on Azure DP-100 actual questions and start Microsoft DP-100 preparation today.
NEW QUESTION # 341
You are analyzing the asymmetry in a statistical distribution.
The following image contains two density curves that show the probability distribution of two datasets.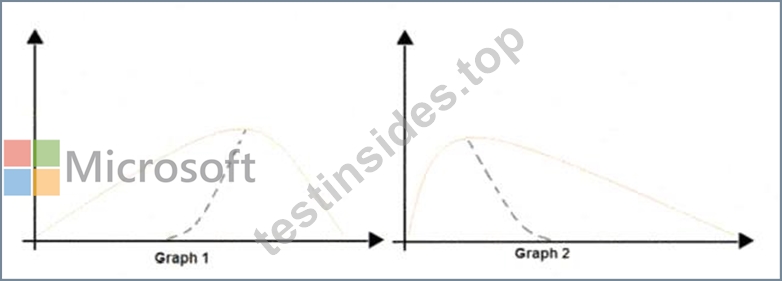
Use the drop-down menus to select the answer choice that answers each question based on the information presented in the graphic.
NOTE: Each correct selection is worth one point.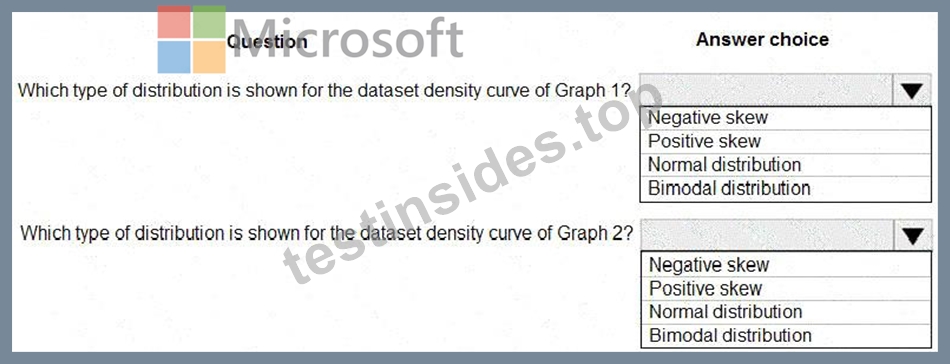
Answer:
Explanation: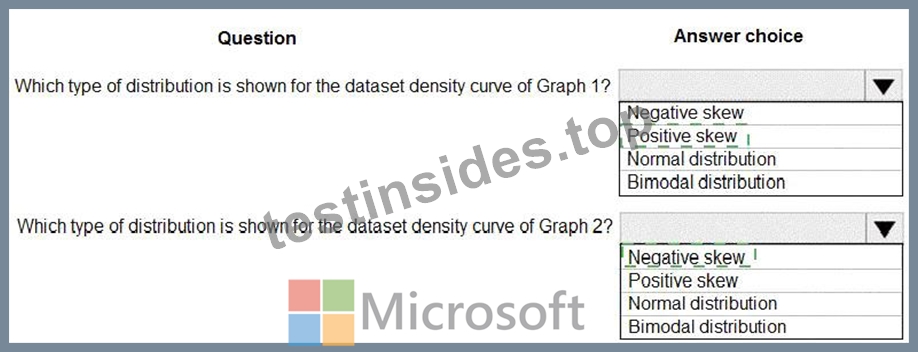
Explanation: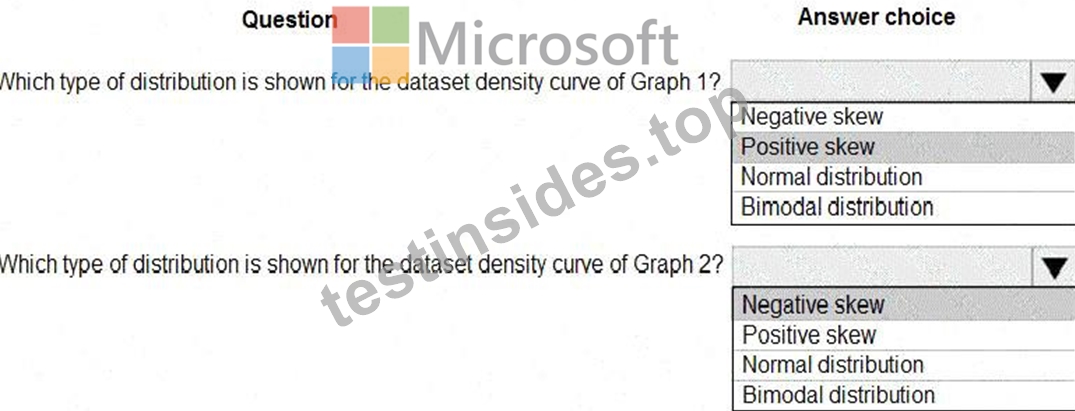
Box 1: Positive skew
Positive skew values means the distribution is skewed to the right.
Box 2: Negative skew
Negative skewness values mean the distribution is skewed to the left.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/compute-elementary- statistics
NEW QUESTION # 342
You have a Python script that executes a pipeline. The script includes the following code:
from azureml.core import Experiment
pipeline_run = Experiment(ws, 'pipeline_test').submit(pipeline)
You want to test the pipeline before deploying the script.
You need to display the pipeline run details written to the STDOUT output when the pipeline completes.
Which code segment should you add to the test script?
Answer: B
Explanation:
wait_for_completion: Wait for the completion of this run. Returns the status object after the wait.
Syntax: wait_for_completion(show_output=False, wait_post_processing=False, raise_on_error=True) Parameter: show_output Indicates whether to show the run output on sys.stdout.
NEW QUESTION # 343
An organization uses Azure Machine Learning service and wants to expand their use of machine learning.
You have the following compute environments. The organization does not want to create another compute environment.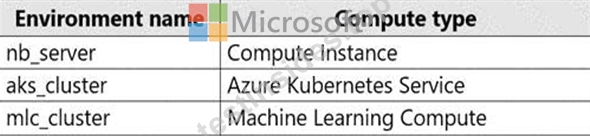
You need to determine which compute environment to use for the following scenarios.
Which compute types should you use? To answer, drag the appropriate compute environments to the correct scenarios. Each compute environment may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.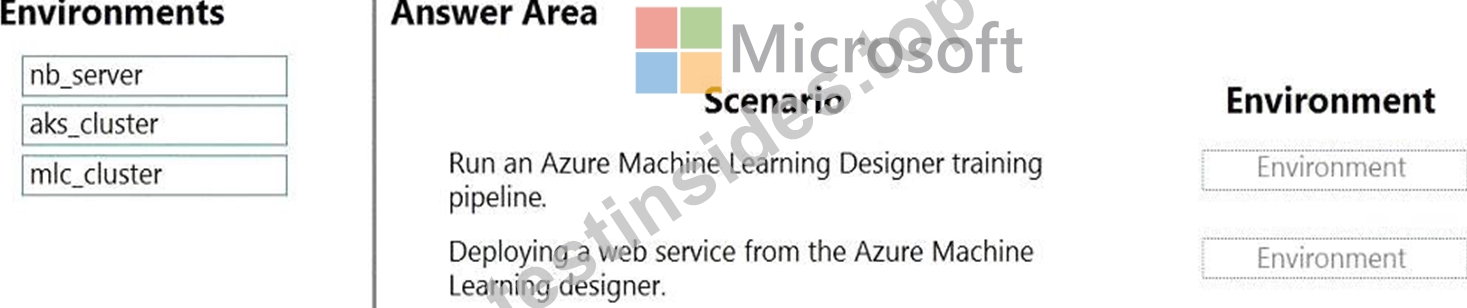
Answer:
Explanation: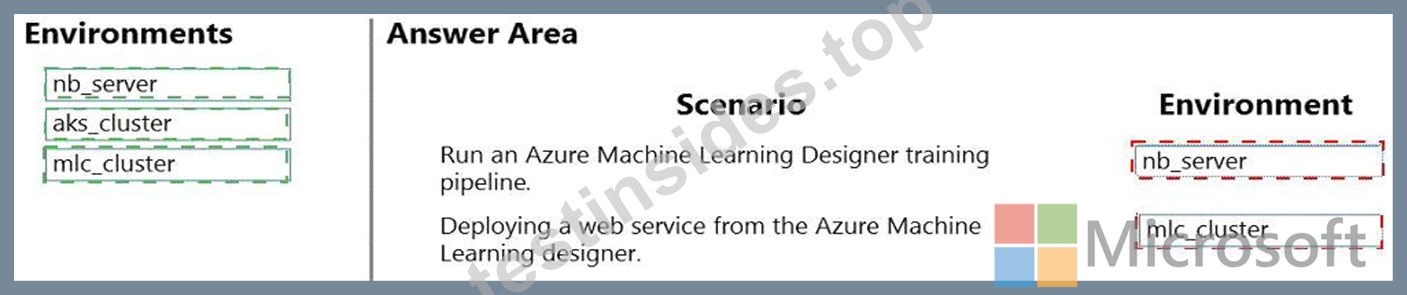
Explanation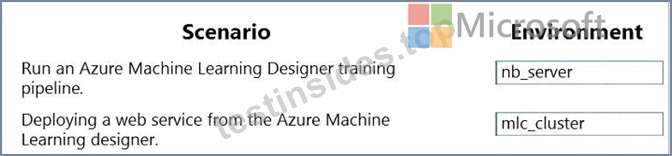
Box 1: nb_server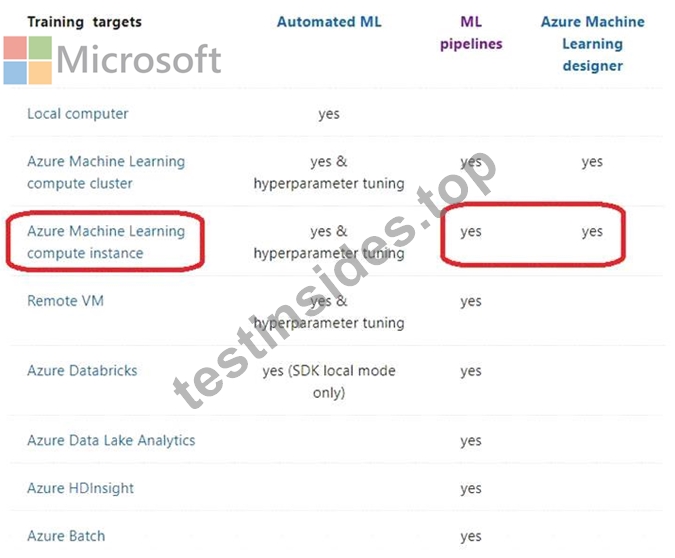
Box 2: mlc_cluster
With Azure Machine Learning, you can train your model on a variety of resources or environments, collectively referred to as compute targets. A compute target can be a local machine or a cloud resource, such as an Azure Machine Learning Compute, Azure HDInsight or a remote virtual machine.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/concept-compute-target
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-set-up-training-targets
Topic 2, Case Study 1
Overview
You are a data scientist in a company that provides data science for professional sporting events. Models will be global and local market data to meet the following business goals:
*Understand sentiment of mobile device users at sporting events based on audio from crowd reactions.
*Access a user's tendency to respond to an advertisement.
*Customize styles of ads served on mobile devices.
*Use video to detect penalty events.
Current environment
Requirements
* Media used for penalty event detection will be provided by consumer devices. Media may include images and videos captured during the sporting event and snared using social media. The images and videos will have varying sizes and formats.
* The data available for model building comprises of seven years of sporting event media. The sporting event media includes: recorded videos, transcripts of radio commentary, and logs from related social media feeds feeds captured during the sporting events.
*Crowd sentiment will include audio recordings submitted by event attendees in both mono and stereo Formats.
Advertisements
* Ad response models must be trained at the beginning of each event and applied during the sporting event.
* Market segmentation nxxlels must optimize for similar ad resporr.r history.
* Sampling must guarantee mutual and collective exclusivity local and global segmentation models that share the same features.
* Local market segmentation models will be applied before determining a user's propensity to respond to an advertisement.
* Data scientists must be able to detect model degradation and decay.
* Ad response models must support non linear boundaries features.
* The ad propensity model uses a cut threshold is 0.45 and retrains occur if weighted Kappa deviates from 0.1
+/-5%.
* The ad propensity model uses cost factors shown in the following diagram: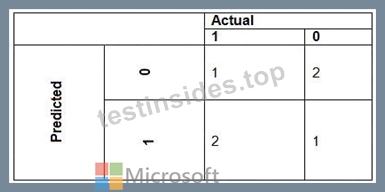
The ad propensity model uses proposed cost factors shown in the following diagram: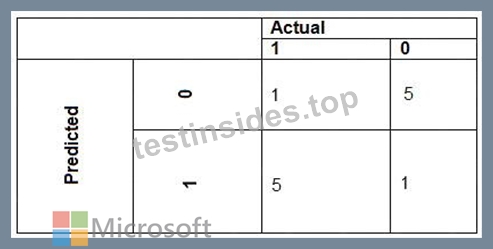
Performance curves of current and proposed cost factor scenarios are shown in the following diagram: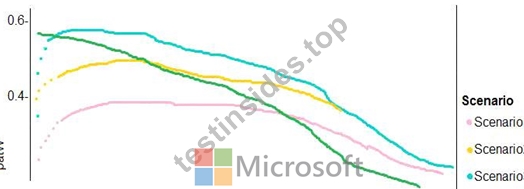
Penalty detection and sentiment
Findings
*Data scientists must build an intelligent solution by using multiple machine learning models for penalty event detection.
*Data scientists must build notebooks in a local environment using automatic feature engineering and model building in machine learning pipelines.
*Notebooks must be deployed to retrain by using Spark instances with dynamic worker allocation
*Notebooks must execute with the same code on new Spark instances to recode only the source of the data.
*Global penalty detection models must be trained by using dynamic runtime graph computation during training.
*Local penalty detection models must be written by using BrainScript.
* Experiments for local crowd sentiment models must combine local penalty detection data.
* Crowd sentiment models must identify known sounds such as cheers and known catch phrases. Individual crowd sentiment models will detect similar sounds.
* All shared features for local models are continuous variables.
* Shared features must use double precision. Subsequent layers must have aggregate running mean and standard deviation metrics Available.
segments
During the initial weeks in production, the following was observed:
*Ad response rates declined.
*Drops were not consistent across ad styles.
*The distribution of features across training and production data are not consistent.
Analysis shows that of the 100 numeric features on user location and behavior, the 47 features that come from location sources are being used as raw features. A suggested experiment to remedy the bias and variance issue is to engineer 10 linearly uncorrected features.
Penalty detection and sentiment
*Initial data discovery shows a wide range of densities of target states in training data used for crowd sentiment models.
*All penalty detection models show inference phases using a Stochastic Gradient Descent (SGD) are running too stow.
*Audio samples show that the length of a catch phrase varies between 25%-47%, depending on region.
*The performance of the global penalty detection models show lower variance but higher bias when comparing training and validation sets. Before implementing any feature changes, you must confirm the bias and variance using all training and validation cases.
NEW QUESTION # 344
You have an Azure Machine Learning workspace. You are running an experiment on your local computer.
You need to ensure that you can use MLflow Tracking with Azure Machine Learning Python SDK v2 to store metrics and artifacts from your local experiment runs in the workspace.
In which order should you perform the actions? To answer, move all actions from the list of actions to the answer area and arrange them in the correct order.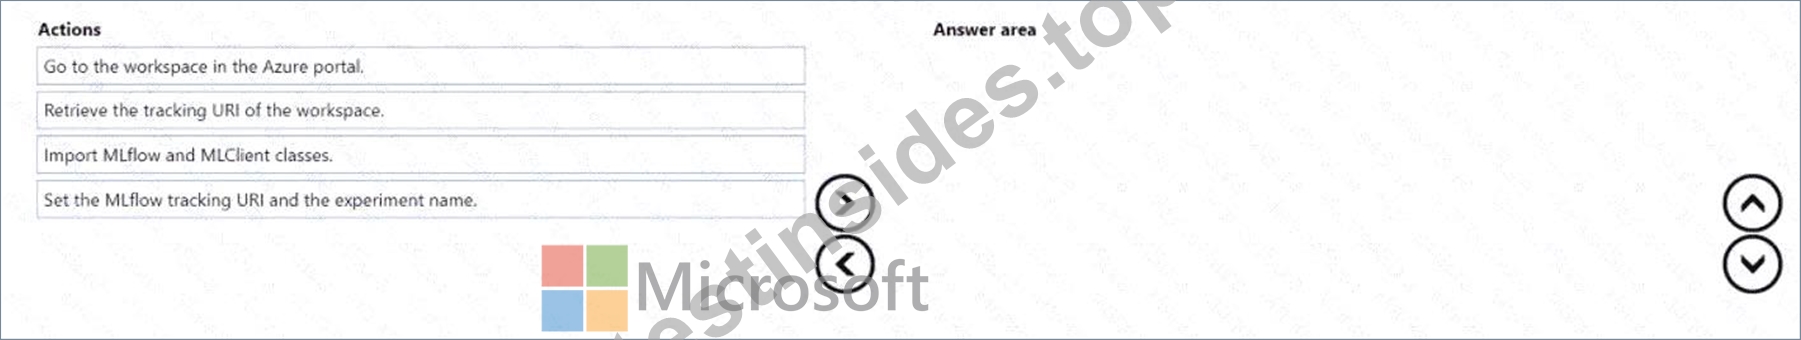
Answer:
Explanation: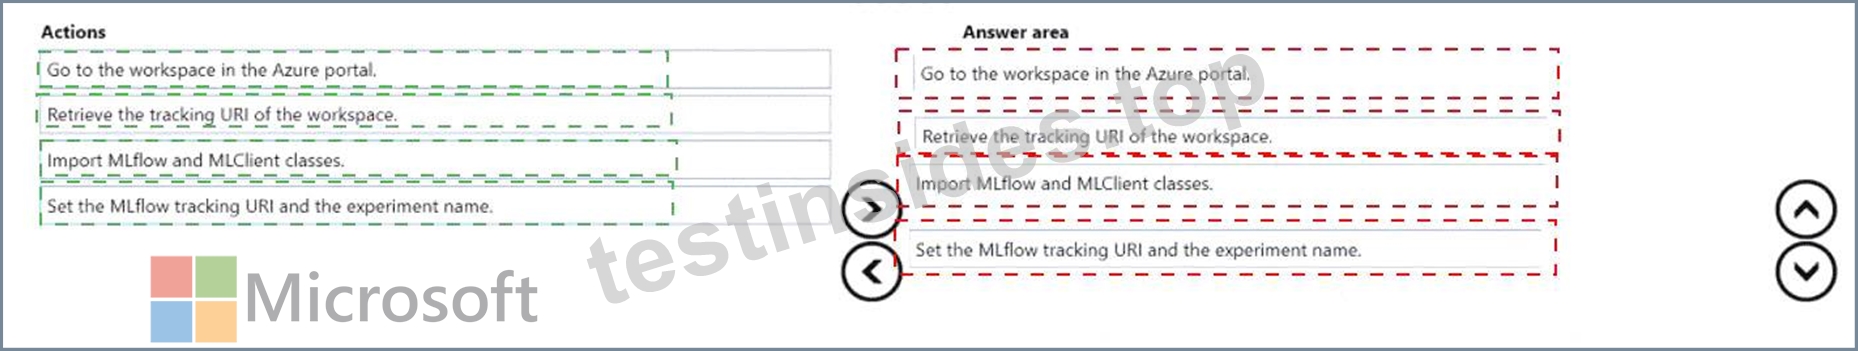
Explanation: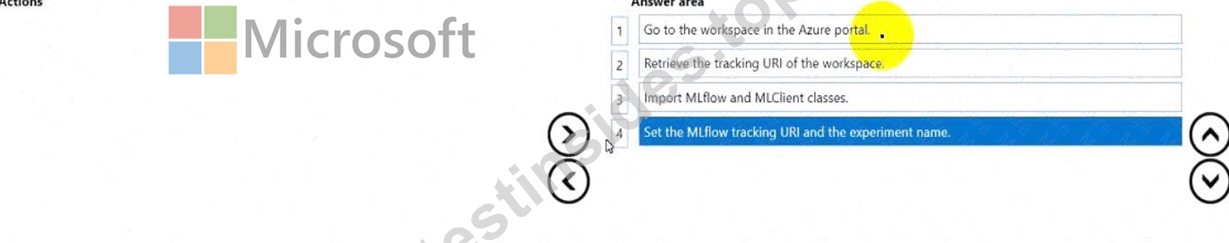
NEW QUESTION # 345
You are attaching an Azure Databricks-based compute resource to an Azure Machine Learning development workspace.
You need to configure parameters to attach the resource.
Which three parameters should you use? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,B,E
Explanation:
https://learn.microsoft.com/en-us/azure/machine-learning/v1/how-to-attach-compute-targets
NEW QUESTION # 346
......
Try to have a positive mindset, keep your mind focused on what you have to do. Self- discipline is important if you want to become successful. Learn to reject temptations. As old saying goes, no pains no gains. Learning our DP-100 preparation materials will help you calm down. What you have learned will finally pay off. With the DP-100 Certification, you can have more oppotunities to the bigger companies. And our DP-100 exam guide is condersidered the best aid to obtain the certification.
New DP-100 Test Notes: https://www.testinsides.top/DP-100-dumps-review.html
P.S. Free & New DP-100 dumps are available on Google Drive shared by TestInsides: https://drive.google.com/open?id=1Eq2u8mjKtrVH5UniCCO6DOPyWc8JT3Jp