P.S. Free 2026 Snowflake DAA-C01 dumps are available on Google Drive shared by BootcampPDF: https://drive.google.com/open?id=1EBDAfSWS7Be3ZBFZXjffHnnMqDehOJeQ
For the SnowPro Advanced: Data Analyst Certification Exam (DAA-C01) web-based practice exam no special software installation is required. because it is a browser-based SnowPro Advanced: Data Analyst Certification Exam (DAA-C01) practice test. The web-based SnowPro Advanced: Data Analyst Certification Exam (DAA-C01) practice exam works on all operating systems like Mac, Linux, iOS, Android, and Windows. In the same way, IE, Firefox, Opera and Safari, and all the major browsers support the web-based Snowflake DAA-C01 Practice Test.
| Section | Weight | Objectives |
|---|---|---|
| Perform Descriptive and Diagnostic Analysis | 10–15% | - Anomaly detection and root cause analysis - Statistical summarization and trend analysis - Exploratory and ad-hoc analysis |
| Prepare and Load Data | 15–20% | - External tables and data validation - File formats: CSV, JSON, Parquet, Avro - Data ingestion methods: COPY INTO, stages, Snowpipe |
| Perform Simple Data Transformations for Analysis | 15–20% | - Data cleansing, standardization, type conversion - Handling NULLs and structuring datasets - Views, materialized views, CTEs |
| Build and Troubleshoot Advanced SQL Queries | 20–25% | - Semi-structured data processing - Query optimization and troubleshooting - Complex joins, subqueries, window functions |
| Prepare and Present Data | 10–15% | - Data visualization and reporting - Snowsight dashboards and sharing results - Align outputs with business requirements |
| Use Built-in Functions and Create UDFs | 10–15% | - Scalar, aggregate, table, system functions - User-Defined Functions (UDFs) |
| Perform Predictive Analysis | 5–10% | - Using Snowflake ML and built-in analytics - Forecasting and predictive modeling |
>> Reliable DAA-C01 Cram Materials <<
Snowflake DAA-C01 dumps PDF version is printable and embedded with valid Snowflake DAA-C01 questions to help you get ready for the DAA-C01 exam quickly. SnowPro Advanced: Data Analyst Certification Exam (DAA-C01) exam dumps pdf are also usable on several smart devices. You can use it anywhere at any time on your smartphones and tablets. We update our Snowflake DAA-C01 Exam Questions bank regularly to match the changes and improve the quality of DAA-C01 questions so you can get a better experience.
NEW QUESTION # 66
You are tasked with creating a Snowsight dashboard to monitor the daily sales performance of an e-commerce platform. The sales data is stored in a table named 'SALES_DATR with columns 'SALE_DATE' (DATE), 'PRODUCT_ID' ONT), 'SALES AMOUNT' (FLOAT), and 'CUSTOMER REGION' (VARCHAR). You need to display a trendline chart showing the total sales amount for each day over the last 30 days, and also a table showing the top 5 regions by total sales amount. Which of the following steps are most efficient to achieve this in Snowsight? (Select TWO)
Answer: B,E
Explanation:
Option A is correct because it directly and efficiently creates the desired visualizations in Snowsight using separate tiles. Option C is also correct. Using Snowsight's Notebook feature allows for pre-aggregation, which can be useful in complex scenarios where directly visualizing from the raw data would impact dashboard performance. Options B, D, and E are either not directly supported or less efficient methods within the current Snowsight dashboarding capabilities.
NEW QUESTION # 67
You are tasked with ingesting data from a REST API that returns data in JSON format. The API requires authentication via an API key passed in the header and returns a large dataset, potentially exceeding Snowflake's recommended file size for optimal loading. Furthermore, the API has rate limits, and exceeding them results in temporary blocking. What is the MOST efficient and reliable way to retrieve this data into Snowflake?
Answer: B,C
Explanation:
Options B and D offer the most robust solutions. Option B, using a Python script with Snowpark, allows for fine-grained control over authentication, rate limiting, and data partitioning before loading into Snowflake. Option D, utilizing a dedicated ETL tool, provides a pre-built and often more scalable solution for complex data ingestion scenarios, including handling authentication, rate limits, and data transformation. Option A is less scalable and maintainable. Option C is incorrect because Snowpipe is designed for continuous loading from cloud storage, not directly from REST APIs. Option E is less efficient because it uses Java UDF inside stored procedure.
NEW QUESTION # 68
A Data Analyst runs this query: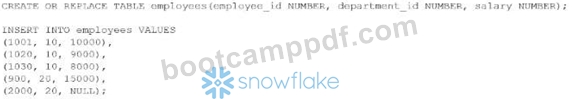
The Analyst men runs this query:
What will be the output?
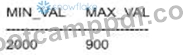
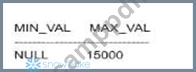
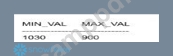
Answer: D
Explanation:
Understanding how Snowflake aggregate functions like MIN() and MAX() handle numerical data and NULL values is fundamental for accurate Data Analysis. In this scenario, we have a table with five records distributed across two departments.
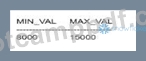
The MIN() function returns the smallest non-null value in the specified column across all rows in the group (or the entire table, if no GROUP BY is present). Looking at the salary column in the employees table, the values are: 10000, 9000, 8000, 15000, and NULL. The NULL value is ignored by the calculation. Among the remaining numerical values, 8000 is the smallest. Therefore, MIN_VAL will be 8000.
The MAX() function operates similarly, returning the largest non-null value from the set. Comparing the same list of numerical values-10000, 9000, 8000, and 15000-the largest value is clearly 15000. Consequently, MAX_VAL will be 15000.
Evaluating the Options based on the exhibit (image_8ca0df.png):
* Option A incorrectly identifies the minimum and maximum based on the employee_id column (where
2000 is max and 900 is min), rather than the requested salary column.
* Option B is incorrect as it seems to mix values from different columns or specific rows.
* Option C is incorrect because it mistakenly suggests that MIN() returns NULL if a NULL value is present in the column. In Snowflake, standard aggregate functions (except for specialized ones like ARRAY_AGG or certain window functions with specific clauses) skip NULL values entirely.
* Option D is the 100% correct output. It displays MIN_VAL as 8000 and MAX_VAL as 15000, which accurately reflects the mathematical minimum and maximum of the non-null entries in the salary column.
This behavior is consistent across all relational databases adhering to ANSI SQL standards, which Snowflake follows for these core aggregate operations.
NEW QUESTION # 69
You have identified corrupted data in a production table 'CUSTOMER DATA. Before attempting to clean the data directly in the production table, you want to create a safe environment to test your data cleaning scripts. You are also concerned about the impact of your data cleaning efforts on downstream reporting. Which of the following approaches using Snowflake clones is the MOST appropriate for this scenario?
Answer: C
Explanation:
Option D is the most appropriate and safely covers all aspects. Cloning to lets you experiment with cleaning. The most important part of the question is to handle the downstream reporting. So cloning 'CUSTOMER DATA' to lets you test how your new updates will affect the reports that depend on the data. Updating the 'CUSTOMER_DATR with the cleaning logic lets you apply the tested data cleaning. The other options do not protect the production reporting from potentially breaking changes during the data cleaning process. They may also directly update the production data, increasing risk. In option B, even though you are pointing to the new cloned reporting table, since that is created from DEV table it will already have changed data, and we want to report on the original, not the one with the dev changes. Option E does not discuss downstream impact on the reports, so this is not fully addressing all the impacts.
NEW QUESTION # 70
While reviewing the query profile for a complex data transformation pipeline, you notice a significant amount of time spent in the 'Join' operation between two large tables, 'transactions' and 'customers'. The join is performed on the 'customer _ id' column. Which of the following are potential strategies to optimize the join performance?
Answer: A,B
Explanation:
Mismatched data types can cause implicit type conversions, which can significantly degrade join performance. Clustering both tables on the join key ('customer_id') will ensure that rows with the same customer ID are located closer together on disk, reducing 1/0 and improving join efficiency. Broadcasting the smaller table is not directly controllable by the user in Snowflake and is handled automatically by the optimizer. 'LATERAL FLATTEN' is not a direct replacement for a join. Increasing the virtual warehouse size might improve overall processing time but doesn't address the specific inefficiency of the join operation.
NEW QUESTION # 71
......
Studying with Snowflake DAA-C01 Exam Questions and understanding is not enough. Regular tests and self-evaluation are mandatory. BootcampPDF's online Snowflake DAA-C01 Practice Test engine helps you self-evaluate anytime, anywhere. The results of these tests will make you feel confident in your studies and highlight areas you need to focus more on for the Snowflake exam. BootcampPDF's approach is highly acknowledged by educationists and experts.
Lab DAA-C01 Questions: https://www.bootcamppdf.com/DAA-C01_exam-dumps.html
P.S. Free 2026 Snowflake DAA-C01 dumps are available on Google Drive shared by BootcampPDF: https://drive.google.com/open?id=1EBDAfSWS7Be3ZBFZXjffHnnMqDehOJeQ