100% Pass Quiz 2026 Microsoft DP-750: High Pass-Rate Implementing Data Engineering Solutions Using Azure Databricks Valid Exam Testking

To keep you updated with latest changes in the DP-750 test questions, we offer one-year free updates in the form of new questions according to the requirement of DP-750 real exam. Updated DP-750 vce dumps ensure the accuracy of learning materials and guarantee success of in your first attempt. Why not let our DP-750 Dumps Torrent help you to pass your exam without spending huge amount of money.
| Section | Weight | Objectives |
|---|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
- 1. Monitor performance, logs, and execution metrics
- 2. Apply SDLC practices and version control
- 3. Troubleshoot failures, repair and restart jobs
- Build and orchestrate pipelines
- 1. Implement CI/CD with Git, Databricks Asset Bundles, CLI, and APIs
- 2. Design and implement Lakeflow Spark Declarative Pipelines
- 3. Configure Lakeflow Jobs: schedules, triggers, alerts, retries
|
| Set up and configure an Azure Databricks environment | 15–20% | - Integrate with Azure services
- 1. Configure monitoring with Azure Monitor and diagnostic settings
- 2. Connect to Azure Data Lake Storage, Azure Data Factory, Microsoft Entra ID
- Select and configure compute resources
- 1. Configure cluster policies, instance pools, and libraries
- 2. Choose compute types: serverless, job compute, SQL warehouse, classic compute
- 3. Manage workspace settings, permissions, and networking
|
| Prepare and process data | 30–35% | - Optimize and manage data storage
- 1. Optimize Delta tables: partitioning, Z-ordering, vacuum, optimize
- 2. Implement lakehouse architecture and manage table versions
- 3. Handle structured, semi-structured, and unstructured data
- Ingest and transform data
- 1. Transform using Spark SQL, PySpark, Scala, and Delta Lake
- 2. Ingest batch and streaming data from multiple sources
- 3. Implement schema enforcement, schema drift, and slowly changing dimensions
|
| Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
- 1. Set up external locations and storage credentials
- 2. Grant and revoke permissions, manage groups and service principals
- Implement data governance and security
- 1. Manage catalogs, schemas, tables, views, and volumes
- 2. Configure access control: row-level, column-level, attribute-based security
- 3. Enforce data quality, lineage, and auditing
|
>> DP-750 Valid Exam Testking <<
Certification DP-750 Sample Questions | DP-750 Interactive Course
Our passing rate is 98%-100% and there is little possibility for you to fail in the exam. But if you are unfortunately to fail in the exam we will refund you in full immediately. Some people worry that if they buy our DP-750 exam questions they may fail in the exam and the procedure of the refund is complicated. But we guarantee to you if you fail in we will refund you in full immediately and the process is simple. If only you provide us the screenshot or the scanning copy of the DP-750 failure marks we will refund you immediately. If you have doubts or other questions please contact us by emails or contact the online customer service and we will reply you and solve your problem as quickly as we can. So feel relieved when you buy our DP-750 guide torrent.
Microsoft Implementing Data Engineering Solutions Using Azure Databricks Sample Questions (Q61-Q66):
NEW QUESTION # 61
You have an Azure Databricks workspace that contains a Delta table named Table 1. Table 1 has accumulated obsolete files.
You need to reduce storage costs. The solution must preserve 30 days of time travel history. Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
- A. Set the delta.deletedFileRetentionDuration table property to 10 days
- B. Run the vacuum command on Table1.
- C. Reduce the deleted file retention period to one day.
- D. Set the delta. logRetentionDuration table property to 30 days.
- E. Run the OPTIMIZE command on Table1
Answer: A,B
Explanation:
The correct answers are B and E.
The goal is to reduce storage costs while preserving 30 days of time travel. Two actions are needed:
Set delta.deletedFileRetentionDuration to a value aligned with the 30-day requirement (Option B). Note: the answer option states '10 days' which would be insufficient for 30-day time travel - in practice this property should be set to at least 30 days. This property defines the retention floor: VACUUM will not delete any file newer than this threshold.
Run VACUUM on Table1 (Option E). VACUUM physically removes unreferenced data files older than the retention duration from storage. Without running VACUUM, obsolete files accumulate indefinitely regardless of the retention property setting - the property tells VACUUM what to keep; VACUUM is what does the actual cleanup.
Option C (OPTIMIZE) compacts small files for better query performance but never deletes anything. Option D (logRetentionDuration) keeps the transaction log for time travel but doesn't free up the data file storage.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/delta-vacuum
NEW QUESTION # 62
Hotspot Question
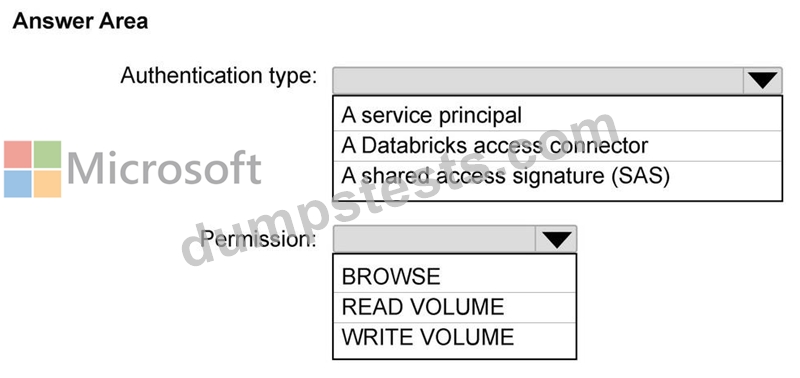
You have an Azure Databricks workspace that is enabled for Unity Catalog.
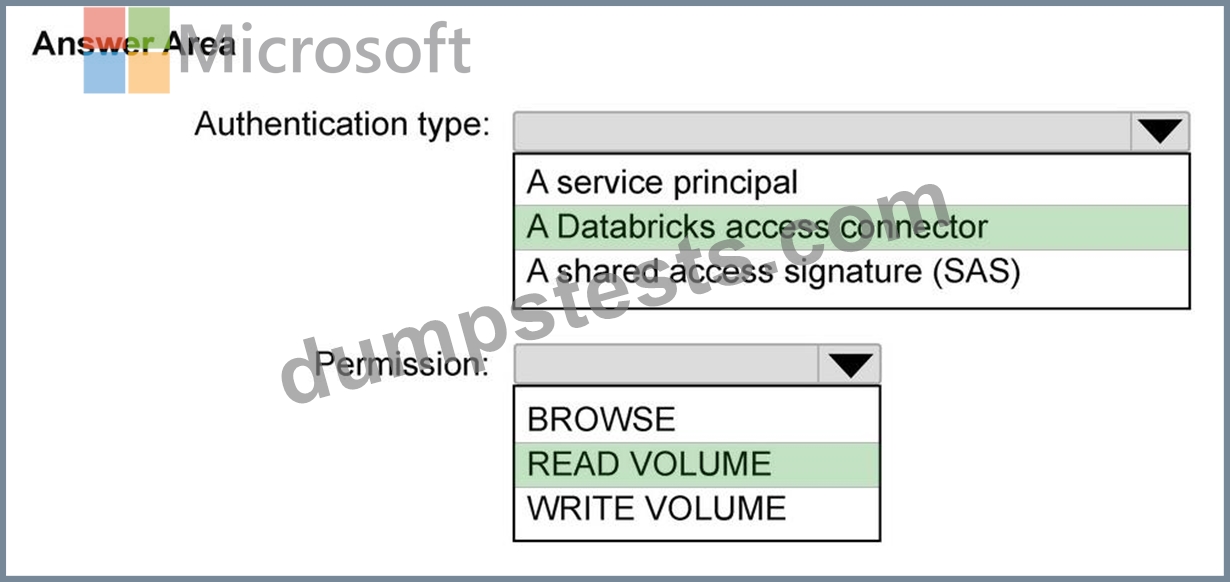
You need to create an external volume named Volume1 in an existing schema. Volume1 must expose files from an Azure Storage container. The solution must meet the following requirements:
- Ensure that authentication does NOT require storing credentials in
Databricks.
- Ensure that users can access the files, but NOT modify the files.
- Follow the principle of least privilege.
Which type of authentication should you configure, and which permission should you grant to the users? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 63
What does the VACUUM command do in Delta Lake?
- A. Compresses JSON files
- B. Rewrites table schema
- C. Deletes old unreferenced files
- D. Optimizes query performance
Answer: C
Explanation:
VACUUM removes old, unreferenced files that are no longer needed after updates or deletes. It helps manage storage but does not improve query performance directly. OPTIMIZE handles performance improvements. Schema changes are unrelated.
NEW QUESTION # 64
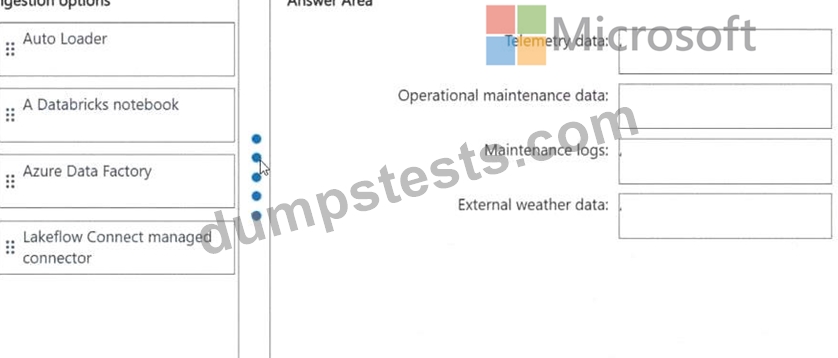
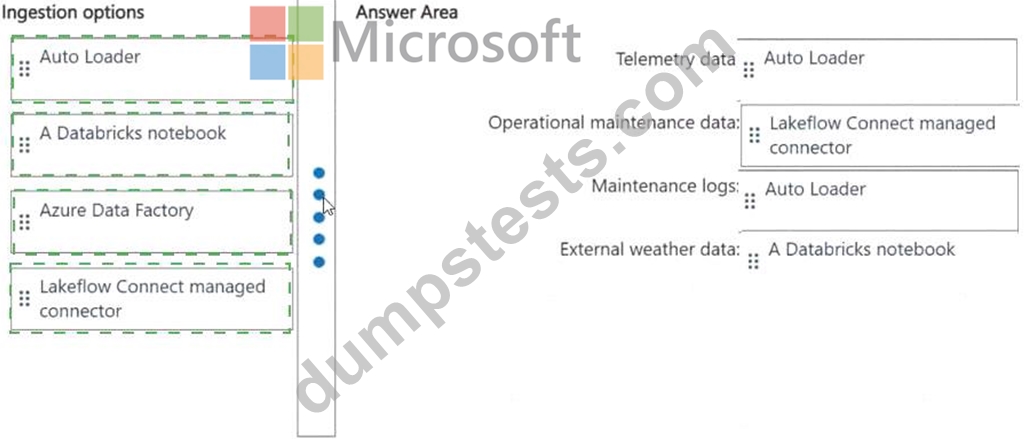
Which ingestion option should you recommend for each data source? To answer, drag the appropriate options to the correct data sources. Each option may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
The right ingestion tool depends on the source characteristics:
File-based telemetry and maintenance data # Auto Loader (cloudFiles). It monitors ADLS Gen2 for new arrivals, handles schema inference and evolution for the frequent schema drift, and requires minimal operational effort.
Real-time telemetry from Event Hubs # Spark Structured Streaming with the azure-eventhubs-spark connector. This provides exactly-once semantics and checkpoint-based recovery, satisfying 'resume processing after failures without reprocessing.' Structured maintenance data from PostgreSQL # JDBC connector. Databricks supports direct JDBC reads from relational databases with pushdown predicates.
Daily CSV ERP extracts (50-100 GB) # COPY INTO or Auto Loader. Both support idempotent incremental batch loading into Delta tables with minimal code.
Reference: https://learn.microsoft.com/en-us/azure/databricks/ingestion/auto-loader/
NEW QUESTION # 65
You have an Azure Databricks workspace named Workspace1 that contains a cluster named Cluster1.
You need to enable a user named User1 to install a Maven package on all the nodes of Cluster1. The solution must follow the principle of least privilege.
What should you do?
- A. Grant User1 the CAN MANAGE permission for Cluster1.
- B. Assign User1 the workspace admins role for Workspace1.
- C. Grant User1 the CAN RESTART permission for Cluster1.
- D. Assign User1 the Contributor role for the resource group that contains Workspace1.
Answer: A
Explanation:
Installing a Maven package on every node requires changing Cluster1's library configuration. The CAN MANAGE permission grants the cluster-level management capabilities required to add or remove libraries without giving User1 broader control over the entire workspace or Azure resource group. CAN RESTART allows a user to restart the cluster but does not provide sufficient authority to change its library configuration.
Assigning the Azure Contributor role would grant excessive control over the resource group and does not represent the appropriate Databricks object-level permission. Making User1 a workspace administrator would provide substantially more privileges than necessary. Granting CAN MANAGE directly on Cluster1 therefore satisfies the operational requirement while limiting User1's authority to the specific compute resource that must be modified.
NEW QUESTION # 66
......
Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification exams are a great way to analyze and evaluate the skills of a candidate effectively. Big companies are always on the lookout for capable candidates. You need to pass the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification exam to become a certified professional. This task is considerably tough for unprepared candidates however with the right DP-750 prep material there remains no chance of failure.
Certification DP-750 Sample Questions: https://www.dumpstests.com/DP-750-latest-test-dumps.html
- DP-750 Exam Dumps Collection 🦖 DP-750 Minimum Pass Score ⬅️ Reliable DP-750 Exam Guide 📼 Search for ⏩ DP-750 ⏪ and easily obtain a free download on { www.dumpsmaterials.com } 🍞Free DP-750 Download Pdf
- Quiz 2026 Microsoft Perfect DP-750: Implementing Data Engineering Solutions Using Azure Databricks Valid Exam Testking 😕 Easily obtain [ DP-750 ] for free download through ➥ www.pdfvce.com 🡄 🧨DP-750 Valid Test Forum
- DP-750 Mock Exam 🌾 Premium DP-750 Exam 📢 Formal DP-750 Test 🐠 Open ☀ www.examcollectionpass.com ️☀️ enter ➡ DP-750 ️⬅️ and obtain a free download 🛬Free DP-750 Download Pdf
- DP-750 Valid Test Forum 🌸 Reliable DP-750 Dumps Questions 🪁 DP-750 Exams Torrent 🔏 Search for ⇛ DP-750 ⇚ and download it for free on ✔ www.pdfvce.com ️✔️ website 🤓DP-750 Mock Exam
- DP-750 Pdf Exam Dump 🧙 DP-750 Mock Exam ⏫ Test DP-750 Price 🌖 Open ☀ www.troytecdumps.com ️☀️ and search for ⇛ DP-750 ⇚ to download exam materials for free 🕖DP-750 Exam Dumps Collection
- Reliable DP-750 Exam Testking 🐝 DP-750 Updated Demo 📅 Exam Topics DP-750 Pdf 🕟 Immediately open ⇛ www.pdfvce.com ⇚ and search for ☀ DP-750 ️☀️ to obtain a free download 🤨Free DP-750 Download Pdf
- DP-750 Updated Demo 🥏 DP-750 Valid Test Forum 💥 DP-750 Exam Dumps Collection 🤲 Download 【 DP-750 】 for free by simply entering ▛ www.prepawayete.com ▟ website 🔶DP-750 Test Certification Cost
- Quiz 2026 Microsoft Perfect DP-750: Implementing Data Engineering Solutions Using Azure Databricks Valid Exam Testking 🍗 Easily obtain free download of ➤ DP-750 ⮘ by searching on ➡ www.pdfvce.com ️⬅️ 🐣Reliable DP-750 Dumps Questions
- 100% Pass Quiz 2026 DP-750: Accurate Implementing Data Engineering Solutions Using Azure Databricks Valid Exam Testking 🔱 ➡ www.troytecdumps.com ️⬅️ is best website to obtain ( DP-750 ) for free download 🪒Reliable DP-750 Exam Testking
- DP-750 Updated Demo 🎩 DP-750 Mock Exam 🙂 DP-750 Pdf Exam Dump 🕎 Simply search for ➡ DP-750 ️⬅️ for free download on 【 www.pdfvce.com 】 🔋DP-750 Valid Exam Voucher
- 100% Pass Quiz 2026 DP-750: Accurate Implementing Data Engineering Solutions Using Azure Databricks Valid Exam Testking 🕢 Go to website ▷ www.exam4labs.com ◁ open and search for 《 DP-750 》 to download for free 🤪DP-750 Exam Dumps Collection
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes