Actual Databricks Certified-Data-Engineer-Professional Exam Dumps - Achieve Success In Exam

Immediately after you have made a purchase for our Certified-Data-Engineer-Professional practice dumps, you can download our Certified-Data-Engineer-Professional study materials to make preparations. It is universally acknowledged that time is a key factor in terms of the success. The more time you spend in the preparation for Certified-Data-Engineer-Professional Training Materials, the higher possibility you will pass the exam. And with our Certified-Data-Engineer-Professional study torrent, you can get preparations and get success as early as possible.
| Section | Objectives |
|---|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Apply Change Data Feed to address streaming table limitations and improve latency
- 2. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 3. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 4. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 5. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Create pipeline components using control flow operators such as if/else and foreach
- 2. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 3. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 4. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 5. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 6. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 7. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 8. Explain the advantages and disadvantages of streaming tables compared to materialized views
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Use row filters and column masks to protect sensitive table data
- 3. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
|
| Data Modeling | - Design and optimize data models
- 1. Design dimensional models for analytical workloads with efficient querying and aggregation
- 2. Design and implement scalable data models using Delta Lake to manage large datasets
- 3. Simplify data layout decisions and optimize query performance using liquid clustering
- 4. Identify the benefits of liquid clustering over partitioning and Z-Ordering
|
| Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Monitoring and Alerting | - Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
- Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Query Profile and Spark UI to monitor workloads
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
|
>> Certified-Data-Engineer-Professional Exam Assessment <<
Pass Guaranteed Quiz Databricks - Certified-Data-Engineer-Professional Exam Assessment
The second format of Databricks Certified-Data-Engineer-Professional exam preparation material is the web-based Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) practice test. It is useful for the ones who prefer to study online. VCEDumps have made this format so that users don't face the hassles of installing software while preparing for the Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) certification. The customizable feature of this format allows you to adjust the settings of Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) practice exams.
Databricks Certified Data Engineer Professional Sample Questions (Q33-Q38):
NEW QUESTION # 33
A data architect has designed a system in which two Structured Streaming jobs will concurrently write to a single bronze Delta table. Each job is subscribing to a different topic from an Apache Kafka source, but they will write data with the same schema. To keep the directory structure simple, a data engineer has decided to nest a checkpoint directory to be shared by both streams.
The proposed directory structure is displayed below:
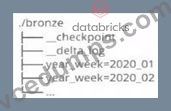
Which statement describes whether this checkpoint directory structure is valid for the given scenario and why?
- A. Yes; both of the streams can share a single checkpoint directory.
- B. No; Delta Lake manages streaming checkpoints in the transaction log.
- C. No; each of the streams needs to have its own checkpoint directory.
- D. No; only one stream can write to a Delta Lake table.
- E. Yes; Delta Lake supports infinite concurrent writers.
Answer: C
Explanation:
This is the correct answer because checkpointing is a critical feature of Structured Streaming that provides fault tolerance and recovery in case of failures. Checkpointing stores the current state and progress of a streaming query in a reliable storage system, such as DBFS or S3. Each streaming query must have its own checkpoint directory that is unique and exclusive to that query. If two streaming queries share the same checkpoint directory, they will interfere with each other and cause unexpected errors or data loss.
NEW QUESTION # 34
A data engineer is building a streaming data pipeline to ingest JSON files from cloud storage into a Delta Lake table. The pipeline must process files incrementally, handle schema evolution automatically, ensure exactly-once processing, and minimize manual infrastructure management.
How should the data engineer fulfill these requirements?
- A. Use Lakeflow Spart Declarative Pipelines with Auto Loader and enabling schema inference with
"cloudFiles.schemaEvolutionMode"= "addNewColumns" - B. Use Lakeflow Spark Declarative Pipelines with a static DataFrame read, merge schema with spark.conf.set ("spark.databricks.delta.schema.autoMerge.enabled", "true")
- C. Use Auto Loader in batch mode with a daily job to overwrite the Delta table.
- D. Use traditional Spark Structured Streaming with Auto Loader, manually configuring checkpoints location and enabling schema inference with "mergeSchema"= "true"
Answer: A
Explanation:
Lakeflow Spark Declarative Pipelines combined with Auto Loader provide fully managed incremental file ingestion with exactly-once guarantees and minimal operational overhead.
Enabling schema inference and evolution allows new columns in incoming JSON files to be incorporated automatically, satisfying the requirements for streaming ingestion, schema evolution, and reduced manual infrastructure management.
NEW QUESTION # 35
A data engineer is tasked with ensuring that a Delta table in Databricks continuously retains deleted files for 15 days (instead of the default 7 days), in order to permanently comply with the organization's data retention policy. Which code snippet correctly sets this retention period for deleted files?
- A. spark.sql("VACUUM my_table RETAIN 15 HOURS")
- B. from delta.tables import *
deltaTable = DeltaTable.forPath(spark, "/mnt/data/my_table")
deltaTable.deletedFileRetentionDuration = "interval 15 days" - C. spark.conf.set("spark.databricks.delta.deletedFileRetentionDuration", "15 days")
- D. spark.sql("ALTER TABLE my_table SET TBLPROPERTIES
('delta.deletedFileRetentionDuration' = 'interval 15 days')")
Answer: D
Explanation:
The deleted file retention period in Delta Lake is controlled by the table property delta.deletedFileRetentionDuration. Setting this property via ALTER TABLE ensures the retention policy is persistently enforced at the table level, extending deleted file retention to 15 days in compliance with organizational requirements.
NEW QUESTION # 36
A data engineer wants to automate job monitoring and recovery in Databricks using the Jobs API.
They need to list all jobs, identify a failed job, and rerun it. Which sequence of API actions should the data engineer perform?
- A. Use the jobs/list endpoint to list jobs, then use the jobs/create endpoint to create a new job, and run the new job using jobs/run-now.
- B. Use the jobs/cancel endpoint to remove failed jobs, then recreate them with jobs/create and run the new ones.
- C. Use the jobs/list endpoint to list jobs, check job run statuses with jobs/runs/list, and rerun a failed job using jobs/run-now.
- D. Use the jobs/get endpoint to retrieve job details, then use jobs/update to rerun failed jobs.
Answer: C
Explanation:
The Databricks Jobs REST API provides several endpoints for automation. The correct monitoring and rerun flow uses three specific calls:
GET /api/2.1/jobs/list - Lists all available jobs within the workspace.
GET /api/2.1/jobs/runs/list - Returns all runs for a specific job, including their current state (e.g., TERMINATED: FAILED).
POST /api/2.1/jobs/run-now - Immediately triggers a rerun of the specified job.
This sequence aligns with Databricks' prescribed automation model for job observability and recovery. Using jobs/update modifies metadata but does not rerun jobs, and jobs/create is only used for creating new jobs, not rerunning failed ones. Cancelling and recreating jobs introduces unnecessary duplication. Therefore, option A is the correct automated recovery workflow.
NEW QUESTION # 37
A data engineer is using Lakeflow Declarative Pipeline to propagate row deletions from a source bronze table (user_bronze) to a target silver table (user_silver). The engineer wants deletions in user_bronze to automatically delete corresponding rows in user_silver during pipeline execution.
Which configuration ensures deletions in the bronze table are propagated to the silver table?
- A. Enable Change Data Feed (CDF) on user_bronze, read its CDF stream, and use apply_changes() with apply_as_deletes=True for user_silver.
- B. Configure VACUUM on user_bronze to delete files, then rebuild user_silver from scratch.
- C. Enable CDF on user_silver, read its transaction log, and use MERGE to sync deletions.
- D. Use apply_changes without CDF and filter rows where _soft_deleted is true.
Answer: A
Explanation:
According to Databricks documentation, Change Data Feed (CDF) allows pipelines to read incremental data changes, including inserts, updates, and deletes, from a Delta table. When deletions occur in the source table, reading the CDF stream ensures downstream consumers receive the deletion records. The Lakeflow Declarative Pipelines API provides the apply_changes() function (or auto-CDC pipelines) with the apply_as_deletes parameter to correctly apply those deletions to the target table. This enables automatic synchronization between bronze and silver layers. Options A and D either require manual handling or complete rebuilds, and C incorrectly applies CDF to the target rather than the source. Therefore, enabling CDF on the bronze table and using apply_as_deletes=True is the correct, Databricks-supported configuration.
NEW QUESTION # 38
......
We have to admit that the processional certificates are very important for many people to show their capacity in the highly competitive environment. If you have the Databricks certification, it will be very easy for you to get a promotion. If you hope to get a job with opportunity of promotion, it will be the best choice chance for you to choose the Certified-Data-Engineer-Professional Study Materials from our company. Because our study materials have the enough ability to help you improve yourself and make you more excellent than other people.
Certified-Data-Engineer-Professional Exam Exercise: https://www.vcedumps.com/Certified-Data-Engineer-Professional-examcollection.html
- Effective Certified-Data-Engineer-Professional Exam Assessment - Guaranteed Databricks Certified-Data-Engineer-Professional Exam Success with Authoritative Certified-Data-Engineer-Professional Exam Exercise 🏡 Open ⮆ www.vce4dumps.com ⮄ and search for ⏩ Certified-Data-Engineer-Professional ⏪ to download exam materials for free 🌺Certified-Data-Engineer-Professional Examinations Actual Questions
- Instantly Crack Databricks Certified-Data-Engineer-Professional Exam with This Foolproof Method 🐹 Go to website ➥ www.pdfvce.com 🡄 open and search for ➽ Certified-Data-Engineer-Professional 🢪 to download for free 😢Certified-Data-Engineer-Professional Test Papers
- Databricks Certified-Data-Engineer-Professional Exam Questions - Proven Way Of Quick Preparation ⬛ Open “ www.practicevce.com ” enter ➠ Certified-Data-Engineer-Professional 🠰 and obtain a free download ⏮Certified-Data-Engineer-Professional Test Papers
- Pass Guaranteed Quiz Certified-Data-Engineer-Professional - Fantastic Databricks Certified Data Engineer Professional Exam Assessment 🍀 The page for free download of ▛ Certified-Data-Engineer-Professional ▟ on ▷ www.pdfvce.com ◁ will open immediately ✏Certified-Data-Engineer-Professional Test Papers
- Certified-Data-Engineer-Professional Test Torrent: Databricks Certified Data Engineer Professional - Certified-Data-Engineer-Professional Actual Exam - Databricks Certified Data Engineer Professional Pass for Sure 🧓 Simply search for ▶ Certified-Data-Engineer-Professional ◀ for free download on ▶ www.vceengine.com ◀ 👼Certified-Data-Engineer-Professional Best Practice
- Certified-Data-Engineer-Professional Test Torrent: Databricks Certified Data Engineer Professional - Certified-Data-Engineer-Professional Actual Exam - Databricks Certified Data Engineer Professional Pass for Sure 🛺 Search for ▛ Certified-Data-Engineer-Professional ▟ and easily obtain a free download on ⇛ www.pdfvce.com ⇚ 🐹Certified-Data-Engineer-Professional Detailed Answers
- Latest Certified-Data-Engineer-Professional Test Testking 🍰 Certified-Data-Engineer-Professional Premium Exam 📏 Certified-Data-Engineer-Professional Certification Dumps 🟪 Open ➽ www.examcollectionpass.com 🢪 enter { Certified-Data-Engineer-Professional } and obtain a free download ⏭Certified-Data-Engineer-Professional New Study Notes
- Certified-Data-Engineer-Professional Premium Exam 👪 Certified-Data-Engineer-Professional Guide Torrent ⏲ Certified-Data-Engineer-Professional Detailed Answers 😧 Search on ( www.pdfvce.com ) for ▶ Certified-Data-Engineer-Professional ◀ to obtain exam materials for free download 🍕New Certified-Data-Engineer-Professional Exam Bootcamp
- Certified-Data-Engineer-Professional Latest Exam Dumps ➰ Certified-Data-Engineer-Professional Test Papers 🥒 Certified-Data-Engineer-Professional Latest Exam 🗼 Simply search for ⇛ Certified-Data-Engineer-Professional ⇚ for free download on ( www.pdfdumps.com ) 🍿Training Certified-Data-Engineer-Professional Material
- Valid Certified-Data-Engineer-Professional Real Test ⭕ Pdf Certified-Data-Engineer-Professional Free 🕠 Certified-Data-Engineer-Professional Detailed Answers 🤵 Simply search for ( Certified-Data-Engineer-Professional ) for free download on [ www.pdfvce.com ] 🎤Certified-Data-Engineer-Professional Certification Dumps
- Valid Certified-Data-Engineer-Professional Real Test 👌 Pdf Certified-Data-Engineer-Professional Free 💲 Pdf Certified-Data-Engineer-Professional Free 🥺 Open website ⏩ www.dumpsmaterials.com ⏪ and search for ▷ Certified-Data-Engineer-Professional ◁ for free download 📘Certified-Data-Engineer-Professional Detailed Answers
- portfolium.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, justpaste.me, Disposable vapes