The Developing AI Apps and Agents on Azure (AI-103) practice questions are designed by experienced and qualified Developing AI Apps and Agents on Azure (AI-103) exam trainers. They have the expertise, knowledge, and experience to design and maintain the top standard of Developing AI Apps and Agents on Azure (AI-103) exam dumps. So rest assured that with the Developing AI Apps and Agents on Azure (AI-103) exam real questions you can not only ace your Developing AI Apps and Agents on Azure (AI-103) exam dumps preparation but also get deep insight knowledge about Microsoft AI-103 exam topics. So download Developing AI Apps and Agents on Azure (AI-103) exam questions now and start this journey.
| Section | Weight | Objectives |
|---|---|---|
| Implement computer vision solutions | 10-15% | - Analyze visual content
|
| Implement generative AI solutions | 25-30% | - Optimize and evaluate models
|
| Implement agentic solutions | 20-25% | - Build AI agents
|
| Plan and manage Azure AI solutions | 25-30% | - Manage AI solution lifecycle
|
| Implement text analysis and information extraction solutions | 10-15% | - Analyze and extract information
|
There are many certificates for you to get but which kind of certificate is most authorized, efficient and useful? We recommend you the AI-103 certificate because it can prove that you are competent in some area and boost outstanding abilities. If you buy our AI-103 study materials you will pass the test smoothly and easily. We boost professional expert team to organize and compile the AI-103 Training Materials diligently and provide the great service which include the service before and after the sale, the 24-hours online customer servic on our AI-103 exam questions.
NEW QUESTION # 101
You successfully run an HTTP request to:
.../regenerateKey?...
with:
{ " keyName " : " Key2 " }
What is the result?
Answer: D
Explanation:
Comprehensive and Detailed 150 to 250 words of Explanation From Azure AI Apps and Agents Developer/Course Guide/topics:
The request invokes the Azure Cognitive Services/Azure AI resource regenerateKey management operation and explicitly specifies " keyName " : " Key2 " .
Azure AI service resources traditionally expose two interchangeable access keys: Key1 and Key2. Key1 is treated as the primary key and Key2 as the secondary key. Regenerating Key2 invalidates the previous Key2 value and produces a new value for that secondary credential.
Only the selected key is regenerated. Key1 remains unchanged, so option D is incorrect.
The request is unrelated to Azure AI Search query keys, which are separate read-only Search credentials. It also does not cause the newly generated key to be written automatically to Azure Key Vault. Such storage would require separate Key Vault configuration or deployment automation.
Maintaining two resource keys enables zero- or low-downtime key rotation: applications can temporarily use one key while the other is regenerated, then switch and rotate the remaining key.
The AI-103 Study Guide includes securing and managing Azure AI systems, including credentials, authentication, least privilege, and operational resource management. Microsoft Learn
NEW QUESTION # 102
You have a Microsoft Foundry project that contains a customer support application.
You create two evaluations named Run1 and Run2 that have the following configurations:
* Both include risk and safety metrics
* Both include the protected material evaluation
* Run1 includes harmful content metrics that use a medium seventy threshold
* Run2 includes harmful content metrics that use a high severity threshold You run both evaluations against a dataset named D61 and receive the following results:
* Content harm defect rate of Run1: 12%
* Content harm defect late of Run2.4%
* Protected material evaluation o ' Run1: 6%
* Protected material evaluation of Run2: 6%
You start a fine-tuning job by using 081. The job fails during automatic RAI checks for multiple content harm types.
You discover that the content filtering configuration is set to high severity.
for each of the following statements, select Yes if the statement is true. Otherwise select No.
NOTE: Each correct selection Is worth one point.
Answer:
Explanation:
Explanation:
The first statement is No because automatic Responsible AI checks applied to a fine-tuning dataset are separate from the runtime content-filter threshold. Changing the runtime filter from high to low does not correct unsafe or disallowed training examples that cause the fine-tuning safety evaluation to fail.
The second statement is Yes . A medium severity threshold evaluates or flags a broader set of content than a high-only threshold. Consequently, Run1 can legitimately report a larger defect rate-12%-while Run2 reports only 4%.
The third statement is also Yes . Protected-material evaluation is a separate evaluation dimension from the standard harmful-content severity categories. Because both runs use the same dataset and protected-material evaluator, an identical 6% result is consistent even though the harmful-content threshold changes.
The key distinction is between runtime harmful-content thresholds , protected-material detection , and automatic RAI checks for training/fine-tuning data . They are related responsible-AI controls but operate independently.
The AI-103 Study Guide covers safety filters, risk detection, safety evaluations, and responsible-AI instrumentation as separate operational controls. Microsoft Learn
NEW QUESTION # 103
You configure Azure AI Content Safety to moderate user-uploaded images in a generative application. During testing, a colleague claims an image returned a Violence severity score of 3.
Why is this result impossible?
Answer: B
Explanation:
The Azure AI Content Safety image model uses a trimmed severity scale that returns only 0, 2, 4, and 6, so an odd value such as 3 cannot occur for image content. The text model uses the full 0 to 7 scale, which is where odd-numbered severities appear.
NEW QUESTION # 104
You have a Python application that sends customer support transcripts to Azure Language in Foundry Tools by using the REST API. The transcripts are in English and can contain customer names, email addresses, and phone numbers.
You need to store a redacted transcript of each conversation. The support workflow must redact only customer names and leave other entity types unchanged.
How should you complete the analyze-text request body? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
The operation must use PII Entity Recognition because the required output is a redacted version of the input based on personally identifiable information.
The " kind " property should therefore be set to " PiiEntityRecognition " . The piiCategories parameter restricts which sensitive categories participate in the analysis. Setting it to only [ " Person " ] ensures that recognized customer names are selected while other PII categories-such as PhoneNumber and email-related categories-are not included in the requested PII category set.
This distinction is important because the service supports numerous PII entity categories. Without category restriction, additional sensitive information could be recognized and redacted, which would violate the requirement to leave email addresses and phone numbers unchanged.
EntityRecognition is general Named Entity Recognition and is designed to identify broad entities such as Person, Organization, Location, and DateTime; it is not the specialized redaction operation required here.
LanguageDetection only identifies language.
The resulting PII response can provide redacted text and entity metadata that the application stores or audits.
Study Guide alignment: configure detection of sensitive content and implement solutions that extract entities and structured information from text . Microsoft Learn
NEW QUESTION # 105
You have a Microsoft Foundry project that processes procurement documents submitted by suppliers.
You need to implement two pipelines by using Azure Content Understanding in Foundry Tools. The solution must meet the following requirements:
* Include a pipeline named Pipeline1 that supports cost-effective, high-volume processing of standalone PDF invoices.
* Include a pipeline named Pipeline2 that supports cross-document validation by using multi-step reasoning and reference data.
How should you configure each pipeline? To answer, drag the appropriate configurations to the correct pipelines. Each configuration may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.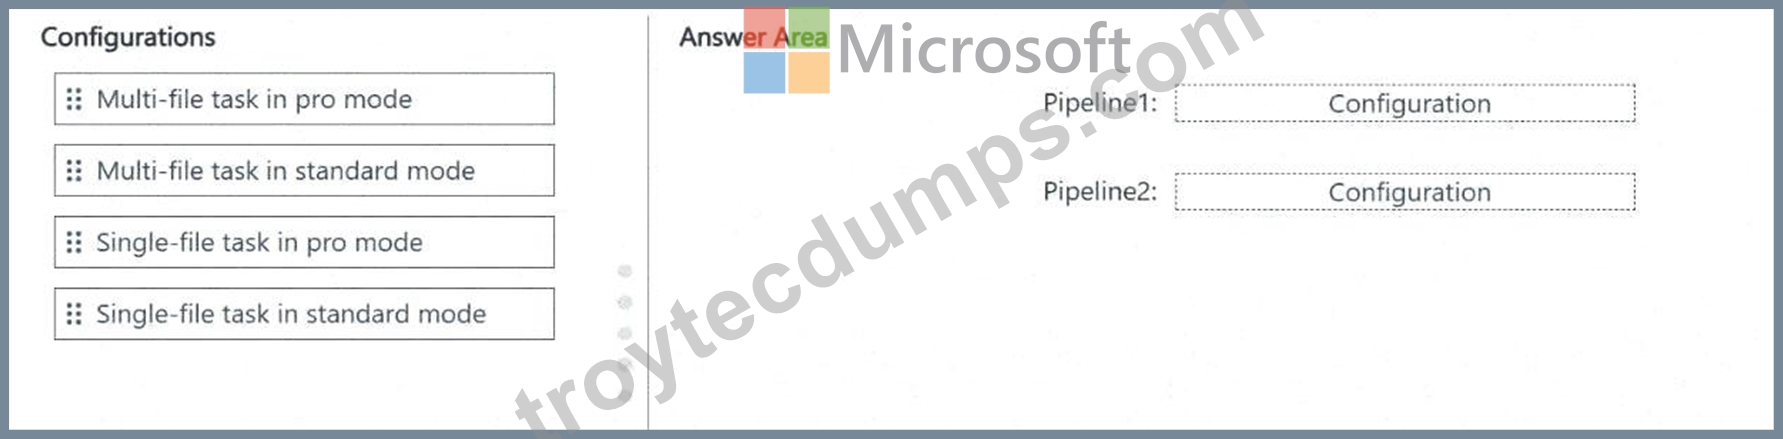
Answer:
Explanation: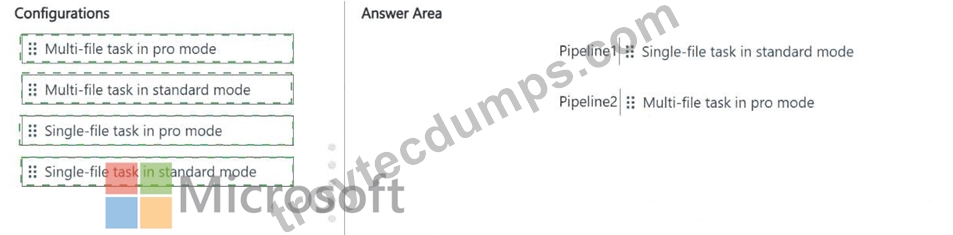
Explanation:
Pipeline1: Single-file task in standard mode
Pipeline2: Multi-file task in pro mode
Pipeline1 should use a single-file task in standard mode because the workload is high-volume processing of standalone PDF invoices. Azure Content Understanding standard mode is intended for individual files that require straightforward structured extraction, and Microsoft describes it as minimizing cost and latency for broad, data-centric processing scenarios. This makes it the best fit for cost-effective invoice extraction where each PDF can be processed independently.
Pipeline2 should use a multi-file task in pro mode because the requirement includes cross-document validation, multi-step reasoning, and reference data. Microsoft guidance states that pro mode is designed for advanced scenarios requiring multi-step reasoning and cross-file analysis, including processing multiple input files in a single request, validating or enriching data across documents, and using reference data to guide extraction and validation.
Single-file pro mode would add unnecessary capability for Pipeline1 and would not optimize for cost- effective high-volume standalone processing. Multi-file standard mode does not meet the pro-mode requirement for reference-data-based reasoning. Reference topics: Azure Content Understanding standard mode, pro mode, single-file tasks, multi-file tasks, field extraction, and procurement document validation.
NEW QUESTION # 106
......
Despite the complex technical concepts, our AI-103 exam questions have been simplified to the level of average candidates, posing no hurdles in understanding the various ideas. It is also the reason that our AI-103 study guide is famous all over the world. We also have tens of thousands of our loyal customers who support us on the AI-103 Learning Materials. Just look at the feedbacks on our website, they all praised our AI-103 practice engine.
AI-103 Upgrade Dumps: https://www.troytecdumps.com/AI-103-troytec-exam-dumps.html