BTW, DOWNLOAD part of VCEDumps MLA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1vk2a6AopYFNN3x609U2-d-WQgVeE-ZKT
MLA-C01 certification can demonstrate your mastery of certain areas of knowledge, which is internationally recognized and accepted by the general public as a certification. MLA-C01 certification is so high that it is not easy to obtain it. It requires you to invest time and energy. If you are not sure whether you can strictly request yourself, our MLA-C01 Exam Training can help you. Help is to arrange time for you and provide you with perfect service. If you use our learning materials to achieve your goals, we will be honored. MLA-C01 exam prep look forward to meeting you.
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified Machine Learning Engineer - Associate |
| Exam Number: | MLA-C01 |
| Available Languages: | Simplified Chinese, English, Korean, Japanese |
| Passing Score: | 720 (scaled score 100–1000) |
| Real Exam Qty: | 65 (50 scored, 15 unscored) |
| Certificate Validity Period: | 3 years |
| Related Certifications: | AWS Certified AI Practitioner AWS Certified Machine Learning - Specialty |
| Exam Price: | 150 USD |
| Exam Format: | Multiple choice, Matching, Case study, Multiple response, Ordering |
| Exam Duration: | 130 minutes |
| Recommended Training: | AWS Certified Machine Learning Engineer - Associate Official Exam Guide AWS Training and Certification |
| Exam Registration: | AWS Certification Portal Pearson VUE Registration |
| Sample Questions: | Amazon MLA-C01 Sample Questions |
| Exam Way: | Online proctored or onsite at Pearson VUE testing centers |
| Pre Condition: | Recommended: 1+ year hands-on experience with AWS services and machine learning engineering; familiarity with Amazon SageMaker and related ML services. No mandatory prerequisite exams. |
| Official Syllabus URL: | https://docs.aws.amazon.com/aws-certification/latest/machine-learning-engineer-associate-01/machine-learning-engineer-associate-01.html |
>> Reliable Amazon MLA-C01 Dumps <<
VCEDumps offers up-to-date AWS Certified Machine Learning Engineer - Associate (MLA-C01) practice material consisting of three formats that will prove to be vital for you. You can easily ace the AWS Certified Machine Learning Engineer - Associate (MLA-C01) exam on the first attempt if you prepare with this material. The Amazon MLA-C01 Exam Dumps have been made under the expert advice of 90,000 highly experienced Amazon professionals from around the globe. They assure that anyone who prepares from it will get AWS Certified Machine Learning Engineer - Associate (MLA-C01) certified on the first attempt.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 34
A company stores historical data in .csv files in Amazon S3. Only some of the rows and columns in the .csv files are populated. The columns are not labeled. An ML engineer needs to prepare and store the data so that the company can use the data to train ML models.
Select and order the correct steps from the following list to perform this task. Each step should be selected one time or not at all. (Select and order three.)
* Create an Amazon SageMaker batch transform job for data cleaning and feature engineering.
* Store the resulting data back in Amazon S3.
* Use Amazon Athena to infer the schemas and available columns.
* Use AWS Glue crawlers to infer the schemas and available columns.
* Use AWS Glue DataBrew for data cleaning and feature engineering.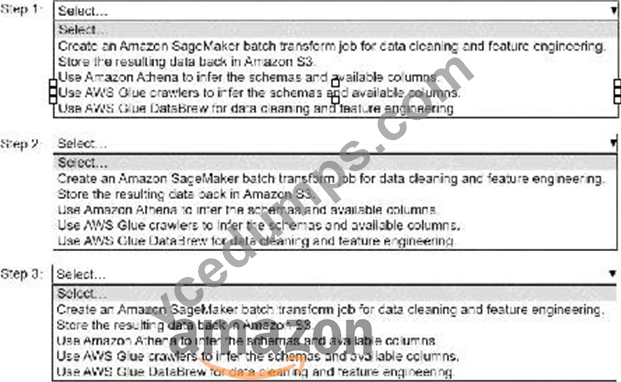
Answer:
Explanation: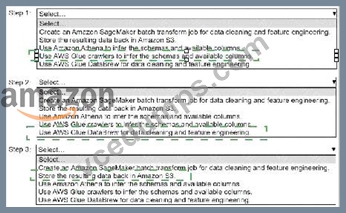
Explanation:
Step 1: Use AWS Glue crawlers to infer the schemas and available columns.Step 2: Use AWS Glue DataBrew for data cleaning and feature engineering.Step 3: Store the resulting data back in Amazon S3.
* Step 1: Use AWS Glue Crawlers to Infer Schemas and Available Columns
* Why?The data is stored in .csv files with unlabeled columns, and Glue Crawlers can scan the raw data in Amazon S3 to automatically infer the schema, including available columns, data types, and any missing or incomplete entries.
* How?Configure AWS Glue Crawlers to point to the S3 bucket containing the .csv files, and run the crawler to extract metadata. The crawler creates a schema in the AWS Glue Data Catalog, which can then be used for subsequent transformations.
* Step 2: Use AWS Glue DataBrew for Data Cleaning and Feature Engineering
* Why?Glue DataBrew is a visual data preparation tool that allows for comprehensive cleaning and transformation of data. It supports imputation of missing values, renaming columns, feature engineering, and more without requiring extensive coding.
* How?Use Glue DataBrew to connect to the inferred schema from Step 1 and perform data cleaning and feature engineering tasks like filling in missing rows/columns, renaming unlabeled columns, and creating derived features.
* Step 3: Store the Resulting Data Back in Amazon S3
* Why?After cleaning and preparing the data, it needs to be saved back to Amazon S3 so that it can be used for training machine learning models.
* How?Configure Glue DataBrew to export the cleaned data to a specific S3 bucket location. This ensures the processed data is readily accessible for ML workflows.
Order Summary:
* Use AWS Glue crawlers to infer schemas and available columns.
* Use AWS Glue DataBrew for data cleaning and feature engineering.
* Store the resulting data back in Amazon S3.
This workflow ensures that the data is prepared efficiently for ML model training while leveraging AWS services for automation and scalability.
NEW QUESTION # 35
A company's ML engineer has deployed an ML model for sentiment analysis to an Amazon SageMaker endpoint. The ML engineer needs to explain to company stakeholders how the model makes predictions.
Which solution will provide an explanation for the model's predictions?
Answer: B
NEW QUESTION # 36
Case Study
An ML engineer is developing a fraud detection model on AWS. The training dataset includes transaction logs, customer profiles, and tables from an on-premises MySQL database. The transaction logs and customer profiles are stored in Amazon S3.
The dataset has a class imbalance that affects the learning of the model's algorithm. Additionally, many of the features have interdependencies. The algorithm is not capturing all the desired underlying patterns in the data.
The ML engineer needs to use an Amazon SageMaker built-in algorithm to train the model.
Which algorithm should the ML engineer use to meet this requirement?
Answer: D
NEW QUESTION # 37
An ML engineer is evaluating several ML models and must choose one model to use in production. The cost of false negative predictions by the models is much higher than the cost of false positive predictions.
Which metric finding should the ML engineer prioritize the MOST when choosing the model?
Answer: D
Explanation:
Recall measures the ability of a model to correctly identify all positive cases (true positives) out of all actual positives, minimizing false negatives. Since the cost of false negatives is much higher than falsepositives in this scenario, the ML engineer should prioritize models with high recall to reduce the likelihood of missing positive cases.
NEW QUESTION # 38
A company has an ML model in Amazon SageMaker AI. An ML engineer needs to implement a monitoring solution to automatically detect changes in the input data distribution of model features.
Which solution will meet this requirement with the LEAST operational overhead?
Answer: A
Explanation:
Option A is correct because the requirement is to detect changes in the input data distribution of model features , which is a data quality / data drift monitoring problem. AWS documentation states that Amazon SageMaker Model Monitor uses rules to detect data drift and alerts you when it happens. The documented workflow is to enable data capture, create a baseline from training data, and then run monitoring jobs that compare incoming inference data against that baseline. That directly matches the need to automatically detect changes in feature distributions.
AWS also documents that Model Monitor can emit metrics to Amazon CloudWatch , and those metrics can be used with CloudWatch alarms to notify teams when data quality drifts beyond acceptable thresholds.
That makes Option A the lowest-operational-overhead solution because it uses SageMaker's built-in monitoring capability plus managed alerting, rather than requiring custom drift logic. The inclusion of emit_metrics and CloudWatch alarming is consistent with the SageMaker monitoring pattern for automated notification.
The other options are weaker. Option B is for model quality monitoring, which focuses on prediction performance against ground truth, not shifts in the input feature distribution. Option C uses SageMaker Debugger, which is aimed at training-time debugging and custom rule analysis rather than managed production data drift monitoring. Option D relies on manual log analysis and endpoint performance metrics, which does not directly solve feature-distribution drift detection and adds more operational effort. Therefore, the best AWS-documented answer is A .
NEW QUESTION # 39
......
Real MLA-C01 Testing Environment: https://www.vcedumps.com/MLA-C01-examcollection.html
DOWNLOAD the newest VCEDumps MLA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1vk2a6AopYFNN3x609U2-d-WQgVeE-ZKT