DOWNLOAD the newest ITexamReview DP-600 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1453Lyo_MSMCG4AHG_pFR1drqEWjLWBIB
Our company has successfully created ourselves famous brands in the past years, and all of the DP-600 valid study guide materials from our company have been authenticated by the international authoritative institutes and cater for the demands of all customers at the same time. We are attested that the quality of the DP-600 Test Prep from our company have won great faith and favor of customers. We persist in keeping creating the best helpful and most suitable DP-600 study practice question for all customers.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Implementing Analytics Solutions Using Microsoft Fabric |
| Exam Number: | DP-600 |
| Related Certifications: | Microsoft Certified: Fabric Analytics Engineer Associate |
| Exam Format: | Case studies, Multiple-choice, Drag-and-drop |
| Exam Price: | $165 USD |
| Exam Duration: | 120 minutes |
| Real Exam Qty: | 40-60 |
| Available Languages: | Korean, English, Japanese, Chinese (Simplified) |
| Passing Score: | 700/1000 |
| Certificate Validity Period: | 1 year |
| Sample Questions: | Microsoft DP-600 Sample Questions |
| Exam Way: | Online proctored or in-person testing center |
| Pre Condition: | Candidates should have foundational knowledge of data concepts, experience with Microsoft Fabric, and proficiency in data transformation and modeling. Familiarity with Power BI is recommended but not required. |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/certifications/exams/dp-600 |
For the quick and complete DP-600 exam preparation the ITexamReview DP-600 practice test questions are the ideal selection. With the Microsoft DP-600 PDF Questions and practice test software, you will get everything that you need to learn, prepare and pass the difficult Microsoft DP-600 Exam with good scores.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 113
Which type of data store should you recommend in the AnalyticsPOC workspace?
Answer: B
Explanation:
A lakehouse (C) should be recommended for the AnalyticsPOC workspace. It combines the capabilities of a data warehouse with the flexibility of a data lake. A lakehouse supports semi-structured and unstructured data and allows for T-SQL and Python read access, fulfilling the technical requirements outlined for Litware.
References = For further understanding, Microsoft ' s documentation on the lakehouse architecture provides insights into how it supports various data types and analytical operations.
Topic 1, Litware. Inc. Case Study
Overview
Litware. Inc. is a manufacturing company that has offices throughout North America. The analytics team at Litware contains data engineers, analytics engineers, data analysts, and data scientists.
Existing Environment
litware has been using a Microsoft Power Bl tenant for three years. Litware has NOT enabled any Fabric capacities and features.
Fabric Environment
Litware has data that must be analyzed as shown in the following table.
The Product data contains a single table and the following columns.
The customer satisfaction data contains the following tables:
* Survey
* Question
* Response
For each survey submitted, the following occurs:
* One row is added to the Survey table.
* One row is added to the Response table for each question in the survey.
The Question table contains the text of each survey question. The third question in each survey response is an overall satisfaction score. Customers can submit a survey after each purchase.
User Problems
The analytics team has large volumes of data, some of which is semi-structured. The team wants to use Fabric to create a new data store.
Product data is often classified into three pricing groups: high, medium, and low. This logic is implemented in several databases and semantic models, but the logic does NOT always match across implementations.
Planned Changes
Litware plans to enable Fabric features in the existing tenant. The analytics team will create a new data store as a proof of concept (PoC). The remaining Litware users will only get access to the Fabric features once the PoC is complete. The PoC will be completed by using a Fabric trial capacity.
The following three workspaces will be created:
* AnalyticsPOC: Will contain the data store, semantic models, reports, pipelines, dataflows, and notebooks used to populate the data store
* DataEngPOC: Will contain all the pipelines, dataflows, and notebooks used to populate Onelake
* DataSciPOC: Will contain all the notebooks and reports created by the data scientists The following will be created in the AnalyticsPOC workspace:
* A data store (type to be decided)
* A custom semantic model
* A default semantic model
* Interactive reports
The data engineers will create data pipelines to load data to OneLake either hourly or daily depending on the data source. The analytics engineers will create processes to ingest transform, and load the data to the data store in the AnalyticsPOC workspace daily. Whenever possible, the data engineers will use low-code tools for data ingestion. The choice of which data cleansing and transformation tools to use will be at the data engineers ' discretion.
All the semantic models and reports in the Analytics POC workspace will use the data store as the sole data source.
Technical Requirements
The data store must support the following:
* Read access by using T-SQL or Python
* Semi-structured and unstructured data
* Row-level security (RLS) for users executing T-SQL queries
Files loaded by the data engineers to OneLake will be stored in the Parquet format and will meet Delta Lake specifications.
Data will be loaded without transformation in one area of the AnalyticsPOC data store. The data will then be cleansed, merged, and transformed into a dimensional model.
The data load process must ensure that the raw and cleansed data is updated completely before populating the dimensional model.
The dimensional model must contain a date dimension. There is no existing data source for the date dimension. The Litware fiscal year matches the calendar year. The date dimension must always contain dates from 2010 through the end of the current year.
The product pricing group logic must be maintained by the analytics engineers in a single location. The pricing group data must be made available in the data store for T-SQL queries and in the default semantic model. The following logic must be used:
* List prices that are less than or equal to 50 are in the low pricing group.
* List prices that are greater than 50 and less than or equal to 1,000 are in the medium pricing group.
* List pnces that are greater than 1,000 are in the high pricing group.
Security Requirements
Only Fabric administrators and the analytics team must be able to see the Fabric items created as part of the PoC. Litware identifies the following security requirements for the Fabric items in the AnalyticsPOC workspace:
* Fabric administrators will be the workspace administrators.
* The data engineers must be able to read from and write to the data store. No access must be granted to datasets or reports.
* The analytics engineers must be able to read from, write to, and create schemas in the data store. They also must be able to create and share semantic models with the data analysts and view and modify all reports in the workspace.
* The data scientists must be able to read from the data store, but not write to it. They will access the data by using a Spark notebook.
* The data analysts must have read access to only the dimensional model objects in the data store. They also must have access to create Power Bl reports by using the semantic models created by the analytics engineers.
* The date dimension must be available to all users of the data store.
* The principle of least privilege must be followed.
Both the default and custom semantic models must include only tables or views from the dimensional model in the data store. Litware already has the following Microsoft Entra security groups:
* FabricAdmins: Fabric administrators
* AnalyticsTeam: All the members of the analytics team
* DataAnalysts: The data analysts on the analytics team
* DataScientists: The data scientists on the analytics team
* Data Engineers: The data engineers on the analytics team
* Analytics Engineers: The analytics engineers on the analytics team
Report Requirements
The data analysis must create a customer satisfaction report that meets the following requirements:
* Enables a user to select a product to filter customer survey responses to only those who have purchased that product
* Displays the average overall satisfaction score of all the surveys submitted during the last 12 months up to a selected date
* Shows data as soon as the data is updated in the data store
* Ensures that the report and the semantic model only contain data from the current and previous year
* Ensures that the report respects any table-level security specified in the source data store
* Minimizes the execution time of report queries
NEW QUESTION # 114
Hotspot Question
You have a Fabric tenant that contains a warehouse named WH1.
You have source data in a CSV file that has the following fields:
- SalesTransactionID
- SaleDate
- CustomerCode
- CustomerName
- CustomerAddress
- ProductCode
- ProductName
- Quantity
- UnitPrice
You plan to implement a star schema for the tables in WH1. The dimension tables in WH1 will implement Type 2 slowly changing dimension (SCD) logic.
You need to design the tables that will be used for sales transaction analysis and load the source data.
Which type of target table should you specify for the CustomerName, CustomerCode, and SaleDate fields? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.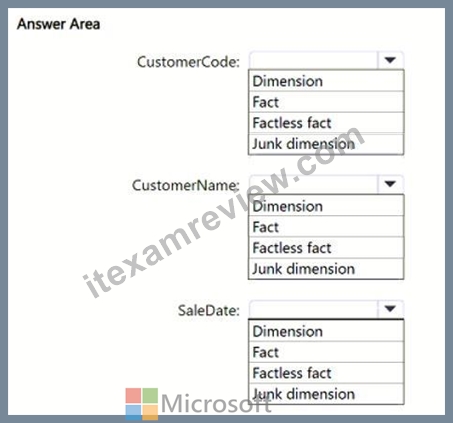
Answer:
Explanation:
NEW QUESTION # 115
You have a Fabric warehouse named Warehouse1 that contains a table named dbo.Product. dbo.Product contains the following columns.
You need to use a T-SQL query to add a column named PriceRange to dbo.Product. The column must categorize each product based on UnitPrice. The solution must meet the following requirements:
* If UnitPrice is 0, PriceRange is " Not for resale " .
* If UnitPrice is less than 50, PriceRange is " Under $50 " .
* If UnitPrice is between 50 and 250, PriceRange is " Under $250 " .
* In all other instances, PriceRange is " $250+ " .
How should you complete the query? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: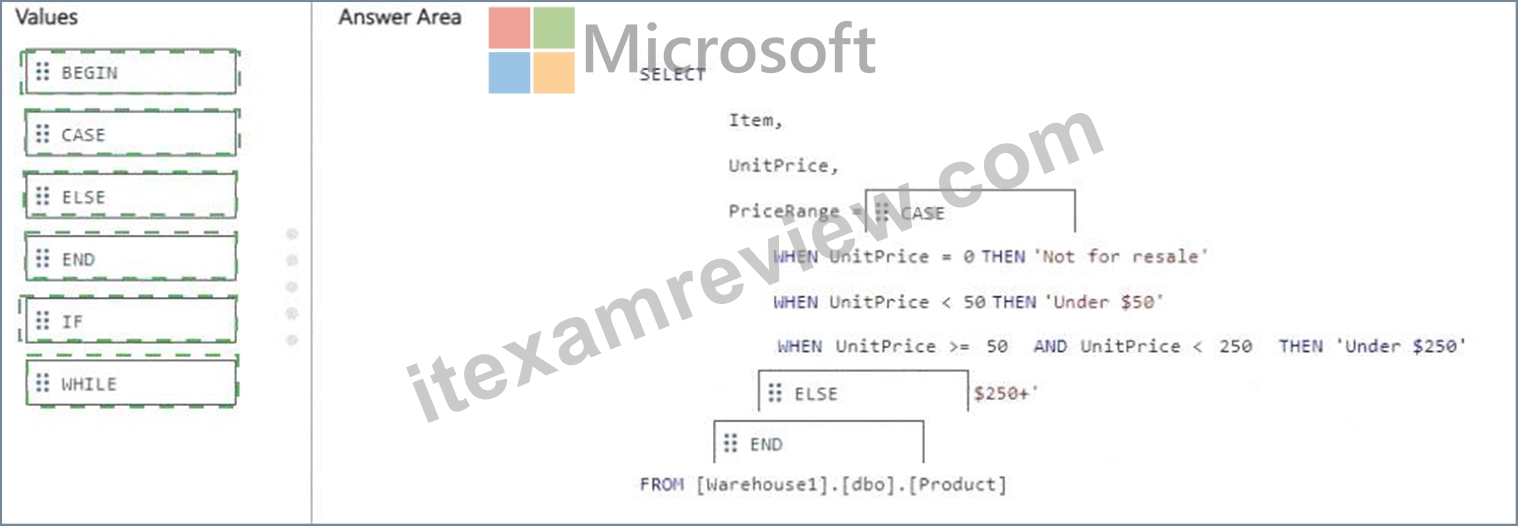
Explanation: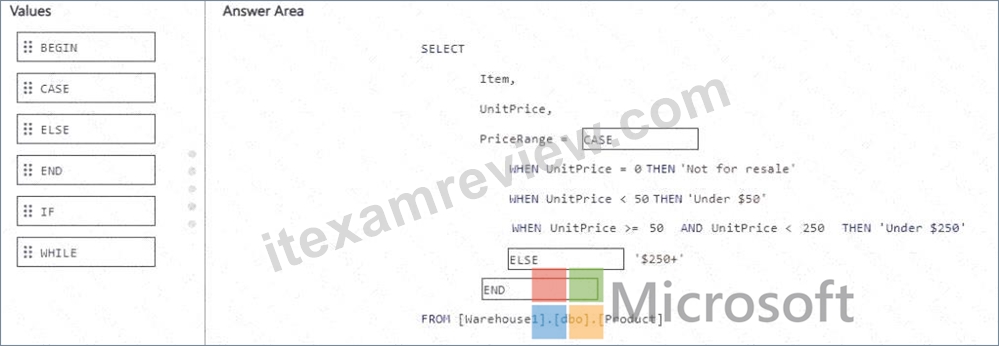
Comprehensive Detailed Explanation
We need to create a computed column PriceRange based on the UnitPrice column in the dbo.Product table.
Step 1: Requirements
If UnitPrice = 0 # " Not for resale "
If UnitPrice < 50 # " Under $50 "
If UnitPrice > = 50 AND UnitPrice < 250 # " Under $250 "
Otherwise # " $250+ "
This matches a CASE expression in T-SQL.
Step 2: CASE Expression Structure
The syntax is:
CASE
WHEN condition THEN result
WHEN condition THEN result
ELSE result
END
Step 3: Apply to Problem
SELECT
Item,
UnitPrice,
PriceRange = CASE
WHEN UnitPrice = 0 THEN ' Not for resale '
WHEN UnitPrice < 50 THEN ' Under $50 '
WHEN UnitPrice > = 50 AND UnitPrice < 250 THEN ' Under $250 '
ELSE ' $250+ '
END
FROM [Warehouse1].[dbo] .[Product];
Step 4: Why This is Correct
CASE starts the conditional evaluation.
ELSE handles the default branch ($250+).
END closes the expression.
Meets all requirements exactly.
References
CASE expression in T-SQL
Computed columns in T-SQL
NEW QUESTION # 116
You are the administrator of a Fabric workspace that contains a lakehouse named Lakehouse1.
Lakehouse1 contains the following tables:
Table1: A Delta table created by using a shortcut
Table2: An external table created by using Spark
Table3: A managed table
You plan to connect to Lakehouse1 by using its SQL endpoint.
What will you be able to do after connecting to Lakehouse1?
Answer: C
NEW QUESTION # 117
Hotspot Question
You have a Fabric tenant that contains a warehouse named Warehouse1. Warehouse1 contains a fact table named FactSales that has one billion rows.
You run the following T-SQL statement.
CREATE TABLE test.FactSales AS CLONE OF Dbo.FactSales;
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.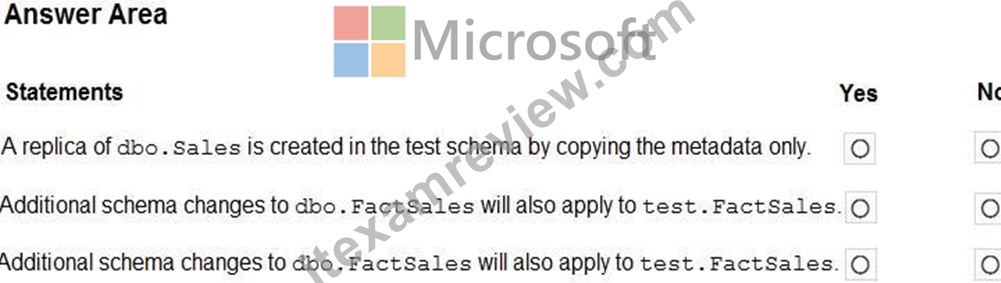
Answer:
Explanation: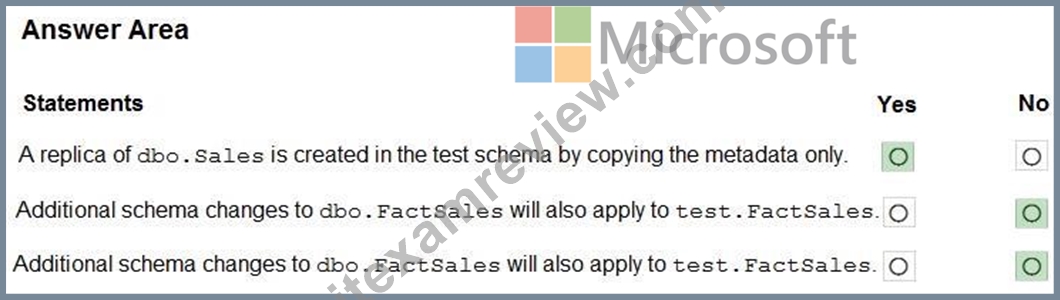
Explanation:
The AS CLONE AS creates a replica of the original table by copying the metadata (no data).
The two copies are independent therefore any changes will not be inherited.
https://learn.microsoft.com/en-us/fabric/data-warehouse/clone-table
NEW QUESTION # 118
......
DP-600 Questions Exam: https://www.itexamreview.com/DP-600-exam-dumps.html
What's more, part of that ITexamReview DP-600 dumps now are free: https://drive.google.com/open?id=1453Lyo_MSMCG4AHG_pFR1drqEWjLWBIB