P.S. Free & New DAA-C01 dumps are available on Google Drive shared by Itexamguide: https://drive.google.com/open?id=1P6SqFSjnR-xmz6KeHOF9UZo3AtnXHEXZ
In order to meet the time requirement of our customers, our experts carefully designed our DAA-C01 test torrent to help customers pass the exam in a lot less time. If you purchase our DAA-C01 guide torrent, we can make sure that you just need to spend twenty to thirty hours on preparing for your exam before you take the exam, it will be very easy for you to save your time and energy. So do not hesitate and buy our DAA-C01 study torrent, we believe it will give you a surprise, and it will not be a dream for you to pass your SnowPro Advanced: Data Analyst Certification Exam exam and get your certification in the shortest time.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and Present Data | 10–15% | - Data visualization and reporting - Align outputs with business requirements - Snowsight dashboards and sharing results |
| Use Built-in Functions and Create UDFs | 10–15% | - User-Defined Functions (UDFs) - Scalar, aggregate, table, system functions |
| Perform Simple Data Transformations for Analysis | 15–20% | - Data cleansing, standardization, type conversion - Handling NULLs and structuring datasets - Views, materialized views, CTEs |
| Perform Predictive Analysis | 5–10% | - Using Snowflake ML and built-in analytics - Forecasting and predictive modeling |
| Perform Descriptive and Diagnostic Analysis | 10–15% | - Exploratory and ad-hoc analysis - Statistical summarization and trend analysis - Anomaly detection and root cause analysis |
| Prepare and Load Data | 15–20% | - External tables and data validation - File formats: CSV, JSON, Parquet, Avro - Data ingestion methods: COPY INTO, stages, Snowpipe |
| Build and Troubleshoot Advanced SQL Queries | 20–25% | - Complex joins, subqueries, window functions - Semi-structured data processing - Query optimization and troubleshooting |
>> Test Snowflake DAA-C01 Dump <<
Itexamguide DAA-C01 exam dumps offer a full refund if you cannot pass DAA-C01 certification on your first try. This is a risk-free guarantee currently enjoyed by our more than 90,000 clients. We can assure that you can always count on our braindumps material. We are proud to say that our DAA-C01 Exam Dumps material to reduce your chances of failing the DAA-C01 certification. Therefore, you are not only saving a lot of time but money as well.
NEW QUESTION # 18
Your organization stores clickstream data in Parquet files in an external stage 's3://your-bucket/clickstreamP. The data includes nested JSON structures representing user activity. You need to create a Snowflake table to query this data efficiently, extracting specific fields from the nested JSON. The challenge is to optimize query performance by leveraging Parquet's columnar storage and schema evolution capabilities. Which of the following approaches offers the BEST combination of performance and flexibility for querying the data in Snowflake, considering potential schema changes in the Parquet files over time?
Answer: B
Explanation:
Materialized Views offer the best performance as they pre-compute and store the results, leveraging Snowflake's caching. They also adapt to schema changes in underlying Parquet files (within limits). External tables alone can be slow because of on-the-fly processing. Loading into VARIANT loses the advantage of Parquet's columnar structure. Predefined columns are rigid and don't handle schema evolution well. Creating standard views on external tables also does not provide the pre-computed benefits of the materialized views.
NEW QUESTION # 19
A data analyst is tasked with identifying the top 3 performing sales representatives in each region based on their total sales amount. The sales data is stored in a table named 'sales data" with columns 'region', 'sales_rep', and 'sales_amount'. Which Snowflake SQL statement(s) would efficiently achieve this?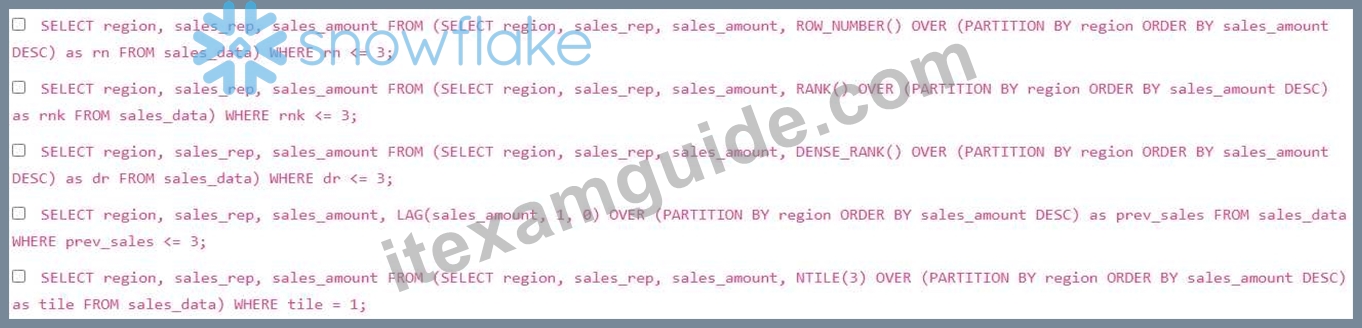
Answer: A,B,C
Explanation:
Options A, B, and C correctly utilize window functions to rank sales representatives within each region. assigns a unique rank, assigns the same rank to ties and skips the subsequent ranks, and 'DENSE RANK()' assigns the same rank to ties but does not skip ranks. All three can be used with a 'WHERE clause to filter for the top 3. Option D incorrectly uses 'LAG' and doesn't achieve the desired ranking. Option E uses 'NTILE' which divides the rows into three groups; filtering 'tile = 1' might not always return the top three based on sales.
NEW QUESTION # 20
You are tasked with aggregating website clickstream data in Snowflake to identify the most popular product categories per region on a daily basis. The clickstream data is stored in a table named 'clickstream eventS with columns: 'event_time', 'user id', 'product id', 'region', and 'category'. You need to create a solution that efficiently identifies the top 3 categories for each region on each day. Which approach offers the best performance and scalability considering the dataset size is expected to grow significantly?
Answer: D
Explanation:
Option D is the most efficient and scalable because it leverages Snowflake's built-in window functions (DENSE_RANK) for efficient ranking within partitions (region and day). Window functions are optimized for parallel processing. DENSE RANK handles ties appropriately (assigning the same rank to tied categories). Options A is similar but DENSE_RANK is better for the case of ties. Option B would be slow and not scalable due to the iterative nature of stored procedures. Option C is inefficient due to the creation of temporary tables and JOIN operations. Option E offloads the crucial filtering to external tools, impacting performance.
NEW QUESTION # 21
You have a Snowflake table 'CUSTOMER ORDERS with columns 'CUSTOMER ID', 'ORDER DATE, and 'ORDER AMOUNT. You need to calculate the cumulative sum of 'ORDER AMOUNT' for each customer, ordered by 'ORDER DATE. However, due to potential late-arriving data, you also need to implement a windowing function that resets the cumulative sum if there's a gap of more than 30 days between consecutive orders for a customer. Which SQL query best accomplishes this?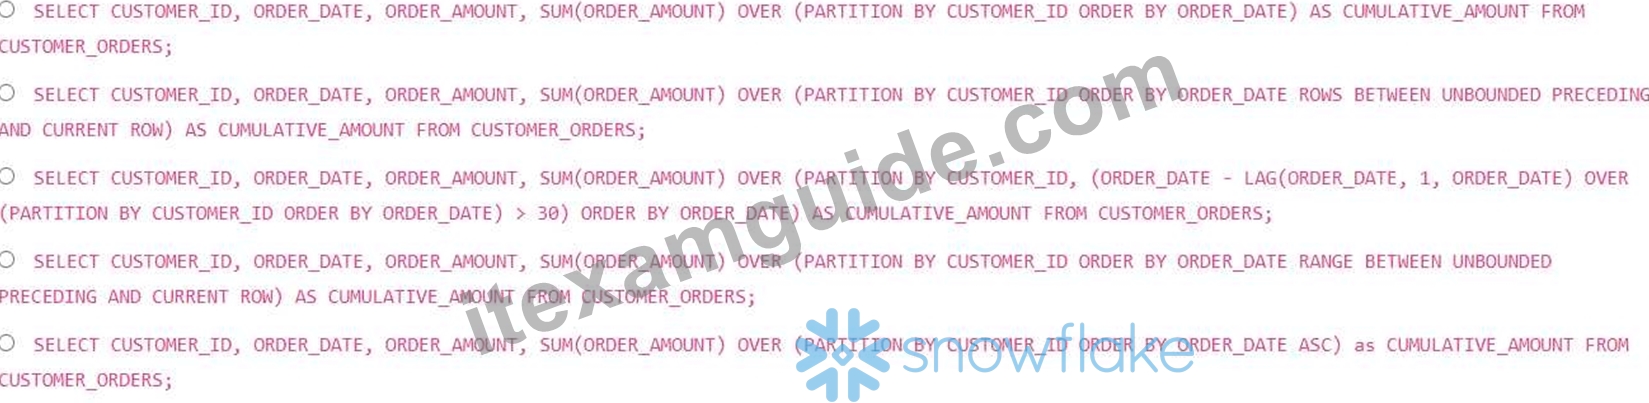
Answer: C
Explanation:
Option C correctly uses a conditional partitioning approach. UG(ORDER DATE, 1, ORDER DATE) OVER (PARTITION BY CUSTOMER_ID ORDER BY ORDER_DATE)' calculates the previous order date for each customer. (ORDER_DATE - 1, ORDER DATE) OVER (PARTITION BY CUSTOMER ID ORDER BY ORDER DATE) > 30)' creates a boolean expression that is true when the difference between consecutive order dates exceeds 30 days. This boolean expression is then used as a secondary partition key, effectively restarting the cumulative sum whenever a gap of more than 30 days occurs. The primary partition is still 'CUSTOMER ID' , ensuring sums are calculated within each customer's order history. The ordering of 'ORDER_DATE is essential for the cumulative sum to be calculated chronologically.
NEW QUESTION # 22
What potential problem can be identified in the Query profile below?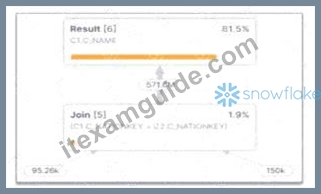
Answer: D
Explanation:
The provided image shows a specific section of a Snowflake Query Profile, which is a visual representation of the execution plan and the actual performance of a query. Analyzing this profile is a critical skill for a Data Analyst to identify performance bottlenecks.
1. Identifying the Exploding Join: The most striking evidence in this profile is the relationship between the input and output row counts of the Join [5] operator.
* Input Row Counts: The join receives approximately 95.26k rows from one branch and 150k rows from the other.
* Output Row Count: The join produces a staggering 571.6M rows.
When a join operation produces a significantly larger number of rows than the sum of its inputs, it is known as an exploding join (or a "Cartesian product-like" behavior). This typically occurs when the join condition is not restrictive enough or when there are many-to-many relationships with duplicate keys in both joining tables. In this specific case, joining on C1.C_NATIONKEY = C2.C_NATIONKEY has caused the row count to balloon from thousands to over half a billion.
2. Impact on Performance: Exploding joins consume excessive CPU and memory resources to process the massive intermediate result set. This often leads to secondary problems like spilling (Option A), where the data exceeds the virtual warehouse's memory and must be written to disk. However, the profile clearly identifies the join itself as the root cause.
Evaluating the Options:
* Option A is a symptom, but the visual evidence of row expansion directly points to the join logic itself.
* Option C (inefficient pruning) would be identified by a high percentage of partitions scanned in the Table Scan nodes, not by a row count explosion after a join.
* Option D is irrelevant; while foreign keys can help the optimizer, their absence doesn't cause this specific visual profile on its own.
* Option B is the 100% correct answer. The "exploded" arrow indicating 571.6M rows leaving a join fed by significantly smaller inputs is the textbook definition of an exploding join.
NEW QUESTION # 23
......
So we can say that the SnowPro Advanced: Data Analyst Certification Exam (DAA-C01) practice test questions are real, valid, and updated and these will greatly help you in DAA-C01 exam preparation. The availability of SnowPro Advanced: Data Analyst Certification Exam (DAA-C01) exam questions in three different formats, free demo download facility, affordable price, free three months updated DAA-C01 Exam Questions download facility, and verified and real SnowPro Advanced: Data Analyst Certification Exam (DAA-C01) exam questions are the top features of Itexamguide DAA-C01 exam questions.
DAA-C01 Dumps Reviews: https://www.itexamguide.com/DAA-C01_braindumps.html
DOWNLOAD the newest Itexamguide DAA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1P6SqFSjnR-xmz6KeHOF9UZo3AtnXHEXZ