Valid Test Databricks Databricks-Certified-Professional-Data-Engineer Testking & Braindump Databricks-Certified-Professional-Data-Engineer Free

Our Databricks-Certified-Professional-Data-Engineer test guide keep pace with contemporary talent development and makes every learner fit in the needs of the society. There is no doubt that our Databricks-Certified-Professional-Data-Engineer latest question can be your first choice for your relevant knowledge accumulation and ability enhancement. Moreover, Databricks-Certified-Professional-Data-Engineer exam questions have been expanded capabilities through partnership with a network of reliable local companies in distribution, software and product referencing for a better development. That helping you pass the Databricks-Certified-Professional-Data-Engineer Exam with our Databricks-Certified-Professional-Data-Engineer latest question successfully has been given priority to our agenda.
Databricks Certified Professional Data Engineer certification is a valuable credential for data engineers who work with Databricks. It demonstrates that the candidate has a deep understanding of Databricks and can use it effectively to solve complex data engineering problems. Databricks Certified Professional Data Engineer Exam certification can help data engineers advance their careers, increase their earning potential, and gain recognition as experts in the field of big data and machine learning.
>> Valid Test Databricks Databricks-Certified-Professional-Data-Engineer Testking <<
Unique Features of ActualtestPDF's Databricks Databricks-Certified-Professional-Data-Engineer Exam Dumps (Desktop and Web-Based)
Software lets you customize your Databricks Databricks-Certified-Professional-Data-Engineer practice exam's duration and question numbers as per your practice needs. You just need an active internet connection to confirm the license of your product. All Windows-based computers support this Databricks Databricks-Certified-Professional-Data-Engineer practice exam software. It is similar to the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) desktop-based exam simulation software, but it requires an active internet. No extra plugins or software installations are required to take the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) web-based practice test.
Databricks Certified Professional Data Engineer certification is a valuable credential for data engineers who want to demonstrate their skills and proficiency in using Databricks for data engineering tasks. Databricks Certified Professional Data Engineer Exam certification can help data engineers to advance their careers and increase their earning potential. It can also help organizations to identify and hire skilled data engineers who can design and implement data solutions using Databricks.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q88-Q93):
NEW QUESTION # 88
The following code has been migrated to a Databricks notebook from a legacy workload:
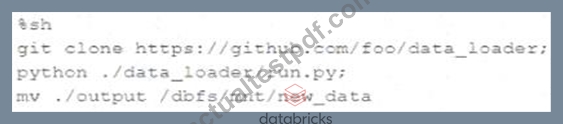
The code executes successfully and provides the logically correct results, however, it takes over 20 minutes to extract and load around 1 GB of data.
Which statement is a possible explanation for this behavior?
- A. Python will always execute slower than Scala on Databricks. The run.py script should be refactored to Scala.
- B. %sh does not distribute file moving operations; the final line of code should be updated to use %fs instead.
- C. %sh triggers a cluster restart to collect and install Git. Most of the latency is related to cluster startup time.
- D. Instead of cloning, the code should use %sh pip install so that the Python code can get executed in parallel across all nodes in a cluster.
- E. %sh executes shell code on the driver node. The code does not take advantage of the worker nodes or Databricks optimized Spark.
Answer: E
Explanation:
https://www.databricks.com/blog/2020/08/31/introducing-the-databricks-web-terminal.html The code is using %sh to execute shell code on the driver node. This means that the code is not taking advantage of the worker nodes or Databricks optimized Spark. This is why the code is taking longer to execute. A better approach would be to use Databricks libraries and APIs to read and write data from Git and DBFS, and to leverage the parallelism and performance of Spark. For example, you can use the Databricks Connect feature to run your Python code on a remote Databricks cluster, or you can use the Spark Git Connector to read data from Git repositories as Spark DataFrames.
NEW QUESTION # 89
A task orchestrator has been configured to run two hourly tasks. First, an outside system writes Parquet data to a directory mounted at /mnt/raw_orders/. After this data is written, a Databricks job containing the following code is executed:
(spark.readStream
.format("parquet")
.load("/mnt/raw_orders/")
.withWatermark("time", "2 hours")
.dropDuplicates(["customer_id", "order_id"])
.writeStream
.trigger(once=True)
.table("orders")
)
Assume that the fields customer_id and order_id serve as a composite key to uniquely identify each order, and that the time field indicates when the record was queued in the source system. If the upstream system is known to occasionally enqueue duplicate entries for a single order hours apart, which statement is correct?
- A. All records will be held in the state store for 2 hours before being deduplicated and committed to the orders table.
- B. Duplicate records enqueued more than 2 hours apart may be retained and the orders table may contain duplicate records with the same customer_id and order_id.
- C. The orders table will not contain duplicates, but records arriving more than 2 hours late will be ignored and missing from the table.
- D. The orders table will contain only the most recent 2 hours of records and no duplicates will be present.
Answer: C
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
Exact extract: "dropDuplicates with watermark performs stateful deduplication on the keys within the watermark delay." Exact extract: "Records older than the event-time watermark are considered late and may be dropped." Exact extract: "trigger(once) processes all available data once and then stops." The watermark of 2 hours bounds the deduplication state. Duplicate orders within the 2-hour window are removed; duplicates arriving later than 2 hours behind the corresponding first event are considered late and are ignored, so they won't appear, but any orders that themselves arrive later than the watermark will be dropped and thus be missing.
Reference:
NEW QUESTION # 90
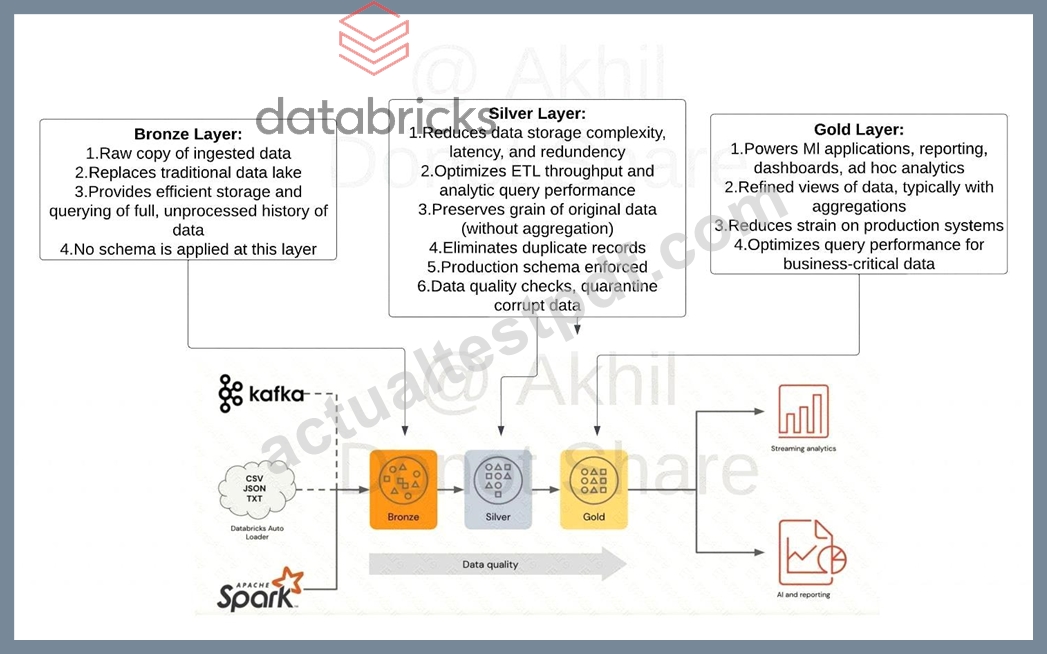
What is the main difference between the silver layer and gold layer in medallion architecture?
- A. Silver is copy of Bronze, Gold is a copy of Silver
- B. Silver may contain aggregated data, gold may preserve the granularity of original data
- C. Silver is stored in Delta Lake, Gold is stored in memory
- D. Silver optimized to perform ETL, Gold is optimized query performance
- E. Gold is optimized go perform ETL, Silver is optimized for query performance
Answer: D
Explanation:
Explanation
Medallion Architecture - Databricks
Gold Layer:
1. Powers Ml applications, reporting, dashboards, ad hoc analytics
2. Refined views of data, typically with aggregations
3. Reduces strain on production systems
4. Optimizes query performance for business-critical data
Exam focus: Please review the below image and understand the role of each layer(bronze, silver, gold) in medallion architecture, you will see varying questions targeting each layer and its purpose.
Sorry I had to add the watermark some people in Udemy are copying my content.
A diagram of a house Description automatically generated with low confidence
NEW QUESTION # 91
A data engineer is designing a Lakeflow Declarative Pipeline to process streaming order data. The pipeline uses Auto Loader to ingest data and must enforce data quality by ensuring customer_id and amount are greater than zero. Invalid records should be dropped.
Which Lakeflow Declarative Pipelines configurations implement this requirement using Python?
- A. @dlt.table
@dlt.expect("valid_customer", "customer_id IS NOT NULL")
@dlt.expect("valid_amount", "amount > 0")
def silver_orders():
return dlt.read_stream("bronze_orders") - B. @dlt.table
@dlt.expect_or_drop("valid_customer", "customer_id IS NOT NULL")
@dlt.expect_or_drop("valid_amount", "amount > 0")
def silver_orders():
return dlt.read_stream("bronze_orders") - C. @dlt.table
def silver_orders():
return (
dlt.read_stream("bronze_orders")
.expect("valid_customer", "customer_id IS NOT NULL")
.expect("valid_amount", "amount > 0")
) - D. @dlt.table
def silver_orders():
return (
dlt.read_stream("bronze_orders")
.expect_or_drop("valid_customer", "customer_id IS NOT NULL")
.expect_or_drop("valid_amount", "amount > 0")
)
Answer: D
Explanation:
Comprehensive and Detailed Explanation from Databricks Documentation:
Lakeflow Declarative Pipelines (LDP), formerly Delta Live Tables (DLT), supports enforcing data quality using expectations. Expectations can either:
Track violations (expect) → records that do not meet conditions are flagged but still included in the pipeline.
Drop violations (expect_or_drop) → records that do not meet conditions are excluded from downstream tables.
Fail pipeline on violations (expect_or_fail) → records that fail conditions stop the pipeline.
In this scenario, the requirement explicitly states that invalid records (where customer_id is null or amount ≤ 0) must be dropped. According to the official documentation, the correct method is .expect_or_drop("expectation_name", "SQL_predicate") applied on the streaming input.
Option A is correct: It uses .expect_or_drop directly within the transformation chain for both rules, ensuring records that fail are removed before writing to the silver table.
Option B incorrectly uses @dlt.expect decorators, which only track violations but do not drop invalid rows.
Option C uses .expect, which also only flags rows, not drop them.
Option D uses @dlt.expect_or_drop decorator syntax, which is not supported in Python API; expect_or_drop must be applied as a method on the DataFrame, not as a decorator.
Therefore, the correct solution is Option A, which ensures compliance by enforcing data quality and dropping invalid rows programmatically during ingestion.
NEW QUESTION # 92
Given the following error traceback (from display(df.select(3* " heartrate " ))) which shows AnalysisException: cannot resolve ' heartrateheartrateheartrate ' , which statement describes the error being raised?
- A. There is a type error because a DataFrame object cannot be multiplied.
- B. There is a type error because a column object cannot be multiplied.
- C. There is no column in the table named heartrateheartrateheartrate.
- D. There is a syntax error because the heartrate column is not correctly identified as a column.
Answer: C
Explanation:
* Exact extract: "select() expects column names or Column expressions." References: PySpark DataFrame select; Column expressions and col().
NEW QUESTION # 93
......
Braindump Databricks-Certified-Professional-Data-Engineer Free: https://www.actualtestpdf.com/Databricks/Databricks-Certified-Professional-Data-Engineer-practice-exam-dumps.html
- Get Databricks Databricks-Certified-Professional-Data-Engineer Practice Test For Quick Preparation (2026) 🔏 Open website ⇛ www.prepawaypdf.com ⇚ and search for ➽ Databricks-Certified-Professional-Data-Engineer 🢪 for free download 😫Intereactive Databricks-Certified-Professional-Data-Engineer Testing Engine
- New Databricks-Certified-Professional-Data-Engineer Test Materials 🧐 Reliable Databricks-Certified-Professional-Data-Engineer Test Camp 😲 Databricks-Certified-Professional-Data-Engineer Exam Questions Pdf 🩺 Open 《 www.pdfvce.com 》 enter ☀ Databricks-Certified-Professional-Data-Engineer ️☀️ and obtain a free download 🕖Databricks-Certified-Professional-Data-Engineer Guide Torrent
- Databricks-Certified-Professional-Data-Engineer Test Testking 🏇 Databricks-Certified-Professional-Data-Engineer Reliable Exam Vce 🎵 Valid Databricks-Certified-Professional-Data-Engineer Test Practice 🦧 Search for ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ and obtain a free download on ☀ www.pdfdumps.com ️☀️ 🥥100% Databricks-Certified-Professional-Data-Engineer Accuracy
- Databricks-Certified-Professional-Data-Engineer Guide Torrent 🤖 New Databricks-Certified-Professional-Data-Engineer Study Materials 🙃 Databricks-Certified-Professional-Data-Engineer Reliable Exam Vce 🐐 Simply search for ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ for free download on [ www.pdfvce.com ] 🕠New Databricks-Certified-Professional-Data-Engineer Test Materials
- Intereactive Databricks-Certified-Professional-Data-Engineer Testing Engine 🧄 Real Databricks-Certified-Professional-Data-Engineer Exam Dumps 😤 Databricks-Certified-Professional-Data-Engineer Guide Torrent 🔲 Search for ✔ Databricks-Certified-Professional-Data-Engineer ️✔️ and easily obtain a free download on [ www.testkingpass.com ] 🕷Valid Databricks-Certified-Professional-Data-Engineer Test Practice
- 100% Databricks-Certified-Professional-Data-Engineer Accuracy ⛲ Study Databricks-Certified-Professional-Data-Engineer Materials 🥽 Databricks-Certified-Professional-Data-Engineer Valid Braindumps Questions 🗻 ☀ www.pdfvce.com ️☀️ is best website to obtain 【 Databricks-Certified-Professional-Data-Engineer 】 for free download 🔀Valid Databricks-Certified-Professional-Data-Engineer Exam Syllabus
- Databricks Certified Professional Data Engineer Exam Online Questions - Outstanding Practice To your Databricks-Certified-Professional-Data-Engineer Exam 🎵 Search for ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ and download exam materials for free through ▛ www.vceengine.com ▟ 💳Databricks-Certified-Professional-Data-Engineer Valid Braindumps Questions
- Databricks-Certified-Professional-Data-Engineer Test Testking 📠 Databricks-Certified-Professional-Data-Engineer Reliable Exam Vce 🍎 Valid Databricks-Certified-Professional-Data-Engineer Test Practice 😎 Search for ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ and download it for free on 《 www.pdfvce.com 》 website 🍶Reliable Databricks-Certified-Professional-Data-Engineer Test Camp
- 2026 Databricks-Certified-Professional-Data-Engineer – 100% Free Valid Test Testking | Latest Braindump Databricks-Certified-Professional-Data-Engineer Free 🤏 Go to website 「 www.prep4sures.top 」 open and search for [ Databricks-Certified-Professional-Data-Engineer ] to download for free 🪓Training Databricks-Certified-Professional-Data-Engineer Materials
- 2026 Databricks-Certified-Professional-Data-Engineer – 100% Free Valid Test Testking | Latest Braindump Databricks-Certified-Professional-Data-Engineer Free 🎠 Easily obtain ▷ Databricks-Certified-Professional-Data-Engineer ◁ for free download through ➠ www.pdfvce.com 🠰 ⛪Databricks-Certified-Professional-Data-Engineer Reliable Exam Vce
- Study Databricks-Certified-Professional-Data-Engineer Materials 🍺 New Databricks-Certified-Professional-Data-Engineer Test Materials 🧊 Reliable Databricks-Certified-Professional-Data-Engineer Test Camp 😛 Search for ➤ Databricks-Certified-Professional-Data-Engineer ⮘ and download exam materials for free through “ www.pdfdumps.com ” 🌭Real Databricks-Certified-Professional-Data-Engineer Exam Dumps
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.bandlab.com, scalar.usc.edu, Disposable vapes