What's more, part of that Pass4cram AI-200 dumps now are free: https://drive.google.com/open?id=1PBi6DE1k2PIXCtxRg-Iz_WYcGL5-gdv7
Pass4cram provides with actual Microsoft AI-200 exam dumps in PDF format. You can easily download and use AI-200 PDF dumps on laptops, tablets, and smartphones. Our real AI-200 dumps PDF is useful for applicants who don't have enough time to prepare for the examination. If you are a busy individual, you can use AI-200 Pdf Dumps on the go and save time.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure, monitor, and optimize AI solutions | 20% | - Manage security and configuration
|
| Topic 2: Integrate backend services and build event-driven architectures | 25% | - Build serverless APIs and workflows
|
| Topic 3: Develop containerized AI solutions on Azure | 25% | - Implement container hosting environments
|
| Topic 4: Develop AI solutions using Azure data services | 30% | - Implement vector-enabled databases
|
>> AI-200 Latest Braindumps Sheet <<
Many people choose to sign up for the Microsoft AI-200 certification examinations in order to advance their knowledge and abilities. We offer updated and actual Microsoft AI-200 Dumps questions that will be enough to get ready for the Microsoft AI-200 test. Our Microsoft AI-200 questions are 100% genuine and will certainly appear in the next Microsoft AI-200 test.
NEW QUESTION # 135
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals.
You are using Azure Monitor Application Insights to investigate a production API. You open the Logs blade and set the time range to Last 24 hours.
An engineer recommends the following query to count requests by result code and sort the results from most frequent to least frequent:
requests
| summarize request_count = count() by resultCode
| order by request_count desc
You need to determine whether the query returns the number of requests grouped by result code and sorted from most to least frequent.
Solution: The query lists every individual request along with its result code.
Does the solution meet the goal?
Answer: B
Explanation:
The solution statement is incorrect because the KQL query does not return every individual request . The summarize operator aggregates input records according to the grouping expression. In this query, count() calculates the number of request records in each group, while by resultCode creates one group for every distinct HTTP result code represented in the selected Application Insights time range. Microsoft documents that summarize produces one output row for each distinct combination of its by expressions.
The resulting dataset therefore contains columns equivalent to resultCode and request_count, not individual request rows. The subsequent order by request_count desc sorts those aggregate groups in descending order, placing the most frequent result code first. Microsoft provides essentially the same Application Insights pattern for displaying the distribution of requests by result code: summarize request counts by result code and order the resulting counts descending.
If the intent were to list individual requests, the query would omit summarize and typically use project to select fields such as timestamp, operation name, and result code.
Therefore, because the proposed solution incorrectly describes the query as listing each individual request, the answer is No .
Study Guide references: Azure Monitor Logs; Application Insights requests; KQL summarize; count(); grouping; descending sorting.
NEW QUESTION # 136
You need to configure vector embedding updates according to the business and technical requirements.
Which information should you use? To answer, select the appropriate option in the answer area.
NOTE: Each correct selection is worth one point.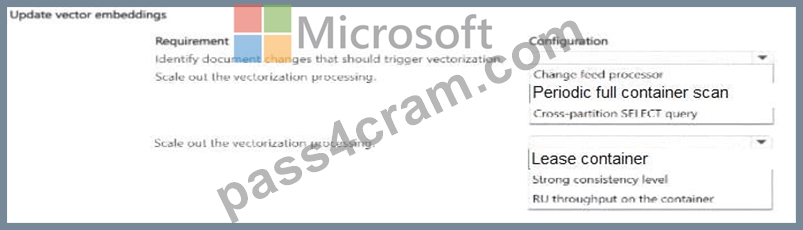
Answer:
Explanation: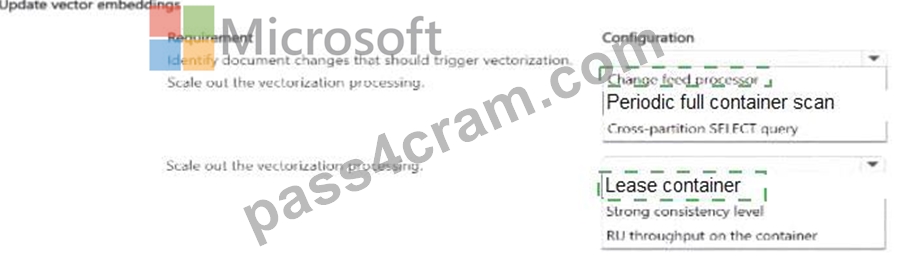
Explanation: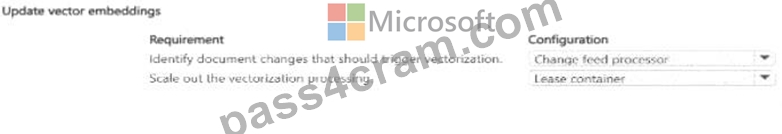
Verified Answer: Identify document changes: Change feed processor. Scale out vectorization processing:
Lease container.
Detailed Explanation: The change feed processor is designed to react to inserts and updates in a monitored Cosmos DB container, which directly matches the requirement to generate embeddings for new or changed documents. Its lease container stores processing state and coordinates work across multiple workers, allowing the processing workload to scale out without duplicating ownership of change-feed ranges. A periodic full scan would consume unnecessary RUs, and neither strong consistency nor container RU throughput is the coordination mechanism for distributed change-feed workers.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Azure Cosmos DB change feed processor
NEW QUESTION # 137
You are configuring sampling for a distributed application that sends traces to Azure Monitor. The solution must:
* Preserve upstream sampling decisions across distributed traces
* Capture all spans during local testing.
* Sample 10 percent of traces in production.
You need to apply the appropriate sampling configuration for each requirement.
What should you do? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once or not at all. You may need to move the split bar Between panes or scroll to view content.
NOTE: Each correct selection is worth one point.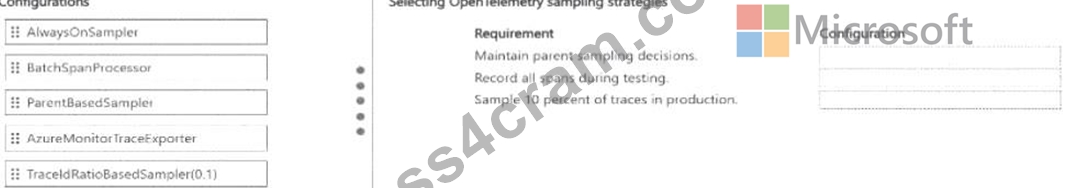
Answer:
Explanation: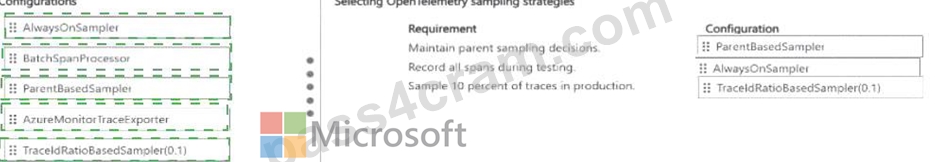
Explanation: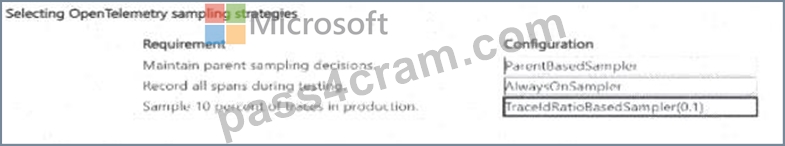
Verified Answer: Preserve parent sampling decisions: ParentBasedSampler. Capture all spans locally:
AlwaysOnSampler. Sample 10% in production: TraceIdRatioBasedSampler(0.1).
Detailed Explanation: Parent-based sampling propagates the sampling decision from the upstream parent, preventing broken sampling decisions across a distributed trace. AlwaysOnSampler records every span, which is suitable for local test environments where complete trace visibility is more important than telemetry volume. TraceIdRatioBasedSampler with 0.1 selects approximately ten percent of traces based on trace identifiers, providing deterministic fixed-ratio sampling for production. A batch span processor and an exporter control processing/export, not the sampling decision itself.
Study Guide Alignment: Security and operations: Key Vault, App Configuration, managed identity, OpenTelemetry, Azure Monitor, and KQL-based troubleshooting.
Official Microsoft Learn References: AI-200 Study Guide | OpenTelemetry sampling in Azure Monitor | Enable Azure Monitor OpenTelemetry
NEW QUESTION # 138
Drag and Drop Question
A Python API running in ACA must send distributed traces to Azure Monitor.
The API creates spans. However, no traces appear in Azure Monitor.
You need to configure the OpenTelemetry SDK pipeline to export traces to Azure Monitor.
What should you do? To answer, move the appropriate actions to the correct requirements. You may use each action once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.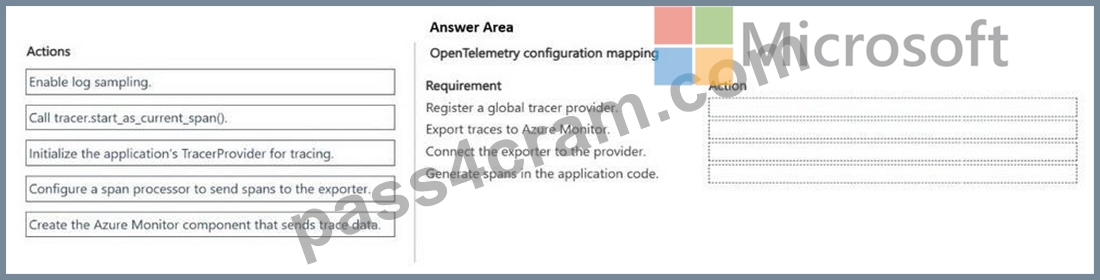
Answer:
Explanation: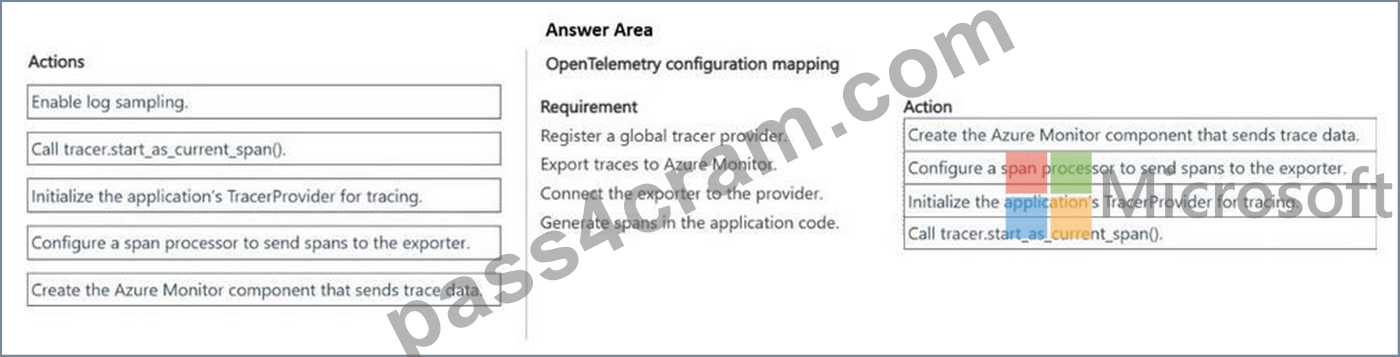
Explanation:
Box 1: Create the Azure Monitor component that sends trace data
To register a global TracerProvider in OpenTelemetry, you must call the SetTracerProvider method on the global tracer provider object, passing in your fully configured TracerProvider instance.
Box 2: Configure a span processor to send spans to the exporter
To export OpenTelemetry traces to Azure Monitor using the Python SDK, you must configure a span processor (such as BatchExportSpanProcessor), pass your initialized Azure Monitor trace exporter to it, and register that span processor with your global tracer provider.
Box 3: Initialize the application's TracerProvider for tracing
Box 4: Call tracer.start_as_current_span()
Acquire your tracer and create spans. Example code (continued from box 2 above):
tracer = trace.get_tracer(__name__)
with tracer.start_as_current_span("hello-aca-span")
Reference:
https://learn.microsoft.com/en-us/azure/durable-task/sdks/durable-task-scheduler-opentelemetry-tracing
https://learn.microsoft.com/en-us/python/api/overview/azure/monitor-opentelemetry-exporter-readme
NEW QUESTION # 139
Your Azure AI Search index must support both exact keyword matches on product SKUs and semantic similarity search on product descriptions in a single query. What should you configure?
Answer: B
Explanation:
Hybrid search in Azure AI Search combines traditional keyword (BM25) search over text fields with vector similarity search over embedding fields in a single query, giving both exact-match precision (SKUs) and semantic recall (descriptions).
NEW QUESTION # 140
......
To find the perfect Developing AI Cloud Solutions on Azure AI-200practice materials for the exam, you search and re-search without reaching the final decision and compare advantages and disadvantages with materials in the market. With systemic and methodological content within our AI-200 practice materials, they have helped more than 98 percent of exam candidates who chose our AI-200 guide exam before getting the final certificates successfully.
AI-200 Training Pdf: https://www.pass4cram.com/AI-200_free-download.html
DOWNLOAD the newest Pass4cram AI-200 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1PBi6DE1k2PIXCtxRg-Iz_WYcGL5-gdv7