Specifications of the Databricks Databricks-Machine-Learning-Professional Desktop Practice Test Software

BTW, DOWNLOAD part of PassExamDumps Databricks-Machine-Learning-Professional dumps from Cloud Storage: https://drive.google.com/open?id=1DrBkQBIYxQAfczhk5UUnXqRRc0qaCqZH
If you cannot complete the task efficiently, we really recommend using Databricks-Machine-Learning-Professional learning materials. Through the assessment of your specific situation, we will provide you with a reasonable schedule, and provide the extensible version of Databricks-Machine-Learning-Professional exam training you can quickly grasp more knowledge in a shorter time. In the same time, you will do more than the people around you. This is what you can do with Databricks-Machine-Learning-Professional Test Guide. Our Databricks-Machine-Learning-Professional learning guide is for you to improve your efficiency and complete the tasks with a higher quality. You will stand out from the crowd both in your studies and your work. The high quality of Databricks-Machine-Learning-Professional exam training is tested and you can be assured of choice.
| Section | Objectives |
|---|
| Model Deployment and Serving | - Model deployment strategies
- 1. Databricks Model Serving
- 2. Batch inference vs real-time inference
|
| Machine Learning Models and Algorithms | - Supervised learning methods
- 1. Model evaluation metrics
- 2. Classification and regression models
- Unsupervised learning methods
- 1. Dimensionality reduction
- 2. Clustering techniques
|
| MLflow and Experiment Tracking | - Model registry
- 1. Versioning and lifecycle management
- Experiment management
- 1. Model comparison and selection
- 2. Tracking runs and parameters
|
| Machine Learning Workflow on Databricks | - End-to-end ML pipelines
- 1. Pipeline construction and orchestration
- 2. Reusable ML workflows
- Data preparation and feature engineering
- 1. Data ingestion and cleaning in Databricks
- 2. Feature engineering techniques
|
| MLOps, Monitoring, and Governance | - Model monitoring
- 1. Performance tracking in production
- 2. Data drift detection
- Governance and compliance
- 1. Model lifecycle governance
- 2. Feature Store usage and management
|
>> New Databricks-Machine-Learning-Professional Test Questions <<
Examcollection Databricks Databricks-Machine-Learning-Professional Dumps, Reliable Databricks-Machine-Learning-Professional Dumps Pdf
Usually you may take months to review a professional exam, but with Databricks-Machine-Learning-Professional exam guide, you only need to spend 20-30 hours to review before the exam, and with our Databricks-Machine-Learning-Professional study materials, you will no longer need any other review materials, because our learning dumps have already included all the important test points. At the same time, Databricks-Machine-Learning-Professional Practice Engine will give you a brand-new learning method to review - let you master the knowledge in the course of the doing exercise.
Databricks Certified Machine Learning Professional Sample Questions (Q161-Q166):
NEW QUESTION # 161
A Data Scientist is training a model to predict whether a customer will purchase a new product.
They are experimenting with many algorithm types (e.g., Linear Regression, Logistic Regression, Decision Trees) and hundreds of hyperparameter combinations. They are using MLflow to track their runs, but managing and distinguishing between runs has become difficult. They need an MLFIow technique that will organize and trace these experiments and that will follow commonly- accepted design patterns. Which technique will fulfill these requirements?
- A. Set each algorithm type as a parent run and use nested runs for different hyperparameter settings within that parent run.
- B. Log runs for each algorithm type to different MLflow Tracking servers to ensure the runs do not get mixed up.
- C. Use MLflows Automatic Logging feature to reduce the number of explicit log statements within each run to increase code readability.
- D. Use AutoML to automatically test a variety of different algorithms and models.
Answer: A
Explanation:
Using parent runs for each algorithm and nested runs for the associated hyperparameter experiments follows a widely accepted MLflow experiment design pattern. This structure makes it easy to organize, compare, and trace large numbers of related runs, improving experiment management and interpretability when exploring many models and hyperparameter configurations.
NEW QUESTION # 162
A machine learning engineer is in the process of implementing a feature drift monitoring solution.
They are planning to use the following steps:
1. Measure the distributions of each feature variable in the training
set
2. Deploy a model to production
3. Measure the distributions of each feature variable in inference
4. _______
Which action should be completed as Step #4?
- A. Obtain the observed values (actual) feature values and compare to the predicted values
- B. Run a statistical test to determine if there are changes in the feature variable distribution over time
- C. Measure the latency of the model's prediction time
- D. Retrain the model based on any new feature variables that have been added to the feature set
Answer: B
Explanation:
The final step in a feature drift monitoring solution is to run a statistical test (e.g., Kolmogorov- Smirnov test) to determine whether the feature distributions in production have significantly diverged from those in the training set. This helps detect drift and maintain model reliability.
NEW QUESTION # 163
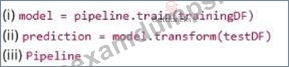
A Data Scientist is building a machine learning pipeline to classify raw text using a Logistic Regression model in Spark using Spark MLlib's Pipelines. This pipeline has three stages: the Tokenizer (to split the raw text in tokens), a HashingTF (to transform tokens into hashes) and the Logistic Regression itself (to perform the classification of texts). The Spark DataFrame with the training data is called trainingDF and the one with the test data is called testDF.
In order to do this, they use the following incomplete piece of code:

Which option correctly states:
(i) The complete command to run model training;
(ii) The complete command to execute the prediction on test data;
(iii) The object type of the model object returned by the model
training command.
Answer: D
Explanation:
In Spark MLlib, a Pipeline is trained using the fit method, which applies all estimator stages to the training DataFrame and returns a PipelineModel. Predictions are generated by calling transform on the fitted PipelineModel, which applies the full pipeline (tokenization, feature hashing, and logistic regression) to the test DataFrame.
NEW QUESTION # 164
A machine learning engineer is converting a Hyperopt-based hyperparameter tuning process from manual MLflow logging to MLflow Autologging. They are trying to determine how to manage nested Hyperopt runs with MLflow Autologging.
Which of the following approaches will create a single parent run for the process and a child run for each unique combination of hyperparameter values when using Hyperopt and MLflow Autologging?
- A. MLflow Autoloqqinq will automatically accomplish this task with Hyperopt
- B. Ensuring that a built-in model flavor is used for the model logging
- C. There is no way to accomplish nested runs with MLflow Autoloqqinq and Hyperopt
- D. Starting a manual child run within the objective function
- E. Startinq a manual parent run before calling fmin
Answer: E
NEW QUESTION # 165
Which of the following is a reason for using Jensen-Shannon (JS) distance over a Kolmogorov-Smirnov (KS) test for numeric feature drift detection?
- A. JS is more robust when working with large datasets
- B. JS is not normalized or smoothed
- C. JS does not require any manual threshold or cutoff determinations
- D. None of these reasons
- E. All of these reasons
Answer: A
NEW QUESTION # 166
......
It is simple and concise study material. The Databricks Certified Machine Learning Professional (Databricks-Machine-Learning-Professional) PDF Questions consist of actual exam questions. The Databricks-Machine-Learning-Professional PDF is a printable format and is extremely portable. You can get a hard copy or share it on your smartphone, laptop, and tablet as needed. The Databricks Databricks-Machine-Learning-Professional PDF is also regularly reviewed by our experts so that you never miss important changes from Databricks Databricks-Machine-Learning-Professional.
Examcollection Databricks-Machine-Learning-Professional Dumps: https://www.passexamdumps.com/Databricks-Machine-Learning-Professional-valid-exam-dumps.html
- Databricks-Machine-Learning-Professional Exam Braindumps 🍈 Test Databricks-Machine-Learning-Professional Result 💡 Databricks-Machine-Learning-Professional Actualtest 🪔 Easily obtain free download of ➥ Databricks-Machine-Learning-Professional 🡄 by searching on ➤ www.prepawayete.com ⮘ 🚝Valid Databricks-Machine-Learning-Professional Practice Materials
- Actual Databricks Databricks-Machine-Learning-Professional Dumps - Quick Test Preparation Tips 🧒 Open ⏩ www.pdfvce.com ⏪ and search for ➽ Databricks-Machine-Learning-Professional 🢪 to download exam materials for free ✊Valid Databricks-Machine-Learning-Professional Study Materials
- Databricks-Machine-Learning-Professional Book Pdf 🚓 Reliable Databricks-Machine-Learning-Professional Exam Camp 🍃 Databricks-Machine-Learning-Professional Download Demo 📨 Search for ✔ Databricks-Machine-Learning-Professional ️✔️ and download exam materials for free through “ www.prepawayexam.com ” 🧧Databricks-Machine-Learning-Professional Latest Test Format
- Reliable Databricks-Machine-Learning-Professional Exam Camp 🌕 Databricks-Machine-Learning-Professional Book Pdf 🆚 Pass4sure Databricks-Machine-Learning-Professional Pass Guide 🎊 Easily obtain free download of ✔ Databricks-Machine-Learning-Professional ️✔️ by searching on ⮆ www.pdfvce.com ⮄ 🕰Certification Databricks-Machine-Learning-Professional Dumps
- Quiz 2026 Databricks-Machine-Learning-Professional New Test Questions - Realistic Examcollection Databricks Certified Machine Learning Professional Dumps 🏤 Open website ( www.troytecdumps.com ) and search for ⮆ Databricks-Machine-Learning-Professional ⮄ for free download 🥃Valid Databricks-Machine-Learning-Professional Practice Materials
- Databricks-Machine-Learning-Professional valid training questions - Databricks-Machine-Learning-Professional updated practice vce - Databricks-Machine-Learning-Professional exam cram test ⬅ Search for “ Databricks-Machine-Learning-Professional ” and obtain a free download on 「 www.pdfvce.com 」 🕍Databricks-Machine-Learning-Professional Latest Test Format
- New Databricks-Machine-Learning-Professional Test Questions 100% Pass | Latest Databricks Examcollection Databricks Certified Machine Learning Professional Dumps Pass for sure 💿 Easily obtain free download of ✔ Databricks-Machine-Learning-Professional ️✔️ by searching on ➡ www.pdfdumps.com ️⬅️ 💂Databricks-Machine-Learning-Professional Download Demo
- New Databricks-Machine-Learning-Professional Exam Prep 🥟 Valid Databricks-Machine-Learning-Professional Exam Test ℹ Reliable Databricks-Machine-Learning-Professional Exam Camp 🕰 Search for [ Databricks-Machine-Learning-Professional ] and easily obtain a free download on ➠ www.pdfvce.com 🠰 🌐Valid Databricks-Machine-Learning-Professional Study Materials
- New Databricks-Machine-Learning-Professional Test Questions 100% Pass | Latest Databricks Examcollection Databricks Certified Machine Learning Professional Dumps Pass for sure ⛺ Download ➡ Databricks-Machine-Learning-Professional ️⬅️ for free by simply searching on ✔ www.verifieddumps.com ️✔️ 🎪Databricks-Machine-Learning-Professional Book Pdf
- Quiz 2026 Databricks-Machine-Learning-Professional New Test Questions - Realistic Examcollection Databricks Certified Machine Learning Professional Dumps 🕳 Enter ⏩ www.pdfvce.com ⏪ and search for ➠ Databricks-Machine-Learning-Professional 🠰 to download for free 😌Databricks-Machine-Learning-Professional Download Demo
- Valid Databricks-Machine-Learning-Professional Study Materials 😭 Valid Dumps Databricks-Machine-Learning-Professional Ebook 😱 Databricks-Machine-Learning-Professional Exams Training 🖍 Search for “ Databricks-Machine-Learning-Professional ” and download exam materials for free through ➠ www.practicevce.com 🠰 🐲Valid Dumps Databricks-Machine-Learning-Professional Ebook
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, placements.lk, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, writeablog.net, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Free 2026 Databricks Databricks-Machine-Learning-Professional dumps are available on Google Drive shared by PassExamDumps: https://drive.google.com/open?id=1DrBkQBIYxQAfczhk5UUnXqRRc0qaCqZH