Microsoft AI-500是其中的重要認證考試之一。Testpdf有資深的IT專家通過自己豐富的經驗和深厚的IT專業知識研究出IT認證考試的學習資料來幫助參加Microsoft AI-500 認證考試的人順利地通過考試。Testpdf提供的學習材料可以讓你100%通過考試而且還會為你提供一年的免費更新。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Develop multi-agent solutions in Azure | 30-35% | - Implement multi-agent orchestration
|
| Topic 2: Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
| Topic 3: Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement security for multi-agent solutions
|
| Topic 4: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Implement observability and monitoring
|
Testpdf的AI-500考古題有两种版本,即PDF版和软件版。這樣可以給你最大的方便。PDF版方便你的使用,你可以下載並且將AI-500考古題列印出來以供隨時學習。軟體版類比了真實的考試,可以讓你切身感受到Microsoft考試的氣氛。这样在考试时你就可以轻松自如地应对了。
問題 #43
You need to implement the business rule for claim Approval. Which workflow node should you use?
答案:A
解題說明:
The business rule requires human review for refunds above the stated threshold before payment can continue.
A workflow therefore needs a user or operator interaction point that pauses progress and obtains an explicit response. In the workflow options provided, Ask a question is the node that introduces that human interaction.
Invoke agent simply delegates work to another agent; it does not itself guarantee human approval. Deliver a message sends information without collecting a decision, and Go to changes control flow without obtaining authorization. Microsoft Agent Framework and Foundry workflow guidance treat human-in-the-loop approval as a first-class orchestration requirement for consequential actions. The decisive requirement is not just to notify a reviewer, but to stop automated progression until the reviewer supplies a decision. Therefore the workflow must include an interactive question/approval step before the refund-processing action can proceed for amounts over the threshold. The implementation should also preserve clear inputs and outputs around this step so that later agents receive only the information they require. This improves debuggability and keeps token, permission, and state growth under control as the workflow becomes more complex.
Official Microsoft reference: Microsoft Agent Framework - Human-in-the-loop workflows
問題 #44
You have a Microsoft Foundry multi-agent solution. The solution includes an orchestrator that uses Azure Al Search as a semantic cache to shortlist agents and invokes the top match.
You have a version-controlled repository that contains a curated dataset, expected routing, and expected responses. A pull request adds an agent named Agent 1, new sample utterances, and a changed selector prompt.
You need to configure an automated prerelease evaluation gate for the pull request. The solution must meet the following requirements:
* Validate the integrated system response after the new agent is available to orchestration.
* Validate the semantic cache retrieval quality against the expected results.
* Keep regression tests aligned with the pull request changes.
How should you configure the evaluation gate? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.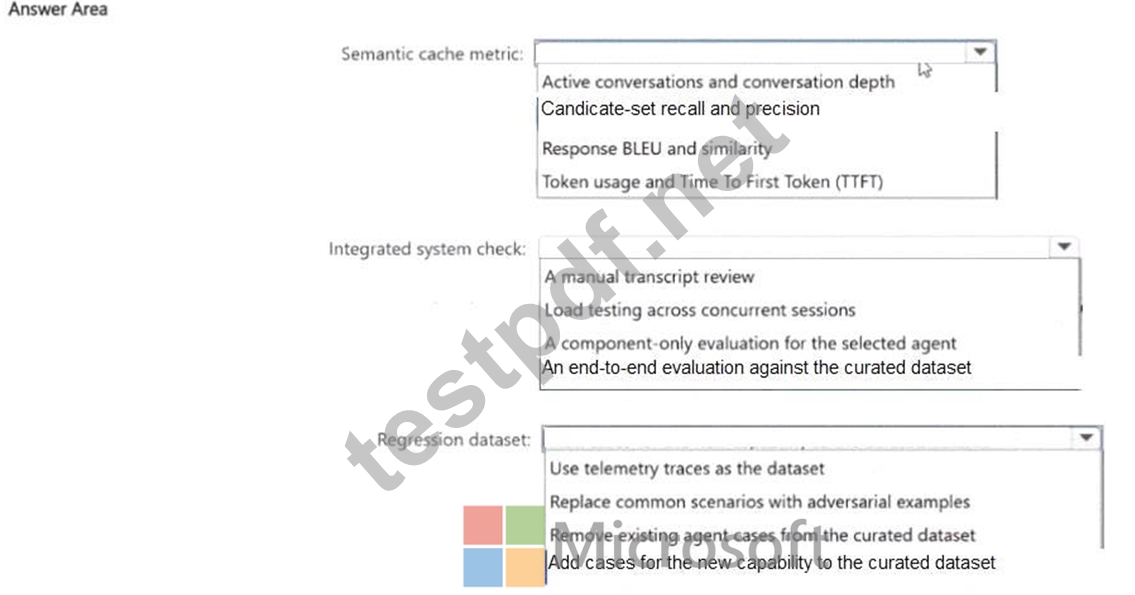
答案:
解題說明: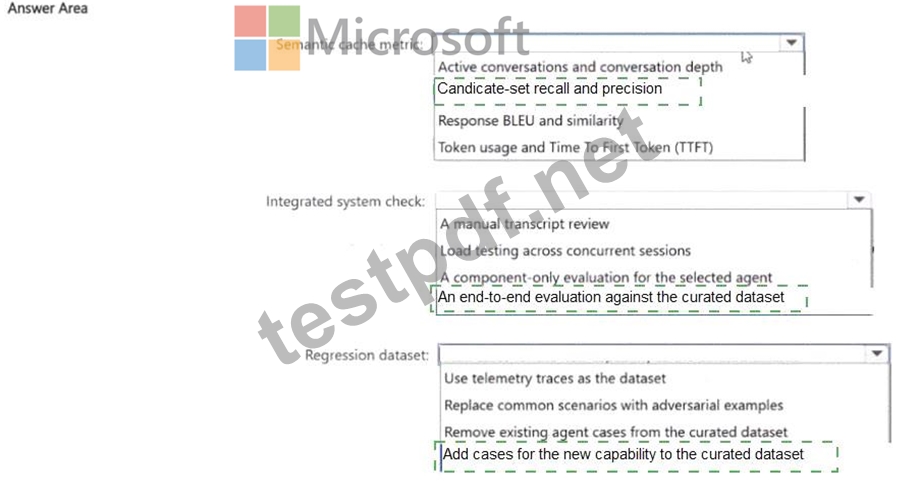
Explanation:
Semantic cache metric: Candidate-set recall and precision; Integrated system check: An end-to-end evaluation against the curated dataset; Regression dataset: Add cases for the new capability to the curated dataset.
The semantic cache is acting as a retrieval/shortlisting component, so recall and precision are the appropriate measures of whether expected agent candidates are surfaced and whether irrelevant candidates are avoided.
The pull request also changes the selector prompt and adds an agent, so component-only tests are insufficient; an end-to-end evaluation must exercise retrieval, routing, the new agent, and final response generation together. Finally, the version-controlled regression dataset should evolve with the capability. Adding representative cases for the new agent keeps expected routing and responses aligned with the code and prompt changes in the pull request. Microsoft Foundry evaluation guidance treats curated datasets as reusable regression assets for CI/CD quality gates. Together, these three selections test retrieval quality, integrated behavior, and regression coverage at the correct layers. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - evaluation datasets and CI/CD evaluation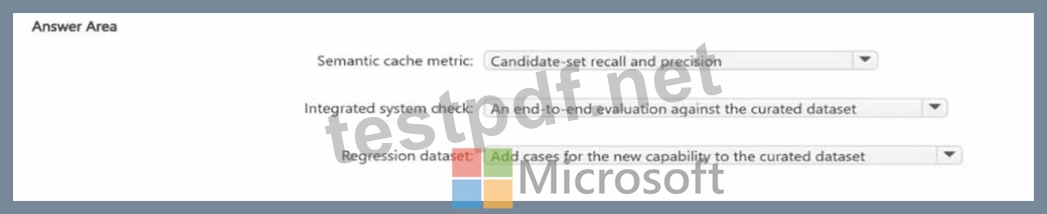
問題 #45
You have a Microsoft Foundry project that contains a multi-agent customer support solution. The solution includes a final response agent.
You need to provide reviewers with the ability to assess agent responses in the preview web app and record a completion score for each agent response. The solution must follow the principle of least privilege.
Which roles should you assign to the reviewers?
答案:A
解題說明:
Microsoft ' s human-evaluation guidance for the Foundry preview web app requires reviewers to have Foundry User permissions on the project plus Reader access on the Foundry account/resource. That combination gives the reviewer enough project-level access to open the agent experience and record evaluation feedback while avoiding project-management or account-management privileges. Application Insights Reader alone only grants telemetry visibility and does not provide the Foundry interaction permissions needed to score responses. Foundry User alone does not satisfy the documented account-level visibility requirement for this preview experience. Foundry Project Manager would be broader than necessary and violate the least-privilege objective. Therefore C is the documented reviewer role combination. The same configuration should be paired with auditable identity, trace, and evaluation data so reviewers can prove which principal acted, which policy was applied, and why a request was allowed or blocked. That is particularly important for production multi-agent systems with external tools. Least privilege remains the governing principle: grant only the identity, data, tool, or deployment access required for the specific operation. The selected answer preserves that boundary while still allowing the workflow to satisfy its functional requirement.
Official Microsoft reference: Microsoft Foundry - Human evaluation
問題 #46
You have a multi-agent Retrieval-Augmented Generation (RAG) solution that uses a Foundry IQ knowledge base. The solution includes a support agent and a policy agent.
You have an evaluation dataset that contains the following for each user query
* The expected source IDs
* Retrieved chunks in rank order
* The final agent response
You discover that an embedding model change and a custom analyzer change cause the failed traces shown in the following table.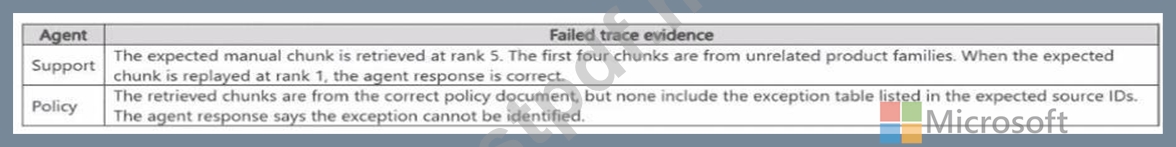
You need to isolate the failing parts of the RAG pipeline.
Which evaluator should you use for each agent? To answer, drag the appropriate evaluators to the correct agents. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.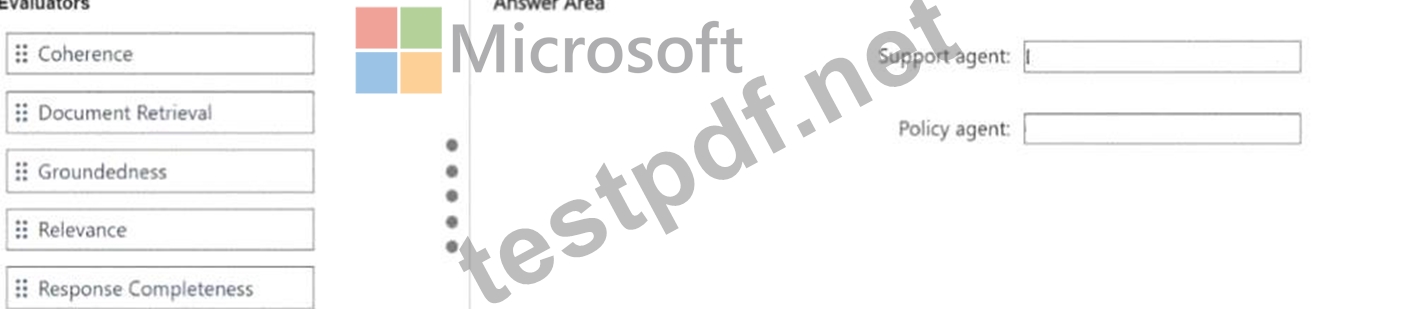
答案:
解題說明: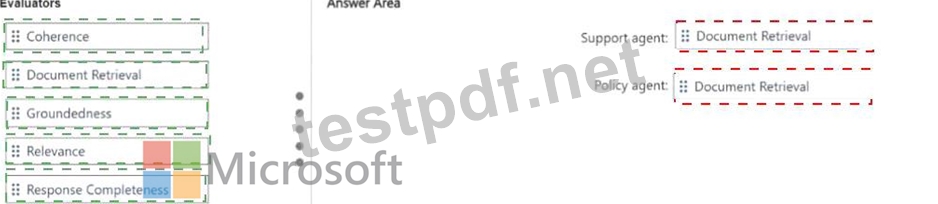
Explanation:
Support agent: Document Retrieval; Policy agent: Document Retrieval.
Both failures are retrieval failures and should therefore be diagnosed with the Document Retrieval evaluator.
The dataset includes expected source IDs and ranked retrieved chunks, which provides the retrieval ground truth required by that evaluator. For the support agent, the expected source appears too low in the ranking after unrelated chunks. For the policy agent, the required exception-table source is missing entirely.
Groundedness would evaluate whether the final response is supported by the context it actually received; it could therefore pass even when the retrieval stage failed to fetch a required source. Microsoft Foundry ' s Document Retrieval evaluator compares retrieved documents against labeled ground truth and reports ranking
/search metrics such as NDCG and Fidelity. The corrected answer is Document Retrieval for both agents. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators
問題 #47
You need to implement an advanced prompt engineering strategy to resolve the Patient Intake agent issues.
The solution must prevent hardcoding new logic into the agent ' s core prompt.
What should you do?
答案:A
解題說明:
The intake problem involves verbose, variable patient narratives and a requirement to avoid hardcoding new logic into the core prompt. Injecting dynamic context with curated few-shot examples gives the model representative demonstrations of how to identify clinically relevant symptoms while ignoring irrelevant narrative details. Microsoft AI-500 objectives explicitly include examples and dynamic context injection as advanced prompt-engineering techniques. Removing defensive guidance would weaken safety. Reducing the context window would not teach the model what information matters and could simply discard useful details.
Frequent full-model fine-tuning is operationally heavier and unnecessary for a behavior that can be demonstrated through curated examples. Dynamic few-shot context also allows the examples to be versioned and updated without rewriting the agent ' s base persona or application logic. Therefore C best addresses the extraction problem while preserving prompt lifecycle flexibility. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: AI-500 Study Guide - advanced prompt engineering
問題 #48
......
為了讓你可以確認AI-500考古題的品質,以及你是不是適合這個考古題,Testpdf的AI-500考古題的兩種版本都提供免費的部分下載。我們將一部分的AI-500試題免費提供給你,你可以在Testpdf的網站上搜索下載。體驗過之後再購買,這樣可以避免你因為不知道資料的品質而盲目購買以後覺得後悔這樣的事情。
AI-500指南: https://www.testpdf.net/AI-500.html