Your chances of passing the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification exam the first time around can be greatly improved if you attempt the DumpsTests Microsoft DP-750 practice exam. To help you succeed on your first try at the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) exam, DumpsTests has created three formats of Implementing Data Engineering Solutions Using Azure Databricks (DP-750) practice exam.
| Section | Weight | Objectives |
|---|---|---|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Prepare and process data | 30-35% | - Ingest and transform data
|
>> DP-750 Real Exam Answers <<
The DumpsTests has specially designed the Microsoft DP-750 desktop practice exam software for the self-assessment of the learned concepts. Our Microsoft DP-750 desktop practice exam software can be installed on all types of windows operating computers. This is Microsoft DP-750 practice exam for the applicant's practice that could be solved without internet access. The Microsoft DP-750 exam questions preparation products have been designed to provide ease to their customers in all aspects. Everybody can use our DP-750 Exam Questions And Answers conveniently. We provide 365 days of free updates after the date of purchase so that you can get updated Microsoft DP-750 exam questions for the DP-750 exam preparation. DumpsTests offers reliable Microsoft DP-750 exam questions and also provides a 30% exclusive discount on all Microsoft exam questions. Use coupon code ‘30OFF’ while purchasing Microsoft DP-750 exam questions preparation products.
NEW QUESTION # 59
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount != None)
Does this meet the goal?
Answer: A
Explanation:
The correct answer is B - No.
This is a common Python-to-PySpark trap. In pure Python, comparing a value to None with != works as expected. In PySpark, null comparisons follow SQL null semantics: any comparison involving NULL returns NULL (not True or False). So df.filter(df.order_amount != None) doesn't evaluate to True for non-null rows
- the comparison itself returns NULL for null values, and Spark interprets NULL in a filter as False, effectively dropping null rows. But the behaviour is undefined in edge cases and is not the documented approach.
More practically, Python's None and Spark's SQL NULL are different concepts. PySpark Column objects don't support Python's native equality/inequality semantics for null checking. The result is typically an empty DataFrame or incorrect filtering behaviour.
Always use .isNotNull() or .isNull() for null checks in PySpark column expressions. These methods are specifically designed for SQL-null-aware comparisons and produce correct, predictable results.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 60
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes records to a Delta table named Table1 by using a data quality rule named rule1 You need to meet the following requirements:
* Records that violate rule! must NOT be written to Table1. but the pipeline must continue processing valid records.
* Data engineers must be able to review expectation metrics by using minimal development effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.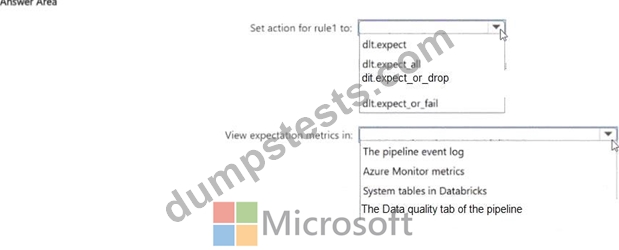
Answer:
Explanation: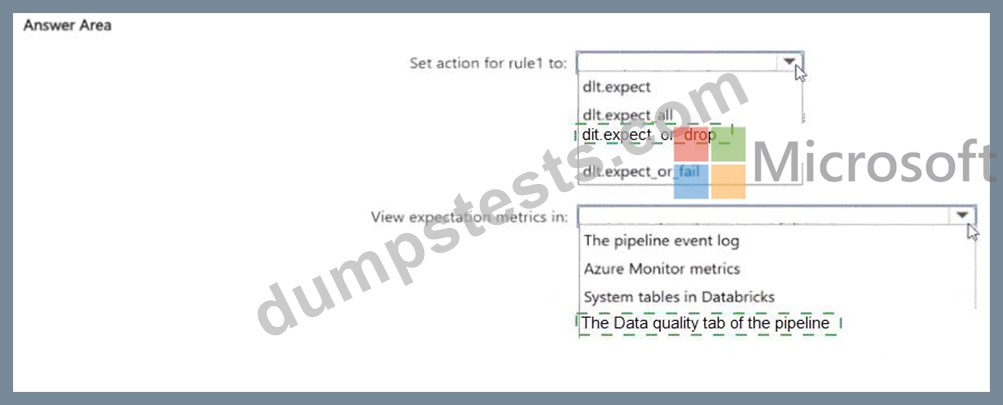
Explanation:
Two things are needed here:
For the rule enforcement: use @dlt.expect_or_drop. This drops any record that violates rule1 before it reaches Table1, while the pipeline continues processing all valid records. The table only ever receives clean data.
For reviewing metrics: the Lakeflow SDP Pipeline UI is the right tool - zero development effort required.
The pipeline graph shows expectation pass/fail counts directly on each table node, and the event log provides a detailed per-batch breakdown of how many records were dropped and why. Data engineers can inspect this at any time without writing additional monitoring queries or connecting external dashboards.
This combination is one of the strongest arguments for SDP over hand-coded Structured Streaming:
expectation observability is built in, not bolted on.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/expectations
NEW QUESTION # 61
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! contains three tasks named Task1, Task2. and Task3.
If Task1 fails, Task2 and Task3 must be prevented from running. Successfully completed tasks must NOT rerun during recovery.
You need to configure Job1 to support controlled failure handling and recovery What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.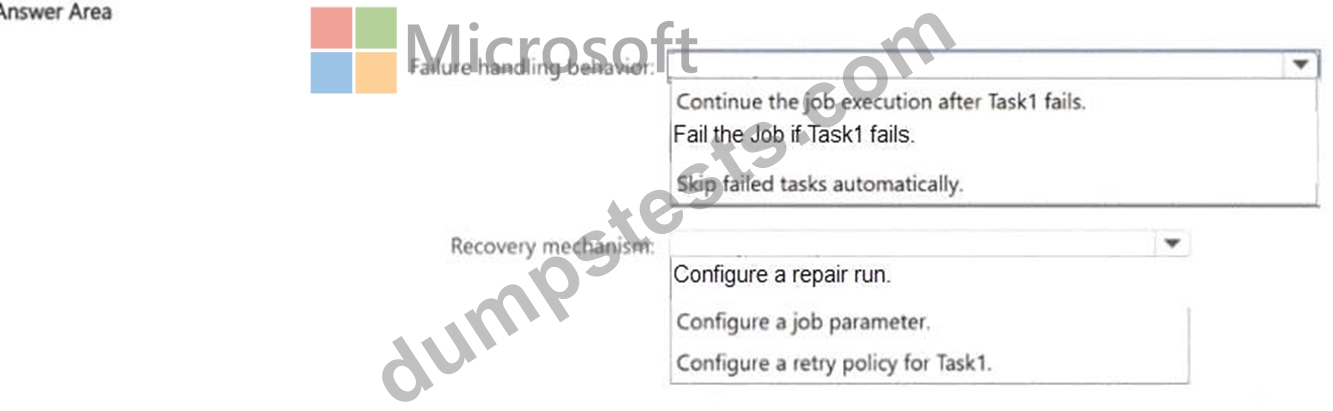
Answer:
Explanation: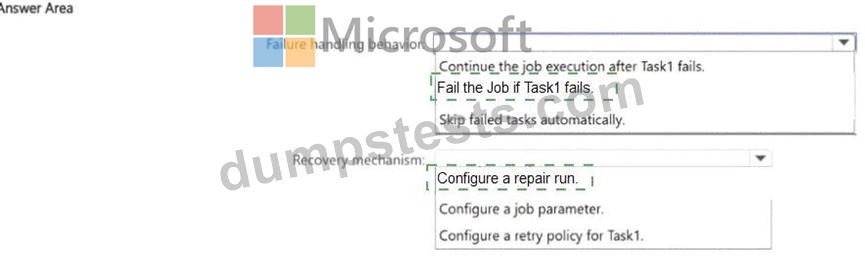
Explanation:
Two configurations are needed:
Task dependency with 'All succeeded' run condition: Set Task2 and Task3 to depend on Task1. Change the run condition on Task2 and Task3 to 'All succeeded' - this means they only execute when all their upstream dependencies (Task1) have succeeded. If Task1 fails, both downstream tasks are skipped automatically, not run with failed inputs.
Repair run for recovery: Lakeflow Jobs' Repair Run feature lets you re-execute only the tasks that failed (Task1 in this case) and their dependents (Task2 and Task3 if they were skipped), while skipping Task1 and any other tasks that already completed successfully. Successfully completed tasks are never re-executed during repair - their results are reused as-is.
Together these provide both controlled failure propagation (nothing runs downstream of a failure) and efficient recovery.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/repair-job-failures
NEW QUESTION # 62
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job! processes raw data files stored in Azure Storage.
New files arrive at unpredictable intervals.
You need to ensure that Job1 starts automatically when new files arrive and does NOT consume compute resources when no data is available.
Which type of job trigger should you use?
Answer: C
Explanation:
The correct answer is C - File Arrival trigger.
File Arrival monitors a specified Azure Storage path and fires a job run each time a new file lands there. This ticks both requirements: Job1 starts automatically in response to new data (no human involvement), and when no files arrive, no job runs - no cluster spins up, no compute cost is incurred.
Option A (scheduled) runs at fixed intervals regardless of whether files are waiting. A quiet weekend still kicks off hourly (or daily) runs, burning compute for nothing. Option B (continuous) keeps the job running perpetually, consuming resources even during long gaps between file arrivals - exactly what 'does NOT consume compute resources when no data is available' rules out. Option D (manual) requires a person to trigger every run, which is unsuitable for unpredictable arrival patterns.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/triggers#file-arrival-trigger
NEW QUESTION # 63
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains two Delta tables named Table1 and Table2 of the same data type.
Table1 contains a column named Columnl. Table2 contains a column named Column2. You run the following query.
SELECT Column1
FROM Table1
GROUP BY Column1
HAVING COUNT(") > 1
INTERSECT
SELECT C0lumn2
FROM Table2
GROUP BY Column2
HAVING COUNT(') > 1;
What occurs when you run the query?
Answer: C
Explanation:
The correct answer is B - values appear in both tables more than once.
Reading the query from the inside out: each subquery identifies values that appear more than once within their own table. The first subquery returns Column1 values that are duplicated in Table1. The second returns Column2 values that are duplicated in Table2. INTERSECT then returns only the values that appear in both result sets - meaning values that are duplicated in Table1 AND also duplicated in Table2.
Option A describes a UNION result (values in either table), not INTERSECT. Option C only considers duplicates in Table1, ignoring the Table2 condition - that would be the first subquery in isolation. Option D describes values exclusive to Table2 (EXCEPT or MINUS), the opposite of INTERSECT's requirement that values appear in both sets.
INTERSECT always requires membership in both operands - that's its fundamental definition in standard SQL.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/sql-ref-syntax-qry-select- setops
NEW QUESTION # 64
......
Being anxious for the exam ahead of you? Have a look of our DP-750 practice materials please. Presiding over the line of DP-750 practice materials over ten years, our experts are proficient as elites who made our DP-750 practice materials, and it is their job to officiate the routines of offering help for you. All points are predominantly related with the exam ahead of you. Every page is full of well-turned words for your reference related wholly with the real exam.
Test DP-750 Study Guide: https://www.dumpstests.com/DP-750-latest-test-dumps.html