Databricks Certified-Data-Engineer-Professional Exam Flashcards, New Study Certified-Data-Engineer-Professional Questions

What's more, part of that TestKingFree Certified-Data-Engineer-Professional dumps now are free: https://drive.google.com/open?id=1CQbcqX19agQhmAPKcq8j2yKdXxvkkzPe
If you come to our website to choose Certified-Data-Engineer-Professional study materials, you will enjoy humanized service. Firstly, we have chat windows to wipe out your doubts about our Certified-Data-Engineer-Professional study materials. You can ask any question about our study materials. All of our online workers are going through special training. They are familiar with all details of our Certified-Data-Engineer-Professional Study Materials. Also, you have easy access to our free demo. Once you apply for our free trials of the study materials, our system will quickly send it via email.
| Section | Objectives |
|---|
| Topic 1: Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Topic 2: Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Share live Lakehouse data with external computing platforms
- 2. Configure Databricks-to-Databricks Sharing
- 3. Configure sharing with external platforms using the open sharing protocol
|
| Topic 3: Ensuring Data Security and Compliance | - Compliance
- 1. Develop data purging solutions according to data retention policies
- 2. Implement pipelines that detect and mask personally identifiable information
- Data Security
- 1. Use ACLs to secure workspace objects and enforce least privilege
- 2. Use row filters and column masks for sensitive data
- 3. Apply anonymization and pseudonymization techniques
|
| Topic 4: Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Use control flow operators in pipeline components
- 2. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 3. Compare streaming tables and materialized views
- 4. Develop unit and integration tests for data processing code
- 5. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 6. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 7. Use APPLY CHANGES APIs for change data capture
- 8. Configure environments, dependencies, memory, and retry behavior
- Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDFs
- 2. Manage and troubleshoot third-party library installations and dependencies
- 3. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
|
| Topic 5: Monitoring and Alerting | - Monitoring
- 1. Use Query Profiler and Spark UI to monitor workloads
- 2. Use system tables for resource, cost, audit, and workload monitoring
- 3. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 4. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
|
| Topic 6: Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- Advanced Data Transformation
- 1. Write efficient Spark SQL and PySpark transformations
- 2. Apply window functions, joins, and aggregations to large datasets
|
| Topic 7: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Build append-only pipelines for batch and streaming data using Delta
- 2. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 3. Ingest data from message buses and cloud storage
|
| Topic 8: Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Optimize data layout using Liquid Clustering
|
| Topic 9: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 3. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
|
| Topic 10: Cost & Performance Optimisation | - Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
- Delta Optimization
- 1. Use Change Data Feed to address streaming table limitations and improve latency
- 2. Apply data skipping and file pruning techniques
- 3. Understand deletion vectors and liquid clustering
|
>> Databricks Certified-Data-Engineer-Professional Exam Flashcards <<
New Study Certified-Data-Engineer-Professional Questions - Certified-Data-Engineer-Professional Exam Sample
Only 20-30 hours are needed for you to learn and prepare our Certified-Data-Engineer-Professional test questions for the exam and you will save your time and energy. No matter you are the students or the in-service staff you are busy in your school learning, your jobs or other important things and can’t spare much time to learn. But you buy our Certified-Data-Engineer-Professional exam materials you will save your time and energy and focus your attention mainly on your most important thing. You only need several hours to learn and prepare for the exam every day. We choose the most typical questions and answers which seize the focus and important information and the questions and answers are based on the real exam. So you can master the most important Certified-Data-Engineer-Professional Exam Torrent in the shortest time and finally pass the exam successfully.
Databricks Certified Data Engineer Professional Sample Questions (Q96-Q101):
NEW QUESTION # 96
Which statement describes a key benefit of an end-to-end test?
- A. It makes it easier to automate your test suite
- B. It pinpoint errors in the building blocks of your application.
- C. It closely simulates real world usage of your application.
- D. It provides testing coverage for all code paths and branches.
Answer: C
Explanation:
End-to-end testing is a methodology used to test whether the flow of an application, from start to finish, behaves as expected. The key benefit of an end-to-end test is that it closely simulates real- world, user behavior, ensuring that the system as a whole operates correctly.
NEW QUESTION # 97
A junior member of the data engineering team is exploring the language interoperability of Databricks notebooks. The intended outcome of the below code is to register a view of all sales that occurred in countries on the continent of Africa that appear in the geo_lookup table.
Before executing the code, running SHOW TABLES on the current database indicates the database contains only two tables: geo_lookup and sales.
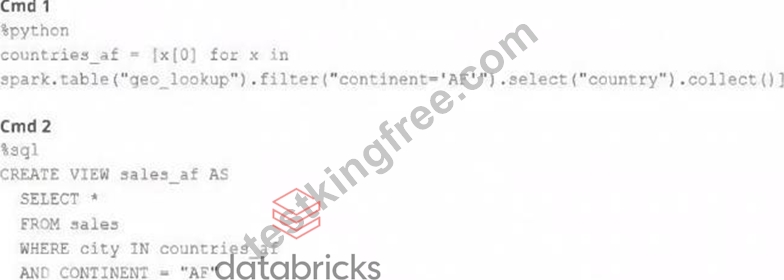
Which statement correctly describes the outcome of executing these command cells in order in an interactive notebook?
- A. Cmd 1 will succeed. Cmd 2 will search all accessible databases for a table or view named countries af: if this entity exists, Cmd 2 will succeed.
- B. Both commands will fail. No new variables, tables, or views will be created.
- C. Cmd 1 will succeed and Cmd 2 will fail, countries at will be a Python variable containing a list of strings.
- D. Cmd 1 will succeed and Cmd 2 will fail, countries at will be a Python variable representing a PySpark DataFrame.
- E. Both commands will succeed. Executing show tables will show that countries at and sales at have been registered as views.
Answer: C
Explanation:
This is the correct answer because Cmd 1 is written in Python and uses a list comprehension to extract the country names from the geo_lookup table and store them in a Python variable named countries af. This variable will contain a list of strings, not a PySpark DataFrame or a SQL view.
Cmd 2 is written in SQL and tries to create a view named sales af by selecting from the sales table where city is in countries af. However, this command will fail because countries af is not a valid SQL entity and cannot be used in a SQL query. To fix this, a better approach would be to use spark.sql() to execute a SQL query in Python and pass the countries af variable as a parameter.
NEW QUESTION # 98
Review the following error traceback:

Which statement describes the error being raised?
- A. There is a type error because a column object cannot be multiplied.
- B. There is no column in the table named heartrateheartrateheartrate
- C. The code executed was PvSoark but was executed in a Scala notebook.
- D. There is a syntax error because the heartrate column is not correctly identified as a column.
- E. There is a type error because a DataFrame object cannot be multiplied.
Answer: B
Explanation:
https://sparkbyexamples.com/spark/spark-cannot-resolve-given-input-columns/
NEW QUESTION # 99
A data engineer needs to productionize a new Spark application written by teammate. This application has numerous external dependencies, including libraries, and requires custom environment variables and Spark configuration parameters to be set. Which two methods will help the data engineer accomplish the task? (Choose two.)
- A. Add libraries to compute policies
- B. Install libraries on DBFS
- C. Use compute policies to set system properties, environment variables, and Spark configuration parameters.
- D. Create init scripts on DBFS.
- E. Use secrets in init scripts to store configuration data
Answer: C,D
Explanation:
Compute policies allow centrally defining and enforcing Spark configuration parameters, system properties, and environment variables required by the application, ensuring consistent production settings. Init scripts enable installing external dependencies and performing custom environment setup at cluster startup, making them essential for productionizing Spark applications with complex dependency and configuration requirements.
NEW QUESTION # 100
The following code has been migrated to a Databricks notebook from a legacy workload:
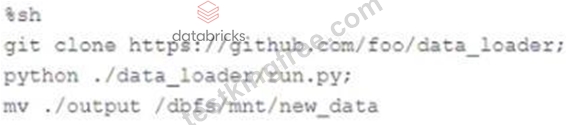
The code executes successfully and provides the logically correct results, however, it takes over
20 minutes to extract and load around 1 GB of data.
Which statement is a possible explanation for this behavior?
- A. %sh triggers a cluster restart to collect and install Git. Most of the latency is related to cluster startup time.
- B. %sh does not distribute file moving operations; the final line of code should be updated to use %fs instead.
- C. Instead of cloning, the code should use %sh pip install so that the Python code can get executed in parallel across all nodes in a cluster.
- D. %sh executes shell code on the driver node. The code does not take advantage of the worker nodes or Databricks optimized Spark.
- E. Python will always execute slower than Scala on Databricks. The run.py script should be refactored to Scala.
Answer: D
Explanation:
https://www.databricks.com/blog/2020/08/31/introducing-the-databricks-web-terminal.html The code is using %sh to execute shell code on the driver node. This means that the code is not taking advantage of the worker nodes or Databricks optimized Spark. This is why the code is taking longer to execute. A better approach would be to use Databricks libraries and APIs to read and write data from Git and DBFS, and to leverage the parallelism and performance of Spark. For example, you can use the Databricks Connect feature to run your Python code on a remote Databricks cluster, or you can use the Spark Git Connector to read data from Git repositories as Spark DataFrames.
NEW QUESTION # 101
......
It is convenient for our consumers to check Databricks Certified-Data-Engineer-Professional exam questions free of charge before purchasing the Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional practice exam. To make the Databricks Certified-Data-Engineer-Professional exam questions content up-to-date for free of cost up to 365 days after buying them, our certified trainers work strenuously to formulate the exam questions in compliance with the Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional Dumps.
New Study Certified-Data-Engineer-Professional Questions: https://www.testkingfree.com/Databricks/Certified-Data-Engineer-Professional-practice-exam-dumps.html
- Certified-Data-Engineer-Professional Exam Flashcards | Databricks New Study Certified-Data-Engineer-Professional Questions: Databricks Certified Data Engineer Professional Pass Success 🥉 ▛ www.vce4dumps.com ▟ is best website to obtain ( Certified-Data-Engineer-Professional ) for free download 😗Test Certified-Data-Engineer-Professional Vce Free
- Certified-Data-Engineer-Professional Exam Flashcards | Databricks New Study Certified-Data-Engineer-Professional Questions: Databricks Certified Data Engineer Professional Pass Success 🏆 Easily obtain free download of { Certified-Data-Engineer-Professional } by searching on ⇛ www.pdfvce.com ⇚ 😌Certified-Data-Engineer-Professional Certified Questions
- Test Certified-Data-Engineer-Professional King 🤞 New Certified-Data-Engineer-Professional Exam Prep 🆔 Certified-Data-Engineer-Professional Reliable Test Test 🦮 Copy URL ( www.dumpsquestion.com ) open and search for { Certified-Data-Engineer-Professional } to download for free ⏭Reliable Certified-Data-Engineer-Professional Test Answers
- 2026 Latest Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Flashcards 🍥 Easily obtain ➽ Certified-Data-Engineer-Professional 🢪 for free download through ▷ www.pdfvce.com ◁ 🌜Certified-Data-Engineer-Professional Exam Fees
- Certified-Data-Engineer-Professional Updated Dumps 👻 Certified-Data-Engineer-Professional Reliable Test Test 🧈 Certified-Data-Engineer-Professional Exam Fees 🛵 Search for 「 Certified-Data-Engineer-Professional 」 and obtain a free download on ▷ www.prepawayexam.com ◁ 🧎Certified-Data-Engineer-Professional Reliable Test Test
- Certified-Data-Engineer-Professional Updated CBT 🦁 Certified-Data-Engineer-Professional Certified Questions 🦼 Reliable Certified-Data-Engineer-Professional Test Tutorial 🚥 Enter ➡ www.pdfvce.com ️⬅️ and search for ➤ Certified-Data-Engineer-Professional ⮘ to download for free 🦑Test Certified-Data-Engineer-Professional Vce Free
- Databricks Certified Data Engineer Professional Valid Torrent - Certified-Data-Engineer-Professional Training Vce - Databricks Certified Data Engineer Professional Latest Pdf 🤨 Immediately open ▛ www.prep4away.com ▟ and search for ⇛ Certified-Data-Engineer-Professional ⇚ to obtain a free download 🕰Certified-Data-Engineer-Professional Updated Dumps
- Certified-Data-Engineer-Professional Updated CBT ❎ Certified-Data-Engineer-Professional Valid Exam Fee 🔩 Certified-Data-Engineer-Professional Reliable Test Test 🌟 Download ⇛ Certified-Data-Engineer-Professional ⇚ for free by simply entering ✔ www.pdfvce.com ️✔️ website 👱Certified-Data-Engineer-Professional Latest Test Vce
- Databricks Certified Data Engineer Professional Valid Torrent - Certified-Data-Engineer-Professional Training Vce - Databricks Certified Data Engineer Professional Latest Pdf ☃ Open ➡ www.testkingpass.com ️⬅️ and search for 【 Certified-Data-Engineer-Professional 】 to download exam materials for free 🎃Exam Certified-Data-Engineer-Professional Pattern
- Pass-Sure Certified-Data-Engineer-Professional Exam Flashcards Help You to Get Acquainted with Real Certified-Data-Engineer-Professional Exam Simulation 🥮 Easily obtain 《 Certified-Data-Engineer-Professional 》 for free download through ➤ www.pdfvce.com ⮘ 🎤Test Certified-Data-Engineer-Professional King
- Pass-Sure Certified-Data-Engineer-Professional Exam Flashcards Help You to Get Acquainted with Real Certified-Data-Engineer-Professional Exam Simulation 🎼 Search for “ Certified-Data-Engineer-Professional ” and download exam materials for free through 【 www.prep4away.com 】 🏔New Certified-Data-Engineer-Professional Exam Prep
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, dorahacks.io, www.ted.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.chordie.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
2026 Latest TestKingFree Certified-Data-Engineer-Professional PDF Dumps and Certified-Data-Engineer-Professional Exam Engine Free Share: https://drive.google.com/open?id=1CQbcqX19agQhmAPKcq8j2yKdXxvkkzPe