BTW, DOWNLOAD part of itPass4sure DP-800 dumps from Cloud Storage: https://drive.google.com/open?id=1s3XRYCyVXFs0raycqm9JbqOKAF3SkCqT
Now you do not need to worry about the relevancy and top standard of itPass4sure Developing AI-Enabled Database Solutions (DP-800) exam questions. These Microsoft DP-800 dumps are designed and verified by qualified Developing AI-Enabled Database Solutions (DP-800) exam trainers. Now you can trust itPass4sure Developing AI-Enabled Database Solutions (DP-800) practice questions and start preparation without wasting further time.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> Reliable DP-800 Test Camp <<
Browsers including MS Edge, Internet Explorer, Safari, Opera, Chrome, and Firefox also support the online version of the Microsoft DP-800 practice exam. Features we have discussed in the above section of the itPass4sure Developing AI-Enabled Database Solutions (DP-800) practice test software are present in the online format as well. But the web-based version of the DP-800 practice exam requires a continuous internet connection.
NEW QUESTION # 92
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a SQL database in Microsoft Fabric that contains a table named dbo.Orders.
dbo.Orders has a clustered index, contains three years of data, and is partitioned by a column named OrderDate by month.
You need to remove all the rows for the oldest month. The solution must minimize the impact on other queries that access the data in dbo.Orders.
Solution: Identify the partition number for the oldest month, and then run the following Transact- SQL statement.
TRUNCATE TABLE dbo.Orders
WITH (PARTITIONS (partition number));
Does this meet the goal?
Answer: A
Explanation:
Correct:
* Identify the partition number for the oldest month, and then run the following Transact-SQL statement.
TRUNCATE TABLE dbo.Orders
WITH (PARTITIONS (partition number));
The best Transact-SQL statement to remove all rows for the oldest month while minimizing the impact on other queries is TRUNCATE TABLE with a WITH (PARTITIONS (...)) clause.
Why TRUNCATE TABLE ... WITH (PARTITIONS (...)) is Best
Efficiency: TRUNCATE TABLE is a Data Definition Language (DDL) operation that removes data by deallocating the data pages, which is a metadata operation and is very fast, regardless of the amount of data in the partition.
Minimal Logging: It uses less transaction log space compared to a DELETE statement, which logs each row deletion individually.
Low Impact on Concurrency: It performs a quick, partition-specific operation. A row-by-row DELETE would be a long-running transaction and could cause locking and blocking issues for other queries accessing the table.
Data Integrity: Because the table has a clustered index and is partitioned by the same column (aligned indexes), the TRUNCATE PARTITION operation is a fast, partition-level maintenance operation that targets only that specific data subset.
Incorrect:
* : Identify the partition scheme for the oldest month, and then run the following Transact-SQL statement.
ALTER TABLE dbo.Orders
DROP PARTITION SCHEME (partition_scheme_name);
The DROP PARTITION SCHEME statement removes the partition scheme object from the database but does not remove the data itself or free up the space, and it requires all tables to be moved off the scheme first, which is a complex operation. This does not meet the goal of removing the data efficiently.
* Run the following Transact-SQL statement.
DELETE FROM dbo.Orders
WHERE OrderDate < DATEADD(month, -36, SYSUTCDATETIME());
A standard DELETE statement, even with a WHERE clause that uses the partition column, can be a time-consuming, logged operation that causes locking and blocking on the main table, negatively impacting performance.
Reference:
https://stackoverflow.com/questions/63632963/truncate-partition-vs-drop-partition-performace- wise-which-one-is-efficient-an
NEW QUESTION # 93
You have a Microsoft SQL Server 2025 database that contains a table named products. products contains two columns named description and embedding. embedding is generated from description.
You have an application named App1. App1 has a feature that uses the following query.
VECTOR_DISTANCE('cosine', @query_vector, embedding)
Users report that the feature is slow during peak usage times.
You discover that during peak usage times, the semantic search latency increases and CPU utilization spikes.
You need to reduce latency and CPU utilization related to the App1 feature.
What should you do?
Answer: E
Explanation:
The correct answer is C because the current query uses VECTOR_DISTANCE( ' cosine ' , @query_vector, embedding) , which performs an exact vector distance calculation . Microsoft explicitly documents that VECTOR_DISTANCE does not use a vector index , even when one exists. Exact k-nearest-neighbor searches can require scanning large numbers of vectors and calculating distances row by row, which explains the observed CPU spikes and increased semantic-search latency during peak load.
A vector index on products.embedding is specifically designed to accelerate nearest-neighbor search, and VECTOR_SEARCH is the Transact-SQL function that can use that approximate nearest-neighbor index when the index metric matches the query metric. Using METRIC = ' cosine ' preserves the same similarity metric currently used by App1 while reducing the amount of computation required.
The other choices are incorrect:
* A normalizes vectors but does not replace the expensive exact search with indexed ANN retrieval.
* B replaces semantic vector search with lexical full-text search and changes the feature's behavior.
* D a standard nonclustered B-tree index cannot accelerate vector-distance operations.
* E converting embeddings to VARBINARY(8000) removes native vector semantics and does not solve the performance problem.
Therefore, the exam-aligned solution is create a vector index and use VECTOR_SEARCH with cosine distance .
NEW QUESTION # 94
You have an Azure SQL database that has Query Store enabled
Query Performance Insight shows that one stored procedure has the longest runtime. The procedure runs the following parameterized query.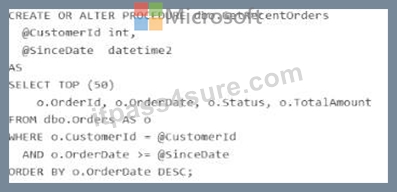
The dbo.orders table has approximately 120 million rows. Customer-id is highly selective, and orderOate is used for range filtering and sorting.
Vou have the following indexes:
* Clustered index: PK_Orders on (Orderld)
* Nonclustered index: lx_0rders_order-Date on (OrderDate) with no included columns An actual execution plan captured from Query Store for slow runs shows the following:
* An index seek on ixordersorderDate followed by a Key Lookup (Clustered) on PKOrders for customerid, status, and TotalAnount
* A sort operator before top (50), because the results are ordered by orderDate DESC For each of the following statements, select Yes if the statement is true. Otherwise, select No. NOTE: Each correct selection is worth one point.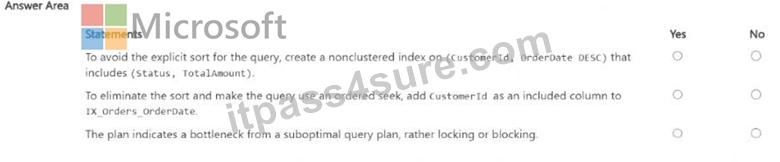
Answer:
Explanation: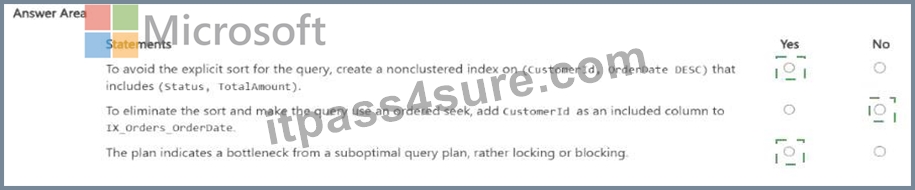
Explanation: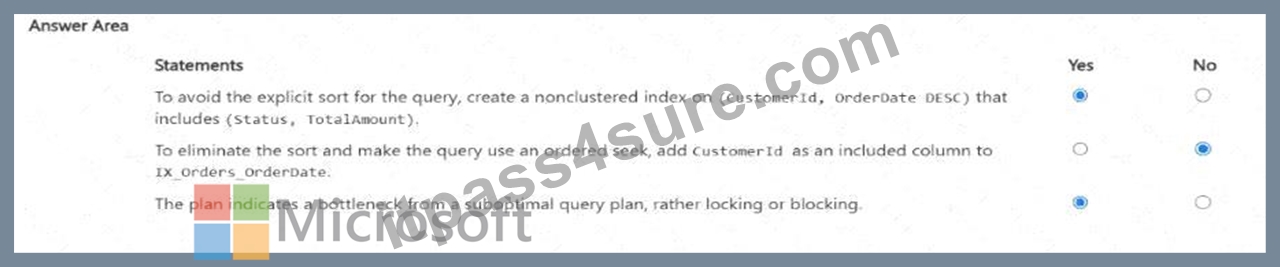
The first statement is Yes . The query filters on CustomerId, applies a range predicate on OrderDate, and sorts by OrderDate DESC. Microsoft's index design guidance recommends putting equality predicates first in the key, followed by columns used for ordering/range access, because the order of key columns determines seek and sort support. A nonclustered index on (CustomerId, OrderDate DESC) can support an ordered seek for this query and avoid the explicit sort. Including Status and TotalAmount helps cover the query, and OrderId is already available because the clustered key is stored with nonclustered index rows.
The second statement is No . Adding CustomerId as an included column to IX_Orders_OrderDate does not make it part of the index's navigational structure. Microsoft states that included columns are nonkey columns used to cover queries; they do not provide the seek and ordering characteristics that key columns do. So an index keyed only on OrderDate still is not the right ordered access path for WHERE CustomerId =
@CustomerId ... ORDER BY OrderDate DESC.
The third statement is Yes . The described actual plan shows an index seek on the wrong access path for the workload, followed by clustered key lookups and an explicit sort before TOP (50). That is characteristic of a suboptimal query/index plan . Query Store and Query Performance Insight are designed to surface plan- related performance regressions, while locking/blocking problems are typically identified through waits
/DMVs and blocking-session indicators, not from a plan shape like seek + lookup + sort alone.
NEW QUESTION # 95
You have an Azure SQL database that contains the following tables and columns.
Embeddings in the NotesEnbeddings and DescriptionEabeddings tables have been generated from values in the Description and notes columns of the Articles table by using different chunk sizes.
You need to perform approximate nearest neighbor (ANN) queries across both embedding tables. The solution must minimize the impact of using different chunk sizes.
What should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
The correct function is VECTOR_SEARCH because the requirement is to perform approximate nearest neighbor (ANN) queries. Microsoft's SQL documentation states that VECTOR_SEARCH is the function used for vector similarity search, and that an ANN index is used only with VECTOR_SEARCH when a compatible vector index exists on the target column. By contrast, VECTOR_DISTANCE calculates an exact distance and does not use a vector index for ANN retrieval.
The correct distance metric is cosine distance. Microsoft documents that VECTOR_SEARCH supports cosine, dot, and euclidean metrics, and Microsoft guidance specifically notes that cosine similarity is commonly used for text embeddings. It also states that retrieval of the most similar texts to a given text typically functions better with cosine similarity, and that Azure OpenAI embeddings rely on cosine similarity to compute similarity between a query and documents. Since both NotesEmbeddings and DescriptionEmbeddings are text-derived embeddings and the goal is to minimize the impact of different chunk sizes, cosine is the best choice because it compares direction/angle rather than being as sensitive to vector magnitude as Euclidean distance.
NEW QUESTION # 96
You need to meet the development requirements for the FeedbackJson column.
How should you complete the Transact SQL query? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
JSON_VALUE(f.FeedbackJson, ' $.text ' ) AS FeedbackText
CONTAINS(FeedbackJson, @Keyword)
SimilarityScore
These three selections are the correct way to complete the query because they align exactly with the stated requirements for the FeedbackJson column.
First, to extract the customer feedback text from the JSON document, the correct expression is JSON_VALUE (f.FeedbackJson, ' $.text ' ) AS FeedbackText. Microsoft documents that JSON_VALUE is used to extract a scalar value from JSON, while JSON_QUERY is used for returning an object or array. Since $.text is the textual feedback string, JSON_VALUE is the correct function.
Second, to filter rows where the JSON text contains a keyword, the best choice is CONTAINS(FeedbackJson,
@Keyword). The scenario explicitly states that FeedbackJson already has a full-text index, and Microsoft documents that CONTAINS is the full-text predicate used in the WHERE clause to search full-text indexed character data. That makes it more appropriate than using EDIT_DISTANCE for keyword filtering.
Third, to order the results by similarity score, highest first, the correct item is SimilarityScore in the ORDER BY clause, which would be paired with DESC in the query. This matches the requirement to sort by the computed fuzzy similarity value. The DP-800 study guide specifically includes writing queries that use fuzzy string matching functions such as EDIT_DISTANCE, which supports the earlier computed SimilarityScore expression in the query.
NEW QUESTION # 97
......
In modern society, innovation is of great significance to the survival of a company. The new technology of the DP-800 study materials is developing so fast. So the competitiveness among companies about the study materials is fierce. Luckily, our company masters the core technology of developing the Developing AI-Enabled Database Solutions study materials. No company in the field can surpass us. So we still hold the strong strength in the market. At present, our DP-800 study materials have applied for many patents. We attach great importance on the protection of our intellectual property. What is more, our research center has formed a group of professional experts responsible for researching new technology of the DP-800 Study Materials. The technology of the DP-800 study materials will be innovated every once in a while. As you can see, we never stop innovating new version of the DP-800 study materials. We really need your strong support.
Valid Dumps DP-800 Files: https://www.itpass4sure.com/DP-800-practice-exam.html
What's more, part of that itPass4sure DP-800 dumps now are free: https://drive.google.com/open?id=1s3XRYCyVXFs0raycqm9JbqOKAF3SkCqT