A certification is not only an affirmation to your ability but also can help you enter a better company and improve your salary. Databricks-Certified-Professional-Data-Engineer exam cram can help you get your certification successfully. We have a professional team to collect and research the latest information for the exam, and we offer you free update for 365 days after payment, so that you can obtain the latest information. In order to build up your confidence for Databricks-Certified-Professional-Data-Engineer Exam Braindumps, we are pass guarantee and money back guarantee if you fail to pass the exam.
| Certification Vendor: | Databricks |
|---|---|
| Exam Name: | Databricks Certified Professional Data Engineer Exam |
| Exam Number: | Databricks-Certified-Professional-Data-Engineer |
| Available Languages: | English |
| Real Exam Qty: | 60-70 |
| Exam Duration: | 120 minutes |
| Exam Price: | USD 200 |
| Certificate Validity Period: | 2 years |
| Related Certifications: | Databricks Certified Data Engineer Associate |
| Exam Format: | Scenario-based questions, Multiple choice, Multiple select |
| Passing Score: | 70% |
| Recommended Training: | Databricks Academy |
| Exam Registration: | Databricks Certification Portal |
| Sample Questions: | Databricks Databricks-Certified-Professional-Data-Engineer Sample Questions |
| Exam Way: | Online proctored exam |
| Pre Condition: | Recommended: Databricks Certified Data Engineer Associate or equivalent experience with Spark and Databricks platform. |
| Official Syllabus URL: | https://www.databricks.com/learn/certification |
>> Latest Databricks-Certified-Professional-Data-Engineer Exam Questions Vce <<
This offline software works only on Windows computers and laptops. SureTorrent also offers up to 1 year of free updates, if for instance, the sections of real Databricks Certified Professional Data Engineer Exam examination changes after your purchase of the Databricks-Certified-Professional-Data-Engineer practice test material. So just download actual Databricks-Certified-Professional-Data-Engineer Exam Questions and start your journey today. It ensures that you would qualify for the Databricks Databricks-Certified-Professional-Data-Engineer certification exam on the maiden strive with brilliant grades.
Databricks Certified Professional Data Engineer certification exam is a challenging exam that requires candidates to have a deep understanding of Databricks technologies and data engineering concepts. Candidates must have experience working with Apache Spark, Delta Lake, SQL, and Python. They must also have experience working with cloud-based data platforms such as AWS, Azure, or Google Cloud Platform.
Databricks Certified Professional Data Engineer exam is an excellent choice for data engineers who want to demonstrate their expertise in using Databricks to process big data. Databricks Certified Professional Data Engineer Exam certification exam is recognized globally and highly valued by organizations that use Databricks for their big data processing needs. By passing the exam, data engineers can validate their knowledge and skills and increase their chances of career advancement.
Databricks Certified Professional Data Engineer exam is designed to test the skills and knowledge of individuals who work with big data and cloud computing technologies. Databricks-Certified-Professional-Data-Engineer Exam is primarily focused on assessing candidates’ abilities to design, build, and maintain big data solutions using the Apache Spark platform. Databricks Certified Professional Data Engineer Exam certification is highly valued in the industry and can help individuals demonstrate their proficiency in managing big data projects.
NEW QUESTION # 108
Although the Databricks Utilities Secrets module provides tools to store sensitive credentials and avoid accidentally displaying them in plain text users should still be careful with which credentials are stored here and which users have access to using these secrets.
Which statement describes a limitation of Databricks Secrets?
Answer: D
Explanation:
This is the correct answer because it describes a limitation of Databricks Secrets. Databricks Secrets is a module that provides tools to store sensitive credentials and avoid accidentally displaying them in plain text. Databricks Secrets allows creating secret scopes, which are collections of secrets that can be accessed by users or groups. Databricks Secrets also allows creating and managing secrets using the Databricks CLI or the Databricks REST API. However, a limitation of Databricks Secrets is that the Databricks REST API can be used to list secrets in plain text if the personal access token has proper credentials. Therefore, users should still be careful with which credentials are stored in Databricks Secrets and which users have access to using these secrets. Verified Reference: [Databricks Certified Data Engineer Professional], under "Databricks Workspace" section; Databricks Documentation, under "List secrets" section.
NEW QUESTION # 109
The data engineering team maintains a table of aggregate statistics through batch nightly updates. This includes total sales for the previous day alongside totals and averages for a variety of time periods including the 7 previous days, year-to-date, and quarter-to-date. This table is named store_saies_summary and the schema is as follows:
The table daily_store_sales contains all the information needed to update store_sales_summary. The schema for this table is:
store_id INT, sales_date DATE, total_sales FLOAT
If daily_store_sales is implemented as a Type 1 table and the total_sales column might be adjusted after manual data auditing, which approach is the safest to generate accurate reports in the store_sales_summary table?
Answer: E
Explanation:
The daily_store_sales table contains all the information needed to update store_sales_summary. The schema of the table is:
store_id INT, sales_date DATE, total_sales FLOAT
The daily_store_sales table is implemented as a Type 1 table, which means that old values are overwritten by new values and no history is maintained. The total_sales column might be adjusted after manual data auditing, which means that the data in the table may change over time.
The safest approach to generate accurate reports in the store_sales_summary table is to use Structured Streaming to subscribe to the change data feed for daily_store_sales and apply changes to the aggregates in the store_sales_summary table with each update. Structured Streaming is a scalable and fault-tolerant stream processing engine built on Spark SQL. Structured Streaming allows processing data streams as if they were tables or DataFrames, using familiar operations such as select, filter, groupBy, or join. Structured Streaming also supports output modes that specify how to write the results of a streaming query to a sink, such as append, update, or complete. Structured Streaming can handle both streaming and batch data sources in a unified manner.
The change data feed is a feature of Delta Lake that provides structured streaming sources that can subscribe to changes made to a Delta Lake table. The change data feed captures both data changes and schema changes as ordered events that can be processed by downstream applications or services. The change data feed can be configured with different options, such as starting from a specific version or timestamp, filtering by operation type or partition values, or excluding no-op changes.
By using Structured Streaming to subscribe to the change data feed for daily_store_sales, one can capture and process any changes made to the total_sales column due to manual data auditing. By applying these changes to the aggregates in the store_sales_summary table with each update, one can ensure that the reports are always consistent and accurate with the latest data. Verified References: [Databricks Certified Data Engineer Professional], under "Spark Core" section; Databricks Documentation, under "Structured Streaming" section; Databricks Documentation, under "Delta Change Data Feed" section.
NEW QUESTION # 110
Where are Interactive notebook results stored in Databricks product architecture?
Answer: C
Explanation:
Explanation
The answer is Data and Control plane,
Only Job results are stored in Data Plane(your storage), Interactive notebook results are stored in a combination of the control plane (partial results for presentation in the UI) and customer storage.
https://docs.microsoft.com/en-us/azure/databricks/getting-started/overview#--high-level-architecture Snippet from the above documentation, Graphical user interface, application Description automatically generated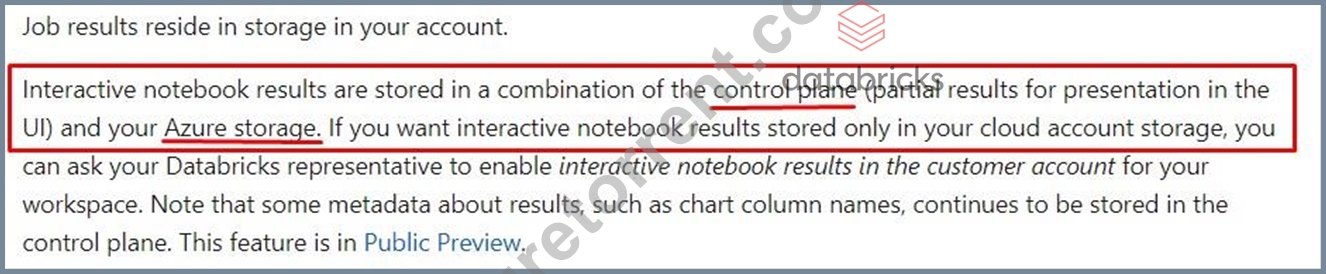
How to change this behavior?
You can change this behavior using Workspace/Admin Console settings for that workspace, once enabled all of the interactive results are stored in the customer account(data plane) except the new notebook visualization feature Databricks has recently introduced, this still stores some metadata in the control pane irrespective of the below settings. please refer to the documentation for more details.
Graphical user interface, text, application, email Description automatically generated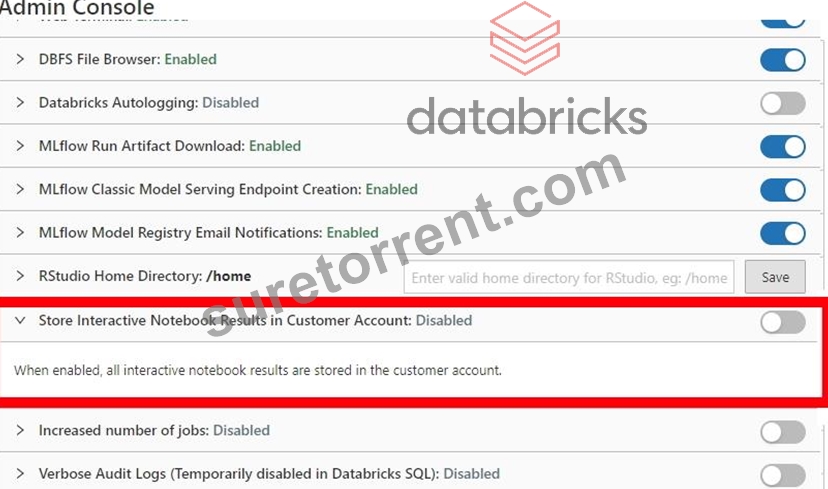
Why is this important to know?
I recently worked on a project where we had to deal with sensitive information of customers and we had a security requirement that all of the data need to be stored in the data plane including notebook results.
NEW QUESTION # 111
A Delta table of weather records is partitioned by date and has the below schema:
date DATE, device_id INT, temp FLOAT, latitude FLOAT, longitude FLOAT
To find all the records from within the Arctic Circle, you execute a query with the below filter:
latitude > 66.3
Which statement describes how the Delta engine identifies which files to load?
Answer: C
Explanation:
This is the correct answer because Delta Lake uses a transaction log to store metadata about each table, including min and max statistics for each column in each data file. The Delta engine can use this information to quickly identify which files to load based on a filter condition, without scanning the entire table or the file footers. This is called data skipping and it can improve query performance significantly. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; [Databricks Documentation], under "Optimizations - Data Skipping" section.
In the Transaction log, Delta Lake captures statistics for each data file of the table. These statistics indicate per file:
- Total number of records
- Minimum value in each column of the first 32 columns of the table
- Maximum value in each column of the first 32 columns of the table
- Null value counts for in each column of the first 32 columns of the table When a query with a selective filter is executed against the table, the query optimizer uses these statistics to generate the query result. it leverages them to identify data files that may contain records matching the conditional filter.
For the SELECT query in the question, The transaction log is scanned for min and max statistics for the price column
NEW QUESTION # 112
A data engineer has created a new cluster using shared access mode with default configurations. The data engineer needs to allow the development team access to view the driver logs if needed.
What are the minimal cluster permissions that allow the development team to accomplish this?
Answer: B
Explanation:
Comprehensive and Detailed In-Depth Explanation:
Databricks provides differentpermission levelsto control access to clusters. The correctminimal permission required for viewing driver logs isCAN VIEW.
Databricks Cluster Permission Levels:
* CAN ATTACH TO:
* Allows users toattach notebooks to a clusterbutdoes notallow them toview logs.
* Not sufficientfor viewing driver logs.
* CAN MANAGE:
* Grantsfull controlover the cluster, including starting, stopping, and editing configurations.
* Too broad for this requirement.
* CAN VIEW (Correct Answer):
* Allows users toview cluster details, logs, and statusbutnot modifyany configurations.
* Minimal required permission for viewing logs.
* CAN RESTART:
* Grants permission torestart the cluster, but doesnot include log access.
* Not sufficientfor viewing logs.
Conclusion:
Theminimalpermission needed to allow the development team toview driver logsisCAN VIEW.
References:
* Databricks Cluster Permissions Documentation
NEW QUESTION # 113
......
Valid Databricks-Certified-Professional-Data-Engineer Exam Labs: https://www.suretorrent.com/Databricks-Certified-Professional-Data-Engineer-exam-guide-torrent.html