Pass Guaranteed Quiz 2026 Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Pass-Sure New Dumps Ppt

Don't you want to make a splendid achievement in your career? Certainly hope so. Then it is necessary to constantly improve yourself. Working in the Databricks industry, what should you do to improve yourself? In fact, it is a good method to improve yourself by taking Databricks certification exams and getting Databricks certificate. Databricks certificate is very important certificate, so more and more people choose to attend Certified-Data-Engineer-Professional Certification Exam.
| Section | Objectives |
|---|
| Topic 1: Monitoring and Alerting | - Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
- Monitoring
- 1. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 2. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 3. Use system tables for resource, cost, audit, and workload monitoring
- 4. Use Query Profiler and Spark UI to monitor workloads
|
| Topic 2: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest data from message buses and cloud storage
- 2. Build append-only pipelines for batch and streaming data using Delta
- 3. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
|
| Topic 3: Data Governance | - Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
- Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
|
| Topic 4: Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
|
| Topic 5: Ensuring Data Security and Compliance | - Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Use ACLs to secure workspace objects and enforce least privilege
- 3. Apply anonymization and pseudonymization techniques
- Compliance
- 1. Develop data purging solutions according to data retention policies
- 2. Implement pipelines that detect and mask personally identifiable information
|
| Topic 6: Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Share live Lakehouse data with external computing platforms
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Configure Databricks-to-Databricks Sharing
|
| Topic 7: Debugging and Deploying | - Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Integrate Git-based CI/CD workflows using Databricks Git Folders
- Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs
- 2. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 3. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
|
| Topic 8: Cost & Performance Optimisation | - Delta Optimization
- 1. Understand deletion vectors and liquid clustering
- 2. Apply data skipping and file pruning techniques
- 3. Use Change Data Feed to address streaming table limitations and improve latency
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
|
| Topic 9: Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Use APPLY CHANGES APIs for change data capture
- 2. Use control flow operators in pipeline components
- 3. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 4. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 5. Compare streaming tables and materialized views
- 6. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 7. Develop unit and integration tests for data processing code
- 8. Configure environments, dependencies, memory, and retry behavior
- Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDFs
- 2. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 3. Manage and troubleshoot third-party library installations and dependencies
|
| Topic 10: Data Modelling | - Dimensional Modelling
- 1. Design dimensional models for analytical workloads
- Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Optimize data layout using Liquid Clustering
- 3. Understand Liquid Clustering versus partitioning and Z-Ordering
|
>> New Certified-Data-Engineer-Professional Dumps Ppt <<
High Pass-Rate New Certified-Data-Engineer-Professional Dumps Ppt, Ensure to pass the Certified-Data-Engineer-Professional Exam
Just like the old saying goes, there is no royal road to success, and only those who do not dread the fatiguing climb of gaining its numinous summits. In a similar way, there is no smoothly paved road to the Certified-Data-Engineer-Professional Certification. You have to work on it and get started from now. If you want to gain the related certification, it is very necessary that you are bound to spend some time on carefully preparing for the Databricks exam, including choosing the convenient and practical study materials, sticking to study and keep an optimistic attitude and so on.
Databricks Certified Data Engineer Professional Sample Questions (Q168-Q173):
NEW QUESTION # 168
The data governance team is reviewing code used for deleting records for compliance with GDPR. They note the following logic is used to delete records from the Delta Lake table named users.
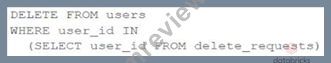
Assuming that user_id is a unique identifying key and that delete_requests contains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
- A. No; files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files.
- B. No; the Delta Lake delete command only provides ACID guarantees when combined with the merge into command.
- C. Yes; Delta Lake ACID guarantees provide assurance that the delete command succeeded fully and permanently purged these records.
- D. Yes; the Delta cache immediately updates to reflect the latest data files recorded to disk.
- E. No; the Delta cache may return records from previous versions of the table until the cluster is restarted.
Answer: A
Explanation:
The code uses the DELETE FROM command to delete records from the users table that match a condition based on a join with another table called delete_requests, which contains all users that have requested deletion. The DELETE FROM command deletes records from a Delta Lake table by creating a new version of the table that does not contain the deleted records. However, this does not guarantee that the records to be deleted are no longer accessible, because Delta Lake supports time travel, which allows querying previous versions of the table using a timestamp or version number. Therefore, files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files from physical storage.
NEW QUESTION # 169
A data architect is implementing Delta Sharing as part of their data governance strategy to enable secure data collaboration with external partners and internal business units. The architect must establish a permission framework that allows designated data stewards to create shares for their respective domains while maintaining security boundaries and audit compliance. Which specific permissions and roles must be assigned to enable users to create, configure, and manage Delta Shares while maintaining proper security governance and access controls?
- A. Only workspace admins can create and manage shares
- B. Any user with USE_CATALOG privilege can create shares
- C. Users need the MANAGE SHARES permission on the workspace
- D. Users need to be metastore admins or have CREATE SHARE privilege for the metastore
Answer: D
Explanation:
Creating and managing Delta Shares requires elevated governance privileges at the metastore level. Assigning users as metastore admins or granting them the CREATE SHARE privilege allows designated data stewards to create and configure shares within defined security boundaries, while preserving centralized auditability and access control.
NEW QUESTION # 170
A data engineer needs to productionize a new Spark application written by teammate. This application has numerous external dependencies, including libraries, and requires custom environment variables and Spark configuration parameters to be set. Which two methods will help the data engineer accomplish the task? (Choose two.)
- A. Create init scripts on DBFS.
- B. Add libraries to compute policies
- C. Use compute policies to set system properties, environment variables, and Spark configuration parameters.
- D. Use secrets in init scripts to store configuration data
- E. Install libraries on DBFS
Answer: A,C
Explanation:
Compute policies allow centrally defining and enforcing Spark configuration parameters, system properties, and environment variables required by the application, ensuring consistent production settings. Init scripts enable installing external dependencies and performing custom environment setup at cluster startup, making them essential for productionizing Spark applications with complex dependency and configuration requirements.
NEW QUESTION # 171
A data engineer is optimizing a MERGE operation on an 800GB UC-managed table that experiences frequent updates and deletions. Which two actions should the engineer prioritize to improve MERGE performance? (Choose two.)
- A. Partition the table by date.
- B. Overwrite the table instead of Merge.
- C. Apply liquid clustering using the merge join keys.
- D. Use ZORDER on high-cardinality columns.
- E. Enable deletion vectors on the table if not already enabled.
Answer: C,E
Explanation:
Liquid clustering on the merge join keys improves data locality and reduces the amount of data scanned during MERGE operations, which is especially effective for large, frequently updated tables. Enabling deletion vectors avoids rewriting entire Parquet files for updates and deletes, significantly reducing I/O and improving MERGE performance on Unity Catalog-managed tables.
NEW QUESTION # 172
The data engineer team has been tasked with configured connections to an external database that does not have a supported native connector with Databricks. The external database already has data security configured by group membership. These groups map directly to user group already created in Databricks that represent various teams within the company. A new login credential has been created for each group in the external database. The Databricks Utilities Secrets module will be used to make these credentials available to Databricks users. Assuming that all the credentials are configured correctly on the external database and group membership is properly configured on Databricks, which statement describes how teams can be granted the minimum necessary access to using these credentials?
- A. "Read" permissions should be set on a secret scope containing only those credentials that will be used by a given team.
- B. "Read'' permissions should be set on a secret key mapped to those credentials that will be used by a given team.
- C. No additional configuration is necessary as long as all users are configured as administrators in the workspace where secrets have been added.
- D. "Manage" permission should be set on a secret scope containing only those credentials that will be used by a given team.
Answer: A
Explanation:
In Databricks, using the Secrets module allows for secure management of sensitive information such as database credentials. Granting 'Read' permissions on a secret key that maps to database credentials for a specific team ensures that only members of that team can access these credentials. This approach aligns with the principle of least privilege, granting users the minimum level of access required to perform their jobs, thus enhancing security.
NEW QUESTION # 173
......
Facing the incoming Databricks Certified-Data-Engineer-Professional Exam, you may feel stained and anxious, suspicious whether you could pass the exam smoothly and successfully. Actually, you must not impoverish your ambition. Our suggestions are never boggle at difficulties. It is your right time to make your mark. Preparation of exam without effective materials is just like a soldier without gun.
Certified-Data-Engineer-Professional Latest Exam Guide: https://www.itexamreview.com/Certified-Data-Engineer-Professional-exam-dumps.html
- Exam Certified-Data-Engineer-Professional Cram Questions 🎧 Certified-Data-Engineer-Professional Valid Braindumps Ebook ♿ New Certified-Data-Engineer-Professional Exam Bootcamp 🥞 【 www.exam4labs.com 】 is best website to obtain ▛ Certified-Data-Engineer-Professional ▟ for free download ⏳Certified-Data-Engineer-Professional Exam Collection Pdf
- Certified-Data-Engineer-Professional Training Materials - Certified-Data-Engineer-Professional Certification Training - Certified-Data-Engineer-Professional Exam Questions 🍋 Enter [ www.pdfvce.com ] and search for ⇛ Certified-Data-Engineer-Professional ⇚ to download for free 🍎Certified-Data-Engineer-Professional Latest Exam Answers
- Certified-Data-Engineer-Professional Valid Practice Materials ⚒ Certified-Data-Engineer-Professional Exam Collection Pdf ⛷ New Certified-Data-Engineer-Professional Exam Bootcamp 🧓 Easily obtain free download of { Certified-Data-Engineer-Professional } by searching on [ www.pdfdumps.com ] 🤧New Certified-Data-Engineer-Professional Exam Bootcamp
- Certified-Data-Engineer-Professional Training Materials - Certified-Data-Engineer-Professional Certification Training - Certified-Data-Engineer-Professional Exam Questions 🚖 Immediately open ➥ www.pdfvce.com 🡄 and search for ▛ Certified-Data-Engineer-Professional ▟ to obtain a free download 🥬Certified-Data-Engineer-Professional Latest Exam Papers
- Certified-Data-Engineer-Professional Training Materials - Certified-Data-Engineer-Professional Certification Training - Certified-Data-Engineer-Professional Exam Questions 🔪 Copy URL ➽ www.prepawayete.com 🢪 open and search for ➽ Certified-Data-Engineer-Professional 🢪 to download for free 🦨Certified-Data-Engineer-Professional 100% Exam Coverage
- Study Certified-Data-Engineer-Professional Dumps 💮 Study Certified-Data-Engineer-Professional Dumps 🗳 Certified-Data-Engineer-Professional Valid Practice Materials 😃 Open ⇛ www.pdfvce.com ⇚ enter ⏩ Certified-Data-Engineer-Professional ⏪ and obtain a free download 😩Practice Certified-Data-Engineer-Professional Test Online
- New Certified-Data-Engineer-Professional Exam Bootcamp 🐡 Exam Certified-Data-Engineer-Professional Cram Questions 🙇 Dumps Certified-Data-Engineer-Professional Download 🤰 Immediately open ( www.vceengine.com ) and search for ▛ Certified-Data-Engineer-Professional ▟ to obtain a free download 🥱Exam Certified-Data-Engineer-Professional Introduction
- Certified-Data-Engineer-Professional Training Materials - Certified-Data-Engineer-Professional Certification Training - Certified-Data-Engineer-Professional Exam Questions ⚡ The page for free download of [ Certified-Data-Engineer-Professional ] on ▷ www.pdfvce.com ◁ will open immediately 🕢Certified-Data-Engineer-Professional 100% Exam Coverage
- Certified-Data-Engineer-Professional Exam Collection Pdf 😫 Certified-Data-Engineer-Professional Latest Exam Answers 📏 Certified-Data-Engineer-Professional Latest Exam Papers 📕 Immediately open ⮆ www.testkingpass.com ⮄ and search for [ Certified-Data-Engineer-Professional ] to obtain a free download 📖Exam Certified-Data-Engineer-Professional Introduction
- Certified-Data-Engineer-Professional Training Materials - Certified-Data-Engineer-Professional Certification Training - Certified-Data-Engineer-Professional Exam Questions ❔ Copy URL ➽ www.pdfvce.com 🢪 open and search for ➡ Certified-Data-Engineer-Professional ️⬅️ to download for free 🕤Certified-Data-Engineer-Professional Latest Exam Papers
- Latest Certified-Data-Engineer-Professional Braindumps 🌎 Valid Certified-Data-Engineer-Professional Test Pass4sure 🤺 Certified-Data-Engineer-Professional Test Centres 🌖 Open website 【 www.prep4sures.top 】 and search for ➽ Certified-Data-Engineer-Professional 🢪 for free download 😙Reliable Certified-Data-Engineer-Professional Exam Question
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, aprenderfotografia.online, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes