P.S. PassTestがGoogle Driveで共有している無料かつ新しいSPS-C01ダンプ:https://drive.google.com/open?id=1QdAtGMjy_N6ZCzfXR7YzXNO55UzimTed
PassTestのSnowflakeのSPS-C01試験トレーニング資料は質も良くて、値段も安いです。うちの学習教材を購入したら、私たちは一年間で無料更新サービスを提供することができます。あなたはSnowflakeのSPS-C01問題集を購入する前に、PassTestは無料でサンプルを提供することができます。もし学習教材は問題があれば、或いは試験に不合格になる場合は、全額返金することを保証いたします。
| Section | Objectives |
|---|---|
| User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Performance Optimization and Best Practices | - Efficient Snowpark execution
|
| Data Engineering with Snowpark | - Pipeline development
|
| DataFrame Operations and Data Processing | - Data transformation workflows
|
| Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Testing, Debugging, and Deployment | - Production readiness
|
当社PassTestのSPS-C01学習教材は常に高い合格率を維持していることがわかっています。教材の質の高さによるものであることは間違いありません。合格率は、SPS-C01トレーニングファイルを証明する最も重要な標準であるというのは常識の問題です。教材の高い合格率は、当社の製品がすべての人々がSPS-C01試験に合格し、関連する認定を取得するために非常に効果的かつ有用であることを意味します。そのため、当社からSPS-C01試験問題を購入すると、短時間で認定資格を取得できます。
質問 # 112
A Snowpark application is designed to process data residing in a Snowflake table called 'ORDERS'. The application needs to create a temporary view named 'TEMP ORDERS VIEW based on a filtered subset of this table. The view should only be accessible within the current Snowpark session and should be automatically dropped when the session ends. What is the MOST efficient and correct Python code snippet using Snowpark to achieve this?


正解:D
解説:
Option A, , is the most efficient and directly creates a temporary view scoped to the session. The 'createOrRepIaceTempView' method is the correct Snowpark API call for creating such views. Options B and D, 'createOrReplaceView' with or 'createView' with , are not valid Snowpark API calls. Option C, createOrReplaceGlobalTempViews , creates a global temporary view, accessible across sessions, which is not the requirement. Option E is adding a redundant step by creating a dataframe from another dataframe.
質問 # 113
You have a Snowflake table 'raw_events' containing JSON data in a VARIANT column named 'event_data'. This column contains nested JSON objects representing user activity on a website. You need to extract specific nested values and load them into a new Snowflake table 'user_activity' with columns 'event_type' , and 'timestamp'. Which of the following Snowpark code snippets is the MOST efficient and correct way to achieve this, assuming you want to minimize data transfer and optimize performance? Consider the potential for null values within the JSON.




正解:E
解説:
Option C is the most efficient because it uses Snowflake's native JSON path notation (using 'f) directly within the 'select' statement, which is optimized for Snowflake's internal JSON handling. The other options use function calls ('get' , 'col'), which can introduce overhead. Furthermore, the code uses try_to_timestamp() to avoid errors due to null values
質問 # 114
Consider a Snowpark DataFrame with columns 'DEPARTMENT, 'SALARY , and 'YEAR. You want to find the average salary for each department over all years and then filter the departments to only include those where the average salary is greater than 100000. Which of the following approaches is the MOST efficient and correct way to achieve this using Snowpark Python?





正解:B
解説:
Options A, B, C, and D are technically valid but use 'avg' or 'col' instead of the recommended 'sf.mean' and 'sf.cor for Snowpark. Option E, is most efficient as it leverages Snowpark's functions ('sf.mean' and 'sf.col') correctly and splits the operation in two steps for clarity and potential optimization. 'col' can be used, 'sf.col' is the recommended way.
質問 # 115
You have a Snowpark Python application that reads data from a Snowflake table, performs a complex transformation using a User- Defined Table Function (UDTF), and then writes the transformed data back to a new Snowflake table. The UDTF is defined as follows: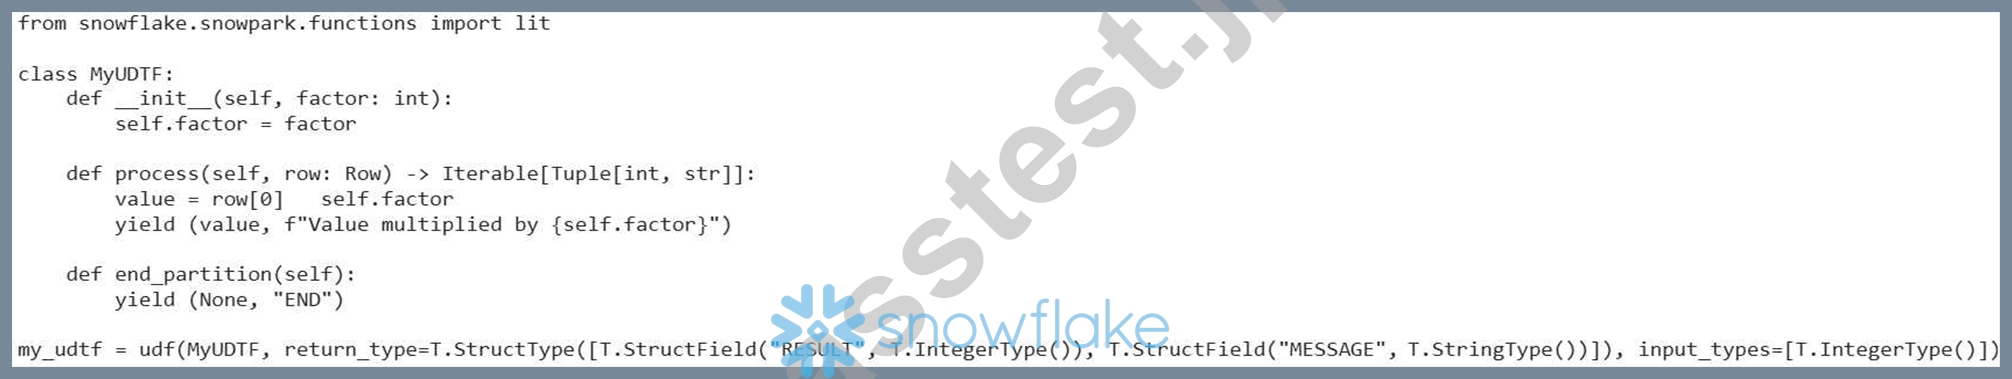
You need to optimize the performance of this application. Which of the following strategies would be MOST effective in reducing the execution time of the UDTF?
正解:A
解説:
Vectorized UDTFs process data in batches, which can significantly improve performance compared to processing each row individually. This is especially true for complex transformations. Increasing warehouse size (A) can help but might not be as efficient as vectorization. Reducing input data (B) is always a good practice, but vectorization provides a more direct performance boost to the UDTF execution. Standard UDFs (D) are not generally faster than UDTFs, especially when dealing with table transformations. Caching (E) can help if the DataFrame is reused multiple times, but it doesn't directly optimize the UDTF's performance.
質問 # 116
You are working with a Snowpark DataFrame named containing information about products, including 'CATEGORY , 'SUBCATEGORY , and 'PRICE'. You want to determine the maximum price for each subcategory within each category. Furthermore, you need to filter the results to only include categories that have more than 5 subcategories. Which of the following Snowpark Python code snippets accomplishes this task? (Select all that apply)





正解:B、C
解説:
The correct options are D and E. They both address the requirement and count distinct subcategories within each category. Option D: Correctly calculates the maximum price for each subcategory within each category. Then separately calculates the count of DISTINCT subcategories for each category. Filters the categories to include only those with more than 5 subcategories. Joins the two resulting DataFrames to provide the final output. This is a standard and explicit way to accomplish the task. Using countDistinct to ensure each subcategory is only counted once. Option E: Aggregates Max Price and CountDistinct of subcategory into same dataframe, this addresses all requirements in a more concise manner. Option A: Does not give the right result since 'count' will not give the countDistinct. Also using 'COUNT(SUBCATEGORYV in category_countS dataframe results in count of all rows in the group instead of the number of groups (number of Subcategories). Option B: Window functions is irrelevant here, and requires more coding while can be handled efficiently by aggregating and countDistinct combination Option C: Option C doesn't aggregate maximum price for each subcategory within each category as the question mentions.
質問 # 117
......
なぜ我々はあなたが購入した前にやってみることを許しますか。なぜ我々はあなたが利用してからSnowflakeのSPS-C01試験に失敗したら、全額で返金するのを承諾しますか。我々は弊社の商品があなたに試験に合格させるのを信じでいます。SnowflakeのSPS-C01試験が更新するとともに我々の作成するソフトは更新しています。
SPS-C01シュミレーション問題集: https://www.passtest.jp/Snowflake/SPS-C01-shiken.html
BONUS!!! PassTest SPS-C01ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1QdAtGMjy_N6ZCzfXR7YzXNO55UzimTed